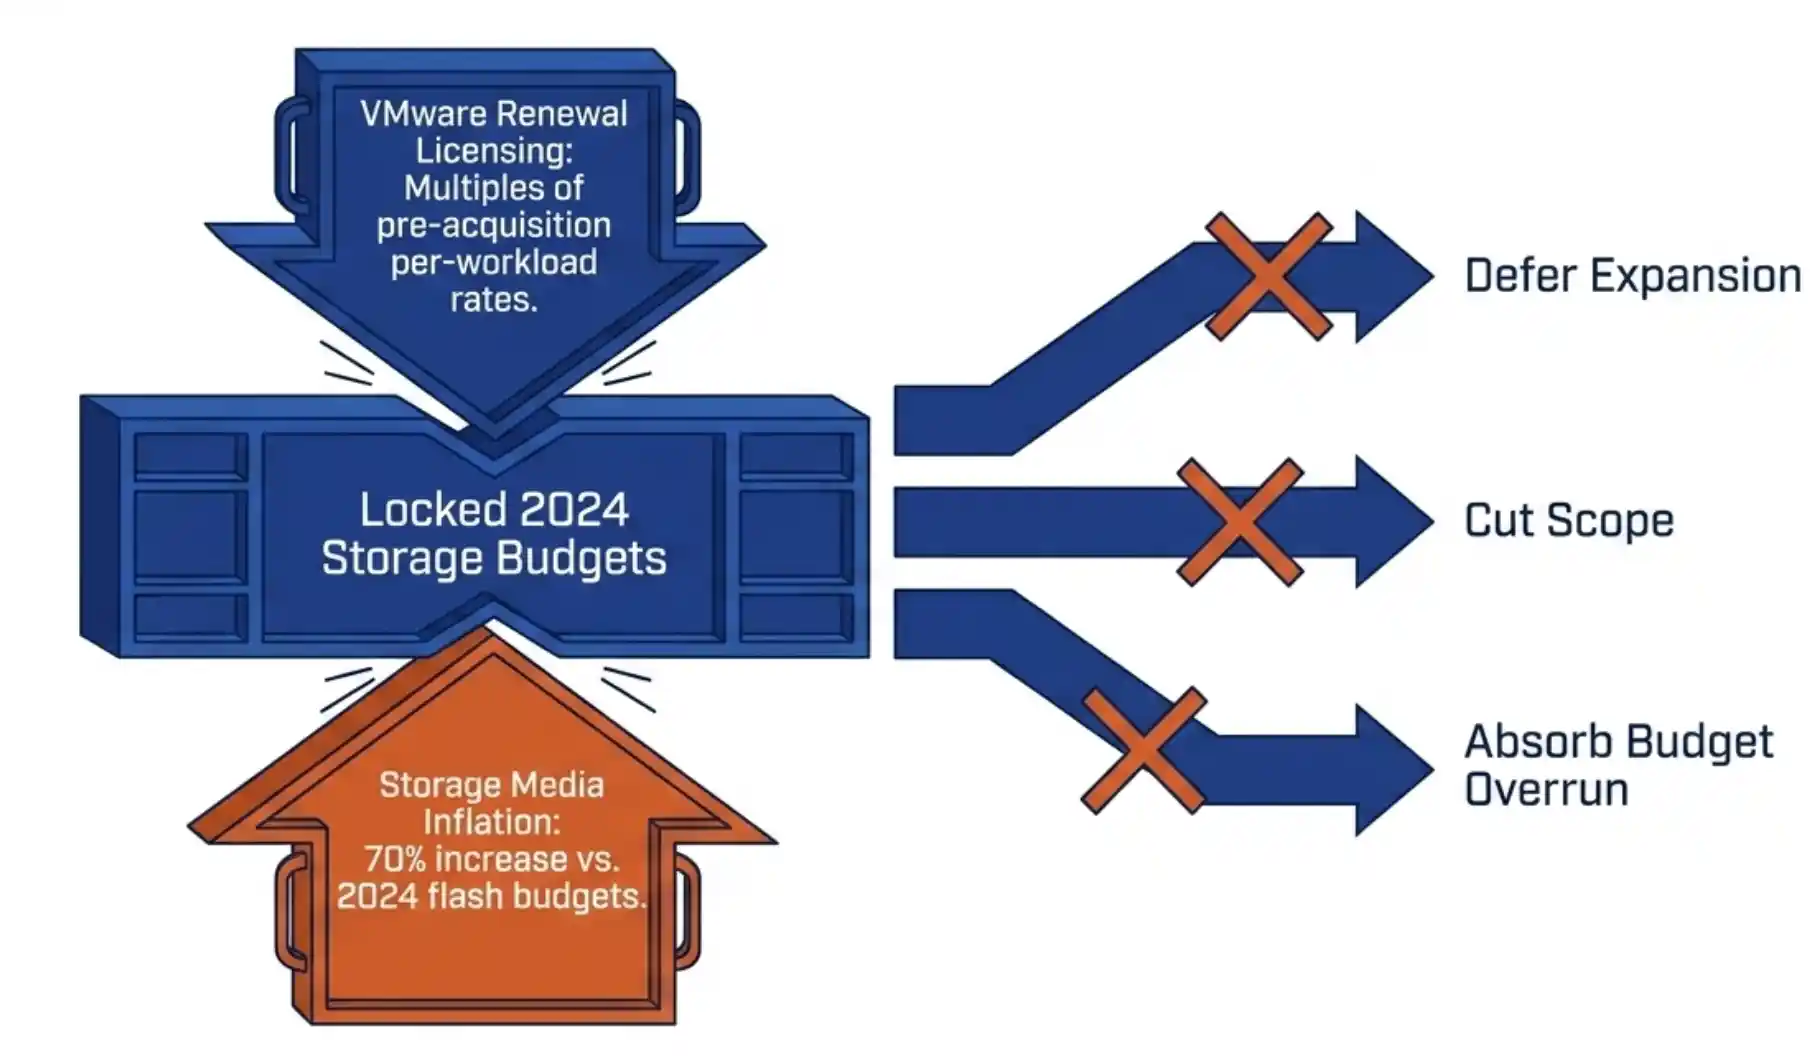
 Your 2026 SAN refresh is in trouble. Flash inflation has pushed enterprise SSD prices up 70 percent. Refresh budgets locked in 2024 are now under-funded against current list pricing. The standard responses are to defer expansion, cut scope, or absorb the cost as a budget overrun. None of those options preserve the operational plan you set last year.
A fourth option exists. Capture the original capacity expansion at 40 to 60 percent of new flash list pricing using the secondary enterprise SSD market. Run that capacity on VergeOS instead of VMware. The hardware savings fund the platform exit. The SAN refresh costs less than it would have last year. The VMware exit pays for itself.
This is not two decisions. It is one decision executed once, with the savings stacking across both line items in the budget. The procurement framework and the architecture ship together, and the financial mechanism only works when both are deployed at the same time. This dynamic has been characterized as Broadcom’s best retention tool, since the same memory and flash supercycle that pushes refresh budgets underwater also makes the migration hardware harder to fund.
Key Takeaways
Why the SAN Refresh and the VMware Exit Belong in the Same Decision
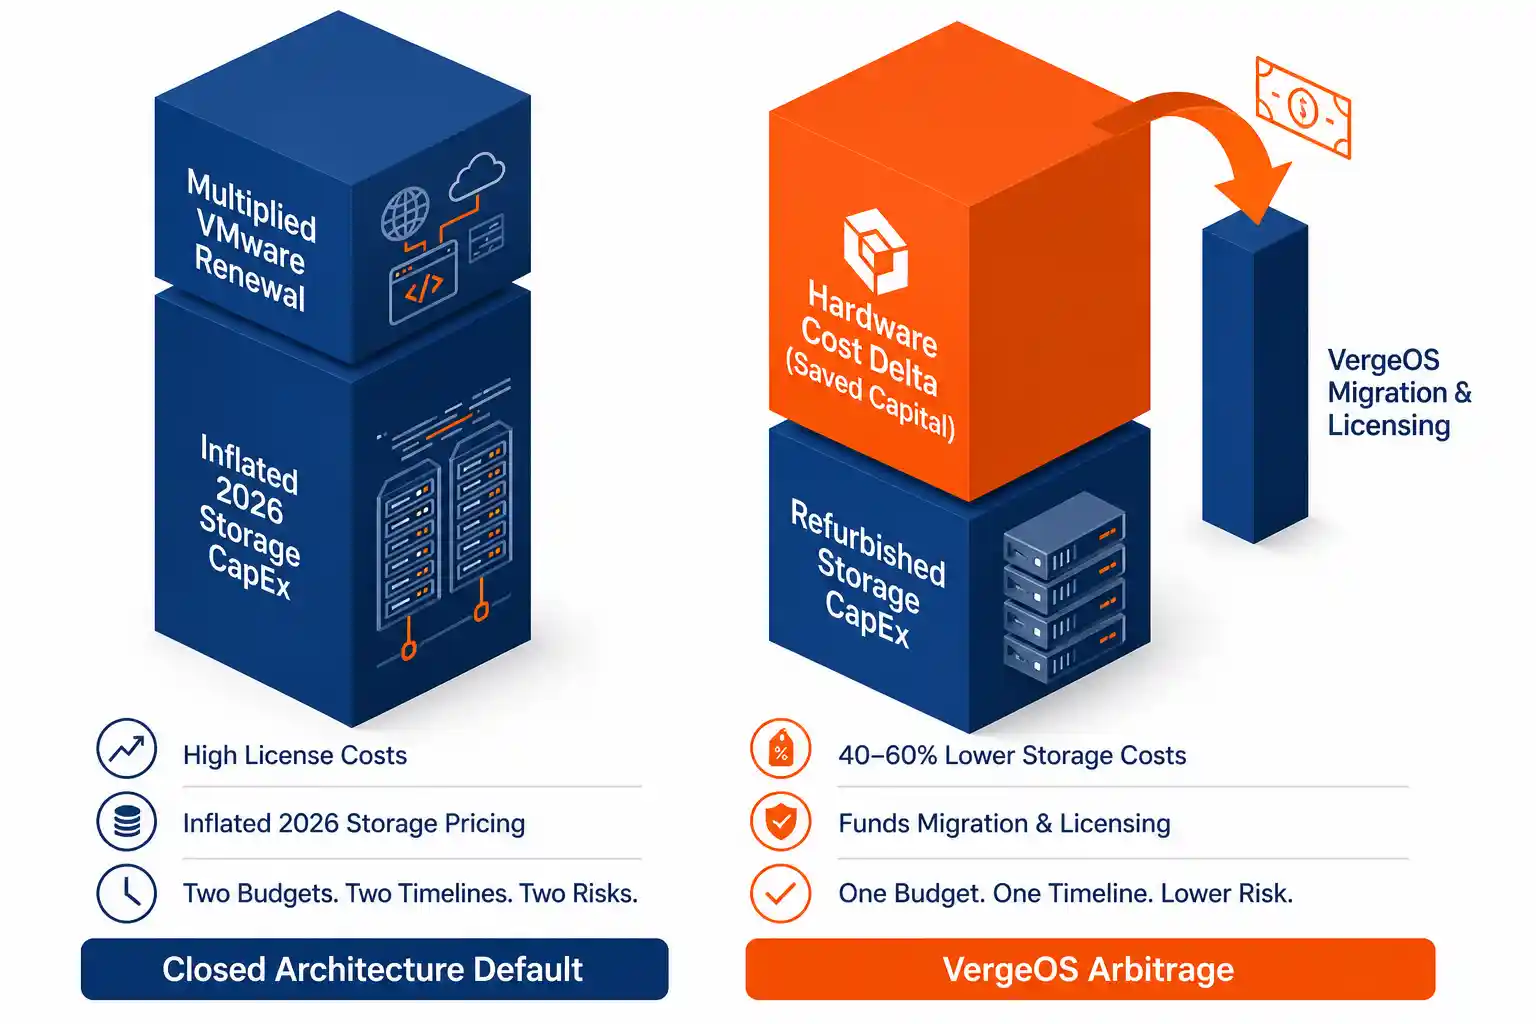 Most infrastructure teams treat their SAN refresh and their hypervisor strategy as separate problems. The SAN refresh is a procurement decision, owned by storage architects. The VMware exit is a platform decision, owned by virtualization leads and the CIO. The two budgets land in different fiscal lines, the two evaluation cycles run on different clocks, and the two vendor conversations rarely overlap.
That separation worked when storage and compute came from different vendors with different procurement paths. It does not work in 2026. VergeOS integrates storage, compute, networking, and virtualization into a single operating system. The SAN refresh and the platform exit run on the same code base, the same hardware substrate, and the same budget cycle. Treating them separately means buying two solutions where one will do.
The financial argument follows directly. A SAN refresh on VergeOS uses commodity x86 servers with refurbished enterprise SSDs at 40 to 60 percent below new flash list pricing. The capacity arrives at a fraction of the cost of a closed-architecture refresh. The hardware delta funds the VMware migration that the same cluster will host. The procurement decision and the platform decision compound into one financial outcome.
The Math: SAN Refresh Below 2025 Prices
The secondary enterprise SSD market is not a salvage market. Hyperscalers, MSPs, and Fortune 500 operators replace drives on rolling multi-year lease schedules, long before wear thresholds are met. Drives enter the secondary market with 80 to 95 percent of their rated write life remaining and 7,000 or more terabytes written endurance ratings intact. The supply is large, growing, and dominated by enterprise-grade media, not consumer drives.
The pricing math is direct. A 3.84TB enterprise SAS SSD sells new at $560 or more in current 2026 list pricing. The same drive, refurbished from a hyperscaler refresh cycle and qualified through a six-part procurement framework, sells at roughly $170. The delta is not 40 to 60 percent below 2026 list pricing. It is 40 to 60 percent below the inflated 2026 number, which means it lands competitively against what the same capacity would have cost new in 2024 or 2025.
The procurement framework is the work. R2v3 supplier qualification confirms the drives came from a certified refurbisher with serialized inventory. NIST 800-88 sanitization certificates document compliant data destruction. Fraud detection verifies retail firmware against rebadged OEM drives. SMART diagnostics baseline the seven attributes that matter. Firmware validation confirms the drive runs vendor-released code. Stress testing proves the drive holds up under sustained workload. The framework is not optional. It is the difference between a SAN refresh strategy and a coin flip.
The Math: The Migration Pays for Itself
VMware renewal pricing has made the status quo untenable for a substantial portion of the installed base. Per-workload license pricing has climbed to multiples of pre-acquisition rates. The renewal conversation is no longer about a routine increase. It is about whether the platform is worth the new contract value at all.
The standard response is to evaluate alternatives, plan a migration, and request CapEx for the destination platform. The CapEx request is the problem. New compute, new storage, and new licensing all hit the budget in the same fiscal cycle, often in the same quarter. The financial picture looks like a one-time capital event piled on top of the existing operational baseline, and procurement defers the decision rather than absorb the impact.
The arbitrage play changes the picture. The VergeOS cluster pools existing flash with newly procured refurbished enterprise drives, creating a unified storage tier that runs at a fraction of standard hardware costs. The hardware cost delta on the SAN refresh creates the budget headroom that the VMware exit needs. The migration funds itself out of the savings on the storage line item. The CapEx request becomes a near-neutral request, or in many cases a net-positive one.
Key Terms
Storage architecture in which every block is written to multiple servers simultaneously. The write acknowledges only after all replicas land, eliminating the rebuild storms and parity-calculation windows that plague closed RAID architectures.
VergeOS replication factors. RF2 keeps two synchronous copies and tolerates the loss of any one drive or host (N+1). RF3 keeps three synchronous copies and tolerates the simultaneous loss of any two drives or hosts (N+2). RF3 is the baseline for production workloads on refurbished media.
VergeOS active-service capability that absorbs concurrent failures beyond the base replication factor’s mathematical tolerance. Surviving replicas serve data at full performance during background re-replication, eliminating the secondary-failure window that turns a single hardware event into a service outage.
The Responsible Recycling Standard, version 3, governs certified refurbishment and remarketing of electronic equipment. R2v3-certified suppliers maintain serialized inventory, documented sanitization processes, and verifiable provenance, which is the procurement floor for refurbished enterprise SSDs.
The Architectural Defense: Refurbished Media Becomes a Non-Event
The financial case is strong. The architectural objection is the question that stops most CFOs from approving the play. Refurbished drives carry a statistically higher failure probability than new drives, and the last thing any infrastructure team wants is a procurement decision that turns into a 2 a.m. outage. The right response to elevated drive failure probability is not avoidance. It is architecture that absorbs the elevated failure rate without service impact.
George Crump and Aaron Richman walk the procurement framework, the architecture, and the migration sequencing in 45 minutes. Live Q&A included.
Register Now →VergeOS protects data with synchronous replication, not RAID. Every block writes to multiple servers simultaneously. The write acknowledges only after all replicas land. There is no parity calculation, no rebuild process running across surviving spindles, no extended window where a single additional failure causes data loss. RF3 on VergeOS keeps three synchronous copies of every block across separate hosts, and the architecture mathematically tolerates the simultaneous loss of any two drives or hosts.
ioGuardian extends that tolerance further. The active-service capability keeps surviving replicas running at full performance during the re-replication window, eliminating the secondary-failure exposure that turns a single hardware event into a service outage on legacy systems. One VergeOS customer ran an RF2 cluster with ioGuardian protection across six servers. During a single incident, four of the six servers went down simultaneously. RF2 mathematically tolerates exactly one host failure. The math says the cluster should have suffered catastrophic data loss. The cluster experienced zero downtime and zero data loss. ioGuardian absorbed three concurrent failures beyond the base replication factor’s tolerance.
That magnitude of architectural over-engineering renders refurbished media failure rates irrelevant. A correlated batch failure across drives from the same lease cycle is the kind of event that would destroy a parity-based RAID set. On VergeOS with RF3 and ioGuardian, the same event is absorbed without service impact. The refurbished SSD strategy is not gambling on drive quality. It is deploying capacity in an architecture that does not depend on individual drive reliability.
SAN Refresh Comparison: Closed Architecture vs. VergeOS Arbitrage
| Closed Architecture Refresh | VergeOS Arbitrage Refresh | |
|---|---|---|
| Storage media | New flash, vendor-locked modules | Refurbished enterprise SSDs, commodity hardware |
| Pricing vs. 2025 list | 70 percent above 2025 list | Below 2025 list, competitive with 2024 pricing |
| Capacity expansion target | Reduced to fit 2024 budget | Original target maintained |
| Failure protection model | Parity-based RAID with rebuild storms | Synchronous replication with N+X ioGuardian |
| Hypervisor licensing | VMware renewal at multi-fold increase | VergeOS integrated, no separate hypervisor cost |
| Migration funding | Separate CapEx request, deferred | Funded by hardware cost delta on the refresh |
The Procurement Floor: How to Qualify Suppliers Without Gambling
The architectural defense answers the technical objection. The procurement objection is the practical one. How does a storage architect actually qualify suppliers without taking a position on every drive that arrives at the loading dock? The answer is the six-part intake framework, which converts refurbished SSD purchasing from a coin flip into a repeatable process.
The framework runs in sequence. R2v3 certification verifies the supplier’s chain of custody and serialized inventory. NIST 800-88 sanitization certificates confirm compliant data destruction on the drives entering the data center. Fraud detection verifies matching serials and retail firmware against rebadged OEM drives. SMART diagnostics baseline the seven attributes that matter for endurance and reliability. Firmware validation confirms the drives run vendor-released code, not modified or counterfeit firmware. Stress testing proves sustained-workload performance under realistic conditions.
The framework is the work. The savings are the reward. A SAN refresh built on this procurement floor delivers the cost advantage of the secondary market without importing the failure modes of the lower-tier suppliers, and it does so on a repeatable schedule that scales with the rest of the operational plan.
One Budget Cycle, Two Wins
The full framework. Fifteen sections covering the secondary market, the four risk categories, the six-part procurement funnel, and the VergeOS architecture that absorbs the residual risk.
Get the Paper →The 2026 storage cost crisis is real. The VMware renewal pressure is real. The combination is what makes most infrastructure teams flinch and defer. The SAN refresh that pays for the VMware exit changes the financial calculation by stacking the savings rather than running them as separate decisions.
The procurement framework qualifies the drives. The architecture absorbs the risk. The cost delta funds the migration. The refresh costs less than it would have last year. The exit pays for itself. None of the three components work in isolation. All three deployed together produce a budget outcome that no other combination of vendors can match in the current supply environment.
The May 7 webinar walks through this play with real numbers. Register for the webinar.
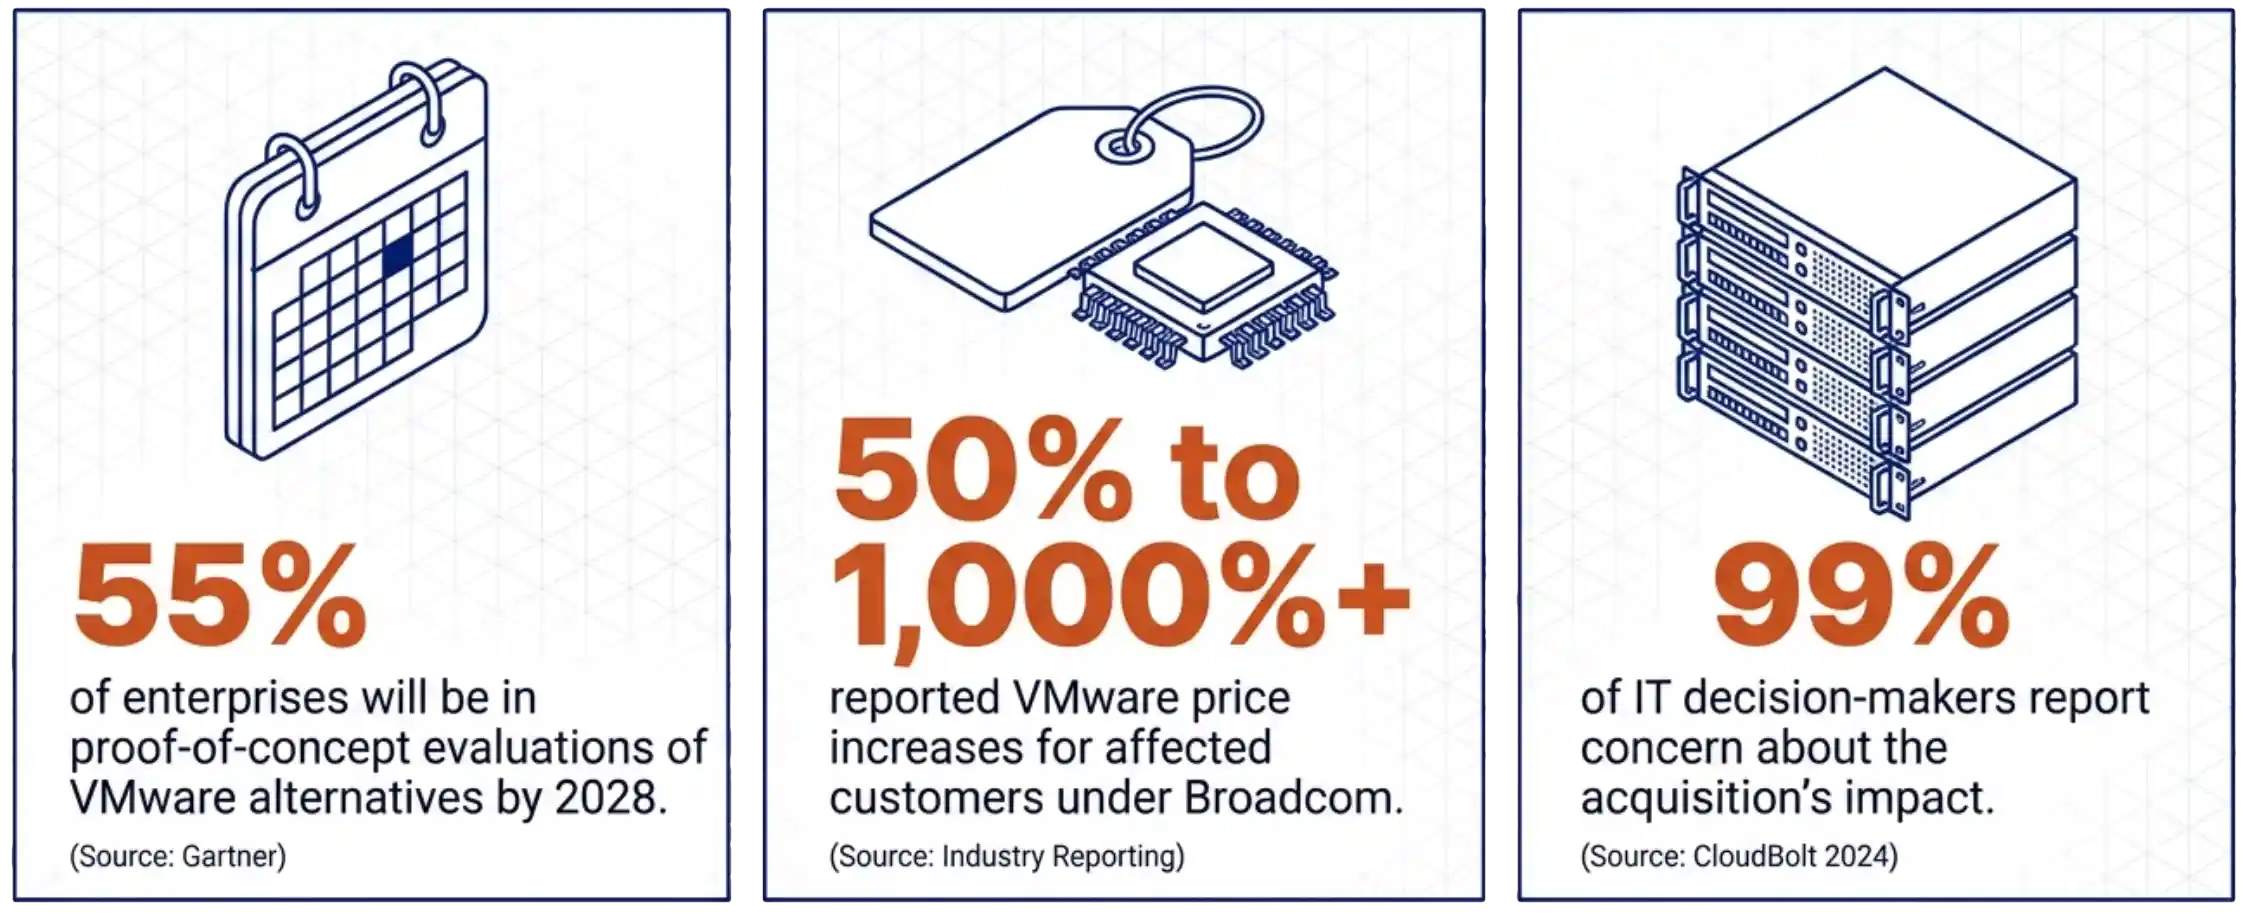 Gartner’s planning data projects that 55 percent of enterprises will be in proof-of-concept evaluations of VMware alternatives by 2028. Industry reporting on VMware price increases under Broadcom shows a range from 50 percent to over 1,000 percent for affected customers. CloudBolt’s 2024 survey found 99 percent of IT decision-makers reporting concern about the acquisition’s impact. These three numbers explain why the migration question is no longer optional for most VMware shops. They do not explain why the backup tier needs to be redesigned alongside it.
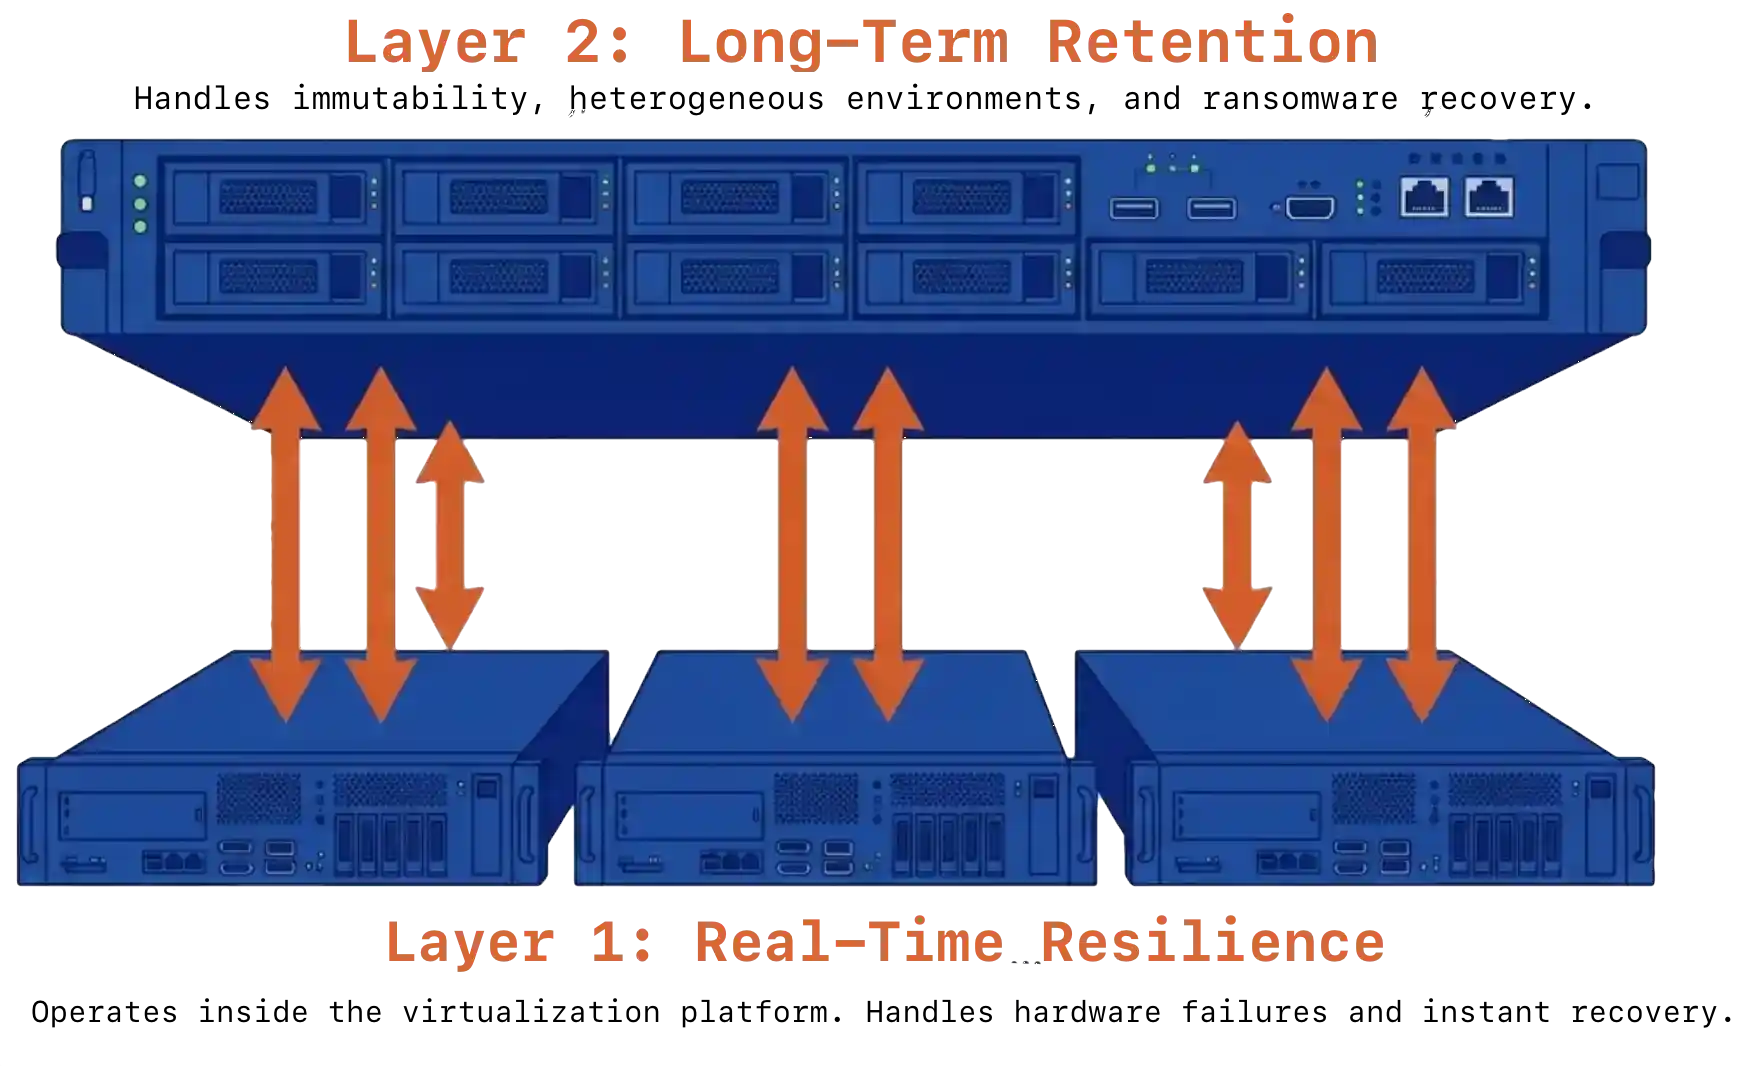 Single-product VMware exit data protection fails one of two tests. Infrastructure-only protection lives inside the virtualization platform. It handles hardware failures and operational continuity well, but offers no compliance retention, no air-gapped immutability, and limited defense against ransomware targeting the production cluster itself. Backup-only protection can take minutes to hours to recover after a hardware event and depends entirely on backup scheduling for meaningful protection.
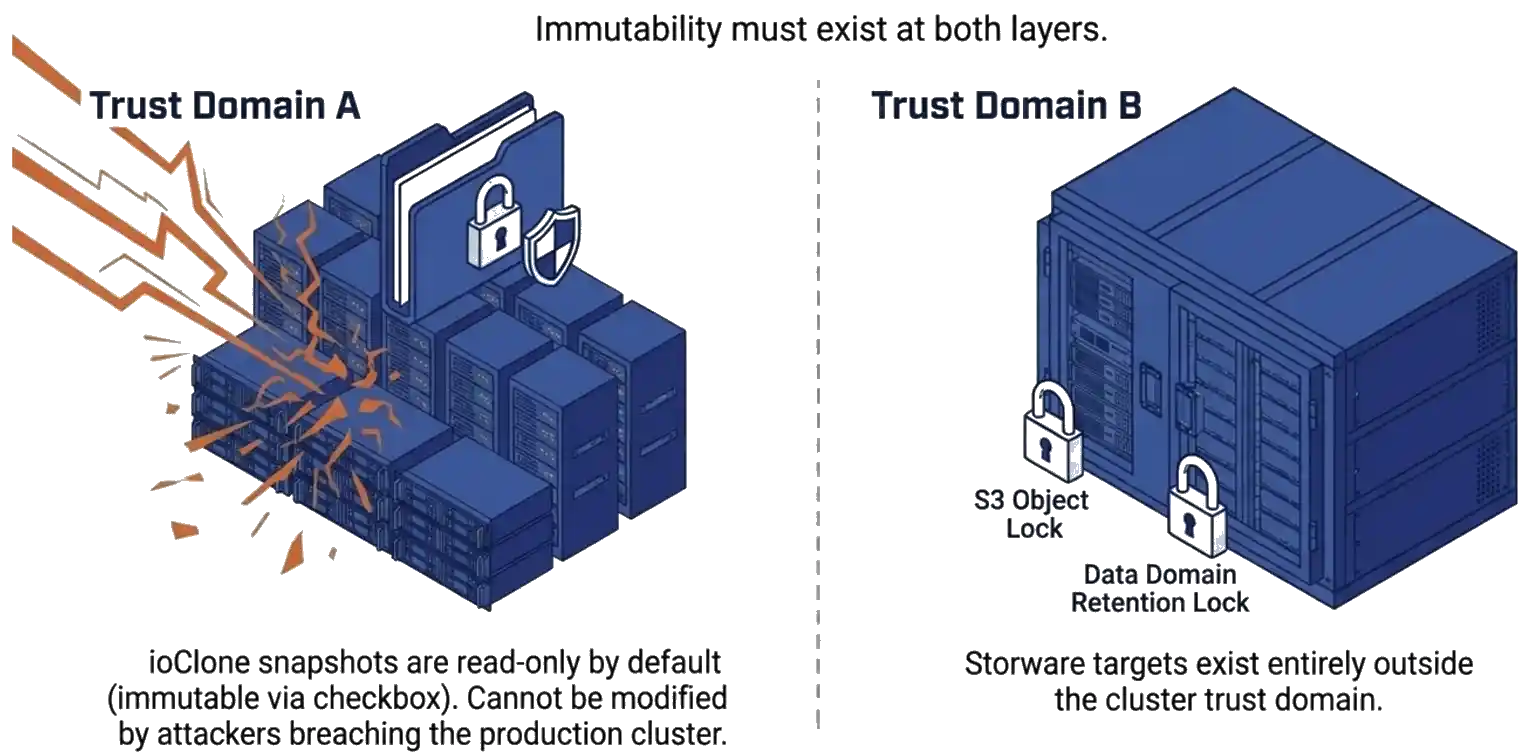 The numbers point to a single architectural answer. A backup that lives in the same trust domain as production has been compromised by definition once an attacker reaches the production system. Immutability has to exist at both layers. ioClone snapshots inside VergeOS are read-only by default and can be set to immutable by checking a box. As a result, they cannot be modified by an attacker who reaches the production cluster. Storware adds immutable storage targets, such as S3 Object Lock and Data Domain Retention Lock, outside the cluster trust domain. Recovery from in-cluster snapshots is near-instant. Recovery from the Storware tier is slower but provides the long-term retention horizon for compliance and forensic analysis.
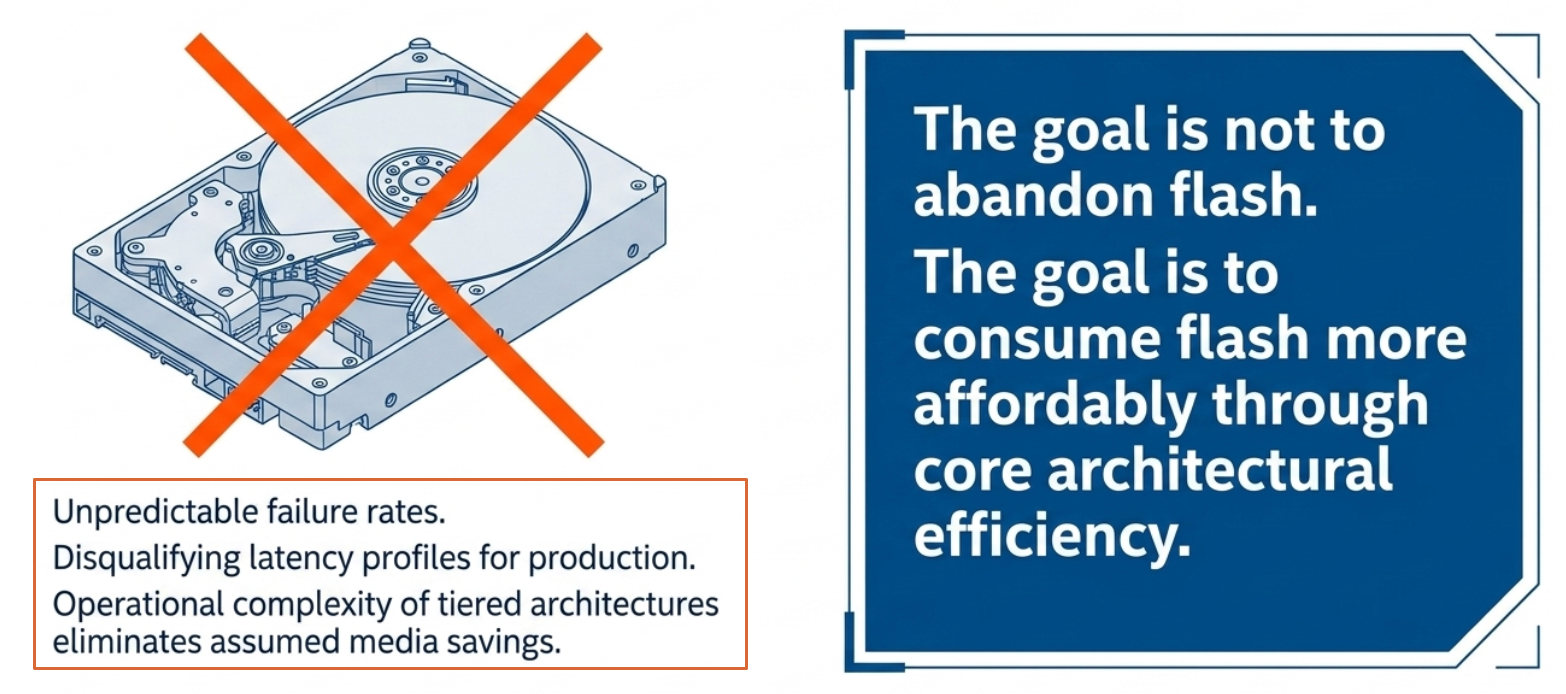 Before addressing what organizations should do, it is worth being direct about what they should not do. Rising all-flash array cost in 2026 does not make hard drives a compelling alternative. HDDs fail unpredictably, carry latency profiles that disqualify them from most production workloads, and the operational complexity of managing a tiered architecture dependent on spinning media eliminates whatever savings the lower media cost implies. There is a reason IT moved to all-flash in the first place. The goal is not to abandon flash — it is to consume flash more affordably. Three architectural decisions determine whether that is possible.
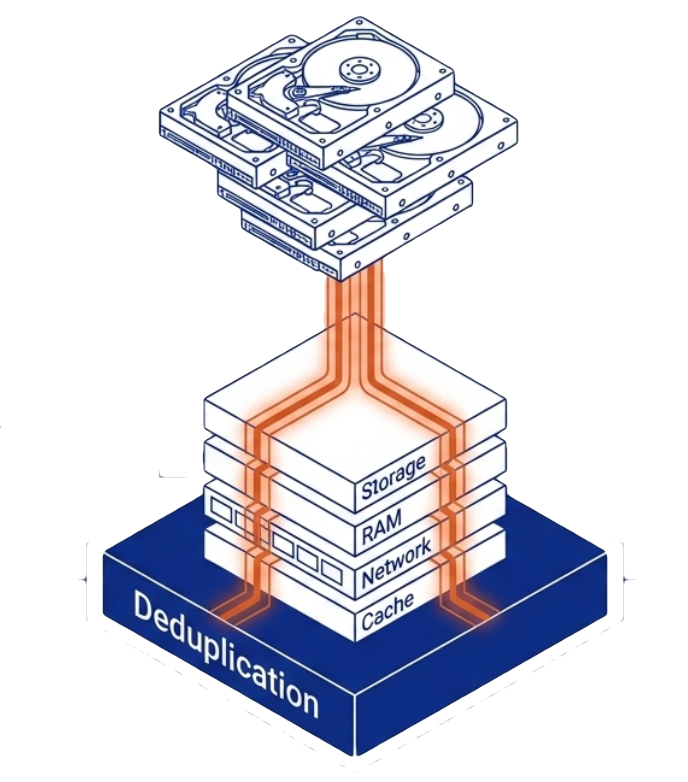 VergeOS takes a fundamentally different approach. Deduplication is not a feature that runs on stored data after the fact. It is built directly into the VergeOS operating system and runs permanently across the entire environment — cache, network, RAM, and storage — as a core function. A single copy of any block exists in the cluster regardless of how many virtual machines reference it, and that deduplication applies from the moment data is written rather than as a background cleanup pass.
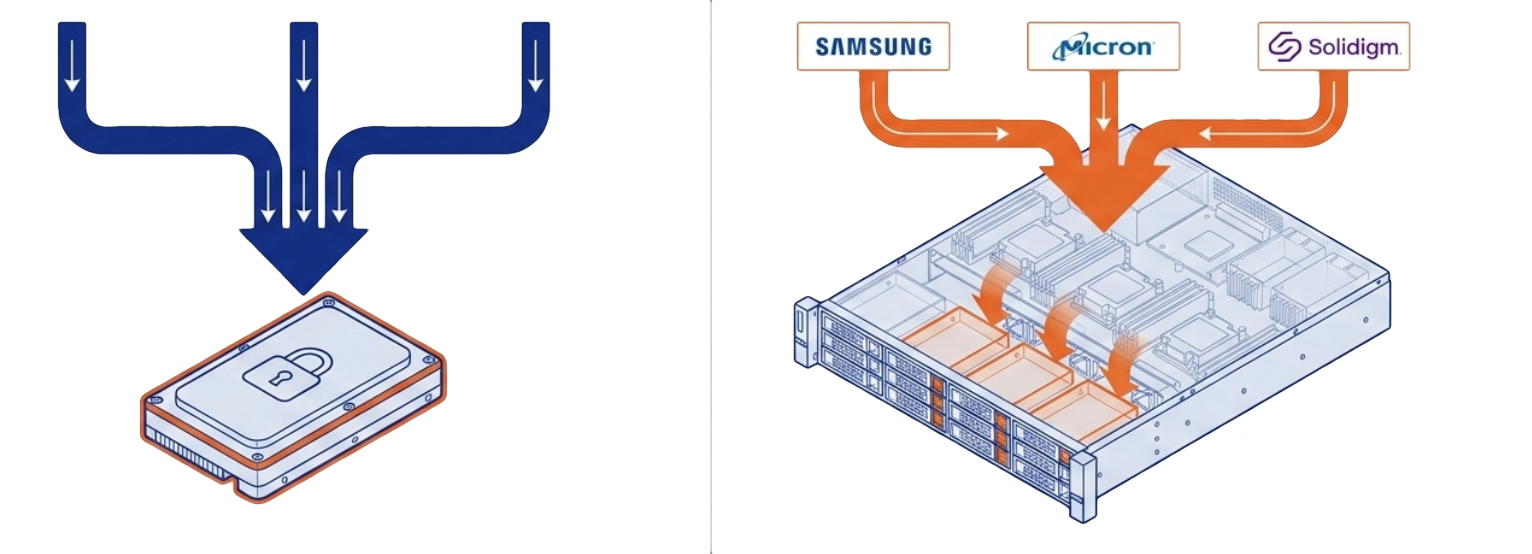 Everpure’s FlashArray and FlashBlade platforms accept only DirectFlash Modules — a proprietary media format that Everpure itself manufactures. Customers cannot source capacity from any other vendor. When component costs surge 300 to 900 percent, a storage platform that accepts media from only one manufacturer has no alternative sourcing path and no way to manage all-flash array cost exposure. The closed architecture that delivered engineering elegance in a declining-price market becomes a one-way pricing funnel when supply inverts.
 That plan made sense in 2024. The renewal was expensive but predictable — Broadcom had only completed the acquisition a year earlier, many organizations still had time remaining on existing contracts, and buying one more year to evaluate alternatives was a reasonable call. The servers were a known quantity. The budget math was uncomfortable but manageable. What changed is not the plan — it is the price of executing it. The two line items that seemed controllable have both moved against you at the same time, and the combined number no longer looks like buying time. It looks like paying a premium to stay on a platform you have already decided to leave.
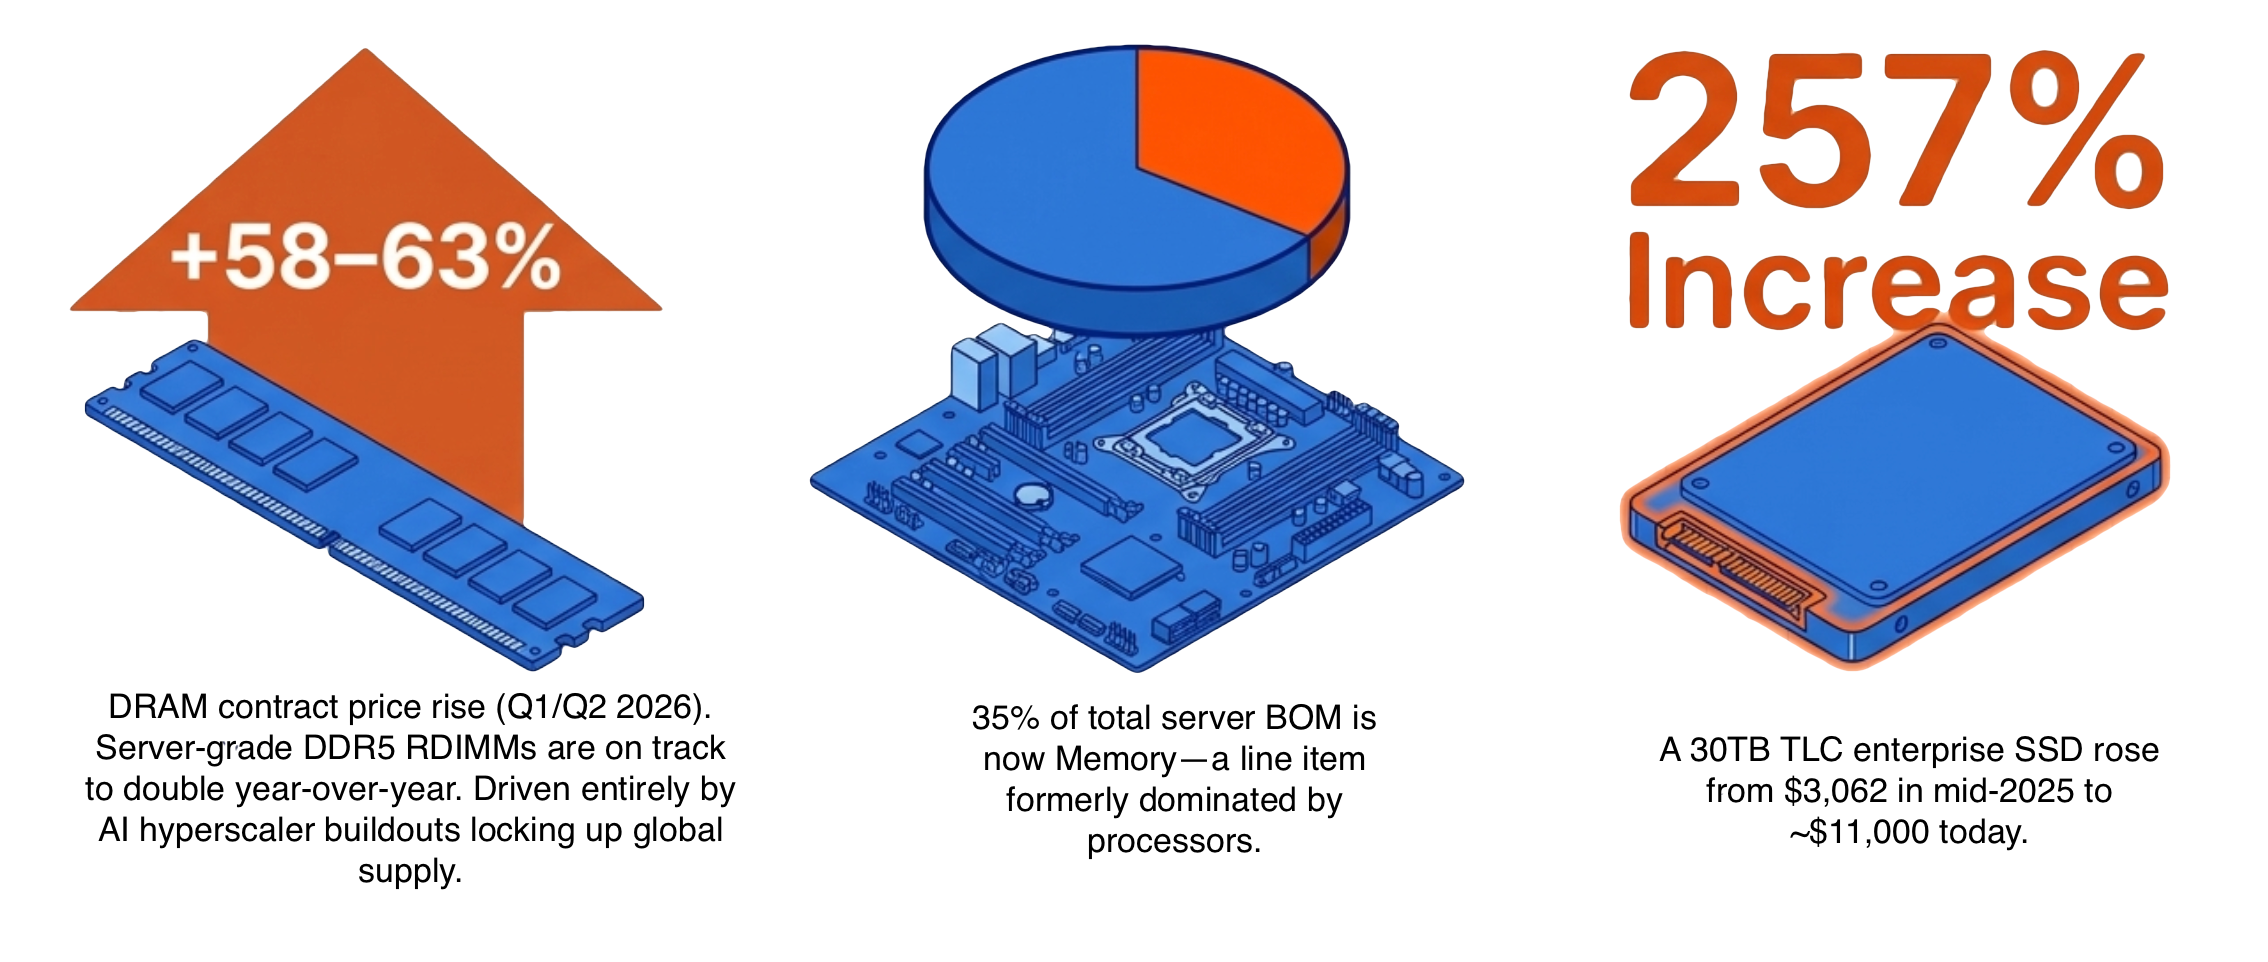 The server market shifted in late 2024 and has not corrected. DRAM contract prices rose 58–63% quarter over quarter in the first half of 2026, driven by AI infrastructure buildout at the hyperscaler level that locked up supply before enterprise buyers could compete. This cycle has been characterized as a
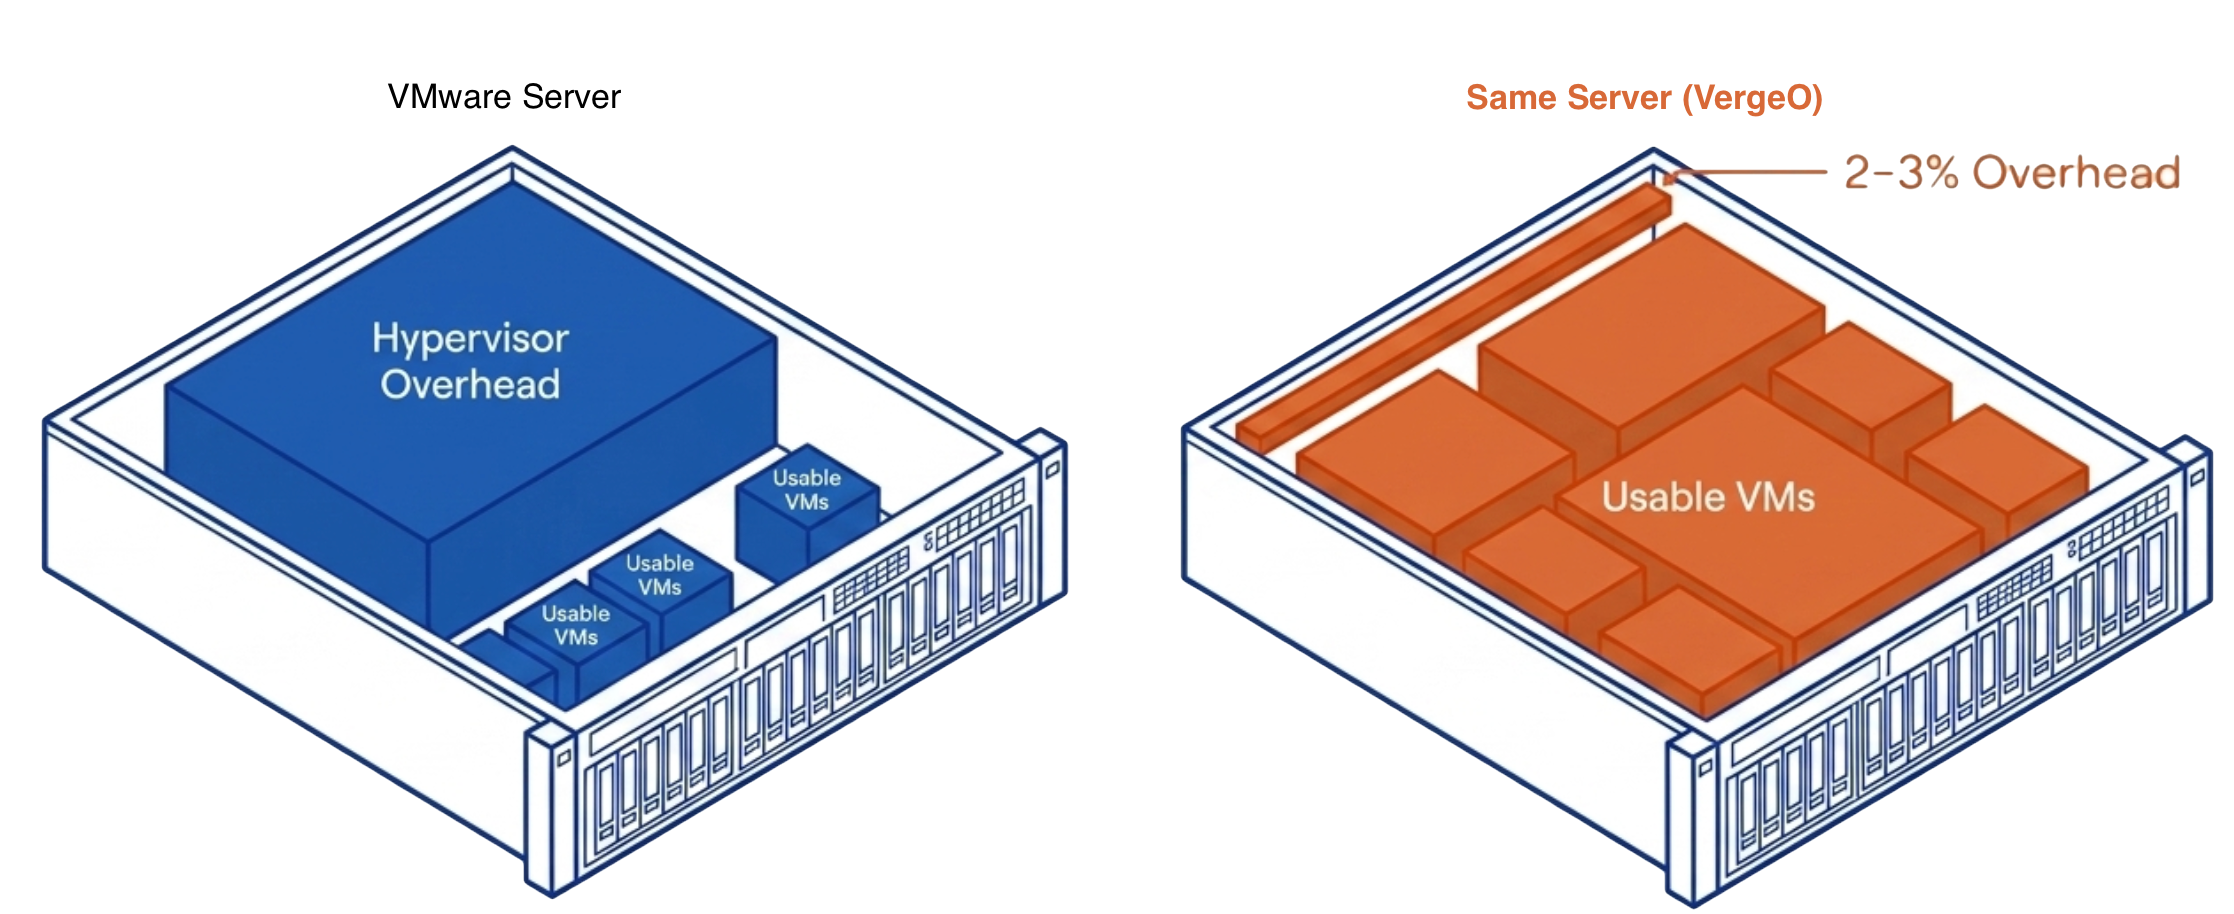 VergeOS changes the math at every layer where the conventional path breaks down. The starting point is hardware: VergeOS installs on any x86 server already in the data center. The servers the organization was planning to buy are no longer required. The $40,000 nodes, the three-to-six-month lead times, the OEM quote that expires before the purchase order clears — none of that applies. The migration starts on the day the organization decides to move, on hardware already powered on and already running workloads.
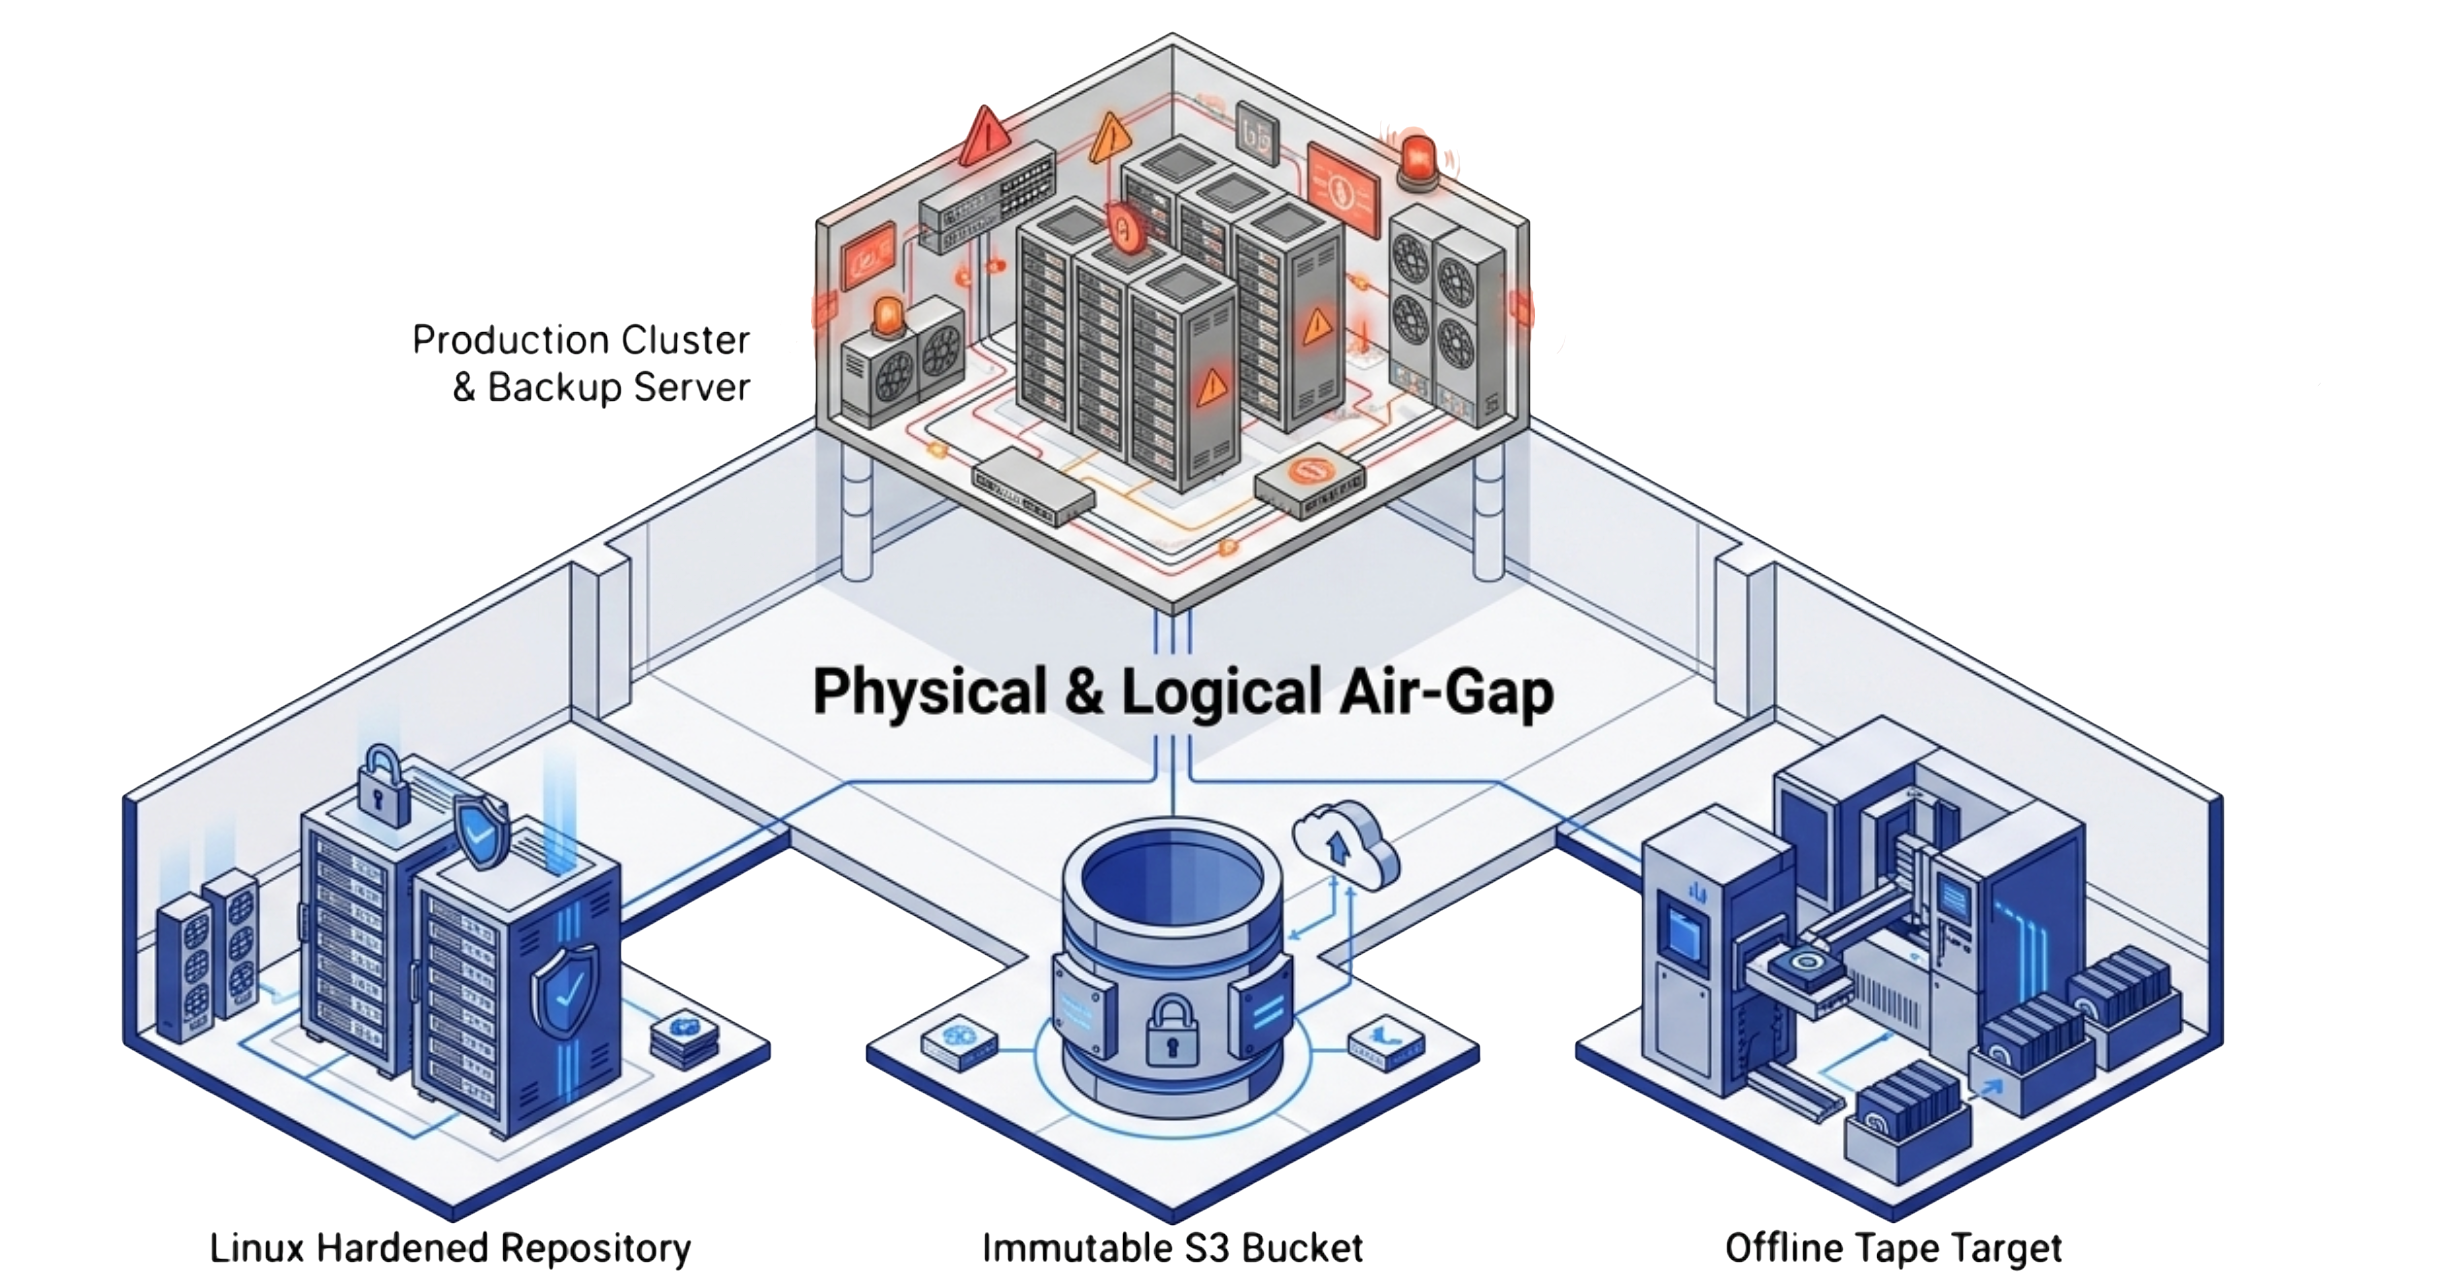 The organizations now leaving VMware face a compounding version of this problem. They are replacing their hypervisor, re-architecting their storage, and migrating workloads to new infrastructure. During that transition, the backup and recovery layer has to keep working. Not after the migration finishes. Not once the new platform stabilizes. Right now, while everything is in motion.
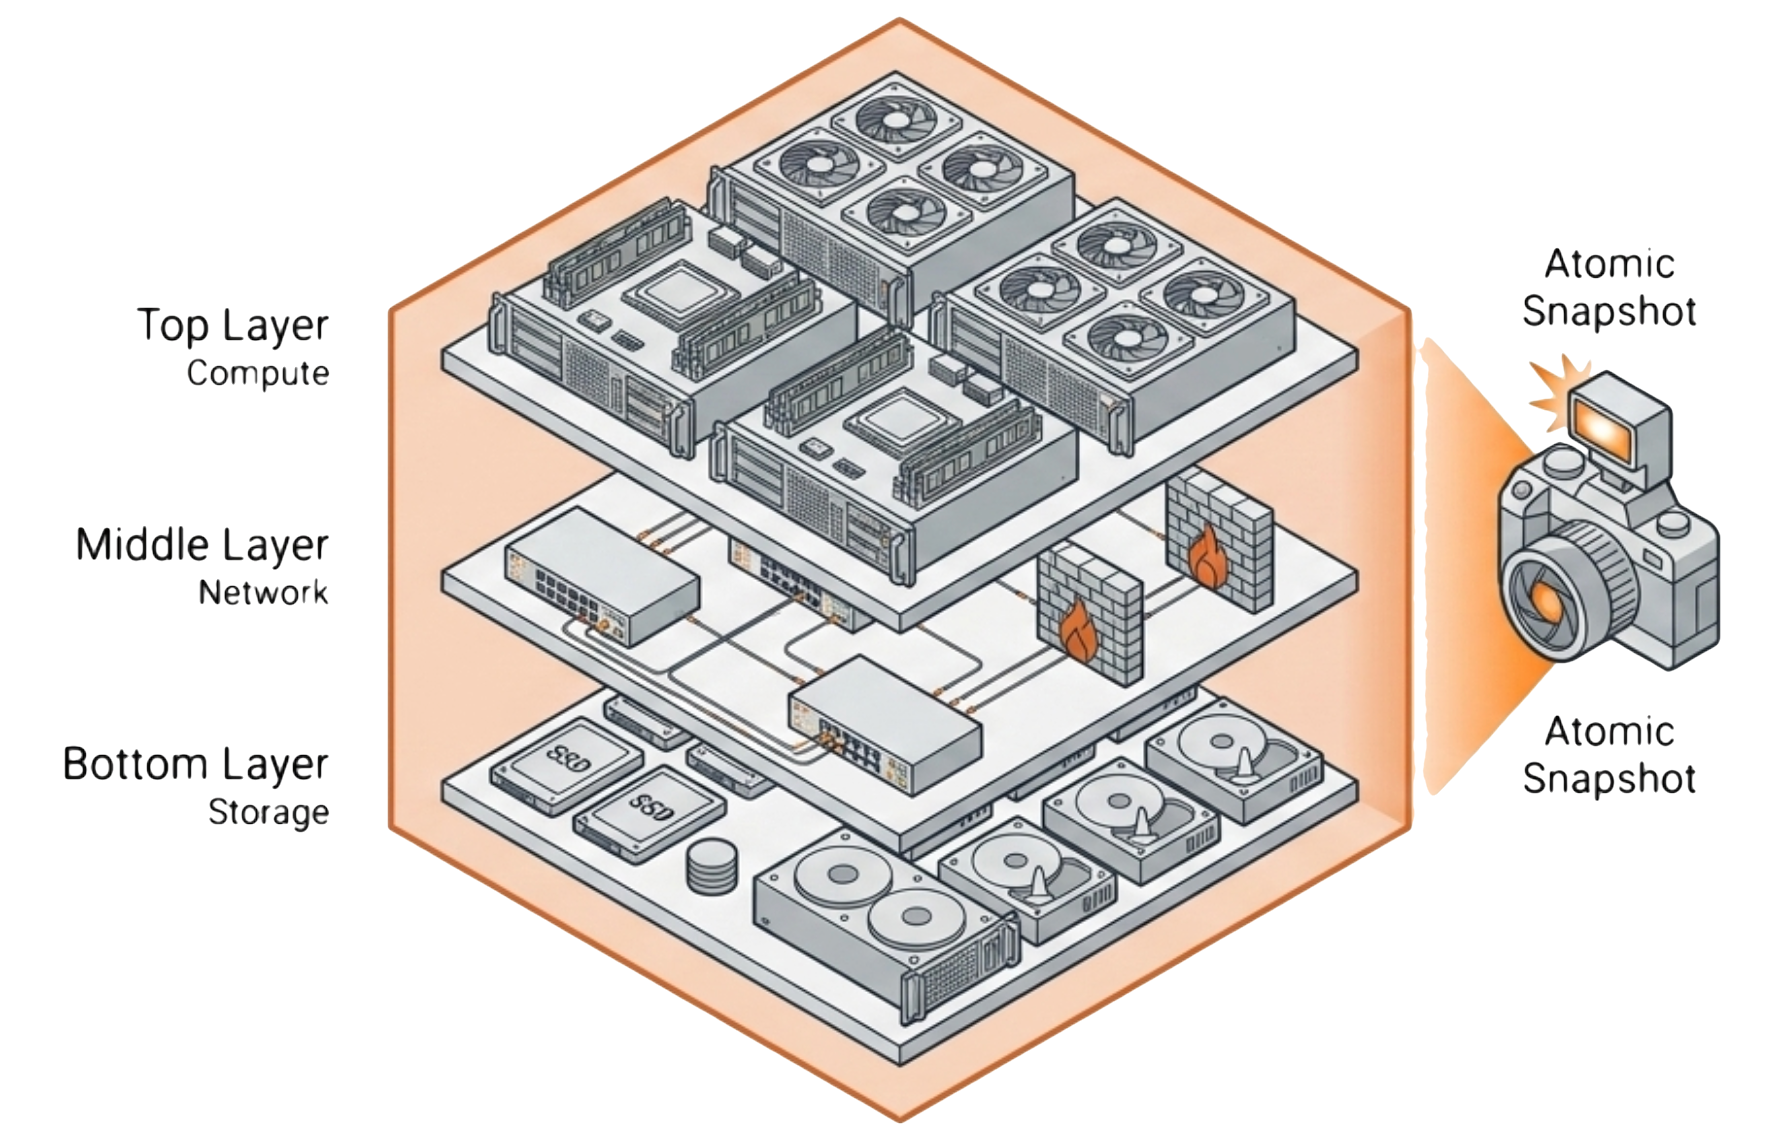 Its architecture treats entire virtual data centers as objects, complete with compute, storage, networking, and security policy. A snapshot of that object captures the full state of every VM, every virtual network, and every firewall rule in a single, atomic operation. Rolling back to that snapshot restores the entire environment to a known-good state in seconds, not hours. Traditional recovery workflows require administrators to identify affected VMs, locate clean backup copies, verify those copies, and restore them one at a time — a process that takes hours in a best-case scenario and days in a realistic one. VergeOS compresses that timeline by operating at a higher level of abstraction.
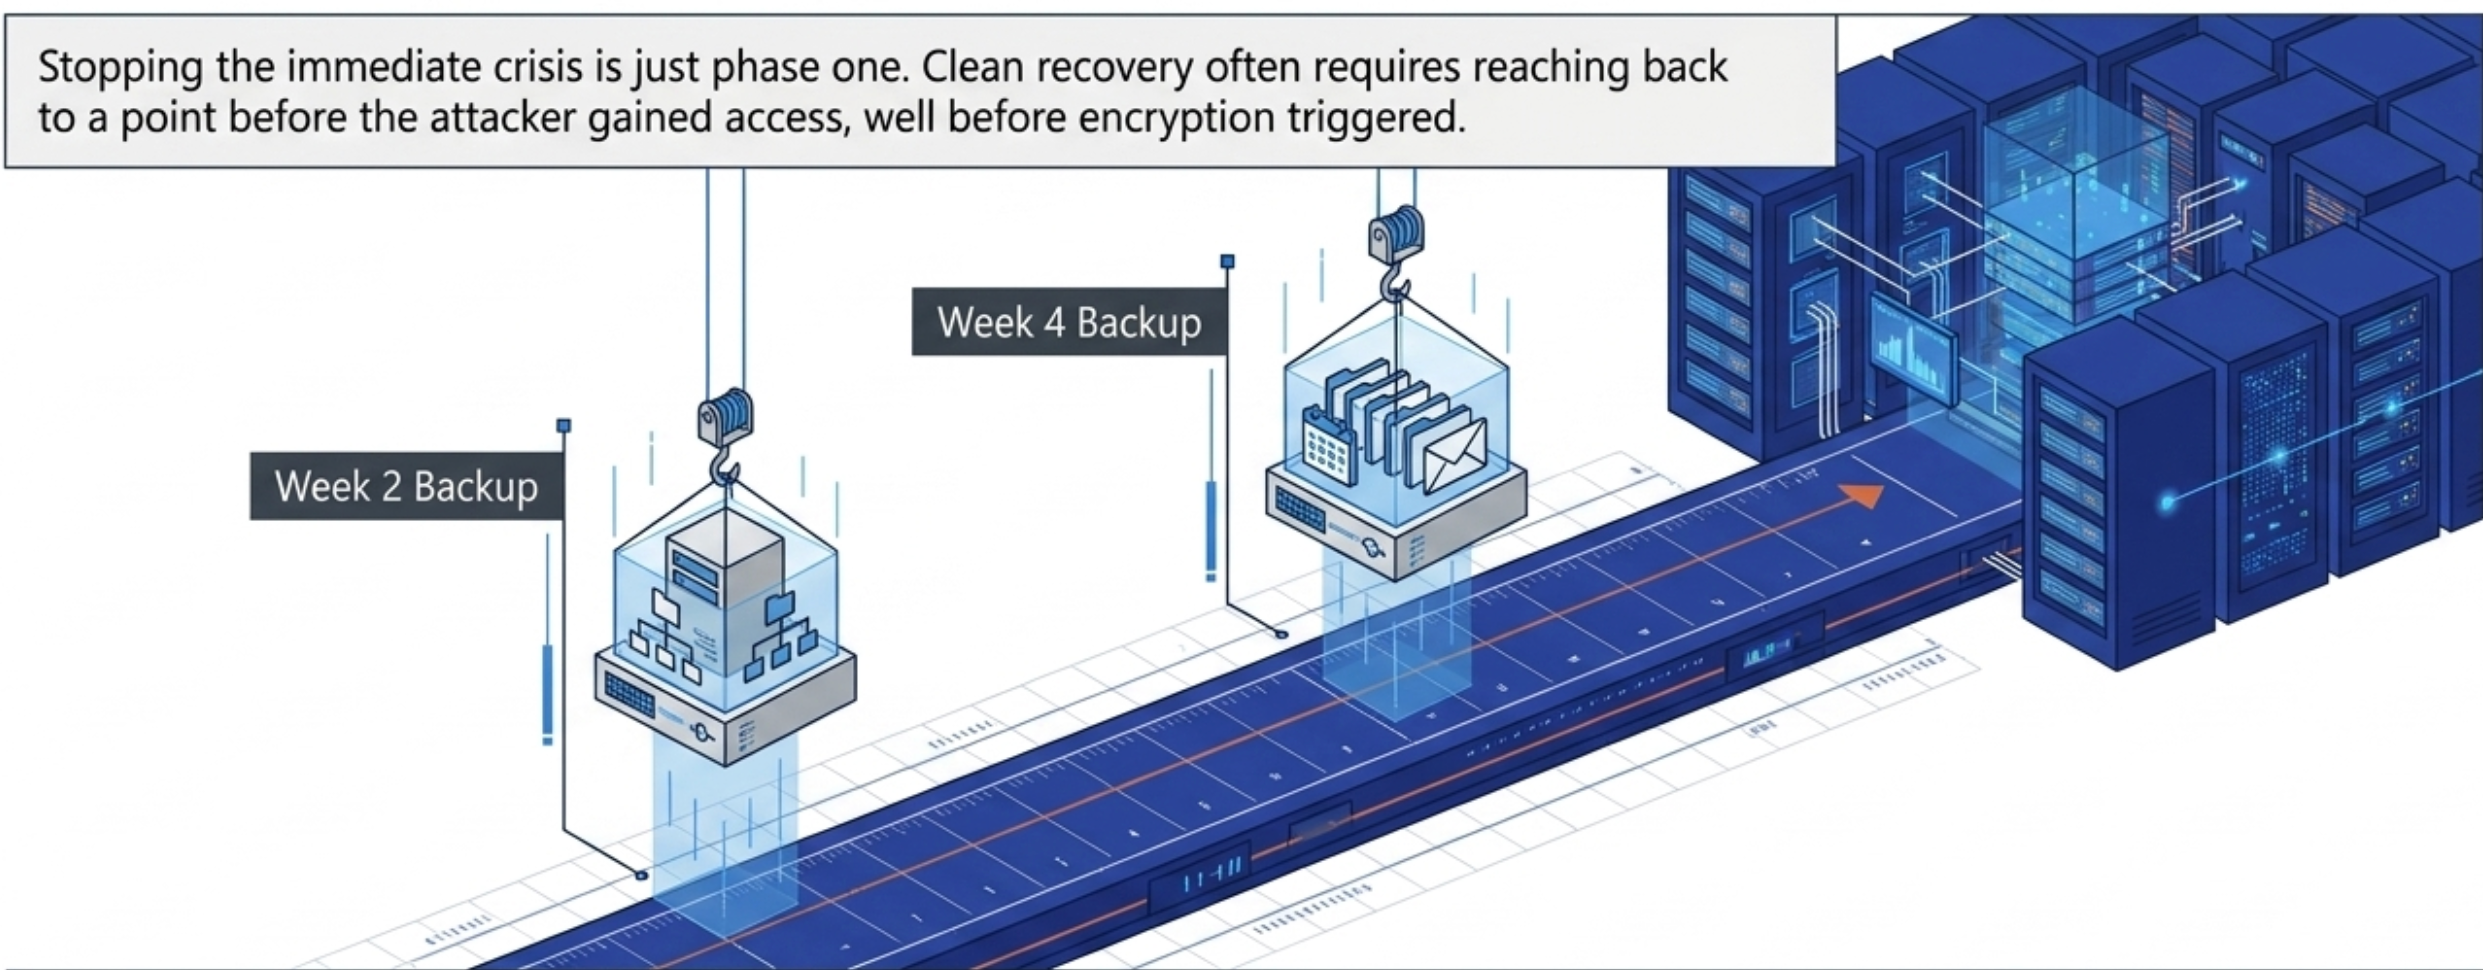 Stopping the immediate crisis is only the beginning. The weeks and months after a disaster bring a different set of demands that require a dedicated backup platform. This is where Veeam carries the load — and where the VMware alternative DR posture built on VergeOS and Veeam goes well beyond what a platform-only approach can deliver.
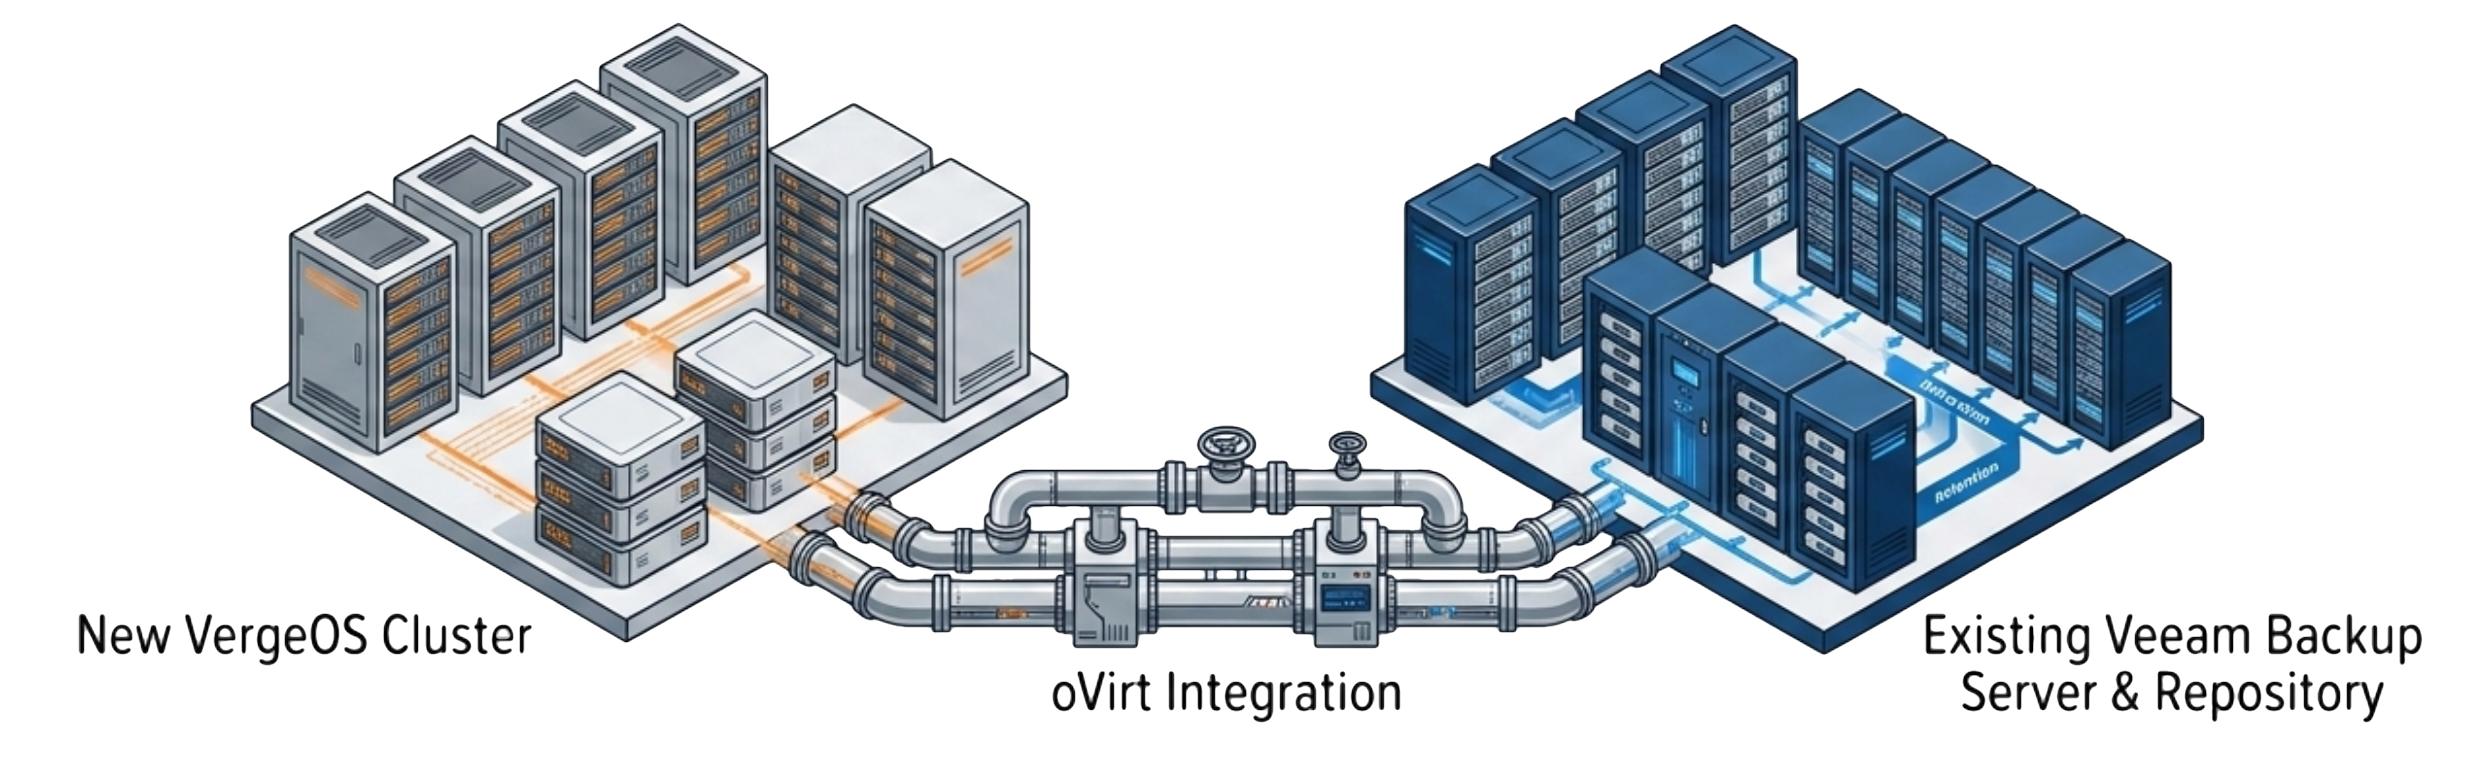 VergeOS’s oVirt compatibility preserves existing Veeam investments through the migration. Backup jobs, retention policies, and repository configurations carry forward to the new platform without modification. Organizations do not have to rebuild their backup infrastructure or retrain their operations teams.
 Veeam is a leading example of this in practice. Veeam’s oVirt driver connects to VergeOS 26.1.2 with no modifications and no custom code. The integration deploys in under an hour and runs at full production scale from day one. For any organization running Veeam as its backup standard, VergeOS is immediately compatible.