• Skip to main content
  • Architecture
    • Overview
      Learn about VergeOS’ unique unfied architecture that integrates virtualization, storage, networking, AI, backup and DR into a single data center operating system
    • Infrastructure Wide Deduplication
      VergeOS transforms deduplication from a storage-only commodity into a native, infrastructure-wide capability that spans storage, virtualization, and networking, eliminating hidden resource taxes
    • VergeFS
      VergeFS is a distributed, high-performance global file system integrated into VergeOS, unifying storage across nodes, tiers, and workloads while eliminating the need for external SANs
    • VergeFabric
      VergeFabric is VergeOS’s integrated virtual networking layer, delivering high-speed, low-latency communication across nodes while eliminating the complexity of traditional network configurations.
    • Infrastructure Automation
      VergeOS integrates Packer, Terraform, and Ansible to deliver an end-to-end automation pipeline that eliminates infrastructure drift and enables predictable, scalable deployments.
    • VergeIQ
      Unlock secure, on-premises generative AI—natively integrated into VergeOS. With VergeIQ, your enterprise gains private AI capabilities without the complexity, cloud dependency, or token-based pricing.
  • Features
    • Virtual Data Centers
      A VergeOS Virtual Data Center (VDC) is a fully isolated, self-contained environment within a single VergeOS instance that includes its own compute, storage, networking, and management controls
    • High Availability
      VergeOS provides a unified, easy-to-manage infrastructure that ensures continuous high availability through automated failover, storage efficiency, clone-like snapshots, and simplified disaster recovery
    • ioClone
      ioClone utilizes global inline deduplication and a blockchain-inspired file system within VergeFS to create instant, independent, space-efficient, and immutable snapshots of individual VMs, volumes, or entire virtual data centers.
    • ioReplicate
      ioReplicate is a unified disaster-recovery solution that enables simple, cost-efficient DR testing and failover via three‑click recovery of entire Virtual Data Centers—including VMs, networking, and storage.
    • ioFortify
      ioFortify creates immutable, restorable VDC checkpoints and provides proactive ransomware detection with instant alerts for rapid recovery and response.
    • ioMigrate
      ioMigrate enables large-scale VMware migrations, automating the rehosting of hundreds of VMs (including networking settings) in seconds with minimal downtime by seamlessly transitioning entire VMware environments onto existing hardware stacks.
    • ioProtect
      ioProtect offers near-real-time replication of VMware VMs—including data, network, and compute configurations—to a remote disaster‑recovery site on existing hardware, slashing DR costs by over 60% while supporting seamless failover and testing in an efficient, turnkey VergeOS Infrastructure.
    • ioOptimize
      ioOptimize leverages AI and machine learning to seamlessly integrate new and old hardware and automatically migrate workloads from aging or failing servers.
    • ioGuardian
      ioGuardian is VergeIO’s built-in data protection and recovery capability, providing near-continuous backup and rapid VM recovery during multiple simultaneous drive or server failures.
  • IT Initiatives
    • VMware Alternative
      VergeOS offers seamless migration from VMware, enhancing performance and scalability by consolidating virtualization, storage, and networking into a single, efficient platform.
    • Hyperconverged Alternative
      VergeIO’s page introduces ultraconverged infrastructure (UCI) via VergeOS, which overcomes HCI limitations by supporting external storage, scaling compute and storage independently, using existing hardware, simplifying provisioning, boosting resiliency, and cutting licensing costs.
    • SAN Replacement / Storage Refresh
      VergeIO’s storage by replacing aging SAN/NAS systems within its ultraconverged infrastructure, enhancing security, scalability, and affordability.
    • Infrastructure Modernization
      Legacy infrastructure is fragmented, complex, and costly, built from disconnected components. VergeOS unifies virtualization, storage, networking, data protection, and AI into one platform, simplifying operations and reducing expenses.
    • Secure Research Computing
      VergeIO's Secure Research Computing solution combines speed, isolation, compliance, scalability, and resilience in a cohesive platform. It’s ideal for institutions needing segmented, compliant compute environments that are easy to deploy, manage, and recover.
    • Venues, Remote Offices, and Edge
      VergeOS delivers resiliency and centralized management across Edge, ROBO, and Venue environments. With one platform, IT can keep remote sites independent while managing them all from a single pane of glass.
  • Blog
      • VMware Migration Testing Is Critical to Completing Your ExitVMware migration testing decides whether your exit finishes. VergeOS keeps the VMware image, takes instant snapshots and isolates each workload in a VDC.
      • How to Use Hard Drive Tiering to Fight Data Center InflationHard drive tiering is back. See how VergeOS lets you pick each drive's tier, move it live, and put the long tail on $56/TB disk instead of $706/TB flash.
      • Leave No VM BehindA complete VMware migration includes clustered SQL Server. VergeOS 26.2 shortens cutover and protects critical workloads inside isolated VDCs.
    • View All Posts
  • Resources
    • Become a Partner
      Get repeatable sales and a platform built to simplify your customers’ infrastructure.
    • Technology Partners
      Learn about our technology and service partners who deliver VergeOS-powered solutions for cloud, VDI, and modern IT workloads.
    • White Papers
      Explore VergeIO’s white papers for practical insights on modernizing infrastructure. Each paper is written for IT pros who value clarity, performance, and ROI.
    • In The News
      See how VergeIO is making headlines as the leading VMware alternative. Industry analysts, press, and partners highlight our impact on modern infrastructure.
    • Press Releases
      Get the latest VergeOS press releases for news on product updates, customer wins, and strategic partnerships.
    • Case Studies
      See how organizations like yours replaced VMware, cut costs, and simplified IT with VergeOS. Real results, real environments—no fluff.
    • Webinars
      Explore VergeIO’s on-demand webinars to get straight-to-the-point demos and real-world infrastructure insights.
    • Documents
      Get quick, no-nonsense overviews of VergeOS capabilities with our datasheets—covering features, benefits, and technical specs in one place.
    • Videos
      Watch VergeIO videos for fast, focused walkthroughs of VergeOS features, customer success, and VMware migration strategies.
    • Technical Documentation
      Access in-depth VergeOS technical guides, configuration details, and step-by-step instructions for IT pros.
  • How to Buy
    • Schedule a Demo
      Seeing is believing, set up a call with one of our technical architects and see VergeOS in action.
    • Versions
      Discover VergeOS’s streamlined pricing and flexible deployment options—whether you bring your own hardware, choose a certified appliance, or run it on bare metal in the cloud.
    • Test Drive – No Hardware Required
      Explore VergeOS with VergeIO’s hands-on labs and gain real-world experience in VMware migration and data center resiliency—no hardware required
  • Company
    • About VergeIO
    • Support
      Get fast, expert help from VergeIO’s support team—focused on keeping your infrastructure running smoothly.
    • Careers
      Join VergeIO and help reshape the future of IT infrastructure. Explore open roles and growth opportunities.
  • 855-855-8300
  • Contact
  • Search
  • 855-855-8300
  • Contact
  • Search
  • Architecture
    • Overview
    • VergeFS
    • VergeFabric
    • Infrastructure Automation
    • VergeIQ
  • Features
    • Virtual Data Centers
    • High Availability
    • ioClone
    • ioReplicate
    • ioFortify
    • ioMigrate
    • ioProtect
    • ioOptimize
    • ioGuardian
  • IT Initiatives
    • VMware Alternative
    • Hyperconverged Alternative
    • SAN Replacement / Storage Refresh
    • Infrastructure Modernization
    • Secure Research Computing
    • Venues, Remote Offices, and Edge
  • Blog
  • Resources
    • Become a Partner
    • Technology Partners
    • White Papers
    • In The News
    • Press Releases
    • Case Studies
    • Webinars
    • Documents
    • Videos
    • Technical Documentation
  • How to Buy
    • Schedule a Demo
    • Versions
    • Test Drive – No Hardware Required
  • Company
    • About VergeIO
    • Support
    • Careers
×
  • Architecture
    • Overview
    • VergeFS
    • VergeFabric
    • Infrastructure Automation
    • VergeIQ
  • Features
    • Virtual Data Centers
    • High Availability
    • ioClone
    • ioReplicate
    • ioFortify
    • ioMigrate
    • ioProtect
    • ioOptimize
    • ioGuardian
  • IT Initiatives
    • VMware Alternative
    • Hyperconverged Alternative
    • SAN Replacement / Storage Refresh
    • Infrastructure Modernization
    • Secure Research Computing
    • Venues, Remote Offices, and Edge
  • Blog
  • Resources
    • Become a Partner
    • Technology Partners
    • White Papers
    • In The News
    • Press Releases
    • Case Studies
    • Webinars
    • Documents
    • Videos
    • Technical Documentation
  • How to Buy
    • Schedule a Demo
    • Versions
    • Test Drive – No Hardware Required
  • Company
    • About VergeIO
    • Support
    • Careers

ioGuardian

October 16, 2026 by George Crump

On-Demand · No Registration

How to Use HCI and Hard Drives to Fight Data Center Inflation

Watch the whole session, with every demo. No registration required.

Watch Now

Hard drive tiering moved back to the top of my list the day Dave Vincent and I priced drives to expand our lab. A 15.36 TB NVMe SSD quoted at $10,850, or about $706 per terabyte. A 24 TB Western Digital hard drive came in at $1,350, about $56 per terabyte. Flash now costs more than 12 times as much per terabyte as disk, and on October 7 Dave and I spent an hour with a record audience working through what IT teams can do about it.

Watch the whole session, with every demo, in the on-demand presentation. No registration required.

Key Takeaways
  • Data center inflation now reaches the drive bay, and putting every workload on flash has become an expensive default.
  • VergeOS sets the tier per virtual drive and moves it live, so the administrator decides placement and can reverse it in seconds.
  • Metadata on NVMe, write reordering, read prefetch and a deduplicated RAM cache make hard drives viable for the long tail of workloads.

Data Center Inflation Has Reached the Drive Bay

I love flash as much as the next guy, but I don’t love it 12 times as much. The price gap keeps widening, and I see no relief coming soon. A new fab takes at least two years to build, longer in countries with strict permitting, and the AI factories driving this demand will absorb new supply as fast as it ships.

Raw media cost, from one terabyte to a 150 TB estate, NVMe flash versus hard drives One terabyte costs about 706 dollars on NVMe flash and about 56 dollars on hard drives. Across a 150 TB estate that grows to 105,900 dollars on flash against 8,400 dollars on hard drives, 97,500 dollars less in raw media. One terabyte, then a 150 TB estate 1 TB of capacity 150 TB of capacity Raw media cost per terabyte Raw media cost for 150 TB All flash · 15.36 TB NVMe $706 $105,900 Hard drives · 24 TB HDD $56 $8,400 $97,500 less in raw media
Kioxia 15.36 TB NVMe at $10,850 against a WD 24 TB hard drive at $1,350, checked September 28, 2026. Raw media for a single copy, before redundancy.

When flash got cheaper every quarter, putting everything on it was like hitting a watermelon with a sledgehammer. It worked, and nobody questioned the bill. Back in my analyst days, friends at the all-flash array vendors told me their systems averaged under 5,000 IOPS. Most data sits idle most of the time. At today’s prices it pays to slice the watermelon, which means IT takes control of placement again.

Pick Your Tier, Then Change Your Mind

The first generation of hybrid storage relied on auto-tiering, where an algorithm decided which blocks went to disk. It moved data you wanted on flash, and undoing its choices meant scripting a touch of every file. I covered why that failed in Hybrid Storage Failed Once. Will It Fail Again? on StorageSwiss.

VergeOS hands the decision to the administrator. Each virtual drive has a preferred tier, and changing it starts a live, background migration with no reboot and no maintenance window. During the webinar Dave ran a SQL Server VM processing about 80,000 rows per second, moved its data drive from Tier 1 NVMe to Tier 5 hard drives, and moved it back. The query monitor never flinched. From the CLI, the same change took about 1.3 seconds to accept.

Hard drive tiering in VergeOS: moving a live SQL Server drive between NVMe and hard drives A SQL Server VM keeps its OS, transaction log and tempdb drives on Tier 1 NVMe. Its data drive moves from Tier 1 NVMe to Tier 5 hard drives and back while queries keep running. Preferred tier, set per virtual drive and changed live SQL Server VM OS · Tier 1 NVMe Transaction log · Tier 1 tempdb · Tier 1 NVMe Data · Tier 1 NVMe Data · Tier 5 hard drives Tier 1 · NVMe flash Tier 5 · hard drives SQL data drive Query monitor: about 80,000 rows per second, steady through both moves
The data drive moves to hard drives and back while the OS, log and tempdb stay on NVMe. The VM never stops.

That speed is what makes hard drive tiering practical. You can be aggressive, push the long tail to disk, and move a drive back to flash the moment someone complains. Dave also showed a local AI agent finding idle drives and moving them with the same CLI. If you want the cost math on a single database VM, Dave walks through it in Can HCI Run a Database Application on Hard Disk Drives?

How VergeOS Makes Hard Drives Perform

Our CTO, Greg Campbell, built most of this a decade ago, right before the industry went all-flash. VergeOS keeps all metadata on Tier 0 NVMe, so lookups never touch a spinning disk. It reorders incoming writes from many VMs into sequential streams, which is how hard drives like to work, and prefetches reads across the cluster.

How VergeOS makes hard drives perform Random writes from several VMs enter VergeOS, which sends metadata to Tier 0 NVMe and reorders the data into a sequential stream for the hard drive tier. A deduplicated RAM cache on each host serves repeat reads from memory. Random writes in, sequential writes out VM 1 VM 2 VM 3 VergeOS write reordering and read prefetch Tier 0 NVMe all metadata Hard drive tier sequential writes Host RAM cache deduplicated, next to the VM repeat reads served from memory
Metadata goes to Tier 0 NVMe, and writes from many VMs reach the hard drives as ordered, sequential streams.

Each host also keeps a RAM cache next to the VM. Global inline deduplication runs in the core code, so the cache holds no duplicate blocks and serves more of the working set from memory. Some of the performance in Dave’s demo came from that cache, and that is by design. It is why the disk tier sees far less random I/O than its raw specs suggest.

Protecting High-Capacity Drives

Hard drives fail, and so do SSDs, but a large hard drive takes longer to rebuild. VergeOS sets redundancy per system and applies it per tier. N+1 keeps two copies of every block and survives one failure. N+2 keeps three copies and survives two. A failure in the hard drive tier stays in that tier.

Frequent, deduplicated snapshots cover logical mistakes. For failures beyond the redundancy level, ioGuardian turns your DR site into a repair server. VergeOS pulls back the 64K blocks it needs from the remote copy, which avoids a rollback to a snapshot. The cost is latency on those reads. You can place a repair server in the primary data center to cut that latency, at the price of another set of drives.

ioGuardian supplies missing blocks from the DR site when drive failures exceed redundancy Three VMs each read from their own hard drive at the primary site. Two of the three drives fail, more than N+1 redundancy covers. The ioGuardian repair server at the DR site then supplies the missing 64K blocks to the two affected VMs, which keep running with added latency on those reads. ioGuardian: the DR copy doubles as a repair server Running VMs Primary site · hard drive tier, N+1 DR site · ioGuardian VM 1 Drive 1 Copy 1 VM 2 Drive 2 Copy 2 VM 3 Drive 3 Copy 3 Normal operation: each VM reads from its own drive 64K blocks Drives 2 and 3 fail, more than N+1 redundancy covers ioGuardian supplies the missing blocks from the DR site
Each VM reads from its own drive. When two drives fail, more than N+1 covers, ioGuardian at the DR site supplies the missing blocks, which avoids a rollback to a snapshot. The trade-off is latency on those reads.

What Attendees Asked

What happens on a cache miss? The read goes to the hard drive at its native speed. The sequential layout gives the drive the best possible access pattern, and the RAM cache absorbs the burst of requests, so the disk avoids hundreds of workloads hammering it at random.

How does VergeOS compare to Proxmox with Ceph? VergeOS is a single code base. You load one image and get compute, storage and networking in one product, which makes it faster to learn and run. Topgolf runs VergeOS across more than 100 venues, offices and data centers.

What server do I need for hard drives? Pick a chassis that fits the workload. That usually means a 2U server with more drive bays instead of a 1U flash-only node.

Where to Start

Pull a 30-day I/O report, find the VMs that sit idle, and set their preferred tier to hard drives. If a workload slows down, move it back.

The first step in fighting data center inflation is to avoid buying new hardware at all. VergeOS runs on the servers you already own, which also makes it the fastest path off VMware. Watch the on-demand presentation for every demo, no registration required, or book a technical whiteboard session and we will map your workloads to tiers.

Key Terms

Hard drive tiering

Placing data on hard disk drives instead of flash according to how often it is accessed.

Preferred tier

The VergeOS setting on each virtual drive that names the storage tier it should live on.

Long tail

The many workloads that generate little I/O over a 30-day period.

ioGuardian

A VergeOS repair server, usually at the DR site, that supplies missing blocks when failures exceed the redundancy level.

Frequently Asked Questions

Does moving a drive to a different tier require downtime?

The move runs in the background and the VM keeps running. Dave moved a live SQL Server data drive from NVMe to hard drives and back during the webinar.

Does VergeOS use auto-tiering?

The administrator sets the preferred tier for each virtual drive and can change it at any time, which keeps placement predictable and reversible.

Which workloads belong on hard drives?

Workloads in the long tail of a 30-day I/O report, such as file servers, ISO libraries, dev and test, backup targets and database data files with modest I/O.

Where can I watch the webinar?

The on-demand presentation includes every demo and requires no registration.
Filed Under: Storage Tagged With: flash inflation, hard disk drives, HCI, HCIandHDD, ioGuardian, Tiering, Webinar

September 29, 2026 by George Crump

Flash now costs 12 to 14 times more per terabyte than a hard drive, and that gap changes how an HCI cluster gets built.

A 24 TB hard drive sells for about $1,350 today, and a 15.36 TB enterprise NVMe SSD sells for $10,850 or more, a gap wide enough to reopen a storage decision most IT teams considered closed years ago. Dave Vincent and I ran into it this month while pricing drives for our labs, where the SSD quote came in near $12,000 and the hard drive quote barely registered by comparison.

Key Takeaways
  • At September 2026 list prices, flash costs 12 to 14 times more per terabyte than a 24 TB hard drive.
  • All-flash HCI ties every terabyte of capacity growth to the most inflated component in the data center.
  • VergeOS runs hard drives and flash in one cluster, moves running VMs between them on command, and protects the hard drive tier with frequent snapshots and ioGuardian.

The Math Behind a $10,000 SSD

These are street prices, checked on September 28, 2026, that show the gap, and they move week to week right now.

DriveCapacityPriceCost per TB
Kioxia KCMYXRUG15T3 NVMe15.36 TB$10,850$706
Solidigm D7-PS1010 NVMe15.36 TB$12,500$814
WD Ultrastar DC HC580 SATA24 TB$1,350$56

The price of one 15.36 TB SSD buys eight 24 TB hard drives, 192 TB of raw capacity for the same money. VergeIO calls this data center inflation, hardware costs rising faster than IT budgets, driven by AI demand for memory and flash. Flash and memory prices climbed 70 to 95 percent through the first half of 2026, and AI buildouts absorb new fab capacity as fast as it comes online. I plan as if this pricing is permanent.

24 TB hard drive versus 15.36 TB SSD, cost per terabyte Kioxia 15.36 TB NVMe SSD at $706 per TB, Solidigm 15.36 TB NVMe SSD at $814 per TB, and a WD 24 TB hard drive at $56 per TB, based on street prices checked September 28, 2026. Cost per terabyte, street prices, September 28, 2026 $0 $200 $400 $600 $800 Kioxia 15.36 TB NVMe SSD: $10,850, or $706 per TB Kioxia 15.36 TB NVMe $10,850 per drive $706 Solidigm D7-PS1010 15.36 TB NVMe SSD: $12,500, or $814 per TB Solidigm 15.36 TB NVMe $12,500 per drive $814 WD Ultrastar DC HC580 24 TB hard drive: $1,350, or $56 per TB WD 24 TB hard drive $1,350 per drive $56 12 to 14 times less per terabyte
A 24 TB hard drive costs $56 per terabyte against $706 to $814 for a 15.36 TB NVMe SSD. Hover a bar for drive prices.

All-Flash HCI Turns a Media Choice into a Refresh Bill

Live Webinar · October 7 · 2:00 PM ET

How to use HCI and Hard Drives to Fight Data Center Inflation

George Crump and Dave Vincent move a running VM from flash to hard drives and back, live from Palo Alto.

Register Now

Every HCI platform sold today defaults to all-flash, a decision the platform made for the customer years ago, back when flash prices fell every quarter and the assumption looked safe. That default now means every terabyte added at refresh time pays the flash price, and capacity-based licensing charges a second time for the same terabyte.

Most workloads need far less performance than all-flash delivers. File shares, VDI profiles, dev and test environments, log retention and a large share of general-purpose VMs sit idle for most of the day. Hard drives are slower than flash, but they stay online, handle most of this work at a speed users accept and cost a fraction as much.

Aging All-Flash Array? Let the Refresh Replace It

An aging dedicated all-flash array faces the same price sheet at its next refresh. The array vendor buys NAND from the same fabs that supply every SSD in the table above, so the quote for new controllers or more capacity arrives with data center inflation already built in. Many arrays also add a per-terabyte software license on top of the hardware, which charges the inflated flash price a second time. For many IT teams, that refresh falls in the same year as a VMware renewal.

Use the refresh to replace the array and exit VMware in one project. VergeOS runs virtualization, storage and networking on standard x86 servers, so the next purchase buys off-the-shelf flash at server prices instead of flash sold through an array vendor. Global inline deduplication means you buy less of that flash, and the file shares, VM templates, aging VMs and snapshots that sit idle on the array today move to 24 TB hard drives at $56 per TB. The separate storage network and the array support contract go away with it. The Storage Refresh vs. Storage Inflation datasheet walks through the math.

Replacing an aging all-flash array and VMware hosts with VergeOS at refresh Animated diagram. Today, VMware hosts reach a dedicated all-flash array over a separate storage network, and the working set, file shares, VM templates, aging VMs and snapshots all pay the flash price. At refresh, VergeOS replaces the hosts and the array. The working set runs on off-the-shelf flash inside the servers, and everything else moves to 24 TB hard drives in the same cluster. Today At refresh, with VergeOS VMware hosts separate storage network Dedicated all-flash array Working set File shares VM templates Aging VMs and snapshots Every terabyte pays the flash price Replaced at refresh refresh VergeOS cluster ServerServerServer FlashFlashFlash 24 TB24 TB24 TB HDDHDDHDD Less flash, off the shelf. The rest at $56 per TB.
At refresh, VergeOS replaces the VMware hosts and the array. The working set runs on off-the-shelf flash inside the servers, and everything else moves to 24 TB hard drives.

Can a 24 TB Hard Drive Keep Up?

For most workloads, yes. Random-I/O databases still belong on flash, but for the rest of the data center the answer comes down to the platform in front of the drive. One of our customers ran a hosting business that sold both flash and spinning-disk capacity with VergeOS underneath. Their customers tested their workloads on hard drives, saw little difference, and kept moving more of them to disk. Dave Vincent saw the same result when he moved a live SQL workload from NVMe to spinning disk and commit latency stayed under a millisecond on both tiers.

VergeOS makes that result repeatable for any IT team. Global inline deduplication runs across every tier, so the cluster stores fewer blocks and more of the working set fits in cache. VergeOS caches data in RAM on the server running the VM, which VergeIO testing shows produces four to five times the cache hit rate of array-side caching. On the write side, VergeOS reorders and groups incoming writes into sequential runs before they reach the platter, the access pattern hard drives handle best.

How VergeOS makes a 24 TB hard drive tier keep up Animated diagram of the VergeOS I/O path. Reads are served from a RAM cache on the server running the VM. Random writes pass through global inline deduplication and are reordered and grouped into sequential runs before they reach the hard drive. VM any workload RAM cache on the server running the VM Reads served from RAM, 4 to 5 times the hit rate of array-side cache Random writes in Dedupe, reorder and group fewer blocks, longer runs Sequential runs out 24 TB hard drive Hard drives handle long sequential runs best. VergeOS shapes the write stream to match before it reaches the platter.
Reads come from RAM next to the VM. Writes arrive random and leave as sequential runs, the pattern a spinning drive handles best.

Afraid of Tiering? Select Tiering That Puts You in Control

Many IT teams steer clear of tiering, and automated tiering is the reason, after two decades of burning plenty of them. An auto-tiering algorithm samples activity, waits for a threshold and makes placement calls without knowing the business behind the workload. It is slow to spot cold data, it misses anything outside its sampling window, and it is slowest of all on the trip back to flash, usually right when users start to notice.

VergeOS puts the IT team in charge of placement instead. The people who run the workloads already know the business calendar, such as a tax application that is write-heavy through April 15 and read-heavy on April 16, and they need no algorithm to predict it. The IT team moves a running VM to the hard drive tier or back to flash on command, in either direction and with no maintenance window, and pins the workloads that must stay hot to a preferred tier. I covered why tiering itself was never the issue in Storage Tiering Is Not the Problem. Losing Control of It Is.

VergeOS moves a running VM between the flash tier and the hard drive tier on command Animated diagram. A running VM sits on the Tier 1 NVMe flash tier, moves down to the Tier 4 hard drive tier on command with the workload online, then moves back to flash the same way. Tier 1 NVMe flash Working set, random-I/O databases Tier 4 24 TB hard drives File shares, templates, aging VMs Move down on command Move back Running VM online the whole time Lab test: API acknowledged the move in 1.3 seconds. A 25 GB disk finished moving in 13 seconds.
The IT team decides placement. A running VM moves to the 24 TB hard drive tier and back on command, with no maintenance window.

Three Ways VergeOS Makes Hard Drives Safe to Use

Tiering under IT control. VergeOS supports six storage tiers inside one vSAN, with tiers 4 and 5 designed for high-capacity hard drives, and the IT team moves a running VM’s disk between tiers on command. In VergeIO lab testing, the API acknowledged the move in 1.3 seconds and a 25 GB disk finished moving in 13 seconds with the workload running. Be aggressive with it, moving a workload to hard drives and moving it back in seconds if someone complains two weeks later.

Frequent snapshots. VergeOS snapshots run on a schedule the IT team controls, hourly by default, which gives every VM on the hard drive tier recent recovery points inside the same system.

ioGuardian. Large drives raise a fair question about exposure during a rebuild. ioGuardian answers it by pulling missing or corrupted blocks from a synchronized remote VergeOS system after a failure that exceeds the cluster’s redundancy, such as multiple drive failures spread across nodes.

VergeOS licenses per server, so the money saved on hard drives and deduplication stays in the budget instead of feeding a capacity meter.

Key Terms

Data center inflation

Hardware costs rising faster than IT budgets, driven by AI demand for memory and flash.

Storage tier

A class of drives in the VergeOS vSAN, numbered 0 through 5, running from metadata NVMe to archival hard drives.

Preferred tier

The VergeOS setting that names the first-choice tier for a VM disk, used to keep critical workloads on flash.

ioGuardian

The VergeOS repair server that restores blocks from a synchronized remote system after a failure beyond redundancy tolerance.

All-Flash HCI and VergeOS Flash Plus Hard Drives

All-flash HCIVergeOS flash plus hard drives
Capacity cost at refreshFlash price for every TBFlash for the working set, $56 per TB for the rest
Workload placementEverything on flashIT team places each VM, moves it live
LicensingOften per TBPer server
Media mixFlash onlyFlash and hard drives in one cluster

See the Answer Live on October 7

Dave and I will answer the question in the title live from Palo Alto on Wednesday, October 7, at 2:00 PM ET, in How to use HCI and Hard Drives to Fight Data Center Inflation. Dave will move a running VM from flash to hard drives and back on camera, and I will walk through the refresh math for a real cluster, so register for the webinar.

Frequently Asked Questions

Can a 24 TB hard drive replace an SSD for every workload?

Random-I/O databases still belong on flash, and VergeOS lets you pin them to a preferred flash tier and place everything else on hard drives.

Does deduplication work on the hard drive tier?

VergeOS runs global inline deduplication across all six tiers, so the hard drive tier gets the same capacity savings as flash.

How long does it take to move a VM back to flash?

The move starts on command and runs with the VM online, and in lab testing small disks finish the trip back to flash in seconds.

Filed Under: Storage Tagged With: Deduplication, flash inflation, HCI, HCIandHDD, ioGuardian, Tiering

September 17, 2026 by George Crump

Hardware fails whether it is new or refurbished. VergeOS turns drive and server failures into routine events, which makes refurbished hardware a practical way to fund the VMware exit.

Refurbished hardware makes financial sense for a VMware exit, but IT teams then ask, “What happens when a used drive or server fails?” Hypervisor license costs have skyrocketed over the past two years but hardware always costs more than the hypervisor license, and the 2026 memory and flash price spike has widened that gap. Many migration projects now stall at finance review. Reusing the servers already on the floor and adding refurbished drives brings the budget back within reach, provided the platform treats hardware failure as routine.

Key Takeaways
  • Every drive and server fails eventually, new or refurbished, so resiliency belongs in the software.
  • VergeOS keeps workloads running through drive and server failures, holds data online past the resiliency factor with ioGuardian, and recovers VMs and files from snapshots at no additional software cost.
  • The on-demand Premier Connects session shows each failure live, from a pulled drive to a full data center failover.

Why Refurbished Hardware Makes IT Nervous

Traditional Recovery PathDrive failsRAID rebuild startsSecond drive failsbefore the rebuild finishesArray goes offlineworkloads stopRestore from backupthe recovery clock starts

In a three-tier data center, the storage array protects blocks with RAID, and a second drive failure during a rebuild turns into a backup restore job with significant downtime. Legacy HCI moved storage into the servers and added workload restart, yet recovery still lives in a separate backup product on separate hardware, with its own license and its own console. In both designs, a failure that exceeds the protection level hands the problem to the backup team and starts the recovery clock.

Buying premium new hardware became the standard way to push that moment further out, which ties resiliency to a purchase order finance now keeps rejecting.

Resiliency and Protection for Refurbished Hardware

The Price of ResiliencyCostResiliencyRAID 5RF2RF3Longer retentionBubble size = performance impact

Resiliency keeps an application running with zero downtime and zero data loss when a component fails. Protection restores data after resiliency runs out. Every environment has a resiliency limit, and raising it costs money. RAID 5 costs the least, offers the least resiliency, and imposes the highest performance penalty. RF2 costs more with almost no performance impact, RF3 costs more again with none, and longer snapshot retention sits at the top of the scale.

VergeOS changes where that money goes. Each step up is a setting in the platform, so climbing the scale costs capacity instead of another software license. Refurbished drives make that capacity affordable. An organization can run RF3 with longer retention on the budget that once bought a smaller pool of new drives.

Saratoga Casino Holdings runs this model in production. The company moved to VergeOS on CXTEC® equal2new® refurbished servers and removed roughly $50,000 a year in Pure Storage array maintenance. Read the Saratoga Casino Holdings case study for the full story.

Resilient: Refurbished Hardware Keeps the Workload Running

VergeOS runs compute, storage, networking, and data protection in one code base. With RF2 or RF3 set per workload, a failed drive is invisible to the application. A server failure triggers an automatic restart of its workloads on the surviving nodes, with no operator in the loop. The age of the failed part makes no difference, so refurbished hardware delivers the same outcome as new hardware.

RF vs. RAID

RF vs. RAIDShare of raw capacityRAID 5Usable20-25%RAID 6Usable25-33%RF2Usable2nd copyGlobal inline dedup recovers most of the gapPerformanceNormalDrive failedRAID 5/6Parity penaltySevereRF2Almost noneNone

At first glance, RF2 looks like it doubles capacity consumption, since every block exists twice. The real gap is much smaller. RAID 5 gives up 20 to 25 percent of raw capacity to parity in a typical four or five drive group, and RAID 6 gives up 25 to 33 percent with two parity drives in a six to eight drive group. VergeOS global inline deduplication makes up for most of the difference. It works across every drive and server in the environment, so a block shared by many VMs is stored once.

Performance favors RF from the start. During normal production operations, RF2 has almost no performance impact, and it improves read performance, since VergeOS serves reads from multiple drives and servers. A failed drive leaves performance where it was, with the surviving copy answering every request. RAID 5 and RAID 6 pay a parity penalty on writes in normal operation, and the penalty grows sharply in a degraded state, when the array reconstructs data on every read and runs a rebuild at the same time. That degraded window is exactly where refurbished hardware puts the most pressure on a design, a point that has been characterized as storage recovery architecture mattering more than drive reliability.

Repairable: Data on Refurbished Hardware Stays Online Past the Limit

The hardest objection to refurbished hardware is a second failure before the first repair finishes. Two drives failing at once exceed RF2, and in most designs that means a restore. ioGuardian covers that window. A dedicated server, the ioGuardian target, delivers missing data segments to VMs in real time, so workloads keep running as the system repairs itself. The mechanics are covered in detail in Surviving Cascading Drive Failure.

▶
On-Demand Webinar · Premier Connects
Exit VMware to Resilient HCI
Aaron Richman and David Vincent fail drives, a server, and a full virtual data center live on VergeOS.
Watch Now →

Recoverable: Recovery From the Same Interface

Recovery Inside the PlatformVM volumeSnapshot 1Snapshot 2Snapshot 3Each ioClone snapshot is a standalone copyVirtual data centerVMs, network,storage settingsDR siterefurbishedhardwareThe whole environment fails over as one object

Some events have nothing to do with hardware, like an administrator deleting a VM or a user removing files. VergeOS snapshots use ioClone and behave as independent copies instead of a dependent chain, so retention is bounded by capacity. A deleted VM comes back instantly from a snapshot, and individual files recover through a hot plug drive attached to the running VM. Recovery works the same way on refurbished hardware as it does on new servers.

For a site-level event, a virtual data center encapsulates the VMs, networking, and storage settings, and it fails over to the DR site as one object. The DR site can run on refurbished hardware too.

How Each Design Handles Failure

FailureThree-TierLegacy HCIVergeOS
One driveRAID rebuild on the arrayHCI storage layerRF2 or RF3, workload unaffected
One serverHypervisor HA restartWorkload restartAutomatic restart on surviving nodes
Beyond the protection levelRestore from backup productRestore from backup productioGuardian keeps data online
Deleted VM or filesSeparate backup productSeparate backup productioClone snapshot, hot plug drive
Site lossArray replication plus runbooksReplication plus separate DR toolingVirtual data center failover
Protection software costSeparate licensesSeparate licensesIncluded in VergeOS
Key Terms
Resiliency factor (RF2, RF3)
The number of synchronous copies VergeOS keeps of each block, set per workload. RF2 survives one failure and RF3 survives two, on new or refurbished hardware.
ioGuardian
The VergeOS capability that delivers missing data segments to VMs in real time during multiple drive or server failures, using a dedicated server called the ioGuardian target.
ioClone
The VergeOS snapshot technology. Each snapshot behaves as an independent copy, so retention is bounded by capacity.
Virtual data center (VDC)
A single object that encapsulates VMs, networking, and storage settings, so the whole environment replicates and fails over together.

See Every Failure Now

The Premier Connects session, Exit VMware to Resilient HCI: Integrated Data Protection, Faster Recovery, and Built-In DR, walks through each stage in order. Aaron Richman, Field Evangelist, explains each feature, and David Vincent, Technical Evangelist, demonstrates it on a running VergeOS environment. The demos escalate from a pulled drive and a failed server to two failed drives, a deleted VM and files, and a full virtual data center failover. Watch the on-demand session to see how refurbished hardware made resilient changes the math on your VMware exit.

Frequently Asked Questions
Is refurbished hardware reliable enough for production?
Every drive and server fails eventually, new or refurbished. VergeOS plans for that failure with RF2 or RF3, ioGuardian, and snapshots, so production reliability comes from the platform instead of the age of the part.
What do these resiliency capabilities cost?
RF2 and RF3, ioGuardian, unlimited snapshots, instant recovery, and virtual data center failover come with VergeOS at no additional software cost.
Do I still need a backup product?
A backup product becomes optional, used for GUI-based single file recovery and long term archiving. VergeOS supports the backup platforms customers already run, including Veeam.

Next Steps

The on-demand session, the architecture behind it, and a customer running VergeOS on refurbished hardware are one click away.

On-Demand Webinar
Exit VMware to Resilient HCI
Live drive, server, and data center failures on VergeOS, from a pulled drive to VDC failover.
White Paper
Beyond the Hypervisor Swap
The VergeOS architecture in depth, including resiliency, recovery, and disaster recovery.
Case Study
Saratoga Casino Holdings
VergeOS on CXTEC® equal2new® refurbished servers, with Pure Storage array maintenance removed.

Filed Under: Storage, VMwareExit Tagged With: data protection, Disaster Recovery, ioGuardian, refurbished hardware, refurbished SSDs, RF3, VergeOS, VMware, VMware alternative, VMware exit

May 27, 2026 by George Crump

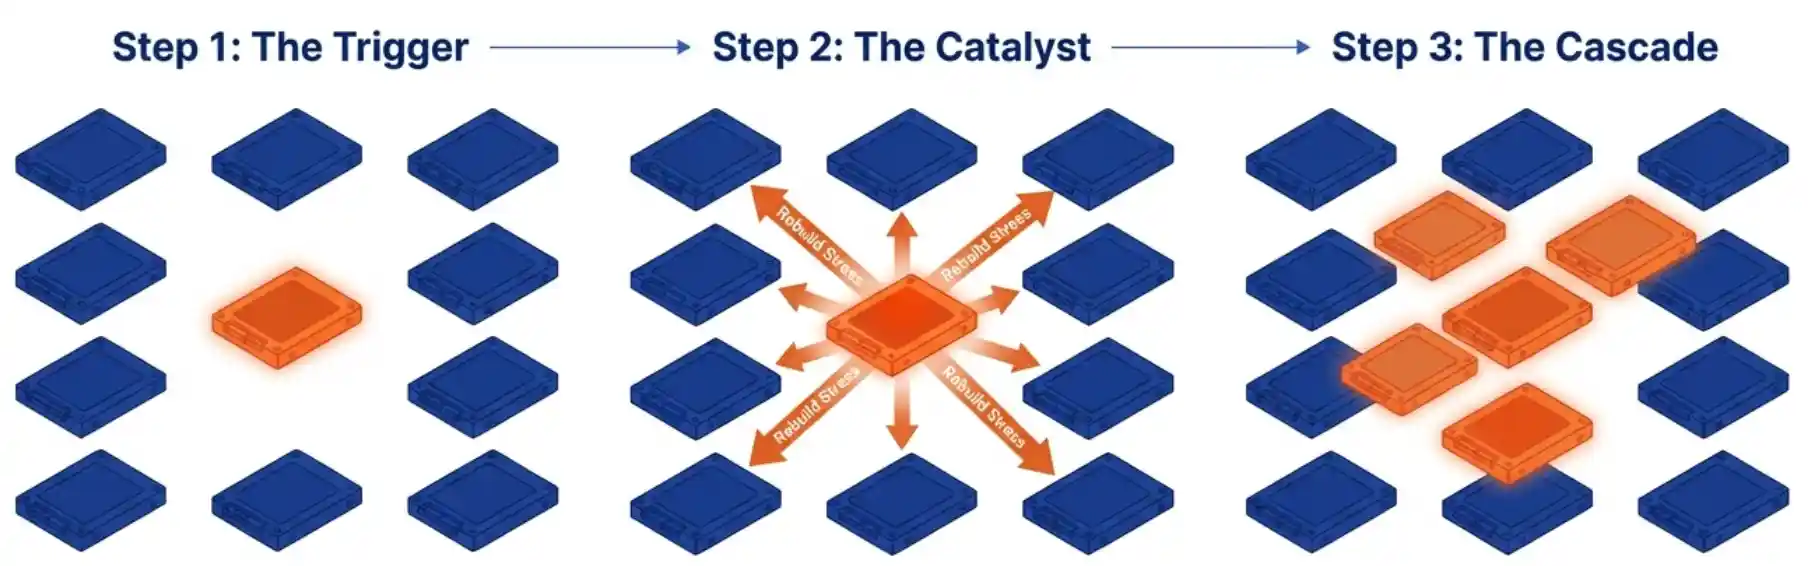
Cascading drive failure is the storage scenario every IT operator wants to never live through. Picture this. A six-node hyperconverged environment running production workloads. A drive fails on one of the nodes. The rebuild starts. Mid-rebuild, a second drive fails. More rebuilds spin up. A third drive fails. Then a fourth. The cluster has now exceeded the tolerance of RF2, the standard two-copy synchronous replication model in VergeOS. It has also exceeded RF3 if you happened to be running it. On most platforms, this cascading drive failure has just ended the cluster, the VMs are stopped, and recovery is a tape-restore conversation.

Key Takeaways
  • Cascading drive failure is the dominant concurrent-failure pattern, not the exception. One drive fails, rebuilds kick off, surviving drives wear faster under the rebuild load, and the next failure arrives before the cluster has recovered from the first.
  • Hyperconverged and ultraconverged architectures raise the stakes on cascading drive failure. Compute and storage share nodes, so a node loss takes both layers down at once.
  • RF2 and RF3 absorb the first one or two losses. ioGuardian streams missing blocks inline beyond that. Live VM migration moves workloads off degraded nodes in parallel. Users see no interruption.

VergeOS handles a cascading drive failure differently. As each drive fails and the failure surface widens, ioGuardian streams the missing blocks inline to the running VMs as the VMs request them. The platform also live-migrates the affected VMs off the most degraded nodes to surviving ones. By the time three or four servers have effectively crashed, the users are still accessing their applications and data. They never see the cascade happen.

The scenario above is a thought experiment built from common failure patterns. Same-batch drives age together. Rebuild storms stress surviving drives and accelerate the next failure. Correlated wear pushes the cascade forward. The pattern is not exotic, it is statistically expected on used media and possible on new media. The architecture that makes the outcome survivable is shipping today. Once you understand how it works, the case for using refurbished media on the right platform becomes a procurement decision rather than a courage test.

4 of 6Servers effectively crashed in the cascading drive failure scenario
0User-noticed service interruptions during the cascade
40–60%Refurbished enterprise SSD discount versus new pricing

Why Cascading Drive Failure Happens

Cascading drive failure is not exotic. Every hyperscaler operating at scale has documented this pattern in their published field data on flash drives. When one SSD fails inside a same-batch group, the probability that two or three more in that group fail within days is materially elevated. The drives shipped together, ran the same workload, and reached the same point on their wear curves at the same time. Rebuilds make it worse, not better, since the surviving drives carry the rebuild load and accelerate their own wear. This is true of new media. It is more true of refurbished media, where the wear distribution is tighter than a fresh procurement order.

Cascading drive failure from correlated wear curves accelerated by rebuild storms

The architectural answer is the same regardless of failure cause. Consider three causes: a same-batch firmware bug, correlated end-of-life on a single procurement order, and rebuild stress that propagates the next failure. All three look identical to the storage layer. The platform either absorbs the cascading drive failure without service interruption or it does not. Refurbished drives raise the prior probability of a cascade. They do not change the response model.

Converged architectures raise the stakes further. Hyperconverged and ultraconverged platforms run compute and storage on the same physical nodes, so the loss of a node takes both layers down at once. A cluster experiencing cascading drive failure across the same week is also watching three VM hosts wobble. The architectural answer has to absorb both halves of that failure surface, not just the storage half. Refurbished media on a converged platform without inline recovery compounds the problem in two dimensions at once. The protection model has to cover storage and compute simultaneously or it does not cover anything that matters.

How VergeOS Absorbs Cascading Drive Failure

VergeOS uses synchronous replication rather than erasure coding. RF2 maintains two copies of every block on different drives across different nodes. RF3 maintains three. A write only completes once the second or third copy acknowledges. The platform survives the loss of any drive, and at RF3 the loss of any two, with no parity calculation, no rebuild storm, and no degraded-mode performance penalty. The choice between RF2 and RF3 is a capacity question, not an architecture question. The replication model is the same.

VergeOS architecture for cascading drive failure: RF2 and RF3 synchronous replication, ioGuardian inline recovery, and live VM migration

ioGuardian extends the protection model beyond the replication tolerance. It is a separate node holding a complete asynchronous copy of the cluster, updated on every system snapshot. When a failure exceeds the configured RF level, ioGuardian does not attempt to rebuild the failed drives. It steps inline and delivers the missing blocks to the running VMs as the VMs request them. Recovery is not a process that runs in the background. Recovery is the data path itself.

The compute layer responds in parallel. As nodes degrade past the threshold where they can serve workloads reliably, VergeOS live-migrates the affected VMs to surviving nodes. The VMs themselves see no interruption. The combination of inline storage recovery plus continuous VM migration is what lets the cluster absorb the loss of multiple servers without service impact, even when the cascading drive failure exceeds both RF2 and RF3 tolerances.

The Ultra Converged Infrastructure model adds another dimension to cascade resilience. VergeOS supports heterogeneous node types in the same cluster: storage-heavy nodes packed with drives, compute-heavy nodes loaded with CPU and RAM, and classic hyperconverged nodes that balance both. A cluster running this mix spreads the cascade surface across different physical roles. When a same-batch cascade hits the storage-heavy nodes, the compute-heavy nodes keep running VMs uninterrupted. When a compute node fails, the storage nodes keep serving data. The same UCI flexibility that lets you scale compute and storage independently during normal operations also makes it structurally harder to lose a cluster to a single concentrated failure.

Two design consequences follow. The first is performance: the surviving drives never carry a rebuild storm, writes incur no parity recalculation tax, and the failed state holds production-level latency when the ioGuardian target runs on flash. The second is hardware flexibility. The ioGuardian server runs on its own license and its own hardware, and it does not need to match the production cluster in CPU family, generation, or media type. Customers run AMD ioGuardian targets behind Intel production environments, repurpose retired servers as ioGuardian capacity, and place a second ioGuardian instance at a cloud service provider for site-level resilience.

Key Terms
Cascading Drive Failure
A drive failure pattern in which one failure triggers conditions (rebuild stress, correlated wear) that make subsequent failures more likely. Common on same-batch media, more pronounced on refurbished media.
RF2 / RF3
VergeOS’s two-copy and three-copy synchronous replication models. Every write completes only after the additional copies acknowledge. Survives loss of one or two drives with no rebuild storm and no degraded-state performance penalty.
ioGuardian
A separate node holding a complete asynchronous copy of the cluster, updated on every system snapshot. Streams missing blocks inline to running VMs when failures exceed the configured RF level. Eliminates the rebuild process as a recovery mechanism.
Live VM Migration
VergeOS’s mechanism for moving running VMs off degraded nodes to surviving ones without service interruption. Works in parallel with ioGuardian during a cascade so the compute layer keeps serving even as storage absorbs the failure.
UCI Node Types
VergeOS supports storage-heavy, compute-heavy, and balanced hyperconverged nodes in the same cluster. Spreading workloads across heterogeneous node types makes the cluster structurally more resilient to a single concentrated failure pattern.

Telemetry Prevents Failure Before It Starts

The cascading drive failure scenario makes the architecture vivid. It also makes the point in the wrong direction. The goal is not to absorb the failure event. The goal is to never reach it. VergeOS does both. The replication model, ioGuardian, and live migration handle the moment of failure. The telemetry layer makes sure the moment rarely arrives.

VergeOS SMART telemetry catching the early signature of cascading drive failure before the second drive fails

The platform tracks seven SMART attributes on every drive in real time: total writes, power-on hours, reallocated sectors, wear leveling, ECC errors, end-to-end errors, and temperature. The data flows through a subscription model. A subscription is a rule that fires an alert on a defined condition.

The obvious subscription watches a wear-level threshold, and most customers set the first alert at seventy percent. The more useful subscription watches rate of change. An alert that fires when a drive’s wear level jumps ten points within ten days catches drives at risk of failure days or weeks ahead of any fixed threshold. The same rate-of-change subscription catches the early signature of a cascading drive failure before the second drive in a batch fails.

This capability turns refurbished procurement into a verifiable transaction. A reputable supplier delivers drives with a stated wear level and chain-of-custody record. The buyer installs them, runs a stress workload for twenty-four hours, and lets the platform watch. A drive that arrives at ninety percent wear when the supplier represented twenty percent gets flagged before any production data lands on it. The drive goes back, the supplier gets the call, and the framework has been validated by the platform itself. Refurbished media stops being a faith-based purchase and becomes a quantifiable one.

VergeIO On-Demand Webinar
The Refurbished SSD Framework

George Crump and Aaron Richman walk through the secondary-market case, the procurement framework, and the architectural model that makes refurbished enterprise drives a procurement decision rather than a courage test.

Watch the Recording →

This is the two-sided coverage VergeOS delivers. The telemetry layer gives you everything you need to try to prevent the cascading drive failure from happening in the first place, through real-time SMART exposure, rate-of-change subscriptions, and verifiable supplier representations. If the cascade still arrives despite the early-warning systems, the architecture has the resiliency to withstand it, through synchronous replication, inline recovery, live migration, and heterogeneous UCI node distribution that keeps user workloads running through the failure. Both halves of the coverage matter. Most platforms leave the second half to you.

What This Means for Refurbished Procurement

The conventional argument against refurbished enterprise SSDs is elevated failure risk. The argument is correct. The platform decision is what changes the consequence of that risk. New media on a naive architecture faces a different set of stakes than refurbished media on a platform built to absorb cascading drive failure. Erasure coding controls protection at the cost of double-digit-hour rebuilds and a real chance that the next drive failure during rebuild ends the cluster. Synchronous replication, inline recovery, and live migration hold the cluster up regardless of failure cause or media age.

Stack the cost math on top of that architectural reality and the picture changes. Refurbished enterprise SSDs run forty to sixty percent below new pricing in the current market, a market whose underlying dynamics have been characterized as memory and flash prices that are not coming down. The reputable supply chain runs through R2v3-certified vendors who serialize inventory, perform NIST 800-88 sanitization, and stand behind their representations. Drives typically carry eighty to ninety-five percent of rated write life remaining. A buyer who runs SMART verification on intake, sets the rate-of-change subscription, and deploys behind RF2 with ioGuardian has answered the failure-risk question in three independent ways before any customer data lands.

Naive Architecture vs VergeOS for Cascading Drive Failure

 Naive ArchitectureVergeOS
Protection modelErasure coding with parity calculation overheadSynchronous replication with no parity overhead
Recovery on failure within toleranceMulti-hour rebuild storm on surviving drivesContinuous serving with no rebuild
Recovery on failure beyond toleranceRecover from backup, days of downtimeioGuardian inline streaming, no service interruption
Compute response during cascadeVMs stop on affected nodes, manual restart requiredLive migration moves VMs to surviving nodes automatically
Failure surface across node typesSymmetric nodes concentrate the cascadeUCI heterogeneous nodes spread the cascade across roles
Refurbished SSD verificationManual intake test, no continuous monitoringSeven SMART attributes monitored real-time, rate-of-change alerts

The cascade is what makes the scenario memorable. The architecture absorbs cascading drive failure for the same reason it absorbs a same-batch firmware bug, a bad refurbished batch, or a single drive that happened to fail on a busy day. The failure cause is not the variable. The platform is. A companion post, How VergeOS Makes Refurbished SSDs Safe to Run, catalogs the platform’s response to each of the four supplier-side refurb risks.

Frequently Asked Questions
What is ioGuardian and how is it different from a backup system?
ioGuardian is a VergeOS data-protection node that holds a complete asynchronous copy of the production cluster, updated on every system snapshot. When a failure exceeds the configured RF protection level, ioGuardian streams the missing blocks inline to running VMs as the VMs request them. The VMs never stop serving. ioGuardian replaces rebuild as the recovery mechanism for failures beyond replication tolerance. It does not replace backup. It eliminates rebuild as the primary recovery path.
Can VergeOS handle a cascading drive failure that exceeds RF2 and RF3?
Yes. RF2 absorbs the first drive loss, RF3 absorbs the first two. When a cascading drive failure exceeds the configured RF level, ioGuardian streams missing blocks inline to running VMs while live migration moves workloads off the most degraded nodes to surviving ones. The UCI node-type flexibility spreads the failure surface across compute-heavy, storage-heavy, and balanced nodes, so the cascade rarely takes the whole cluster. The cluster keeps serving even when concurrent failures take out a majority of nodes.
Why is cascading drive failure protection more critical on HCI and UCI than on split architectures?
Hyperconverged and ultraconverged platforms run compute and storage on the same physical nodes. The loss of a node takes both layers down at once. A cluster experiencing cascading drive failure is also watching three or four VM hosts wobble. The architectural answer has to absorb both halves of that failure surface, not just the storage half. ioGuardian and live migration were designed for that combined blast radius.
How does VergeOS verify that a refurbished drive’s stated wear level is accurate?
VergeOS exposes seven SMART attributes per drive in real time and lets administrators define subscription rules. A wear-level threshold subscription alerts when any drive crosses a defined value. A rate-of-change subscription alerts when wear increases faster than expected, catching drives that arrived in worse condition than the supplier represented. Both subscriptions fire before production data is at risk.
Does ioGuardian require the same hardware as the production cluster?
No. The ioGuardian server runs on its own license and its own hardware. It does not need to match the production cluster in CPU family, generation, or storage media. Customers run AMD ioGuardian targets behind Intel production environments, repurpose retired servers as ioGuardian capacity, and place a second ioGuardian instance at a cloud service provider for site-level resilience.
What happens if a same-batch firmware bug takes out multiple drives at once?
The architectural response is the same as cascading drive failure from any other cause. RF2 or RF3 absorbs the first one to two failures within tolerance. ioGuardian absorbs the rest by streaming inline, and live migration moves VMs off the affected nodes. The cluster keeps serving. The corrective action with the manufacturer or supplier happens on a normal-business-hours schedule rather than a 3 AM emergency.

Filed Under: Storage Tagged With: cascading drive failure, ioGuardian, live migration, refurbished SSDs, RF2, RF3, UCI, VergeOS

May 5, 2026 by George Crump

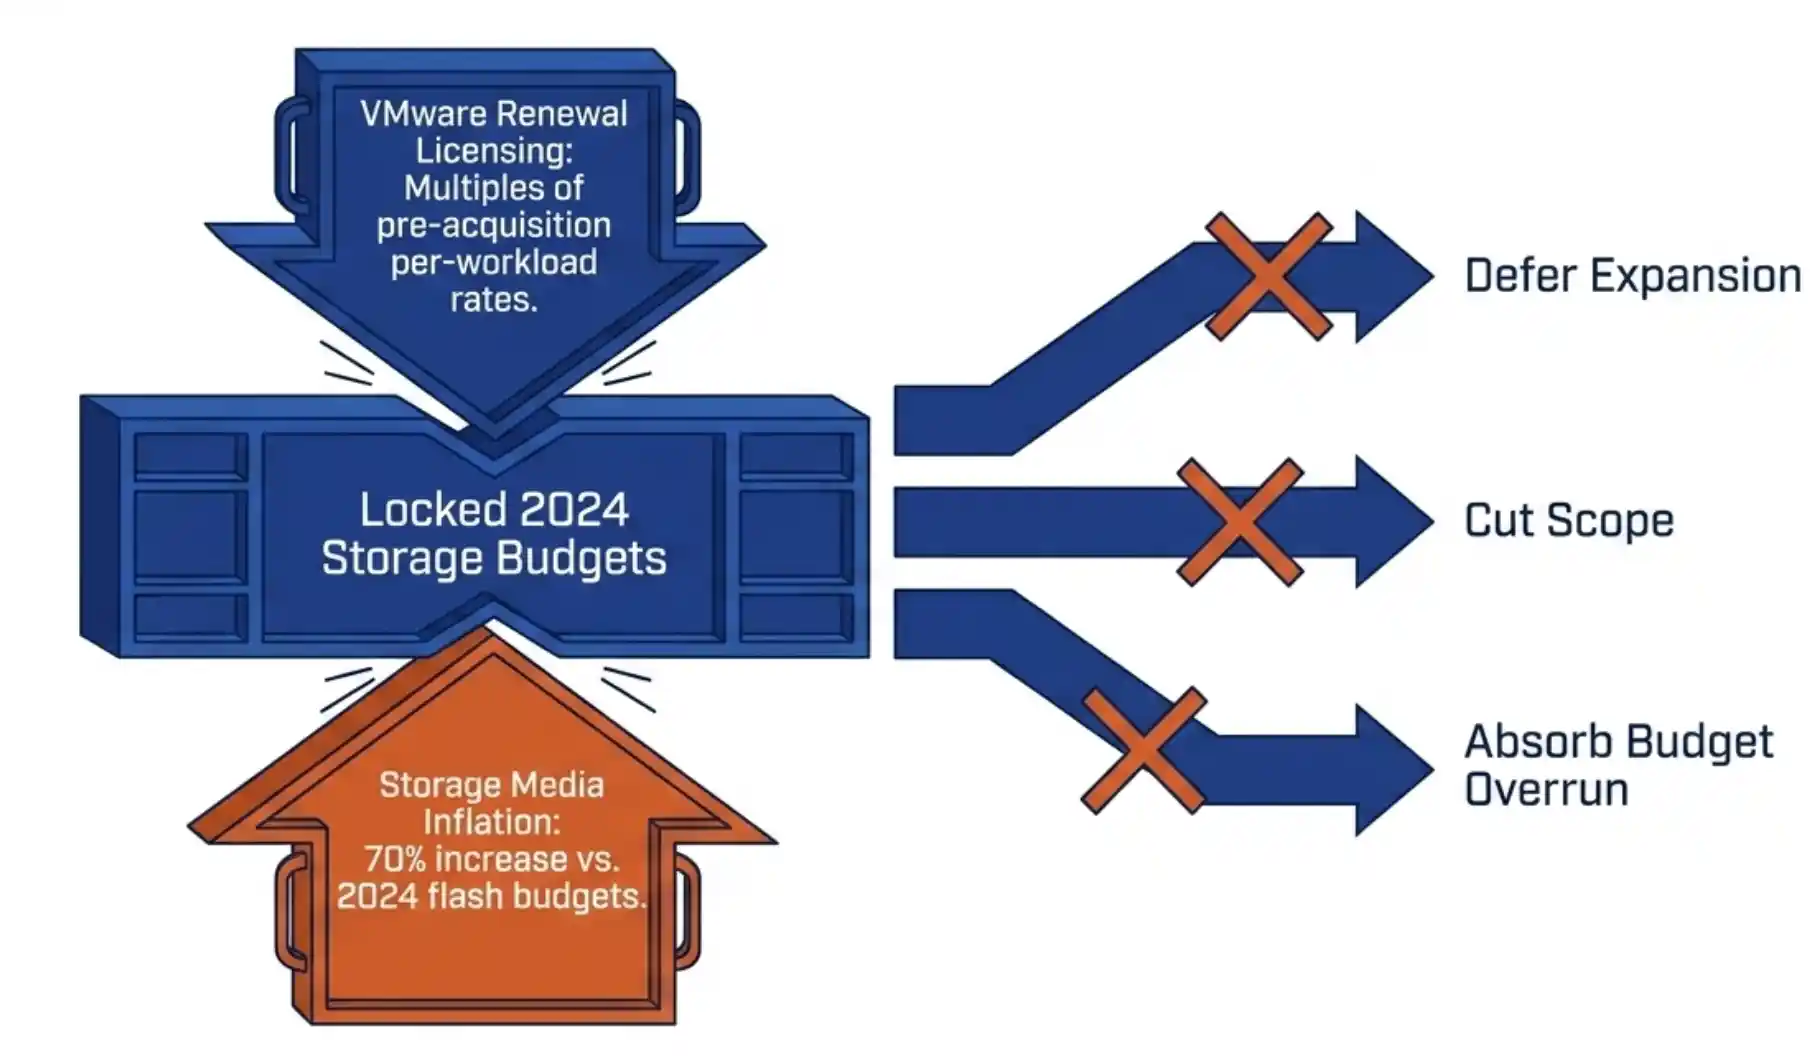
SAN refresh in trouble: 2026 flash inflation under-funds 2024 budgetsYour 2026 SAN refresh is in trouble. Flash inflation has pushed enterprise SSD prices up 70 percent. Refresh budgets locked in 2024 are now under-funded against current list pricing. The standard responses are to defer expansion, cut scope, or absorb the cost as a budget overrun. None of those options preserve the operational plan you set last year.
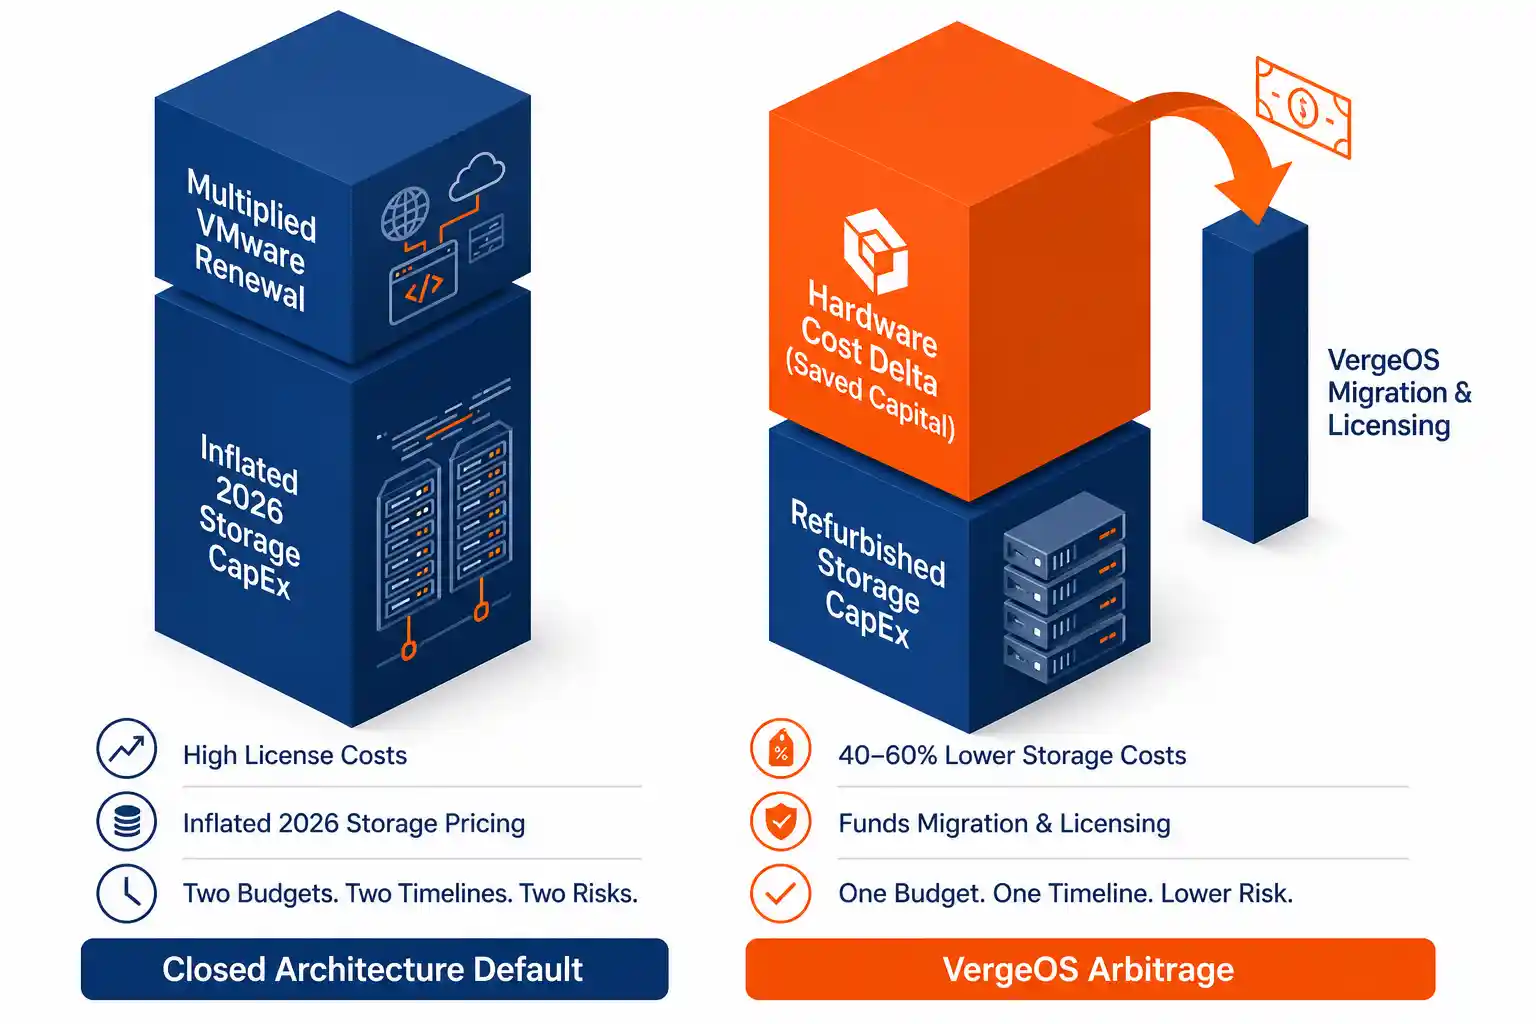
A fourth option exists. Capture the original capacity expansion at 40 to 60 percent of new flash list pricing using the secondary enterprise SSD market. Run that capacity on VergeOS instead of VMware. The hardware savings fund the platform exit. The SAN refresh costs less than it would have last year. The VMware exit pays for itself.

This is not two decisions. It is one decision executed once, with the savings stacking across both line items in the budget. The procurement framework and the architecture ship together, and the financial mechanism only works when both are deployed at the same time. This dynamic has been characterized as Broadcom’s best retention tool, since the same memory and flash supercycle that pushes refresh budgets underwater also makes the migration hardware harder to fund.

Key Takeaways
Refurbished enterprise SSDs sell at 40 to 60 percent below 2026 new flash list pricing, with 80 to 95 percent rated write life remaining at market entry.
The hardware cost delta on a SAN refresh covers the software and licensing line items of a VMware migration, converting a painful CapEx event into a near-neutral financial maneuver.
VergeOS synchronous replication with RF3 plus ioGuardian absorbs the failure rate of refurbished media without service interruption, validated by a documented customer event in which four of six hosts went down simultaneously with zero downtime and zero data loss.

Why the SAN Refresh and the VMware Exit Belong in the Same Decision

VergeOS arbitrage refresh stacks SAN and VMware exit savingsMost infrastructure teams treat their SAN refresh and their hypervisor strategy as separate problems. The SAN refresh is a procurement decision, owned by storage architects. The VMware exit is a platform decision, owned by virtualization leads and the CIO. The two budgets land in different fiscal lines, the two evaluation cycles run on different clocks, and the two vendor conversations rarely overlap.

That separation worked when storage and compute came from different vendors with different procurement paths. It does not work in 2026. VergeOS integrates storage, compute, networking, and virtualization into a single operating system. The SAN refresh and the platform exit run on the same code base, the same hardware substrate, and the same budget cycle. Treating them separately means buying two solutions where one will do.

The financial argument follows directly. A SAN refresh on VergeOS uses commodity x86 servers with refurbished enterprise SSDs at 40 to 60 percent below new flash list pricing. The capacity arrives at a fraction of the cost of a closed-architecture refresh. The hardware delta funds the VMware migration that the same cluster will host. The procurement decision and the platform decision compound into one financial outcome.

The Math: SAN Refresh Below 2025 Prices

The secondary enterprise SSD market is not a salvage market. Hyperscalers, MSPs, and Fortune 500 operators replace drives on rolling multi-year lease schedules, long before wear thresholds are met. Drives enter the secondary market with 80 to 95 percent of their rated write life remaining and 7,000 or more terabytes written endurance ratings intact. The supply is large, growing, and dominated by enterprise-grade media, not consumer drives.

The pricing math is direct. A 3.84TB enterprise SAS SSD sells new at $560 or more in current 2026 list pricing. The same drive, refurbished from a hyperscaler refresh cycle and qualified through a six-part procurement framework, sells at roughly $170. The delta is not 40 to 60 percent below 2026 list pricing. It is 40 to 60 percent below the inflated 2026 number, which means it lands competitively against what the same capacity would have cost new in 2024 or 2025.

40–60%
Cost reduction below 2026 new flash list pricing
80–95%
Rated write life remaining at secondary market entry
7,000+
Terabytes written endurance rating on enterprise refurbished

The procurement framework is the work. R2v3 supplier qualification confirms the drives came from a certified refurbisher with serialized inventory. NIST 800-88 sanitization certificates document compliant data destruction. Fraud detection verifies retail firmware against rebadged OEM drives. SMART diagnostics baseline the seven attributes that matter. Firmware validation confirms the drive runs vendor-released code. Stress testing proves the drive holds up under sustained workload. The framework is not optional. It is the difference between a SAN refresh strategy and a coin flip.

The Math: The Migration Pays for Itself

VMware renewal pricing has made the status quo untenable for a substantial portion of the installed base. Per-workload license pricing has climbed to multiples of pre-acquisition rates. The renewal conversation is no longer about a routine increase. It is about whether the platform is worth the new contract value at all.

The standard response is to evaluate alternatives, plan a migration, and request CapEx for the destination platform. The CapEx request is the problem. New compute, new storage, and new licensing all hit the budget in the same fiscal cycle, often in the same quarter. The financial picture looks like a one-time capital event piled on top of the existing operational baseline, and procurement defers the decision rather than absorb the impact.

The arbitrage play changes the picture. The VergeOS cluster pools existing flash with newly procured refurbished enterprise drives, creating a unified storage tier that runs at a fraction of standard hardware costs. The hardware cost delta on the SAN refresh creates the budget headroom that the VMware exit needs. The migration funds itself out of the savings on the storage line item. The CapEx request becomes a near-neutral request, or in many cases a net-positive one.

The financial mechanism only works when the SAN refresh and the VMware exit run on the same platform. Two separate vendors mean two separate budgets and two separate procurement cycles. One unified operating system collapses both decisions into one budget event with stacked savings.
Key Terms
Synchronous Replication

Storage architecture in which every block is written to multiple servers simultaneously. The write acknowledges only after all replicas land, eliminating the rebuild storms and parity-calculation windows that plague closed RAID architectures.

RF2 / RF3

VergeOS replication factors. RF2 keeps two synchronous copies and tolerates the loss of any one drive or host (N+1). RF3 keeps three synchronous copies and tolerates the simultaneous loss of any two drives or hosts (N+2). RF3 is the baseline for production workloads on refurbished media.

ioGuardian (N+X)

VergeOS active-service capability that absorbs concurrent failures beyond the base replication factor’s mathematical tolerance. Surviving replicas serve data at full performance during background re-replication, eliminating the secondary-failure window that turns a single hardware event into a service outage.

R2v3 Certification

The Responsible Recycling Standard, version 3, governs certified refurbishment and remarketing of electronic equipment. R2v3-certified suppliers maintain serialized inventory, documented sanitization processes, and verifiable provenance, which is the procurement floor for refurbished enterprise SSDs.

The Architectural Defense: Refurbished Media Becomes a Non-Event

The financial case is strong. The architectural objection is the question that stops most CFOs from approving the play. Refurbished drives carry a statistically higher failure probability than new drives, and the last thing any infrastructure team wants is a procurement decision that turns into a 2 a.m. outage. The right response to elevated drive failure probability is not avoidance. It is architecture that absorbs the elevated failure rate without service impact.

Live Webinar · May 7, 2026
Solve the Storage Crisis with Refurbished Enterprise Drives

George Crump and Aaron Richman walk the procurement framework, the architecture, and the migration sequencing in 45 minutes. Live Q&A included.

Register Now →

VergeOS protects data with synchronous replication, not RAID. Every block writes to multiple servers simultaneously. The write acknowledges only after all replicas land. There is no parity calculation, no rebuild process running across surviving spindles, no extended window where a single additional failure causes data loss. RF3 on VergeOS keeps three synchronous copies of every block across separate hosts, and the architecture mathematically tolerates the simultaneous loss of any two drives or hosts.

ioGuardian extends that tolerance further. The active-service capability keeps surviving replicas running at full performance during the re-replication window, eliminating the secondary-failure exposure that turns a single hardware event into a service outage on legacy systems. One VergeOS customer ran an RF2 cluster with ioGuardian protection across six servers. During a single incident, four of the six servers went down simultaneously. RF2 mathematically tolerates exactly one host failure. The math says the cluster should have suffered catastrophic data loss. The cluster experienced zero downtime and zero data loss. ioGuardian absorbed three concurrent failures beyond the base replication factor’s tolerance.

That magnitude of architectural over-engineering renders refurbished media failure rates irrelevant. A correlated batch failure across drives from the same lease cycle is the kind of event that would destroy a parity-based RAID set. On VergeOS with RF3 and ioGuardian, the same event is absorbed without service impact. The refurbished SSD strategy is not gambling on drive quality. It is deploying capacity in an architecture that does not depend on individual drive reliability.

SAN Refresh Comparison: Closed Architecture vs. VergeOS Arbitrage

 Closed Architecture RefreshVergeOS Arbitrage Refresh
Storage mediaNew flash, vendor-locked modulesRefurbished enterprise SSDs, commodity hardware
Pricing vs. 2025 list70 percent above 2025 listBelow 2025 list, competitive with 2024 pricing
Capacity expansion targetReduced to fit 2024 budgetOriginal target maintained
Failure protection modelParity-based RAID with rebuild stormsSynchronous replication with N+X ioGuardian
Hypervisor licensingVMware renewal at multi-fold increaseVergeOS integrated, no separate hypervisor cost
Migration fundingSeparate CapEx request, deferredFunded by hardware cost delta on the refresh

The Procurement Floor: How to Qualify Suppliers Without Gambling

The architectural defense answers the technical objection. The procurement objection is the practical one. How does a storage architect actually qualify suppliers without taking a position on every drive that arrives at the loading dock? The answer is the six-part intake framework, which converts refurbished SSD purchasing from a coin flip into a repeatable process.

The framework runs in sequence. R2v3 certification verifies the supplier’s chain of custody and serialized inventory. NIST 800-88 sanitization certificates confirm compliant data destruction on the drives entering the data center. Fraud detection verifies matching serials and retail firmware against rebadged OEM drives. SMART diagnostics baseline the seven attributes that matter for endurance and reliability. Firmware validation confirms the drives run vendor-released code, not modified or counterfeit firmware. Stress testing proves sustained-workload performance under realistic conditions.

The framework is the work. The savings are the reward. A SAN refresh built on this procurement floor delivers the cost advantage of the secondary market without importing the failure modes of the lower-tier suppliers, and it does so on a repeatable schedule that scales with the rest of the operational plan.

One Budget Cycle, Two Wins

Digital White Paper
Solve the Storage Crisis with Refurbished Enterprise Drives

The full framework. Fifteen sections covering the secondary market, the four risk categories, the six-part procurement funnel, and the VergeOS architecture that absorbs the residual risk.

Get the Paper →

The 2026 storage cost crisis is real. The VMware renewal pressure is real. The combination is what makes most infrastructure teams flinch and defer. The SAN refresh that pays for the VMware exit changes the financial calculation by stacking the savings rather than running them as separate decisions.

The procurement framework qualifies the drives. The architecture absorbs the risk. The cost delta funds the migration. The refresh costs less than it would have last year. The exit pays for itself. None of the three components work in isolation. All three deployed together produce a budget outcome that no other combination of vendors can match in the current supply environment.

The May 7 webinar walks through this play with real numbers. Register for the webinar.

Frequently Asked Questions
How much does a SAN refresh on VergeOS with refurbished enterprise SSDs cost compared to a new flash refresh in 2026?
Refurbished enterprise SSDs sell at 40 to 60 percent below 2026 new flash list pricing. A VergeOS refresh on commodity x86 servers with qualified refurbished SSDs runs at a fraction of the cost of a closed-architecture refresh. The exact savings depend on cluster size and capacity targets, but the math typically produces a hardware line item that lands below 2025 list pricing for the same capacity. The May 7 webinar walks through three cluster sizes with real numbers.
Are refurbished enterprise SSDs reliable enough for production workloads?
Refurbished enterprise SSDs from R2v3-certified suppliers carry 80 to 95 percent of their rated write life and ship with 7,000 or more terabytes written endurance ratings intact. They include power-loss protection, premium NAND binning, and the architectural features that consumer drives lack. The reliability case rests on two pillars: a six-part procurement framework that filters out fraud and OEM firmware lock, and an architecture that absorbs the residual failure rate without service interruption.
Can VergeOS pool existing legacy storage with newly procured refurbished SSDs?
Yes. VergeOS pools heterogeneous storage media seamlessly. Existing legacy flash continues serving production capacity alongside newly procured refurbished enterprise drives in the same cluster. The architecture treats hardware as commodity substrate, not as a procurement constraint. The flexibility is a critical part of the financial case for the VMware exit, since it eliminates the requirement to purchase 100 percent new storage as part of the migration.
Does the architectural strategy work with RF2, or does it require RF3?
RF3 is the baseline recommendation for production workloads on refurbished media. It tolerates the simultaneous loss of any two drives or hosts, and combined with ioGuardian it absorbs additional concurrent failures beyond the mathematical N+2 tolerance. RF2 with ioGuardian works for capacity-sensitive deployments and has a documented customer record of surviving four-of-six host failures with zero data loss. The choice depends on workload criticality and capacity targets.
What does the VMware migration look like operationally?
The VergeOS cluster runs alongside the VMware estate during the migration window. Workloads move in waves on a schedule the customer controls. The new platform absorbs production traffic as the old platform is decommissioned. The hardware cost delta from the SAN refresh provides the budget headroom for the licensing and migration services line items, which removes the financial barrier that defers most VMware exit decisions in the first place.

Filed Under: Storage Tagged With: flash inflation, ioGuardian, refurbished SSDs, RF3, SAN Refresh, secondary market, VergeOS, VMware exit

855-855-8300

Get Started

  • Versions
  • Request Tour

VergeIO For

  • SAN Replacement
  • Solving Infrastructure Modernization Challenges
  • Artificial Intelligence
  • Hyperconverged
  • Server Room
  • Secure Research Computing

Product

  • Benefits
  • Documents
  • Architecture Overview
  • Use Cases
  • Videos

Company

  • Blog
  • Technical Documentation
  • Legal

© 2026 VergeIO. All Rights Reserved.