• Skip to main content
  • Architecture
    • Overview
      Learn about VergeOS’ unique unfied architecture that integrates virtualization, storage, networking, AI, backup and DR into a single data center operating system
    • Infrastructure Wide Deduplication
      VergeOS transforms deduplication from a storage-only commodity into a native, infrastructure-wide capability that spans storage, virtualization, and networking, eliminating hidden resource taxes
    • VergeFS
      VergeFS is a distributed, high-performance global file system integrated into VergeOS, unifying storage across nodes, tiers, and workloads while eliminating the need for external SANs
    • VergeFabric
      VergeFabric is VergeOS’s integrated virtual networking layer, delivering high-speed, low-latency communication across nodes while eliminating the complexity of traditional network configurations.
    • Infrastructure Automation
      VergeOS integrates Packer, Terraform, and Ansible to deliver an end-to-end automation pipeline that eliminates infrastructure drift and enables predictable, scalable deployments.
    • VergeIQ
      Unlock secure, on-premises generative AI—natively integrated into VergeOS. With VergeIQ, your enterprise gains private AI capabilities without the complexity, cloud dependency, or token-based pricing.
  • Features
    • Virtual Data Centers
      A VergeOS Virtual Data Center (VDC) is a fully isolated, self-contained environment within a single VergeOS instance that includes its own compute, storage, networking, and management controls
    • High Availability
      VergeOS provides a unified, easy-to-manage infrastructure that ensures continuous high availability through automated failover, storage efficiency, clone-like snapshots, and simplified disaster recovery
    • ioClone
      ioClone utilizes global inline deduplication and a blockchain-inspired file system within VergeFS to create instant, independent, space-efficient, and immutable snapshots of individual VMs, volumes, or entire virtual data centers.
    • ioReplicate
      ioReplicate is a unified disaster-recovery solution that enables simple, cost-efficient DR testing and failover via three‑click recovery of entire Virtual Data Centers—including VMs, networking, and storage.
    • ioFortify
      ioFortify creates immutable, restorable VDC checkpoints and provides proactive ransomware detection with instant alerts for rapid recovery and response.
    • ioMigrate
      ioMigrate enables large-scale VMware migrations, automating the rehosting of hundreds of VMs (including networking settings) in seconds with minimal downtime by seamlessly transitioning entire VMware environments onto existing hardware stacks.
    • ioProtect
      ioProtect offers near-real-time replication of VMware VMs—including data, network, and compute configurations—to a remote disaster‑recovery site on existing hardware, slashing DR costs by over 60% while supporting seamless failover and testing in an efficient, turnkey VergeOS Infrastructure.
    • ioOptimize
      ioOptimize leverages AI and machine learning to seamlessly integrate new and old hardware and automatically migrate workloads from aging or failing servers.
    • ioGuardian
      ioGuardian is VergeIO’s built-in data protection and recovery capability, providing near-continuous backup and rapid VM recovery during multiple simultaneous drive or server failures.
  • IT Initiatives
    • VMware Alternative
      VergeOS offers seamless migration from VMware, enhancing performance and scalability by consolidating virtualization, storage, and networking into a single, efficient platform.
    • Hyperconverged Alternative
      VergeIO’s page introduces ultraconverged infrastructure (UCI) via VergeOS, which overcomes HCI limitations by supporting external storage, scaling compute and storage independently, using existing hardware, simplifying provisioning, boosting resiliency, and cutting licensing costs.
    • SAN Replacement / Storage Refresh
      VergeIO’s storage by replacing aging SAN/NAS systems within its ultraconverged infrastructure, enhancing security, scalability, and affordability.
    • Infrastructure Modernization
      Legacy infrastructure is fragmented, complex, and costly, built from disconnected components. VergeOS unifies virtualization, storage, networking, data protection, and AI into one platform, simplifying operations and reducing expenses.
    • Secure Research Computing
      VergeIO's Secure Research Computing solution combines speed, isolation, compliance, scalability, and resilience in a cohesive platform. It’s ideal for institutions needing segmented, compliant compute environments that are easy to deploy, manage, and recover.
    • Venues, Remote Offices, and Edge
      VergeOS delivers resiliency and centralized management across Edge, ROBO, and Venue environments. With one platform, IT can keep remote sites independent while managing them all from a single pane of glass.
  • Blog
      • VMware Migration Testing Is Critical to Completing Your ExitVMware migration testing decides whether your exit finishes. VergeOS keeps the VMware image, takes instant snapshots and isolates each workload in a VDC.
      • How to Use Hard Drive Tiering to Fight Data Center InflationHard drive tiering is back. See how VergeOS lets you pick each drive's tier, move it live, and put the long tail on $56/TB disk instead of $706/TB flash.
      • Leave No VM BehindA complete VMware migration includes clustered SQL Server. VergeOS 26.2 shortens cutover and protects critical workloads inside isolated VDCs.
    • View All Posts
  • Resources
    • Become a Partner
      Get repeatable sales and a platform built to simplify your customers’ infrastructure.
    • Technology Partners
      Learn about our technology and service partners who deliver VergeOS-powered solutions for cloud, VDI, and modern IT workloads.
    • White Papers
      Explore VergeIO’s white papers for practical insights on modernizing infrastructure. Each paper is written for IT pros who value clarity, performance, and ROI.
    • In The News
      See how VergeIO is making headlines as the leading VMware alternative. Industry analysts, press, and partners highlight our impact on modern infrastructure.
    • Press Releases
      Get the latest VergeOS press releases for news on product updates, customer wins, and strategic partnerships.
    • Case Studies
      See how organizations like yours replaced VMware, cut costs, and simplified IT with VergeOS. Real results, real environments—no fluff.
    • Webinars
      Explore VergeIO’s on-demand webinars to get straight-to-the-point demos and real-world infrastructure insights.
    • Documents
      Get quick, no-nonsense overviews of VergeOS capabilities with our datasheets—covering features, benefits, and technical specs in one place.
    • Videos
      Watch VergeIO videos for fast, focused walkthroughs of VergeOS features, customer success, and VMware migration strategies.
    • Technical Documentation
      Access in-depth VergeOS technical guides, configuration details, and step-by-step instructions for IT pros.
  • How to Buy
    • Schedule a Demo
      Seeing is believing, set up a call with one of our technical architects and see VergeOS in action.
    • Versions
      Discover VergeOS’s streamlined pricing and flexible deployment options—whether you bring your own hardware, choose a certified appliance, or run it on bare metal in the cloud.
    • Test Drive – No Hardware Required
      Explore VergeOS with VergeIO’s hands-on labs and gain real-world experience in VMware migration and data center resiliency—no hardware required
  • Company
    • About VergeIO
    • Support
      Get fast, expert help from VergeIO’s support team—focused on keeping your infrastructure running smoothly.
    • Careers
      Join VergeIO and help reshape the future of IT infrastructure. Explore open roles and growth opportunities.
  • 855-855-8300
  • Contact
  • Search
  • 855-855-8300
  • Contact
  • Search
  • Architecture
    • Overview
    • VergeFS
    • VergeFabric
    • Infrastructure Automation
    • VergeIQ
  • Features
    • Virtual Data Centers
    • High Availability
    • ioClone
    • ioReplicate
    • ioFortify
    • ioMigrate
    • ioProtect
    • ioOptimize
    • ioGuardian
  • IT Initiatives
    • VMware Alternative
    • Hyperconverged Alternative
    • SAN Replacement / Storage Refresh
    • Infrastructure Modernization
    • Secure Research Computing
    • Venues, Remote Offices, and Edge
  • Blog
  • Resources
    • Become a Partner
    • Technology Partners
    • White Papers
    • In The News
    • Press Releases
    • Case Studies
    • Webinars
    • Documents
    • Videos
    • Technical Documentation
  • How to Buy
    • Schedule a Demo
    • Versions
    • Test Drive – No Hardware Required
  • Company
    • About VergeIO
    • Support
    • Careers
×
  • Architecture
    • Overview
    • VergeFS
    • VergeFabric
    • Infrastructure Automation
    • VergeIQ
  • Features
    • Virtual Data Centers
    • High Availability
    • ioClone
    • ioReplicate
    • ioFortify
    • ioMigrate
    • ioProtect
    • ioOptimize
    • ioGuardian
  • IT Initiatives
    • VMware Alternative
    • Hyperconverged Alternative
    • SAN Replacement / Storage Refresh
    • Infrastructure Modernization
    • Secure Research Computing
    • Venues, Remote Offices, and Edge
  • Blog
  • Resources
    • Become a Partner
    • Technology Partners
    • White Papers
    • In The News
    • Press Releases
    • Case Studies
    • Webinars
    • Documents
    • Videos
    • Technical Documentation
  • How to Buy
    • Schedule a Demo
    • Versions
    • Test Drive – No Hardware Required
  • Company
    • About VergeIO
    • Support
    • Careers

VMware exit

October 20, 2026 by George Crump

VergeOS 26.2 moves the data faster. Snapshots and virtual data centers prove each workload runs before it goes into production.

VMware migration testing is one of the most important parts of selecting and moving to a VMware alternative. I mean the big migration, when you move everything into production. That is a different job from moving a few VMs during a proof of concept, which I covered in How to Create a VMware Migration Test. As we will show in our webinar, Finish the VMware Exit, the latest VergeOS release raises the bar for fully exiting VMware.

In our lab, transfer performance runs 2.2 times faster than VergeOS 26.1.8, so even large workloads complete their move. VergeFS now supports shared disks for Microsoft Failover Clustering. That means clustered applications like SQL Server and file services migrate too. These changes move data and applications into VergeOS, where you enjoy our simple server-based licensing model. You also get the operational simplicity of a unified codebase.

Key Takeaways
  • VergeOS stores the original VMware image and offers a snapshot when you create the VM, so a failed test sends you back to the original state without re-copying data.
  • VergeOS snapshots take less than a second, use almost no capacity, and stand independent of each other, so any snapshot can become the new source.
  • Placing each migrated workload in its own Virtual Data Center isolates VMware migration testing, caps CPU and GPU use, and lets many testers work in parallel.

Why VMware Migration Testing Decides the Exit

Completing the move to a VMware alternative is about more than getting data and applications from point A to point B. Everything has to work when it gets there. Migration capability belongs on the short list of requirements for any VMware alternative, but moving the data only proves the platform can receive it. VMware migration testing proves the applications run, which is critical, and VergeOS uniquely excels here.

Key Terms
VMware Migration Testing
Validating that each migrated workload runs correctly on the new platform before it goes into production.
Virtual Data Center (VDC)
The VergeOS implementation of multi-tenancy. A VDC holds VMs, networks, storage, and policies in an isolated environment that IT manages as one unit.
Independent Snapshot
A VergeOS snapshot with no dependency on other snapshots or the original source. Any snapshot can become the new source, and you can delete the rest.

Snapshots Make VMware Migration Testing Safe

VergeOS Keeps the Original VMware Image

After your VMware data set arrives on VergeOS, it stays in its original VMware format at first. VergeOS stores the VMware image. If something goes wrong in testing, you return to it without re-copying data from the VMware environment. Then, when you create that VM under VergeOS, it asks whether you want to create a snapshot. That gives you a second copy of the original state before the first test runs.

Snapshots Built for Aggressive Testing

Those snapshots let you test aggressively. You can take as many as you want. Each takes less than a second, with almost no capacity impact. VergeOS snapshots are also independent of each other and of the original source. For example, you can make snapshot 100 the new source and delete all the other snapshots. The same cleanup on a dedicated external array can take hours, or even days, to reclaim space.

Snapshots make VMware migration testing safeSNAPSHOTS · SAFE TESTINGVMware VMsource environmentVergeOSOriginal VMware imageKept on VergeFS. Revert without re-copying.VM created under VergeOSCreate a snapshot?Yes ✓SNAPSHOTS · UNDER A SECOND EACH#1#2#3#4#5#6#7…#99#100New sourceDelete the rest. No chain to unwind.CAPACITY IMPACTalmost none

Virtual Data Centers for VMware Migration Testing

The next way VergeOS excels is our Virtual Data Center (VDC) technology, our take on multi-tenancy. It is also the most distinctive and underused. Most customers use VDCs in production. Cloud service providers create a tenant for each client. Enterprises use VDCs to isolate mission-critical workloads from standard business workloads. That same isolation makes VDCs ideal for testing.

One Workload, One VDC

A testing best practice is to migrate by workload instead of one VM at a time. We suggest that each workload you migrate goes into its own VDC. That isolates it from the workloads you have already migrated, which ideally sit in their own VDCs. Now you can test the latest workload relentlessly without impacting other workloads. You can also control how much CPU and GPU a workload gets, so a runaway process can’t steal resources from workloads you have already certified and are now running in production on VergeOS.

One workload, one VDCONE WORKLOAD, ONE VDCVergeOSVDCProd ✓VDCProd ✓VDCProd ✓Test VDC · newest workloadVMVMVMtestCPUGPUA runaway process stops at its cap.Certified workloads keep their resources.

Mass VMware Migration Testing with VDC Snapshots

You can take VDCs a step further. First, migrate the workload into a VDC with all of its special network and configuration settings intact. Next, make five or ten snapshots of it. Then assign each one to a fellow IT staffer, or even an application stakeholder, for mass testing.

The IP addresses and other settings within each VDC can be the same. The VDC technology keeps them isolated, so testers work without IP address conflicts. If one tester breaks the application, the other testers keep working. If another tester creates the perfect configuration, you promote that version. Then you delete all the others, including the original.

Mass VMware migration testing with VDC snapshotsMASS TESTING · VDC SNAPSHOTSOrder app VDCmigrated workload · 10.0.0.105 SNAPSHOTSCopy 1Order app10.0.0.10ITCopy 2Order app10.0.0.10brokenDBACopy 3Order app10.0.0.10App ownerCopy 4Order app10.0.0.10ITCopy 5Order app10.0.0.10Stakeholderothers unaffectedbest configPromoted copyFive copies of one workload. Same IPs, no conflicts.

Prove the Cluster Before Cutover

This approach pays off most with clustered applications. Migrate a SQL Server failover cluster into its own VDC, snapshot it, and hand copies to the DBA team and the application owners. One tester shuts down a cluster node. That tester confirms the shared disk on VergeFS changes hands through SCSI-3 Persistent Reservations and the database comes back online. Another runs the month-end workload against the cluster. All of this happens before production depends on the cluster, giving application owners the confidence they need to approve cutover.

Prove the cluster before cutoverPROVE THE CLUSTERTest VDC · SQL Server clusterSQL Node 1ownerSQL Node 1shut down ✕SQL Node 2standbySQL Node 2new ownerVergeFS shared diskSCSI-3 Persistent ReservationsDatabase onlineFailover proven before production depends on it.

Add AI to Your VMware Migration Testing Team

With the GPU management built into VergeOS, you can even run a local AI LLM as part of the testing team. It puts the application through its paces alongside your staff and stakeholders. The model runs on your own GPUs inside its own VDC and works through test cases around the clock. Your application data stays inside your environment.

AI on the VMware migration testing teamAI ON THE TESTING TEAMTest VDCGPUlocal LLMMigratedappTEST CASES · AROUND THE CLOCK✓ Logins and permissions✓ Month-end batch run✓ Reports and integrations✓ Edge cases at 3:00 AMYour GPUs. Your data stays in your environment.
Live Webinar · October 22 · 12:00 PM CT
Finish the VMware Exit
Aaron Richman and Dave Vincent demonstrate faster migration, Failover Clustering on VergeFS, and VDCs for testing and protection.
Register

Finish the VMware Exit

From Tested to Production

The certified VDC becomes production. You put into service the environment your testers approved, with its VMs, network settings, and configuration. Nothing gets rebuilt or re-entered between the last test and go-live. When the next workload arrives, you start the process again in a new VDC. The production VDCs you already certified stay untouched.

From tested to productionFROM TESTED TO PRODUCTIONTestingProductionCertified VDCtests passed ✓Same VDC, same settings. Nothing rebuilt.

Parallel Testing Shortens the Exit

Testing is where most migration timelines slip. Parallel VMware migration testing changes that. When several testers and an AI model work against identical copies of the same workload, serial testing that delays cutover shrinks. Each workload reaches production sooner, the next one starts in its own VDC, and the last workloads leave VMware on a schedule you control instead of one the testing backlog sets.

Parallel testing shortens the exitPARALLEL TESTING SHORTENS THE EXITOne tester at a timecutoverParallel VMware migration testingtesters + AI model on identical VDC copiescutoverEach workload reaches production sooner.

See VergeOS 26.2 Live

VergeOS 26.2 moves the data faster and brings clustered applications across. Its snapshots and VDCs let you prove everything works once it arrives. The VergeOS 26.2 datasheet covers everything in the release. Leave No VM Behind explains how 26.2 moves the last workloads off VMware. Aaron Richman and Dave Vincent demonstrate it live on Thursday, October 22, 2026, at 12:00 PM CT. Register for Finish the VMware Exit, or schedule a technical whiteboard session to plan your own migration and testing approach.

Finish the VMware exitFINISH THE VMWARE EXITVMwareVergeOSClustered SQL Server included.LIVE DEMO · OCT 22 · 12:00 PM CT

VMware Migration Testing on VergeOS

Testing NeedWhat VergeOS Provides
Fall back to the originalStored VMware image plus a snapshot at VM creation
Many test iterationsSnapshots in under a second with almost no capacity impact
Keep the winner, drop the restIndependent snapshots, any one can become the new source
Protect production during testsOne VDC per workload with CPU and GPU limits
Parallel testersVDC snapshots per tester with the same IP addresses
Clustered applicationsFailover tests on VergeFS shared disks inside an isolated VDC
Go-liveThe certified VDC becomes production, with nothing rebuilt
Frequently Asked Questions
What is VMware migration testing?
It validates each migrated workload on the new platform before it goes into production. That covers application behavior, network configuration, and performance.
Can I return to the original VMware VM if a test fails?
Yes. VergeOS stores the VMware image and offers a snapshot when you create the VM. You return to the original state without re-copying data from VMware.
Why put each migrated workload in its own VDC?
A VDC isolates the workload from everything already in production and caps its CPU and GPU use. It also lets several testers work on copies with identical IP addresses and no conflicts.

Next Steps

The datasheet, the live demonstration and the first 26.2 blog are one click away.
Datasheet
VergeOS 26.2
Faster VMware migration, Failover Clustering on VergeFS and single-server distributed data centers.
Live Webinar · October 22
Finish the VMware Exit
Aaron Richman and Dave Vincent demonstrate the release. 12:00 PM CT.
Blog
Leave No VM Behind
How VergeOS 26.2 moves clustered SQL Server and the last workloads off VMware.

Filed Under: VMwareExit Tagged With: migration testing, snapshots, SQL Server, VergeOS 26.2, virtual data center, VMware, VMware exit, VMware migration

October 13, 2026 by George Crump

A complete VMware migration now includes clustered SQL Server. VergeOS 26.2 cuts migration transfer time by about 55 percent and protects mission-critical workloads inside isolated virtual data centers.

A complete VMware migration moves every workload, including the clustered SQL Server instances that nobody wants to touch. Most VMware exits start with the easy virtual machines. File servers, web tiers and test systems move quickly. Then the project stalls on two problems: the cutover window for large, busy VMs and the Windows workloads that depend on Microsoft Failover Clustering. The organization ends up running two hypervisors and paying VMware to protect a handful of servers. VergeOS 26.2 solves both problems, so IT can finish a complete VMware migration.

Key Takeaways
  • VergeOS 26.2 adds asynchronous I/O to NBD transfers, so initial and final migration transfers finish in about 55 percent less time and cutover windows shrink.
  • Microsoft Failover Clustering now runs on VergeFS with shared disks and SCSI-3 Persistent Reservations, so a complete VMware migration includes clustered SQL Server.
  • Virtual data centers encapsulate those workloads for portable test and DR, and isolate them from the rest of the environment.

Why a Complete VMware Migration Stalls

A complete VMware migration stalls when clustered SQL Server stays behind on VMware VMware VMware Alternative Clustered SQL Migration progress Stalls at the last workloads

The last workloads in a VMware estate are the ones the business depends on most. They run the ERP database, the order system and the applications with uptime commitments written into contracts. Two issues hold them back. Large VMs with high change rates need a cutover window that application owners refuse to approve. Windows workloads protected by Microsoft Failover Clustering need a shared disk with SCSI-3 Persistent Reservations, a requirement that has historically pushed customers toward a dedicated storage array.

When those requirements go unmet, IT keeps a small VMware cluster running next to the new platform. That choice means two management interfaces, two support contracts and a VMware renewal sized around the servers that matter to the business. Many teams renew VMware for just one year to buy time, and the renewal repeats every year the hard workloads stay put. The exit stays incomplete, and the savings that justified it shrink.

Shorter Cutover for a Complete VMware Migration

VergeOS 26.2 cuts migration transfer time by about 55 percent compared to the previous VergeOS release Migration transfer time Previous VergeOS release VergeOS 26.2 About 55% less time 2.2x faster NBD transfers

The VergeOS VMware migration service has used changed block tracking for years. First, it copies the full VM with the source still running. Then it sends only the blocks that changed since the last pass. At cutover, the source VM powers off, the last changed blocks transfer, and the VM boots on VergeOS. Version 26.2 adds asynchronous I/O to its network block device (NBD) transfers, so both the initial full copy and the final transfer move faster. In VergeIO lab testing against VergeOS 26.1.8, transfers ran 2.2 times faster, cutting transfer time by about 55 percent.

A cutover that fits inside a standard maintenance window gets approved. One that stretches past it gets deferred, and deferred workloads are how VMware exits stall.

Mission-Critical Windows Workloads on VergeFS

SQL Server Failover Cluster Instances and clustered file servers rely on a shared disk that every cluster node can reach. Microsoft Failover Clustering also uses SCSI-3 Persistent Reservations to control which node owns that disk at any moment. VergeOS 26.2 delivers both inside VergeFS, the storage layer built into VergeOS. VergeFS aggregates the drives inside each server into a single high-performance pool, so the cluster gets its shared disk from the same servers that run it.

Clustered SQL Server now moves with the rest of the estate. For the workloads that kept VMware in the data center, a complete VMware migration is finally on the table.

Three VMware hosts in production Drain host 3 with vMotion Install VergeOS on host 3 Full copy of host 2’s workloads into VergeOS Validate the copies on VergeOS Incremental pass: changed blocks only Cutover: host 2’s workloads now run on VergeOS Move SQL node B to host 1 with vMotion Install VergeOS on host 2 Balance workloads across both VergeOS hosts Full copy of host 1’s workloads into VergeOS Validate, then send changed blocks only Cutover: only the SQL cluster remains on VMware Last move: the SQL cluster and its shared disk Final pass, then cutover to a VergeFS shared disk Install VergeOS on host 1 and retire the array Same three servers, one VergeOS cluster Add File node B: a file cluster with no new hardware VMware ESXiHost 1 VergeOSHost 1 VMware ESXiHost 2 VergeOSHost 2 VMware ESXiHost 3 VergeOSHost 3 Web 1 Web 2 File App 1 App 2 Print Dev Test SQL node A SQL node B App 1 App 2 Print Test Web 1 Web 2 FileFile node A Dev SQL node A SQL node B Storage array | shared disk VergeFS shared disk spans hosts 2 and 3 | SCSI-3 PR VergeFS spans all three hosts | SCSI-3 PR shared disk File node B LEAVE NO VM BEHIND | ONE CLUSTER, SAME SERVERS, NO ARRAY
One host at a time on the same servers. General workloads move first, and the SQL Server failover cluster and its shared disk move last, onto VergeFS. Once the move is complete, the file server becomes a cluster with no new infrastructure.

Protect Mission-Critical Workloads After a Complete VMware Migration

VergeOS virtual data centers (VDCs) give these workloads a home of their own. A VDC encapsulates virtual machines, virtual networks, storage and policies into a single object that IT manages as a unit. The clustered database, its application servers and the network that connects them all live inside one VDC.

A VergeOS virtual data center encapsulates mission-critical workloads after a complete VMware migration for test clones, DR replication and ransomware isolation Virtual Data Center SQL Cluster App Servers Virtual network Storage and policies Test cloneSame addressing, isolated network DR siteWhole VDC replicated as one unit Ransomware stops at the VDC boundary

Portable for Test and DR

IT snapshots, clones and replicates the entire VDC as one object. For example, cloning a production VDC creates a copy of the application environment, network configuration included, for testing patches, upgrades or a new SQL Server version without touching production. The clone keeps its internal addressing inside its own isolated network, so nobody re-addresses servers for a test lab. For disaster recovery, IT replicates the VDC to a second VergeOS site and brings up the whole application environment there with its networking intact.

Isolated from Ransomware

Each VDC runs in its own network space, separate from other VDCs and from the host environment. Ransomware that compromises a workstation or a general-purpose server elsewhere reaches the VDC holding the clustered database only through the paths IT explicitly allows. That boundary limits lateral movement, the technique attackers use to spread from an initial foothold to the systems that hold the most valuable data. Frequent VergeOS snapshots of the VDC also give IT a clean, complete point to recover from.

Live Webinar · October 22 · 12:00 PM CT
See VergeOS 26.2 Live
Aaron Richman and Dave Vincent demonstrate faster migration, Failover Clustering on VergeFS and VDC protection.
Register
Key Terms
Network Block Device (NBD)
The transport VergeOS uses to read VM disks from VMware during migration, with changed block tracking limiting later passes to the blocks that changed.
SCSI-3 Persistent Reservations
The disk-locking mechanism Microsoft Failover Clustering uses to control which node owns a shared disk.
Virtual Data Center (VDC)
A VergeOS object that encapsulates VMs, networks, storage and policies so IT manages, protects and moves them as one unit.

Before and After VergeOS 26.2

WorkloadWhat Held It on VMwareVergeOS 26.2
Large, busy VMsCutover window too longAsynchronous I/O on NBD cuts transfer time by about 55 percent
Clustered SQL ServerShared disk with SCSI-3 PRFailover Clustering on VergeFS
Critical app environmentsHard to clone, test and recover as a unitVDC snapshots, clones and replication

Finish Your Complete VMware Migration

VergeOS 26.2 removes the two most common reasons VMware migrations stop short. Once the workloads move, VDCs keep them portable and isolated. The VergeOS 26.2 datasheet covers everything in the release. Aaron Richman and Dave Vincent demonstrate it live on Thursday, October 22, 2026, at 12:00 PM CT. Register for the webinar. To scope your own exit, start with the VMware Exit Readiness Assessment or schedule a technical whiteboard session.

Frequently Asked Questions
Can a complete VMware migration include clustered SQL Server?
Yes. VergeOS 26.2 runs Microsoft Failover Clustering on VergeFS, which provides the shared disk and SCSI-3 Persistent Reservations from the drives inside the VergeOS servers.
How does VergeOS 26.2 shorten cutover?
Changed block tracking keeps the final transfer small, and asynchronous I/O on NBD cuts the time for both transfers by about 55 percent.
What does a virtual data center add for mission-critical workloads?
A VDC lets IT clone the full application environment for testing, replicate it for DR, and isolate it from other workloads to limit ransomware spread.

Next Steps

The datasheet, the live demonstration, the VDC overview and an exit readiness check are one click away.

Datasheet
VergeOS 26.2
Faster VMware migration, Failover Clustering on VergeFS and single-server distributed data centers.
Live Webinar · October 22
See VergeOS 26.2 Live
Aaron Richman and Dave Vincent demonstrate the release. 12:00 PM CT.
Platform
VergeOS Virtual Data Centers
Encapsulate, clone, replicate and isolate entire application environments.
Assessment · 3 Minutes
VMware Exit Readiness Assessment
Check your pain points, see which part of VergeOS addresses each one and get a live savings estimate.

Filed Under: VMwareExit Tagged With: ransomware, SQL Server, VergeOS 26.2, virtual data center, VMware, VMware exit, VMware migration

October 12, 2026 by George Crump

Press Release

VergeOS 26.2 makes VMware migrations 120% faster, brings Microsoft Failover Clustering to VergeFS, and extends to single-server distributed data centers.

ANN ARBOR, Mich., October 13, 2026 – VergeIO, the infrastructure software company, today announced the immediate availability of VergeOS 26.2. VergeIO customers use VergeOS to exit VMware, fight data center inflation, support distributed data centers, and prepare their infrastructure and their organization for private AI, eliminating per-token costs.

What’s new in VergeOS 26.2

  • Faster VMware migration. Initial and final transfers now run 120% faster.
  • Mission-critical Windows workloads. Microsoft Failover Clustering now runs on VergeFS.
  • Single-server distributed data centers. Remote sites need only one server with two network connections.

Faster VMware migration

The VergeOS VMware migration service has delivered rapid migrations for years through changed block tracking, which keeps cutover time short. VergeOS 26.2 adds asynchronous I/O to its network block device (NBD) transfers, making both the initial full backup and the final transfer 120% faster and shortening cutover even further.

Same VMware workload, two VergeOS releasesVergeOS 26.2 finishes in less than half the timeVMware ESXiVM 1VM 2VM 3VM 4VM 5VM 6VergeOSVM 1VM 2VM 3VM 4VM 5VM 6VergeOS 26.1DoneVergeOS 26.2 | asynchronous I/O for NBDDone120% faster2.2 times the transfer speed of VergeOS 26.1INITIAL FULL BACKUP | FINAL TRANSFER | 120% FASTER
The same VMware workload on VergeOS 26.1 and 26.2. Bar lengths reflect the measured 2.2x speedup.

A complete exit for mission-critical workloads

Mission-critical Windows workloads like Microsoft SQL Server typically rely on Microsoft Failover Clustering, which requires a shared disk and SCSI-3 Persistent Reservations. That requirement has often led customers to a dedicated storage array, stalled many VMware migrations, or left customers running two hypervisors. VergeOS 26.2 now supports Microsoft Failover Clustering within VergeFS, its internal storage capability, which aggregates commodity drives inside servers into a highly scalable, high-performance vSAN.

A VMware estate: general VMs and a SQL cluster The first migration waves move the general VMs The SQL cluster stays behind on its shared disk Two platforms, and the VMware renewal is still due VergeOS 26.2 puts a SQL node on each server The ESXi host converts to a VergeOS server VMs rebalance across three VergeOS servers VMware ESXiProduction VergeOSServer 3 VergeOSServer 1 VergeOSServer 2 Storage array | shared disk VergeFS shared disk spans both servers | SCSI-3 PR VergeFS shared disk spans all three servers | SCSI-3 PR VM 1 VM 2 VM 3 VM 4 SQL node A SQL node B VMware renewal still due ONE PLATFORM | NO SECOND RENEWAL | NO ARRAY
The last workloads decide whether the VMware renewal goes away.

Single-server distributed data centers

Distributed architectures like retail point-of-sale often run single-server data centers that replicate back to a core VergeOS implementation. VergeOS 26.2 lowers the requirements for these sites to one server with two network connections and no core network, so customers can bring those locations along in their VMware exit.

“VergeIO is focused on simplifying infrastructure design and operations by helping customers exit legacy stacks, reuse hardware to combat data center inflation, manage any number of distributed data centers, and prepare for on-premises AI workloads. Today’s release lets IT execute a faster, less disruptive, and more complete VMware exit.”

Parag Patel, CEO of VergeIO

Availability and live webinar

VergeOS 26.2 is available now. For details on each capability, see the VergeOS 26.2 datasheet. Aaron Richman, Field Evangelist, and Dave Vincent, Technical Solutions Strategist, will explain and demonstrate its capabilities in a live webinar on Thursday, October 22, at 12:00 PM CT. Register for the webinar.

About VergeIO

VergeOS is infrastructure software that customers use to replace VMware, fight data center inflation, support distributed data centers, and prepare their infrastructure for AI and private AI workloads. It is a single piece of software for the entire infrastructure that runs on bare metal on the servers the organization already owns. It can mix vendors and CPU generations within the same instance and helps customers run private AI on GPUs they already own, avoiding expensive token costs and maintaining data sovereignty. VergeIO is headquartered in Ann Arbor, Michigan. Learn more at verge.io.

Media contact

George Crump
CMO
VergeIO
[email protected]

###

Filed Under: Press Release Tagged With: Edge, Migration, Press Release, SQL Server, VergeOS, VergeOS26dot2, VMware, VMware exit, vSAN

September 17, 2026 by George Crump

Hardware fails whether it is new or refurbished. VergeOS turns drive and server failures into routine events, which makes refurbished hardware a practical way to fund the VMware exit.

Refurbished hardware makes financial sense for a VMware exit, but IT teams then ask, “What happens when a used drive or server fails?” Hypervisor license costs have skyrocketed over the past two years but hardware always costs more than the hypervisor license, and the 2026 memory and flash price spike has widened that gap. Many migration projects now stall at finance review. Reusing the servers already on the floor and adding refurbished drives brings the budget back within reach, provided the platform treats hardware failure as routine.

Key Takeaways
  • Every drive and server fails eventually, new or refurbished, so resiliency belongs in the software.
  • VergeOS keeps workloads running through drive and server failures, holds data online past the resiliency factor with ioGuardian, and recovers VMs and files from snapshots at no additional software cost.
  • The on-demand Premier Connects session shows each failure live, from a pulled drive to a full data center failover.

Why Refurbished Hardware Makes IT Nervous

Traditional Recovery PathDrive failsRAID rebuild startsSecond drive failsbefore the rebuild finishesArray goes offlineworkloads stopRestore from backupthe recovery clock starts

In a three-tier data center, the storage array protects blocks with RAID, and a second drive failure during a rebuild turns into a backup restore job with significant downtime. Legacy HCI moved storage into the servers and added workload restart, yet recovery still lives in a separate backup product on separate hardware, with its own license and its own console. In both designs, a failure that exceeds the protection level hands the problem to the backup team and starts the recovery clock.

Buying premium new hardware became the standard way to push that moment further out, which ties resiliency to a purchase order finance now keeps rejecting.

Resiliency and Protection for Refurbished Hardware

The Price of ResiliencyCostResiliencyRAID 5RF2RF3Longer retentionBubble size = performance impact

Resiliency keeps an application running with zero downtime and zero data loss when a component fails. Protection restores data after resiliency runs out. Every environment has a resiliency limit, and raising it costs money. RAID 5 costs the least, offers the least resiliency, and imposes the highest performance penalty. RF2 costs more with almost no performance impact, RF3 costs more again with none, and longer snapshot retention sits at the top of the scale.

VergeOS changes where that money goes. Each step up is a setting in the platform, so climbing the scale costs capacity instead of another software license. Refurbished drives make that capacity affordable. An organization can run RF3 with longer retention on the budget that once bought a smaller pool of new drives.

Saratoga Casino Holdings runs this model in production. The company moved to VergeOS on CXTEC® equal2new® refurbished servers and removed roughly $50,000 a year in Pure Storage array maintenance. Read the Saratoga Casino Holdings case study for the full story.

Resilient: Refurbished Hardware Keeps the Workload Running

VergeOS runs compute, storage, networking, and data protection in one code base. With RF2 or RF3 set per workload, a failed drive is invisible to the application. A server failure triggers an automatic restart of its workloads on the surviving nodes, with no operator in the loop. The age of the failed part makes no difference, so refurbished hardware delivers the same outcome as new hardware.

RF vs. RAID

RF vs. RAIDShare of raw capacityRAID 5Usable20-25%RAID 6Usable25-33%RF2Usable2nd copyGlobal inline dedup recovers most of the gapPerformanceNormalDrive failedRAID 5/6Parity penaltySevereRF2Almost noneNone

At first glance, RF2 looks like it doubles capacity consumption, since every block exists twice. The real gap is much smaller. RAID 5 gives up 20 to 25 percent of raw capacity to parity in a typical four or five drive group, and RAID 6 gives up 25 to 33 percent with two parity drives in a six to eight drive group. VergeOS global inline deduplication makes up for most of the difference. It works across every drive and server in the environment, so a block shared by many VMs is stored once.

Performance favors RF from the start. During normal production operations, RF2 has almost no performance impact, and it improves read performance, since VergeOS serves reads from multiple drives and servers. A failed drive leaves performance where it was, with the surviving copy answering every request. RAID 5 and RAID 6 pay a parity penalty on writes in normal operation, and the penalty grows sharply in a degraded state, when the array reconstructs data on every read and runs a rebuild at the same time. That degraded window is exactly where refurbished hardware puts the most pressure on a design, a point that has been characterized as storage recovery architecture mattering more than drive reliability.

Repairable: Data on Refurbished Hardware Stays Online Past the Limit

The hardest objection to refurbished hardware is a second failure before the first repair finishes. Two drives failing at once exceed RF2, and in most designs that means a restore. ioGuardian covers that window. A dedicated server, the ioGuardian target, delivers missing data segments to VMs in real time, so workloads keep running as the system repairs itself. The mechanics are covered in detail in Surviving Cascading Drive Failure.

▶
On-Demand Webinar · Premier Connects
Exit VMware to Resilient HCI
Aaron Richman and David Vincent fail drives, a server, and a full virtual data center live on VergeOS.
Watch Now →

Recoverable: Recovery From the Same Interface

Recovery Inside the PlatformVM volumeSnapshot 1Snapshot 2Snapshot 3Each ioClone snapshot is a standalone copyVirtual data centerVMs, network,storage settingsDR siterefurbishedhardwareThe whole environment fails over as one object

Some events have nothing to do with hardware, like an administrator deleting a VM or a user removing files. VergeOS snapshots use ioClone and behave as independent copies instead of a dependent chain, so retention is bounded by capacity. A deleted VM comes back instantly from a snapshot, and individual files recover through a hot plug drive attached to the running VM. Recovery works the same way on refurbished hardware as it does on new servers.

For a site-level event, a virtual data center encapsulates the VMs, networking, and storage settings, and it fails over to the DR site as one object. The DR site can run on refurbished hardware too.

How Each Design Handles Failure

FailureThree-TierLegacy HCIVergeOS
One driveRAID rebuild on the arrayHCI storage layerRF2 or RF3, workload unaffected
One serverHypervisor HA restartWorkload restartAutomatic restart on surviving nodes
Beyond the protection levelRestore from backup productRestore from backup productioGuardian keeps data online
Deleted VM or filesSeparate backup productSeparate backup productioClone snapshot, hot plug drive
Site lossArray replication plus runbooksReplication plus separate DR toolingVirtual data center failover
Protection software costSeparate licensesSeparate licensesIncluded in VergeOS
Key Terms
Resiliency factor (RF2, RF3)
The number of synchronous copies VergeOS keeps of each block, set per workload. RF2 survives one failure and RF3 survives two, on new or refurbished hardware.
ioGuardian
The VergeOS capability that delivers missing data segments to VMs in real time during multiple drive or server failures, using a dedicated server called the ioGuardian target.
ioClone
The VergeOS snapshot technology. Each snapshot behaves as an independent copy, so retention is bounded by capacity.
Virtual data center (VDC)
A single object that encapsulates VMs, networking, and storage settings, so the whole environment replicates and fails over together.

See Every Failure Now

The Premier Connects session, Exit VMware to Resilient HCI: Integrated Data Protection, Faster Recovery, and Built-In DR, walks through each stage in order. Aaron Richman, Field Evangelist, explains each feature, and David Vincent, Technical Evangelist, demonstrates it on a running VergeOS environment. The demos escalate from a pulled drive and a failed server to two failed drives, a deleted VM and files, and a full virtual data center failover. Watch the on-demand session to see how refurbished hardware made resilient changes the math on your VMware exit.

Frequently Asked Questions
Is refurbished hardware reliable enough for production?
Every drive and server fails eventually, new or refurbished. VergeOS plans for that failure with RF2 or RF3, ioGuardian, and snapshots, so production reliability comes from the platform instead of the age of the part.
What do these resiliency capabilities cost?
RF2 and RF3, ioGuardian, unlimited snapshots, instant recovery, and virtual data center failover come with VergeOS at no additional software cost.
Do I still need a backup product?
A backup product becomes optional, used for GUI-based single file recovery and long term archiving. VergeOS supports the backup platforms customers already run, including Veeam.

Next Steps

The on-demand session, the architecture behind it, and a customer running VergeOS on refurbished hardware are one click away.

On-Demand Webinar
Exit VMware to Resilient HCI
Live drive, server, and data center failures on VergeOS, from a pulled drive to VDC failover.
White Paper
Beyond the Hypervisor Swap
The VergeOS architecture in depth, including resiliency, recovery, and disaster recovery.
Case Study
Saratoga Casino Holdings
VergeOS on CXTEC® equal2new® refurbished servers, with Pure Storage array maintenance removed.

Filed Under: Storage, VMwareExit Tagged With: data protection, Disaster Recovery, ioGuardian, refurbished hardware, refurbished SSDs, RF3, VergeOS, VMware, VMware alternative, VMware exit

May 5, 2026 by George Crump

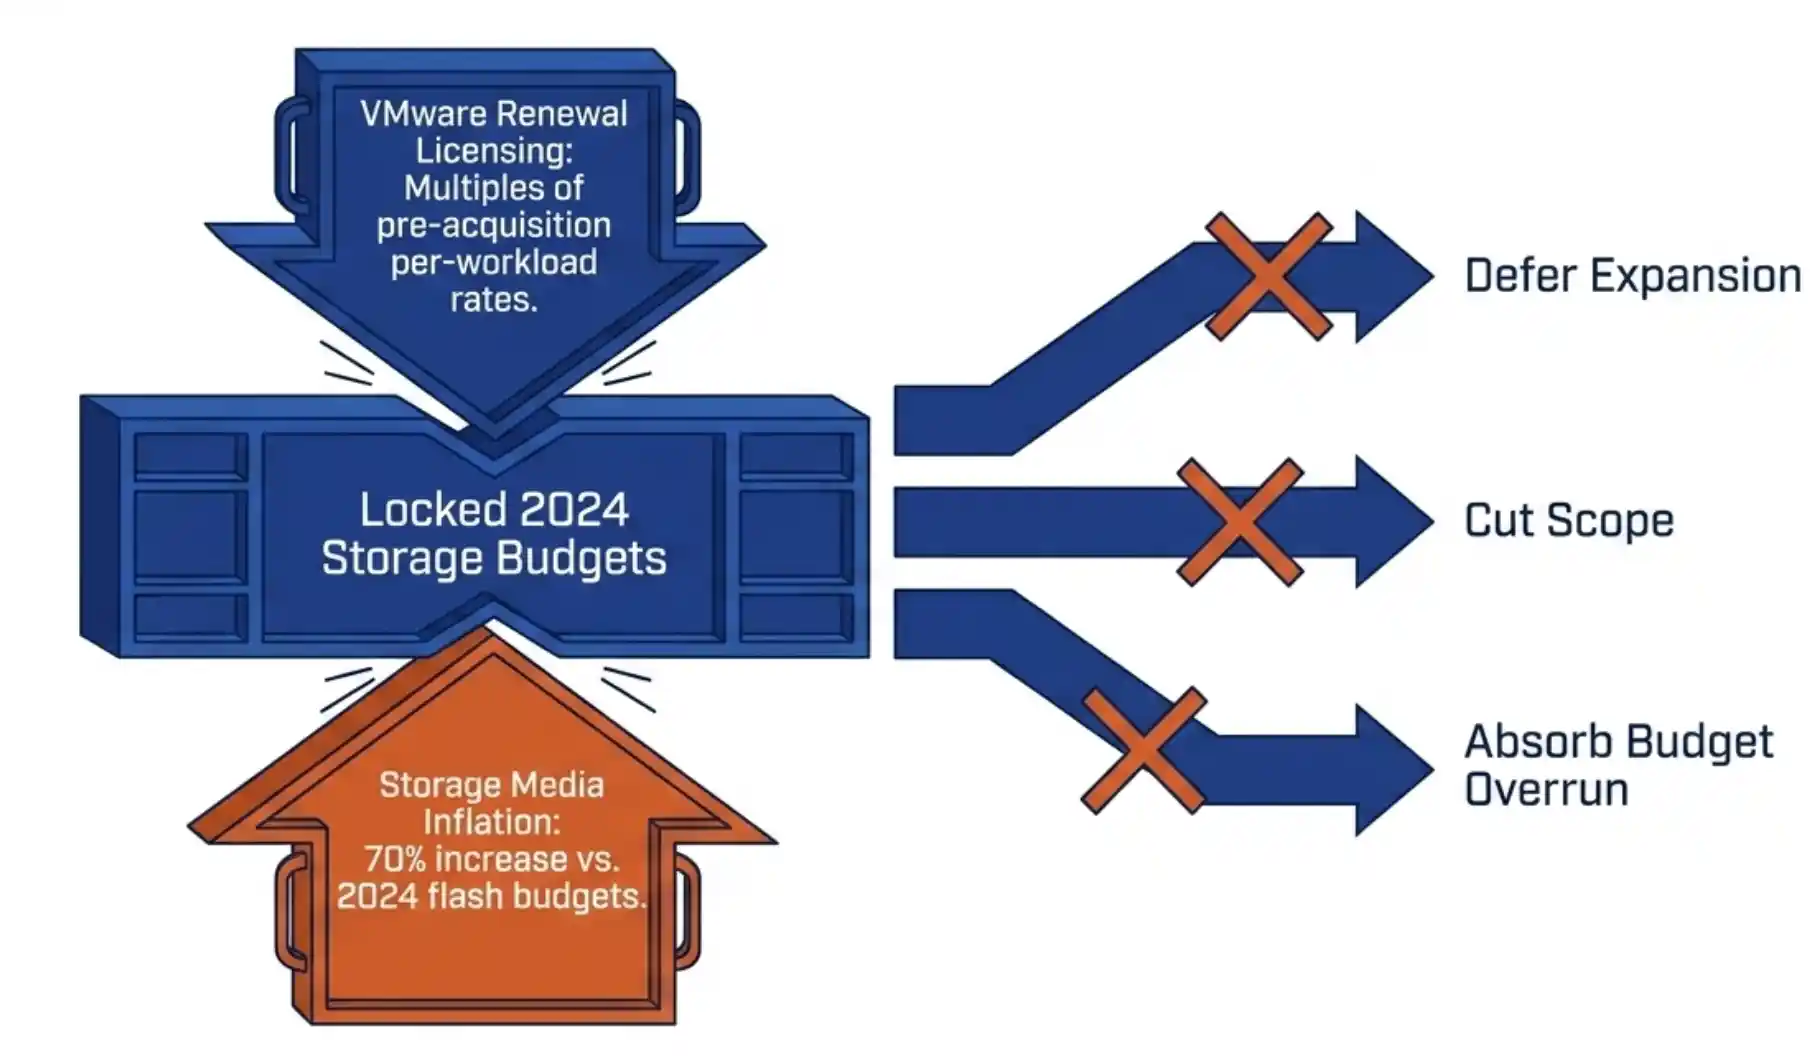
SAN refresh in trouble: 2026 flash inflation under-funds 2024 budgetsYour 2026 SAN refresh is in trouble. Flash inflation has pushed enterprise SSD prices up 70 percent. Refresh budgets locked in 2024 are now under-funded against current list pricing. The standard responses are to defer expansion, cut scope, or absorb the cost as a budget overrun. None of those options preserve the operational plan you set last year.
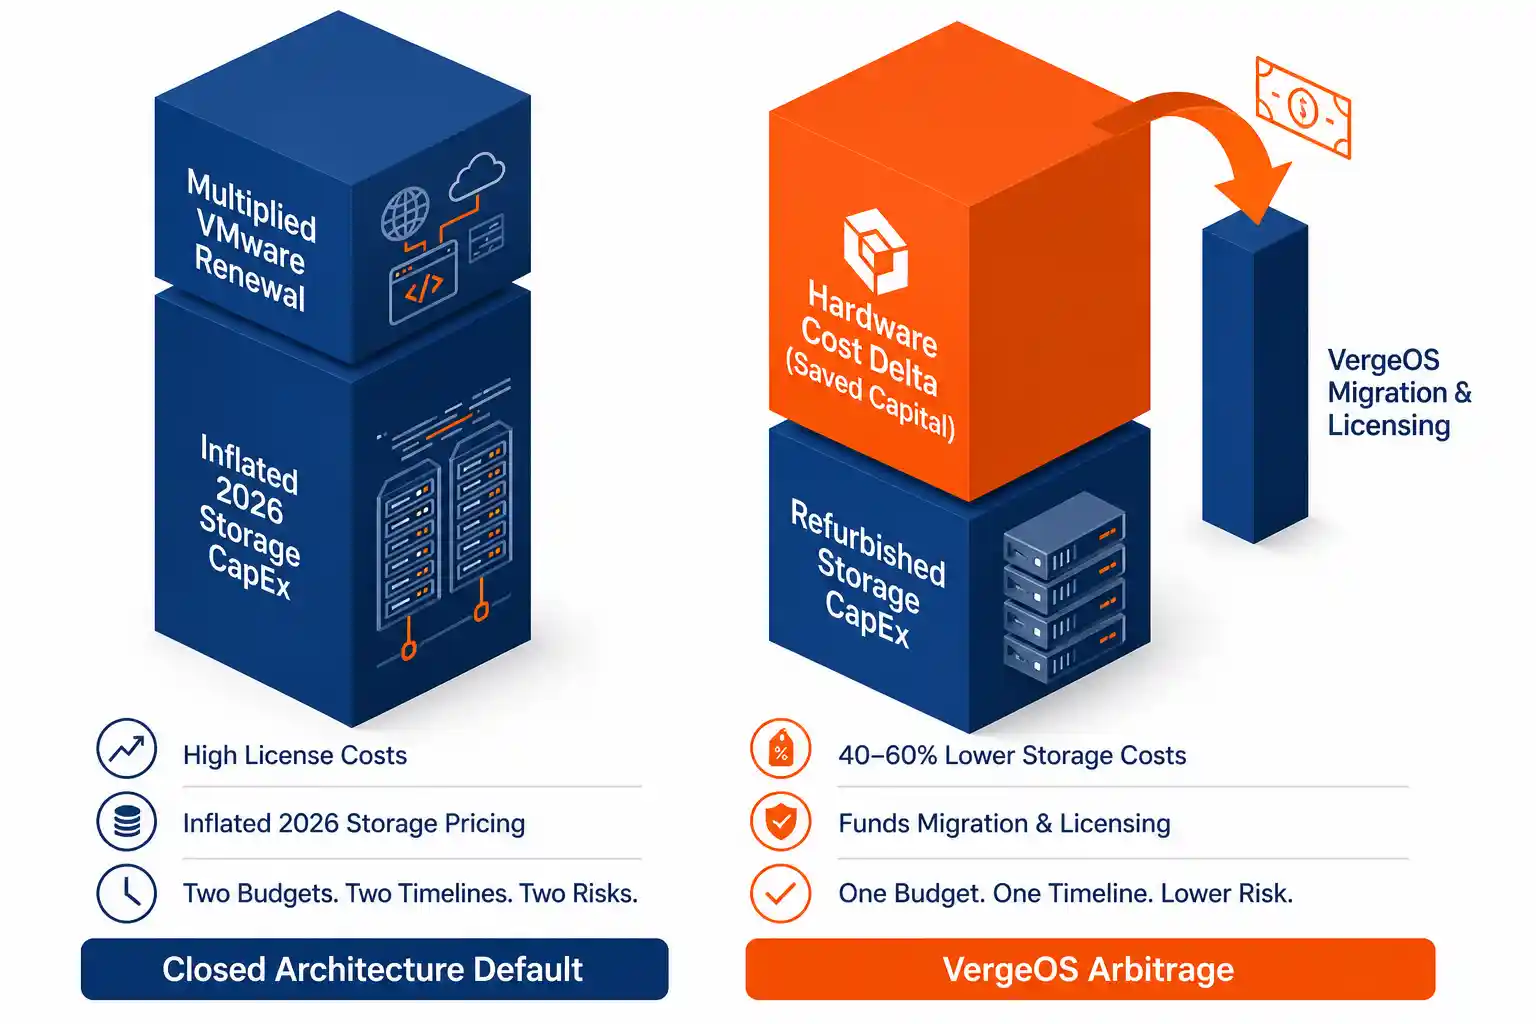
A fourth option exists. Capture the original capacity expansion at 40 to 60 percent of new flash list pricing using the secondary enterprise SSD market. Run that capacity on VergeOS instead of VMware. The hardware savings fund the platform exit. The SAN refresh costs less than it would have last year. The VMware exit pays for itself.

This is not two decisions. It is one decision executed once, with the savings stacking across both line items in the budget. The procurement framework and the architecture ship together, and the financial mechanism only works when both are deployed at the same time. This dynamic has been characterized as Broadcom’s best retention tool, since the same memory and flash supercycle that pushes refresh budgets underwater also makes the migration hardware harder to fund.

Key Takeaways
Refurbished enterprise SSDs sell at 40 to 60 percent below 2026 new flash list pricing, with 80 to 95 percent rated write life remaining at market entry.
The hardware cost delta on a SAN refresh covers the software and licensing line items of a VMware migration, converting a painful CapEx event into a near-neutral financial maneuver.
VergeOS synchronous replication with RF3 plus ioGuardian absorbs the failure rate of refurbished media without service interruption, validated by a documented customer event in which four of six hosts went down simultaneously with zero downtime and zero data loss.

Why the SAN Refresh and the VMware Exit Belong in the Same Decision

VergeOS arbitrage refresh stacks SAN and VMware exit savingsMost infrastructure teams treat their SAN refresh and their hypervisor strategy as separate problems. The SAN refresh is a procurement decision, owned by storage architects. The VMware exit is a platform decision, owned by virtualization leads and the CIO. The two budgets land in different fiscal lines, the two evaluation cycles run on different clocks, and the two vendor conversations rarely overlap.

That separation worked when storage and compute came from different vendors with different procurement paths. It does not work in 2026. VergeOS integrates storage, compute, networking, and virtualization into a single operating system. The SAN refresh and the platform exit run on the same code base, the same hardware substrate, and the same budget cycle. Treating them separately means buying two solutions where one will do.

The financial argument follows directly. A SAN refresh on VergeOS uses commodity x86 servers with refurbished enterprise SSDs at 40 to 60 percent below new flash list pricing. The capacity arrives at a fraction of the cost of a closed-architecture refresh. The hardware delta funds the VMware migration that the same cluster will host. The procurement decision and the platform decision compound into one financial outcome.

The Math: SAN Refresh Below 2025 Prices

The secondary enterprise SSD market is not a salvage market. Hyperscalers, MSPs, and Fortune 500 operators replace drives on rolling multi-year lease schedules, long before wear thresholds are met. Drives enter the secondary market with 80 to 95 percent of their rated write life remaining and 7,000 or more terabytes written endurance ratings intact. The supply is large, growing, and dominated by enterprise-grade media, not consumer drives.

The pricing math is direct. A 3.84TB enterprise SAS SSD sells new at $560 or more in current 2026 list pricing. The same drive, refurbished from a hyperscaler refresh cycle and qualified through a six-part procurement framework, sells at roughly $170. The delta is not 40 to 60 percent below 2026 list pricing. It is 40 to 60 percent below the inflated 2026 number, which means it lands competitively against what the same capacity would have cost new in 2024 or 2025.

40–60%
Cost reduction below 2026 new flash list pricing
80–95%
Rated write life remaining at secondary market entry
7,000+
Terabytes written endurance rating on enterprise refurbished

The procurement framework is the work. R2v3 supplier qualification confirms the drives came from a certified refurbisher with serialized inventory. NIST 800-88 sanitization certificates document compliant data destruction. Fraud detection verifies retail firmware against rebadged OEM drives. SMART diagnostics baseline the seven attributes that matter. Firmware validation confirms the drive runs vendor-released code. Stress testing proves the drive holds up under sustained workload. The framework is not optional. It is the difference between a SAN refresh strategy and a coin flip.

The Math: The Migration Pays for Itself

VMware renewal pricing has made the status quo untenable for a substantial portion of the installed base. Per-workload license pricing has climbed to multiples of pre-acquisition rates. The renewal conversation is no longer about a routine increase. It is about whether the platform is worth the new contract value at all.

The standard response is to evaluate alternatives, plan a migration, and request CapEx for the destination platform. The CapEx request is the problem. New compute, new storage, and new licensing all hit the budget in the same fiscal cycle, often in the same quarter. The financial picture looks like a one-time capital event piled on top of the existing operational baseline, and procurement defers the decision rather than absorb the impact.

The arbitrage play changes the picture. The VergeOS cluster pools existing flash with newly procured refurbished enterprise drives, creating a unified storage tier that runs at a fraction of standard hardware costs. The hardware cost delta on the SAN refresh creates the budget headroom that the VMware exit needs. The migration funds itself out of the savings on the storage line item. The CapEx request becomes a near-neutral request, or in many cases a net-positive one.

The financial mechanism only works when the SAN refresh and the VMware exit run on the same platform. Two separate vendors mean two separate budgets and two separate procurement cycles. One unified operating system collapses both decisions into one budget event with stacked savings.
Key Terms
Synchronous Replication

Storage architecture in which every block is written to multiple servers simultaneously. The write acknowledges only after all replicas land, eliminating the rebuild storms and parity-calculation windows that plague closed RAID architectures.

RF2 / RF3

VergeOS replication factors. RF2 keeps two synchronous copies and tolerates the loss of any one drive or host (N+1). RF3 keeps three synchronous copies and tolerates the simultaneous loss of any two drives or hosts (N+2). RF3 is the baseline for production workloads on refurbished media.

ioGuardian (N+X)

VergeOS active-service capability that absorbs concurrent failures beyond the base replication factor’s mathematical tolerance. Surviving replicas serve data at full performance during background re-replication, eliminating the secondary-failure window that turns a single hardware event into a service outage.

R2v3 Certification

The Responsible Recycling Standard, version 3, governs certified refurbishment and remarketing of electronic equipment. R2v3-certified suppliers maintain serialized inventory, documented sanitization processes, and verifiable provenance, which is the procurement floor for refurbished enterprise SSDs.

The Architectural Defense: Refurbished Media Becomes a Non-Event

The financial case is strong. The architectural objection is the question that stops most CFOs from approving the play. Refurbished drives carry a statistically higher failure probability than new drives, and the last thing any infrastructure team wants is a procurement decision that turns into a 2 a.m. outage. The right response to elevated drive failure probability is not avoidance. It is architecture that absorbs the elevated failure rate without service impact.

Live Webinar · May 7, 2026
Solve the Storage Crisis with Refurbished Enterprise Drives

George Crump and Aaron Richman walk the procurement framework, the architecture, and the migration sequencing in 45 minutes. Live Q&A included.

Register Now →

VergeOS protects data with synchronous replication, not RAID. Every block writes to multiple servers simultaneously. The write acknowledges only after all replicas land. There is no parity calculation, no rebuild process running across surviving spindles, no extended window where a single additional failure causes data loss. RF3 on VergeOS keeps three synchronous copies of every block across separate hosts, and the architecture mathematically tolerates the simultaneous loss of any two drives or hosts.

ioGuardian extends that tolerance further. The active-service capability keeps surviving replicas running at full performance during the re-replication window, eliminating the secondary-failure exposure that turns a single hardware event into a service outage on legacy systems. One VergeOS customer ran an RF2 cluster with ioGuardian protection across six servers. During a single incident, four of the six servers went down simultaneously. RF2 mathematically tolerates exactly one host failure. The math says the cluster should have suffered catastrophic data loss. The cluster experienced zero downtime and zero data loss. ioGuardian absorbed three concurrent failures beyond the base replication factor’s tolerance.

That magnitude of architectural over-engineering renders refurbished media failure rates irrelevant. A correlated batch failure across drives from the same lease cycle is the kind of event that would destroy a parity-based RAID set. On VergeOS with RF3 and ioGuardian, the same event is absorbed without service impact. The refurbished SSD strategy is not gambling on drive quality. It is deploying capacity in an architecture that does not depend on individual drive reliability.

SAN Refresh Comparison: Closed Architecture vs. VergeOS Arbitrage

 Closed Architecture RefreshVergeOS Arbitrage Refresh
Storage mediaNew flash, vendor-locked modulesRefurbished enterprise SSDs, commodity hardware
Pricing vs. 2025 list70 percent above 2025 listBelow 2025 list, competitive with 2024 pricing
Capacity expansion targetReduced to fit 2024 budgetOriginal target maintained
Failure protection modelParity-based RAID with rebuild stormsSynchronous replication with N+X ioGuardian
Hypervisor licensingVMware renewal at multi-fold increaseVergeOS integrated, no separate hypervisor cost
Migration fundingSeparate CapEx request, deferredFunded by hardware cost delta on the refresh

The Procurement Floor: How to Qualify Suppliers Without Gambling

The architectural defense answers the technical objection. The procurement objection is the practical one. How does a storage architect actually qualify suppliers without taking a position on every drive that arrives at the loading dock? The answer is the six-part intake framework, which converts refurbished SSD purchasing from a coin flip into a repeatable process.

The framework runs in sequence. R2v3 certification verifies the supplier’s chain of custody and serialized inventory. NIST 800-88 sanitization certificates confirm compliant data destruction on the drives entering the data center. Fraud detection verifies matching serials and retail firmware against rebadged OEM drives. SMART diagnostics baseline the seven attributes that matter for endurance and reliability. Firmware validation confirms the drives run vendor-released code, not modified or counterfeit firmware. Stress testing proves sustained-workload performance under realistic conditions.

The framework is the work. The savings are the reward. A SAN refresh built on this procurement floor delivers the cost advantage of the secondary market without importing the failure modes of the lower-tier suppliers, and it does so on a repeatable schedule that scales with the rest of the operational plan.

One Budget Cycle, Two Wins

Digital White Paper
Solve the Storage Crisis with Refurbished Enterprise Drives

The full framework. Fifteen sections covering the secondary market, the four risk categories, the six-part procurement funnel, and the VergeOS architecture that absorbs the residual risk.

Get the Paper →

The 2026 storage cost crisis is real. The VMware renewal pressure is real. The combination is what makes most infrastructure teams flinch and defer. The SAN refresh that pays for the VMware exit changes the financial calculation by stacking the savings rather than running them as separate decisions.

The procurement framework qualifies the drives. The architecture absorbs the risk. The cost delta funds the migration. The refresh costs less than it would have last year. The exit pays for itself. None of the three components work in isolation. All three deployed together produce a budget outcome that no other combination of vendors can match in the current supply environment.

The May 7 webinar walks through this play with real numbers. Register for the webinar.

Frequently Asked Questions
How much does a SAN refresh on VergeOS with refurbished enterprise SSDs cost compared to a new flash refresh in 2026?
Refurbished enterprise SSDs sell at 40 to 60 percent below 2026 new flash list pricing. A VergeOS refresh on commodity x86 servers with qualified refurbished SSDs runs at a fraction of the cost of a closed-architecture refresh. The exact savings depend on cluster size and capacity targets, but the math typically produces a hardware line item that lands below 2025 list pricing for the same capacity. The May 7 webinar walks through three cluster sizes with real numbers.
Are refurbished enterprise SSDs reliable enough for production workloads?
Refurbished enterprise SSDs from R2v3-certified suppliers carry 80 to 95 percent of their rated write life and ship with 7,000 or more terabytes written endurance ratings intact. They include power-loss protection, premium NAND binning, and the architectural features that consumer drives lack. The reliability case rests on two pillars: a six-part procurement framework that filters out fraud and OEM firmware lock, and an architecture that absorbs the residual failure rate without service interruption.
Can VergeOS pool existing legacy storage with newly procured refurbished SSDs?
Yes. VergeOS pools heterogeneous storage media seamlessly. Existing legacy flash continues serving production capacity alongside newly procured refurbished enterprise drives in the same cluster. The architecture treats hardware as commodity substrate, not as a procurement constraint. The flexibility is a critical part of the financial case for the VMware exit, since it eliminates the requirement to purchase 100 percent new storage as part of the migration.
Does the architectural strategy work with RF2, or does it require RF3?
RF3 is the baseline recommendation for production workloads on refurbished media. It tolerates the simultaneous loss of any two drives or hosts, and combined with ioGuardian it absorbs additional concurrent failures beyond the mathematical N+2 tolerance. RF2 with ioGuardian works for capacity-sensitive deployments and has a documented customer record of surviving four-of-six host failures with zero data loss. The choice depends on workload criticality and capacity targets.
What does the VMware migration look like operationally?
The VergeOS cluster runs alongside the VMware estate during the migration window. Workloads move in waves on a schedule the customer controls. The new platform absorbs production traffic as the old platform is decommissioned. The hardware cost delta from the SAN refresh provides the budget headroom for the licensing and migration services line items, which removes the financial barrier that defers most VMware exit decisions in the first place.

Filed Under: Storage Tagged With: flash inflation, ioGuardian, refurbished SSDs, RF3, SAN Refresh, secondary market, VergeOS, VMware exit

855-855-8300

Get Started

  • Versions
  • Request Tour

VergeIO For

  • SAN Replacement
  • Solving Infrastructure Modernization Challenges
  • Artificial Intelligence
  • Hyperconverged
  • Server Room
  • Secure Research Computing

Product

  • Benefits
  • Documents
  • Architecture Overview
  • Use Cases
  • Videos

Company

  • Blog
  • Technical Documentation
  • Legal

© 2026 VergeIO. All Rights Reserved.