• Skip to main content
  • Architecture
    • Overview
      Learn about VergeOS’ unique unfied architecture that integrates virtualization, storage, networking, AI, backup and DR into a single data center operating system
    • Infrastructure Wide Deduplication
      VergeOS transforms deduplication from a storage-only commodity into a native, infrastructure-wide capability that spans storage, virtualization, and networking, eliminating hidden resource taxes
    • VergeFS
      VergeFS is a distributed, high-performance global file system integrated into VergeOS, unifying storage across nodes, tiers, and workloads while eliminating the need for external SANs
    • VergeFabric
      VergeFabric is VergeOS’s integrated virtual networking layer, delivering high-speed, low-latency communication across nodes while eliminating the complexity of traditional network configurations.
    • Infrastructure Automation
      VergeOS integrates Packer, Terraform, and Ansible to deliver an end-to-end automation pipeline that eliminates infrastructure drift and enables predictable, scalable deployments.
    • VergeIQ
      Unlock secure, on-premises generative AI—natively integrated into VergeOS. With VergeIQ, your enterprise gains private AI capabilities without the complexity, cloud dependency, or token-based pricing.
  • Features
    • Virtual Data Centers
      A VergeOS Virtual Data Center (VDC) is a fully isolated, self-contained environment within a single VergeOS instance that includes its own compute, storage, networking, and management controls
    • High Availability
      VergeOS provides a unified, easy-to-manage infrastructure that ensures continuous high availability through automated failover, storage efficiency, clone-like snapshots, and simplified disaster recovery
    • ioClone
      ioClone utilizes global inline deduplication and a blockchain-inspired file system within VergeFS to create instant, independent, space-efficient, and immutable snapshots of individual VMs, volumes, or entire virtual data centers.
    • ioReplicate
      ioReplicate is a unified disaster-recovery solution that enables simple, cost-efficient DR testing and failover via three‑click recovery of entire Virtual Data Centers—including VMs, networking, and storage.
    • ioFortify
      ioFortify creates immutable, restorable VDC checkpoints and provides proactive ransomware detection with instant alerts for rapid recovery and response.
    • ioMigrate
      ioMigrate enables large-scale VMware migrations, automating the rehosting of hundreds of VMs (including networking settings) in seconds with minimal downtime by seamlessly transitioning entire VMware environments onto existing hardware stacks.
    • ioProtect
      ioProtect offers near-real-time replication of VMware VMs—including data, network, and compute configurations—to a remote disaster‑recovery site on existing hardware, slashing DR costs by over 60% while supporting seamless failover and testing in an efficient, turnkey VergeOS Infrastructure.
    • ioOptimize
      ioOptimize leverages AI and machine learning to seamlessly integrate new and old hardware and automatically migrate workloads from aging or failing servers.
    • ioGuardian
      ioGuardian is VergeIO’s built-in data protection and recovery capability, providing near-continuous backup and rapid VM recovery during multiple simultaneous drive or server failures.
  • IT Initiatives
    • VMware Alternative
      VergeOS offers seamless migration from VMware, enhancing performance and scalability by consolidating virtualization, storage, and networking into a single, efficient platform.
    • Hyperconverged Alternative
      VergeIO’s page introduces ultraconverged infrastructure (UCI) via VergeOS, which overcomes HCI limitations by supporting external storage, scaling compute and storage independently, using existing hardware, simplifying provisioning, boosting resiliency, and cutting licensing costs.
    • SAN Replacement / Storage Refresh
      VergeIO’s storage by replacing aging SAN/NAS systems within its ultraconverged infrastructure, enhancing security, scalability, and affordability.
    • Infrastructure Modernization
      Legacy infrastructure is fragmented, complex, and costly, built from disconnected components. VergeOS unifies virtualization, storage, networking, data protection, and AI into one platform, simplifying operations and reducing expenses.
    • Secure Research Computing
      VergeIO's Secure Research Computing solution combines speed, isolation, compliance, scalability, and resilience in a cohesive platform. It’s ideal for institutions needing segmented, compliant compute environments that are easy to deploy, manage, and recover.
    • Venues, Remote Offices, and Edge
      VergeOS delivers resiliency and centralized management across Edge, ROBO, and Venue environments. With one platform, IT can keep remote sites independent while managing them all from a single pane of glass.
  • Blog
      • Could a 24 TB Hard Drive Replace a $10,000 SSD?A 24 TB hard drive costs about $56 per TB, and a 15.36 TB SSD costs over $700. See how VergeOS puts hard drives back to work inside HCI clusters.
      • Refurbished Hardware Made ResilientRefurbished hardware funds your VMware exit. VergeOS keeps it running through drive and server failures with RF2, RF3, and ioGuardian.
      • Storage Tiering is Not the Problem. Losing Control of It Is.Auto-tiering guesses which data is hot, and the guess costs money in both directions: flash held too long, or flash withheld too late. VergeOS puts storage tiering control back with the team running the workload, moving live VMs between tiers instantly, shrinking what the next flash refresh has to buy.
    • View All Posts
  • Resources
    • Become a Partner
      Get repeatable sales and a platform built to simplify your customers’ infrastructure.
    • Technology Partners
      Learn about our technology and service partners who deliver VergeOS-powered solutions for cloud, VDI, and modern IT workloads.
    • White Papers
      Explore VergeIO’s white papers for practical insights on modernizing infrastructure. Each paper is written for IT pros who value clarity, performance, and ROI.
    • In The News
      See how VergeIO is making headlines as the leading VMware alternative. Industry analysts, press, and partners highlight our impact on modern infrastructure.
    • Press Releases
      Get the latest VergeOS press releases for news on product updates, customer wins, and strategic partnerships.
    • Case Studies
      See how organizations like yours replaced VMware, cut costs, and simplified IT with VergeOS. Real results, real environments—no fluff.
    • Webinars
      Explore VergeIO’s on-demand webinars to get straight-to-the-point demos and real-world infrastructure insights.
    • Documents
      Get quick, no-nonsense overviews of VergeOS capabilities with our datasheets—covering features, benefits, and technical specs in one place.
    • Videos
      Watch VergeIO videos for fast, focused walkthroughs of VergeOS features, customer success, and VMware migration strategies.
    • Technical Documentation
      Access in-depth VergeOS technical guides, configuration details, and step-by-step instructions for IT pros.
  • How to Buy
    • Schedule a Demo
      Seeing is believing, set up a call with one of our technical architects and see VergeOS in action.
    • Versions
      Discover VergeOS’s streamlined pricing and flexible deployment options—whether you bring your own hardware, choose a certified appliance, or run it on bare metal in the cloud.
    • Test Drive – No Hardware Required
      Explore VergeOS with VergeIO’s hands-on labs and gain real-world experience in VMware migration and data center resiliency—no hardware required
  • Company
    • About VergeIO
    • Support
      Get fast, expert help from VergeIO’s support team—focused on keeping your infrastructure running smoothly.
    • Careers
      Join VergeIO and help reshape the future of IT infrastructure. Explore open roles and growth opportunities.
  • 855-855-8300
  • Contact
  • Search
  • 855-855-8300
  • Contact
  • Search
  • Architecture
    • Overview
    • VergeFS
    • VergeFabric
    • Infrastructure Automation
    • VergeIQ
  • Features
    • Virtual Data Centers
    • High Availability
    • ioClone
    • ioReplicate
    • ioFortify
    • ioMigrate
    • ioProtect
    • ioOptimize
    • ioGuardian
  • IT Initiatives
    • VMware Alternative
    • Hyperconverged Alternative
    • SAN Replacement / Storage Refresh
    • Infrastructure Modernization
    • Secure Research Computing
    • Venues, Remote Offices, and Edge
  • Blog
  • Resources
    • Become a Partner
    • Technology Partners
    • White Papers
    • In The News
    • Press Releases
    • Case Studies
    • Webinars
    • Documents
    • Videos
    • Technical Documentation
  • How to Buy
    • Schedule a Demo
    • Versions
    • Test Drive – No Hardware Required
  • Company
    • About VergeIO
    • Support
    • Careers
×
  • Architecture
    • Overview
    • VergeFS
    • VergeFabric
    • Infrastructure Automation
    • VergeIQ
  • Features
    • Virtual Data Centers
    • High Availability
    • ioClone
    • ioReplicate
    • ioFortify
    • ioMigrate
    • ioProtect
    • ioOptimize
    • ioGuardian
  • IT Initiatives
    • VMware Alternative
    • Hyperconverged Alternative
    • SAN Replacement / Storage Refresh
    • Infrastructure Modernization
    • Secure Research Computing
    • Venues, Remote Offices, and Edge
  • Blog
  • Resources
    • Become a Partner
    • Technology Partners
    • White Papers
    • In The News
    • Press Releases
    • Case Studies
    • Webinars
    • Documents
    • Videos
    • Technical Documentation
  • How to Buy
    • Schedule a Demo
    • Versions
    • Test Drive – No Hardware Required
  • Company
    • About VergeIO
    • Support
    • Careers

Deduplication

September 29, 2026 by George Crump

Flash now costs 12 to 14 times more per terabyte than a hard drive, and that gap changes how an HCI cluster gets built.

A 24 TB hard drive sells for about $1,350 today, and a 15.36 TB enterprise NVMe SSD sells for $10,850 or more, a gap wide enough to reopen a storage decision most IT teams considered closed years ago. Dave Vincent and I ran into it this month while pricing drives for our labs, where the SSD quote came in near $12,000 and the hard drive quote barely registered by comparison.

Key Takeaways
  • At September 2026 list prices, flash costs 12 to 14 times more per terabyte than a 24 TB hard drive.
  • All-flash HCI ties every terabyte of capacity growth to the most inflated component in the data center.
  • VergeOS runs hard drives and flash in one cluster, moves running VMs between them on command, and protects the hard drive tier with frequent snapshots and ioGuardian.

The Math Behind a $10,000 SSD

These are street prices, checked on September 28, 2026, that show the gap, and they move week to week right now.

DriveCapacityPriceCost per TB
Kioxia KCMYXRUG15T3 NVMe15.36 TB$10,850$706
Solidigm D7-PS1010 NVMe15.36 TB$12,500$814
WD Ultrastar DC HC580 SATA24 TB$1,350$56

The price of one 15.36 TB SSD buys eight 24 TB hard drives, 192 TB of raw capacity for the same money. VergeIO calls this data center inflation, hardware costs rising faster than IT budgets, driven by AI demand for memory and flash. Flash and memory prices climbed 70 to 95 percent through the first half of 2026, and AI buildouts absorb new fab capacity as fast as it comes online. I plan as if this pricing is permanent.

24 TB hard drive versus 15.36 TB SSD, cost per terabyte Kioxia 15.36 TB NVMe SSD at $706 per TB, Solidigm 15.36 TB NVMe SSD at $814 per TB, and a WD 24 TB hard drive at $56 per TB, based on street prices checked September 28, 2026. Cost per terabyte, street prices, September 28, 2026 $0 $200 $400 $600 $800 Kioxia 15.36 TB NVMe SSD: $10,850, or $706 per TB Kioxia 15.36 TB NVMe $10,850 per drive $706 Solidigm D7-PS1010 15.36 TB NVMe SSD: $12,500, or $814 per TB Solidigm 15.36 TB NVMe $12,500 per drive $814 WD Ultrastar DC HC580 24 TB hard drive: $1,350, or $56 per TB WD 24 TB hard drive $1,350 per drive $56 12 to 14 times less per terabyte
A 24 TB hard drive costs $56 per terabyte against $706 to $814 for a 15.36 TB NVMe SSD. Hover a bar for drive prices.

All-Flash HCI Turns a Media Choice into a Refresh Bill

Live Webinar · October 7 · 2:00 PM ET

How to use HCI and Hard Drives to Fight Data Center Inflation

George Crump and Dave Vincent move a running VM from flash to hard drives and back, live from Palo Alto.

Register Now

Every HCI platform sold today defaults to all-flash, a decision the platform made for the customer years ago, back when flash prices fell every quarter and the assumption looked safe. That default now means every terabyte added at refresh time pays the flash price, and capacity-based licensing charges a second time for the same terabyte.

Most workloads need far less performance than all-flash delivers. File shares, VDI profiles, dev and test environments, log retention and a large share of general-purpose VMs sit idle for most of the day. Hard drives are slower than flash, but they stay online, handle most of this work at a speed users accept and cost a fraction as much.

Aging All-Flash Array? Let the Refresh Replace It

An aging dedicated all-flash array faces the same price sheet at its next refresh. The array vendor buys NAND from the same fabs that supply every SSD in the table above, so the quote for new controllers or more capacity arrives with data center inflation already built in. Many arrays also add a per-terabyte software license on top of the hardware, which charges the inflated flash price a second time. For many IT teams, that refresh falls in the same year as a VMware renewal.

Use the refresh to replace the array and exit VMware in one project. VergeOS runs virtualization, storage and networking on standard x86 servers, so the next purchase buys off-the-shelf flash at server prices instead of flash sold through an array vendor. Global inline deduplication means you buy less of that flash, and the file shares, VM templates, aging VMs and snapshots that sit idle on the array today move to 24 TB hard drives at $56 per TB. The separate storage network and the array support contract go away with it. The Storage Refresh vs. Storage Inflation datasheet walks through the math.

Replacing an aging all-flash array and VMware hosts with VergeOS at refresh Animated diagram. Today, VMware hosts reach a dedicated all-flash array over a separate storage network, and the working set, file shares, VM templates, aging VMs and snapshots all pay the flash price. At refresh, VergeOS replaces the hosts and the array. The working set runs on off-the-shelf flash inside the servers, and everything else moves to 24 TB hard drives in the same cluster. Today At refresh, with VergeOS VMware hosts separate storage network Dedicated all-flash array Working set File shares VM templates Aging VMs and snapshots Every terabyte pays the flash price Replaced at refresh refresh VergeOS cluster ServerServerServer FlashFlashFlash 24 TB24 TB24 TB HDDHDDHDD Less flash, off the shelf. The rest at $56 per TB.
At refresh, VergeOS replaces the VMware hosts and the array. The working set runs on off-the-shelf flash inside the servers, and everything else moves to 24 TB hard drives.

Can a 24 TB Hard Drive Keep Up?

For most workloads, yes. Random-I/O databases still belong on flash, but for the rest of the data center the answer comes down to the platform in front of the drive. One of our customers ran a hosting business that sold both flash and spinning-disk capacity with VergeOS underneath. Their customers tested their workloads on hard drives, saw little difference, and kept moving more of them to disk. Dave Vincent saw the same result when he moved a live SQL workload from NVMe to spinning disk and commit latency stayed under a millisecond on both tiers.

VergeOS makes that result repeatable for any IT team. Global inline deduplication runs across every tier, so the cluster stores fewer blocks and more of the working set fits in cache. VergeOS caches data in RAM on the server running the VM, which VergeIO testing shows produces four to five times the cache hit rate of array-side caching. On the write side, VergeOS reorders and groups incoming writes into sequential runs before they reach the platter, the access pattern hard drives handle best.

How VergeOS makes a 24 TB hard drive tier keep up Animated diagram of the VergeOS I/O path. Reads are served from a RAM cache on the server running the VM. Random writes pass through global inline deduplication and are reordered and grouped into sequential runs before they reach the hard drive. VM any workload RAM cache on the server running the VM Reads served from RAM, 4 to 5 times the hit rate of array-side cache Random writes in Dedupe, reorder and group fewer blocks, longer runs Sequential runs out 24 TB hard drive Hard drives handle long sequential runs best. VergeOS shapes the write stream to match before it reaches the platter.
Reads come from RAM next to the VM. Writes arrive random and leave as sequential runs, the pattern a spinning drive handles best.

Afraid of Tiering? Select Tiering That Puts You in Control

Many IT teams steer clear of tiering, and automated tiering is the reason, after two decades of burning plenty of them. An auto-tiering algorithm samples activity, waits for a threshold and makes placement calls without knowing the business behind the workload. It is slow to spot cold data, it misses anything outside its sampling window, and it is slowest of all on the trip back to flash, usually right when users start to notice.

VergeOS puts the IT team in charge of placement instead. The people who run the workloads already know the business calendar, such as a tax application that is write-heavy through April 15 and read-heavy on April 16, and they need no algorithm to predict it. The IT team moves a running VM to the hard drive tier or back to flash on command, in either direction and with no maintenance window, and pins the workloads that must stay hot to a preferred tier. I covered why tiering itself was never the issue in Storage Tiering Is Not the Problem. Losing Control of It Is.

VergeOS moves a running VM between the flash tier and the hard drive tier on command Animated diagram. A running VM sits on the Tier 1 NVMe flash tier, moves down to the Tier 4 hard drive tier on command with the workload online, then moves back to flash the same way. Tier 1 NVMe flash Working set, random-I/O databases Tier 4 24 TB hard drives File shares, templates, aging VMs Move down on command Move back Running VM online the whole time Lab test: API acknowledged the move in 1.3 seconds. A 25 GB disk finished moving in 13 seconds.
The IT team decides placement. A running VM moves to the 24 TB hard drive tier and back on command, with no maintenance window.

Three Ways VergeOS Makes Hard Drives Safe to Use

Tiering under IT control. VergeOS supports six storage tiers inside one vSAN, with tiers 4 and 5 designed for high-capacity hard drives, and the IT team moves a running VM’s disk between tiers on command. In VergeIO lab testing, the API acknowledged the move in 1.3 seconds and a 25 GB disk finished moving in 13 seconds with the workload running. Be aggressive with it, moving a workload to hard drives and moving it back in seconds if someone complains two weeks later.

Frequent snapshots. VergeOS snapshots run on a schedule the IT team controls, hourly by default, which gives every VM on the hard drive tier recent recovery points inside the same system.

ioGuardian. Large drives raise a fair question about exposure during a rebuild. ioGuardian answers it by pulling missing or corrupted blocks from a synchronized remote VergeOS system after a failure that exceeds the cluster’s redundancy, such as multiple drive failures spread across nodes.

VergeOS licenses per server, so the money saved on hard drives and deduplication stays in the budget instead of feeding a capacity meter.

Key Terms

Data center inflation

Hardware costs rising faster than IT budgets, driven by AI demand for memory and flash.

Storage tier

A class of drives in the VergeOS vSAN, numbered 0 through 5, running from metadata NVMe to archival hard drives.

Preferred tier

The VergeOS setting that names the first-choice tier for a VM disk, used to keep critical workloads on flash.

ioGuardian

The VergeOS repair server that restores blocks from a synchronized remote system after a failure beyond redundancy tolerance.

All-Flash HCI and VergeOS Flash Plus Hard Drives

All-flash HCIVergeOS flash plus hard drives
Capacity cost at refreshFlash price for every TBFlash for the working set, $56 per TB for the rest
Workload placementEverything on flashIT team places each VM, moves it live
LicensingOften per TBPer server
Media mixFlash onlyFlash and hard drives in one cluster

See the Answer Live on October 7

Dave and I will answer the question in the title live from Palo Alto on Wednesday, October 7, at 2:00 PM ET, in How to use HCI and Hard Drives to Fight Data Center Inflation. Dave will move a running VM from flash to hard drives and back on camera, and I will walk through the refresh math for a real cluster, so register for the webinar.

Frequently Asked Questions

Can a 24 TB hard drive replace an SSD for every workload?

Random-I/O databases still belong on flash, and VergeOS lets you pin them to a preferred flash tier and place everything else on hard drives.

Does deduplication work on the hard drive tier?

VergeOS runs global inline deduplication across all six tiers, so the hard drive tier gets the same capacity savings as flash.

How long does it take to move a VM back to flash?

The move starts on command and runs with the VM online, and in lab testing small disks finish the trip back to flash in seconds.
Filed Under: Storage Tagged With: Deduplication, flash inflation, HCI, HCIandHDD, ioGuardian, Tiering

March 9, 2026 by George Crump

The ability to reduce RAM consumption may be the most important factor in choosing a VMware alternative in 2026. What started as a licensing decision after Broadcom’s acquisition has become an infrastructure economics decision. Organizations began evaluating replacements to escape licensing uncertainty. Then the Flash and Memory Supercycle hit.

Key Takeaways
The Memory and Flash Supercycle is driving DRAM prices up 171% YoY through 2027, NAND flash up 55–60% in a single quarter, and server deliveries delayed by months. VMware licensing changes from Broadcom compound the pressure.
Memory ballooning, transparent page sharing, and hypervisor swapping are reactive workarounds that manage scarcity after it occurs. None of them reduce total physical RAM requirements.
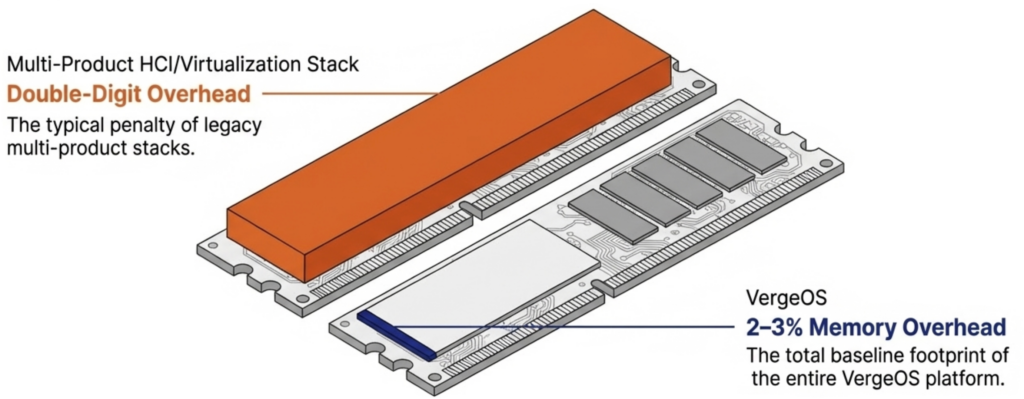
VergeOS integrates virtualization, storage, networking, and data protection into a single code base that runs at 2–3% memory overhead, compared to the double-digit percentages consumed by multi-product stacks.
Topgolf reduced server count by 50% per venue across 100+ locations. Alinsco Insurance migrated a mission-critical VxRail environment during business hours with zero downtime and gained memory headroom on the same hardware.
VergeOS runs safely on commodity NVMe drives, uses global inline deduplication to reduce flash capacity requirements, and delivers snapshot-driven local replication through ioGuardian that protects against multiple simultaneous drive failures without hardware RAID.
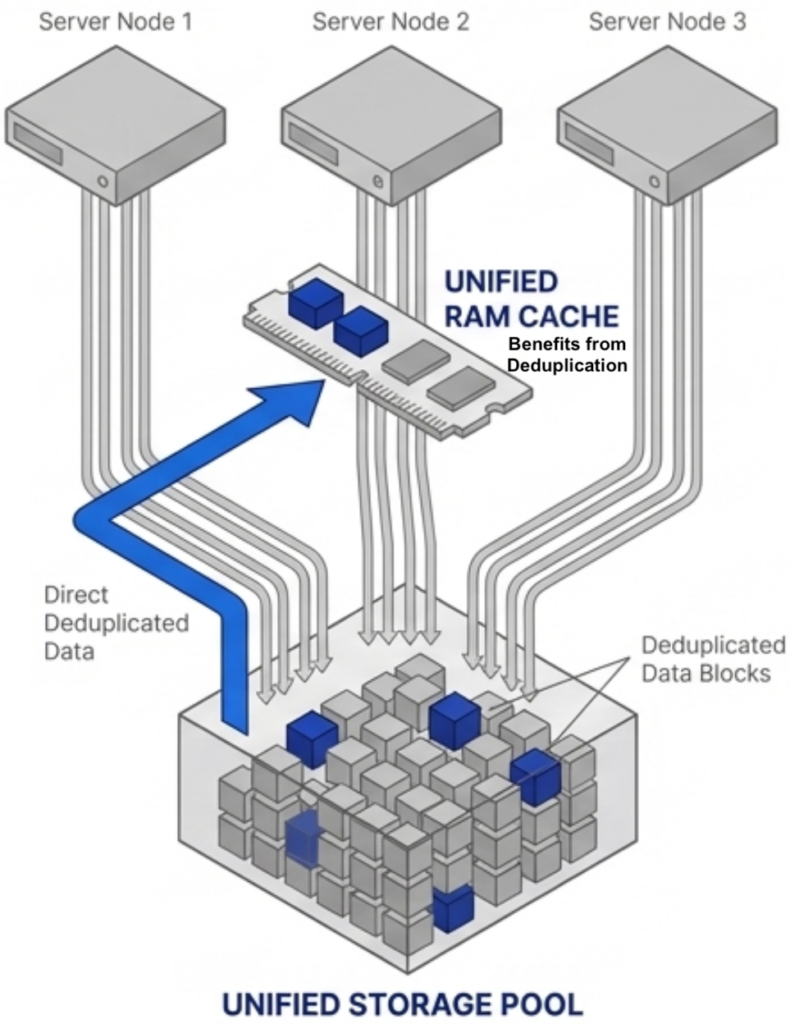
The platform’s global deduplicated cache operates across all VMs across all nodes, caching only unique data blocks from the already-deduplicated storage pool. This drives higher cache hit rates and fewer flash reads without wasting RAM on redundant cached data.

How a Hypervisor Can Reduce RAM ConsumptionDRAM prices are expected to increase 171% year-over-year through 2027. NAND flash contract prices jumped 55–60% in Q1 2026 alone. Server orders that once shipped in weeks now face multi-month delivery delays. The platform you choose now determines how much RAM, flash, and hardware you need for the next three to five years.
171%
Projected YoY DRAM price increase through 2027
55–60%
NAND flash contract price increase in Q1 2026
Months
Server delivery delays in categories that shipped in weeks

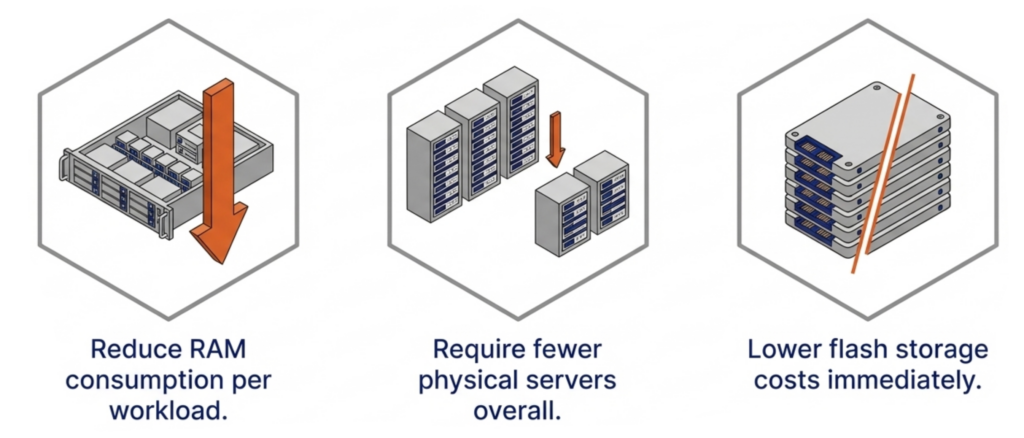
Finding a VMware alternative is still the primary mission. But the supercycle raises the bar. It is no longer enough to swap one hypervisor for another just because it costs less to license. The replacement must also reduce RAM consumption per workload, require fewer servers, and reduce flash storage costs. Any platform that relies on memory ballooning, transparent page sharing, or hypervisor swapping to manage RAM is using the same software tricks the industry has relied on for years. Those techniques react to memory pressure after it occurs. None of them reduce the total physical RAM your infrastructure actually requires.

Key Terms
Memory and Flash Supercycle

A sustained period of rising DRAM and NAND flash prices driven by AI infrastructure demand, DDR4 end-of-life, and constrained fabrication capacity. Industry analysts project tight supply through at least 2027.

Memory Ballooning

A hypervisor technique that uses a guest driver to reclaim unused RAM from idle VMs. Reactive by design, it fails under tight VM sizing and causes cascading performance degradation when multiple VMs spike simultaneously.

Transparent Page Sharing (TPS)

A memory deduplication technique that merges identical OS pages across VMs. Limited to identical pages, disabled by default in VMware since 2014 due to security concerns, and ineffective for application data.

Global Inline Deduplication

VergeOS technology that identifies and eliminates duplicate data blocks at the storage layer before they are written to flash. Reduces total flash capacity requirements, lowers write amplification to extend drive life, and feeds only unique blocks into the RAM cache.

Global Deduplicated Cache

A VergeOS RAM cache that operates across all VMs across all nodes and draws from the already-deduplicated storage pool. Holds only unique data blocks, increasing effective cache capacity and hit rates without the CPU overhead of a separate cache-level deduplication algorithm.

ioGuardian

VergeOS data availability technology that uses snapshot-driven local replication to protect against multiple simultaneous drive failures. Eliminates the need for hardware RAID controllers and delivers consistent performance during failures and rebuilds.

Commodity NVMe

Standard NVMe solid-state drives that cost significantly less than enterprise or server-class SSDs. VergeOS makes commodity drives production-safe through software-managed wear leveling, global deduplication to reduce writes, and ioGuardian replication to handle failures gracefully.

Our on-demand webinar goes deeper into each of these points. Watch Architecting for the Flash and Memory Supercycle to see how the platform decisions you make today determine your infrastructure costs for the next three to five years.

Start with an Efficient Code Base That Reduces RAM Consumption

The first question to ask any VMware alternative is how much RAM the platform itself consumes before a single VM even starts. VMware environments running vSphere, vSAN, vCenter, and NSX stack four separate products on every host. Each product reserves memory for its own management processes. Add external replication software and hardware RAID controllers, and the cumulative overhead climbs even further.

VergeOS takes a different architectural approach. It delivers a complete private cloud operating system that integrates virtualization, storage, networking, and data protection as services within a single code base. There is no separate storage product. There is no separate networking product. The platform is built with global deduplication, enabling synchronous replication without the typical capacity impact and delivering better, more consistent performance in production and during failures.

Memory usage comparison across virtualization platformsIt eliminates the need for hardware RAID controllers, which are also increasing in price because they consume RAM. VergeOS includes built-in data replication for disaster recovery, and its global inline deduplication reduces capacity costs at the disaster recovery site as well. The entire platform runs at 2–3% memory overhead. Compare that to the double-digit percentages consumed by multi-product virtualization stacks and HCI platforms that reserve tens of gigabytes per node before workloads even start.
A lower baseline means more RAM available for production workloads on the same hardware. During a supercycle, that difference translates directly into fewer servers needing to be purchased at inflated prices.

Use Existing Hardware and Reduce How Much You Need

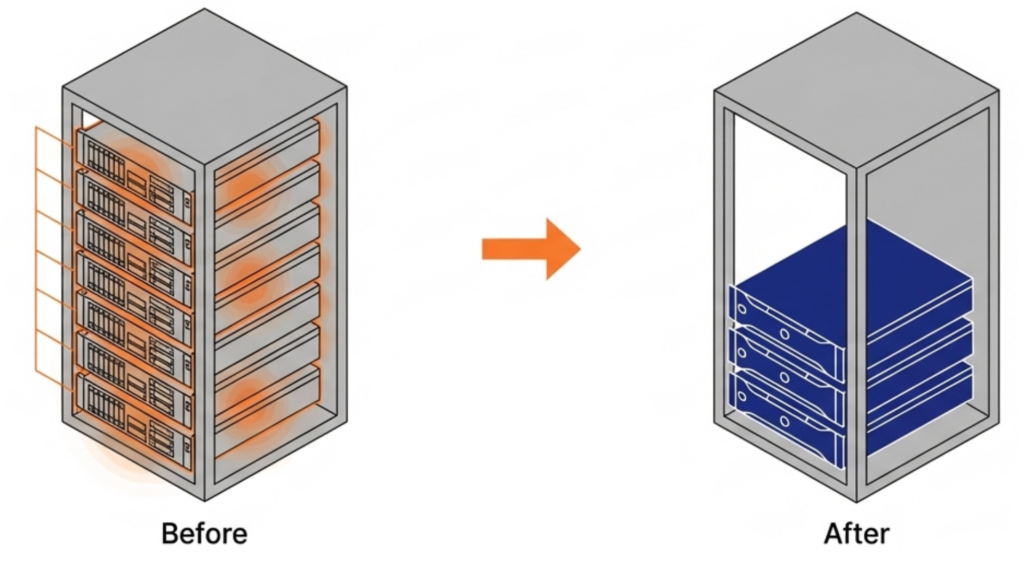
Server reduction through VergeOS consolidationVergeOS installs on any x86 server from any manufacturer. Organizations migrating from VMware continue to run on the same physical servers they already own. There is no hardware forklift upgrade. No waiting six months for new server deliveries that keep getting pushed back as memory and flash shortages worsen. The servers, RAM, and SSDs already purchased and deployed remain in production.
Getting there does not require the purchase of a parallel environment or even a maintenance window. VergeOS supports node-by-node migration from VMware. Evacuate workloads from one host, install VergeOS on that host, migrate VMs onto the new platform, and repeat across the remaining hosts. Production continues running throughout the process. Alinsco Insurance completed this on a five-node VxRail cluster running a mission-critical insurance application that cannot tolerate downtime. The team migrated node by node during business hours with zero downtime. Critical web servers were moved at night out of an abundance of caution, but even those migrations produced no service interruption. During a supercycle, this approach eliminates the capital expense of purchasing a second set of servers to stand up alongside the existing environment.

On-Demand Webinar
Architecting for the Flash and Memory Supercycle

How the platform decisions you make today determine your infrastructure costs for the next three to five years.

Watch On-Demand →

Because VergeOS consumes less RAM per host, organizations can increase VM density and consolidate to fewer servers. Topgolf, operating more than 100 venues globally, reduced each site from six-node VxRail clusters to three-node VergeOS clusters. That is a 50% server reduction per venue. Alinsco Insurance continued to run on the same VxRail hardware and internal SSDs after migration, and servers that felt constrained under VMware gained additional headroom under VergeOS.

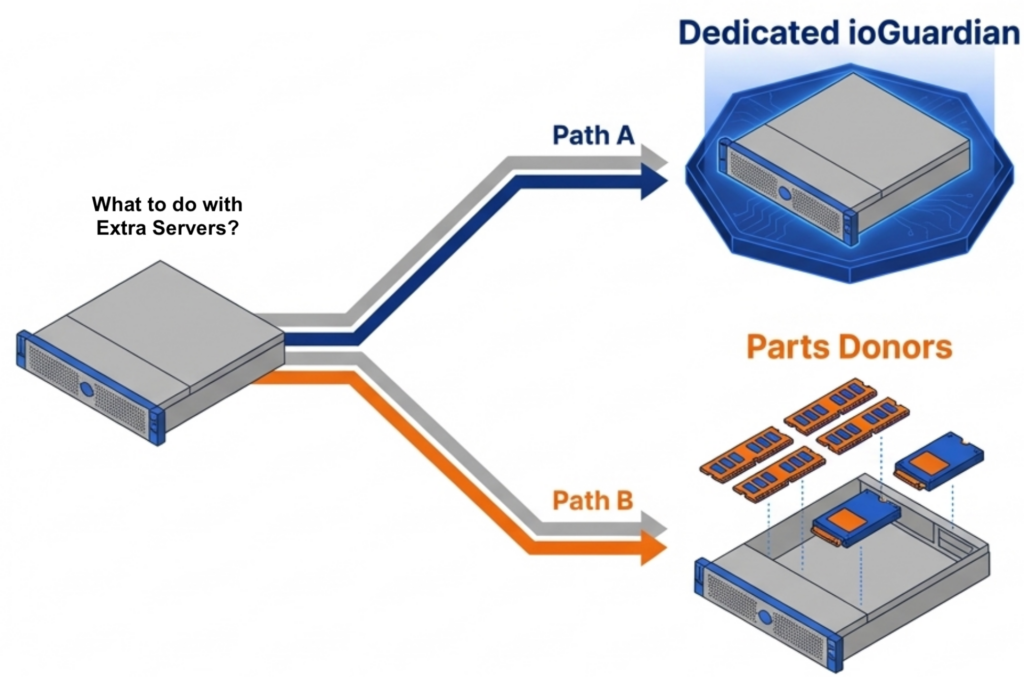
The freed servers create immediate value. One becomes a dedicated ioGuardian server, delivering N+2 or greater (N+X) data protection without purchasing new hardware or hardware RAID. The remaining servers become part donors. Pull the DRAM and NVMe drives and redistribute them across the active production nodes. VergeOS supports mixed node types and mixed node roles in the same cluster, so the redistribution does not require matching hardware specifications.

Freed servers from VergeOS consolidation become parts donors or ioGuardian nodesThe consolidation math works across an entire fleet. An organization running 100 six-node VMware clusters that consolidates to 100 three-node VergeOS clusters frees 300 servers for repurposing, retirement, or spare parts — during a supercycle where replacement hardware is both expensive and slow to ship.
Reduce Flash Costs with Commodity SSDs

The supercycle affects flash storage as well as memory. Enterprise and server-class SSDs carry steep price premiums that continue to climb alongside NAND contract prices. Commodity NVMe drives are rising in price, too. But the price gap between enterprise and commodity is widening, not narrowing, and commodity drives do seem to be more readily available. Organizations that can safely run on commodity flash pay less per terabyte today relative to enterprise alternatives than they did a year ago.

VergeOS runs safely on commodity SSDs. The platform’s storage engine manages I/O scheduling and wear management at the software layer, reducing dependence on the drive’s internal controller. Global inline deduplication reduces total writes to each drive, directly extending drive life. ioGuardian’s snapshot-driven local replication protects against multiple simultaneous drive failures without data loss or downtime, so that a commodity drive that wears out faster than an enterprise drive is replaced gracefully. No hardware RAID controller is required. The combination makes commodity flash a production-safe choice at a fraction of the cost of enterprise SSDs.

A Cache That Benefits from Deduplication

Unified RAM cache across VergeOS nodes drawing from deduplicated storage poolMost virtualization platforms cache storage data independently on each node. If ten nodes access the same data block, ten separate copies sit in ten separate caches. That wastes RAM on redundant data across the cluster.
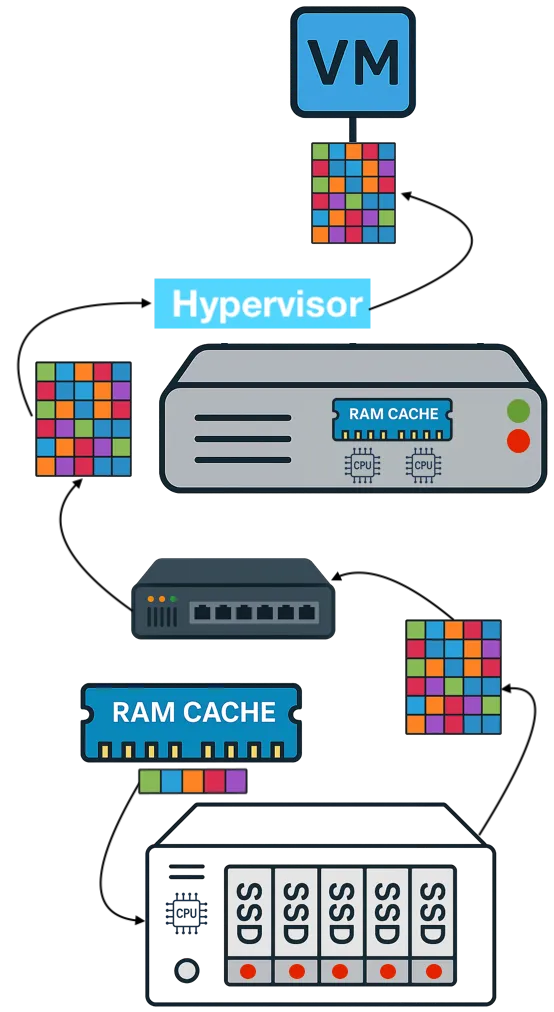
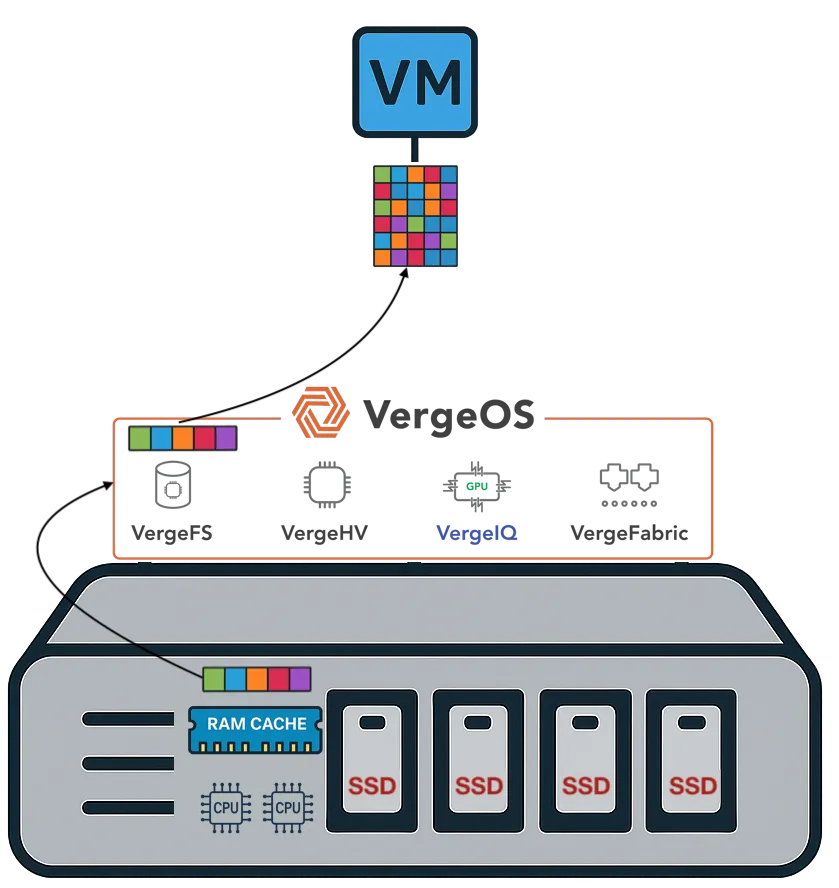
VergeOS approaches caching differently. The platform performs global inline deduplication at the storage layer, so the storage pool contains only unique blocks. The RAM cache operates across all VMs across all nodes and draws from that already-deduplicated pool. The cache holds only unique data without running a separate deduplication algorithm inside the cache itself. More unique blocks fit in the same physical RAM, driving higher cache hit rates and fewer reads from flash.

An important factor in making this work across nodes is VergeOS’s optimized internode communication protocol, purpose-built for this use case and free from the overhead of chatty iSCSI or NFS protocols. We will explore the technical details of this architecture in an upcoming post. The takeaway for now: VergeOS does not waste RAM caching duplicate data.

The VMware Alternative Decision Just Got Bigger

The search for a VMware alternative is no longer just about licensing. The supercycle means the platform you choose determines your RAM consumption, your flash costs, your server count, and how long your existing hardware stays in production. Choose a platform that relies on the same memory tricks the industry has used for decades, and you inherit the same overhead during the most expensive hardware market in years. Choose a platform built to reduce RAM consumption from a single efficient code base with built-in data availability, and you start with less overhead, run on the servers you already own, and reduce how many you need going forward.

Frequently Asked Questions
What is the Memory and Flash Supercycle?
A sustained period of rising DRAM and NAND flash prices driven by AI infrastructure demand, DDR4 end-of-life, and constrained fabrication capacity. DRAM prices are expected to increase 171% year-over-year through 2027, and NAND flash contract prices jumped 55–60% in Q1 2026 alone. Server delivery times have extended to multi-month delays.
Why don’t memory ballooning and transparent page sharing solve the problem?
These are reactive techniques that manage memory pressure after it occurs. Memory ballooning reclaims unused RAM from idle VMs but fails under tight sizing. Transparent page sharing merges identical OS pages but has been disabled by default in VMware since 2014 due to security concerns. Neither technique reduces the total physical RAM your infrastructure requires.
How much RAM overhead does VergeOS consume?
The entire VergeOS platform — including virtualization, storage, networking, and data protection — runs at 2–3% memory overhead. Compare that to multi-product VMware stacks that consume double-digit percentages, or HCI platforms like Nutanix that reserve 24–32 GB per node for controller VMs before workloads start.
Can I migrate from VMware without buying new servers?
Yes. VergeOS installs on any x86 server from any manufacturer and supports node-by-node migration from VMware. Evacuate workloads from one host, install VergeOS, migrate VMs onto the new platform, and repeat. The servers, RAM, and SSDs you already own stay in production. Alinsco Insurance completed this on a five-node VxRail cluster during business hours with zero downtime.
How does VergeOS reduce the number of servers needed?
Lower platform overhead means more RAM is available for production workloads on each host, increasing VM density. Topgolf reduced each venue from six-node VxRail clusters to three-node VergeOS clusters — a 50% reduction in servers across more than 100 locations. Freed servers become parts donors or dedicated ioGuardian data protection nodes.
Is it safe to run commodity NVMe drives in production?
With VergeOS, yes. The storage engine manages I/O scheduling and wear management at the software layer. Global inline deduplication reduces total writes to each drive, extending drive life. ioGuardian’s snapshot-driven local replication protects against multiple simultaneous drive failures without hardware RAID, so a commodity drive that wears faster is replaced gracefully with no data loss or downtime.
How does VergeOS cache data differently from VMware or Nutanix?
Most platforms cache storage data independently on each node, meaning duplicate blocks are cached separately on every host. VergeOS performs global inline deduplication at the storage layer first, then the RAM cache draws from the already-deduplicated pool. The cache holds only unique blocks across all VMs across all nodes, using an optimized internode protocol instead of iSCSI or NFS. More unique data fits in the same physical RAM, driving higher cache hit rates.
What happens to servers freed up after consolidation?
One freed server becomes a dedicated ioGuardian node, delivering N+2 or greater data protection without a new hardware purchase and without hardware RAID. The remaining servers become parts donors — pull the DRAM and NVMe drives and redistribute them across active production nodes. VergeOS supports mixed node types and mixed node roles, so no matching hardware specifications are required.

Filed Under: Private Cloud Tagged With: Cache, data protection, Deduplication, FlashAndMemorySupercycle, Migration, Performance, servers, Storage, VergeOS, VMware, VMware alternative

September 24, 2025 by George Crump

Deduplication and RAM cache are two of the most critical technologies in modern IT infrastructure. Both are designed to improve efficiency and performance, but in storage-centric designs, they often work against each other. Deduplication reduces the amount of data that must be stored and transmitted, while cache accelerates access to frequently used data. The problem is that the way these features are typically implemented causes them to clash.

The effectiveness of cache depends on the location. When cache sits inside the server hosting the VM, it is directly alongside the application and delivers immediate performance benefits. When cache resides in a shared storage system connected over the network, its value is far less meaningful. From the application’s perspective, there is little difference between retrieving a block from the array’s cache and retrieving it from the array’s flash drives—both require a network hop.

Deduplication complicates this further. Before cached data can be sent from the storage system, it must often be rehydrated. This process eliminates much of the performance advantage that cache is supposed to provide.

Infrastructure-wide deduplication changes the deduplication and RAM cache dynamics. By sharing metadata across storage, virtualization, and networking layers, it ensures that deduplication and cache work together rather than in opposition. Cache remains in the right place—next to the VM—while data stays deduplicated until the moment it is consumed. For a deeper explanation of this concept, see the blog What Is Infrastructure-Wide Deduplication.

The Role of RAM Cache Today

RAM cache is one of the most powerful tools available for improving application performance. Because it operates at memory speeds, it delivers far lower latency than even the fastest flash storage. Modern workloads—including databases, analytics platforms, and AI/ML pipelines—depend on cache to meet user and business expectations for responsiveness.

But the effectiveness of cache is determined by its placement. Cache inside the server hosting the VM eliminates unnecessary trips across the network, delivering measurable and consistent benefits.

By contrast, cache located inside a shared storage system provides limited value. Retrieving a block from the storage array’s cache is not much different than retrieving it from the array’s SSD tier—both require a network hop. Worse, storage-centric deduplication forces cached data to be rehydrated before transmission, erasing the supposed advantage of having the block in cache at all.

The result is a gap between what cache should provide and what it actually delivers. As applications grow more cache-dependent, that gap widens, exposing the shortcomings of architectures that treat deduplication and cache as isolated features rather than complementary technologies.

How Storage-Centric Deduplication Undermines RAM Cache

deduplication and RAM cache

All-Flash Array vendors promote deduplication as a space-saving feature of their arrays. In theory, deduplication and RAM cache should complement each other; the smaller the dataset, the more effective the cache. In practice, the opposite occurs.

Deduplicated blocks inside an array must be rehydrated before they can be transmitted across the network to the VM. This means that even when a cache hit occurs, the system spends CPU cycles rebuilding the block before it can leave the array. The benefit of the cache hit is diminished, and the VM receives the data with little to no latency improvement.

From the application’s perspective, this creates an illusion of acceleration. The array may report cache efficiency, but because rehydration is required, the VM experiences almost the same delay it would if the block were read directly from flash. Customers end up buying expensive all-flash arrays with large caches that deliver almost no practical benefit to the workloads they are supposed to accelerate. This problem is explored further in AFA Deduplication vs vSAN, which highlights the compromises of storage-centric deduplication approaches.

This is not just a performance issue—it is a resource issue. Rehydration consumes CPU and memory resources in the storage system, forcing organizations to overprovision those resources just to keep workloads running. The result is higher cost, wasted infrastructure, and inconsistent performance.

Infrastructure-Wide Deduplication: The Metadata Advantage

The key to making deduplication and RAM cache work together is eliminating the need for rehydration until the very last step—when the data is delivered to the VM. This is possible only when deduplication metadata is shared across the entire infrastructure, rather than being locked inside a storage array.

deduplication and RAM cache

With infrastructure-wide deduplication, VergeOS maintains a single, global metadata structure that spans storage, virtualization, and networking. This ensures that data can remain deduplicated as it moves through the system. Blocks do not need to be reassembled or expanded in the storage system before traveling across the network. Instead, they stay in their deduplicated form until consumed by the VM or application.

This shift has a direct impact on cache strategy. Cache no longer needs to sit inside the storage system, where rehydration undermines its value. Instead, cache can be placed where it matters most—in the server, right next to the workload. By maintaining consistent deduplication awareness across all layers, cached blocks remain optimized and deliver real performance benefits without the overhead of premature rehydration.

In practice, this often improves effective cache hit rates by a factor of four to five compared to array-side caching, because server-side cache is no longer wasted storing redundant blocks. Applications see faster response times, more consistently low latency, and higher resource utilization efficiency.

Comparing Storage-Centric vs. Infrastructure-Wide Approaches

Feature / ImpactStorage-Centric Deduplication + CacheInfrastructure-Wide Deduplication + Cache
Cache LocationInside storage array, across networkInside server, next to VM
Rehydration RequirementBefore transmission, even from cacheOnly at VM, at point of use
Effective Cache Hit RateLow, due to redundant blocks + rehydration4–5x higher, dedupe shrinks working set
Latency ImprovementMinimal (network hop and rehydration erases benefit)Significant (direct from RAM cache to VM)
Resource OverheadHigh CPU/RAM in array for rehydrationLower overhead, fewer wasted cycles
Business Value DeliveredEfficiency for the array vendorEfficiency and performance for the business

The Deduplication and RAM cache Takeaway

Deduplication and RAM cache are both essential to modern infrastructure, but in storage-centric designs, they often work at cross purposes. Deduplication reduces storage requirements but forces rehydration, undermining cache. Storage-system caches sit on the far side of the network and provide little practical benefit to the applications that need them most.

Infrastructure-wide deduplication resolves this conflict. By sharing metadata across storage, virtualization, and networking, data remains deduplicated until the VM consumes it. Cache can be located directly in the server, where it accelerates workloads without the penalty of premature rehydration. Instead of competing for resources, deduplication and cache reinforce one another—smaller datasets, higher cache hit rates, and faster, more consistent application performance.

The distinction is clear. Storage deduplication and cache create efficiency for the array. Infrastructure-wide deduplication and cache create efficiency for the business—delivering responsiveness, reducing costs, and scaling with modern workloads like AI, analytics, and VDI that storage-centric models struggle to support. For a broader discussion of why deduplication must evolve, download the white paper Building Infrastructure on Integrated Deduplication.

Filed Under: Storage Tagged With: Cache, Deduplication, Storage

September 10, 2025 by George Crump

Infrastructure-wide deduplication expands what IT professionals know about deduplication, a storage feature that saves disk space. Arrays deduplicate blocks, backup systems compress datasets, and WAN optimizers reduce transmission overhead. Each system handles deduplication independently, creating islands of efficiency in an already fragmented infrastructure.

Infrastructure-wide deduplication takes a fundamentally different approach. Instead of treating deduplication as separate features scattered across various systems, it implements deduplication as a unified capability that spans the entire infrastructure—storage, virtualization, networking, and data protection—under a single, consistent framework.

The Problem with Fragmented Deduplication

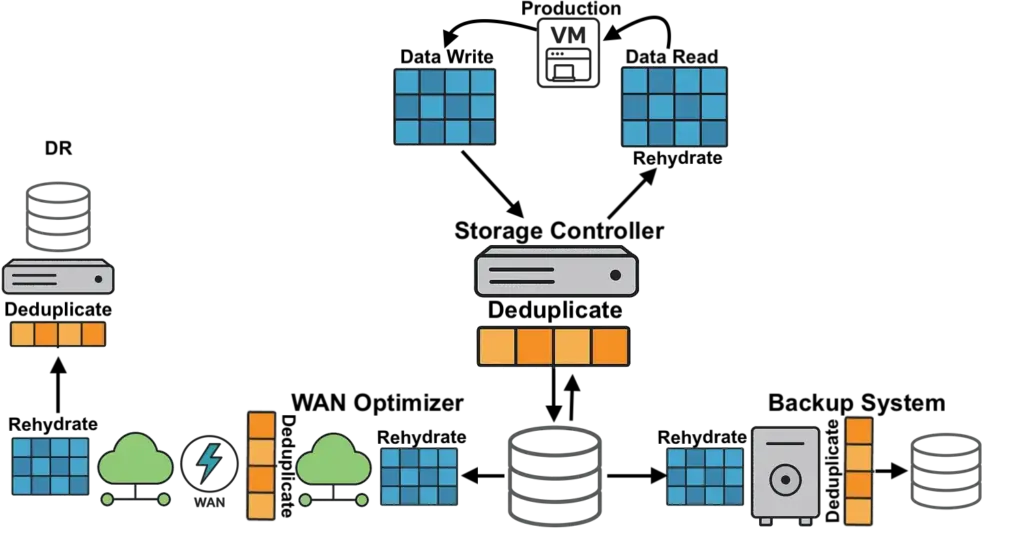
Traditional deduplication creates a cycle of inefficiency. Data may start deduplicated in primary storage, expand to full size during backup operations, then deduplicate again in the backup appliance using different algorithms. For disaster recovery, the same data rehydrates before replication, deduplicates for transmission, expands again at the destination, and deduplicates once more on DR storage.

Infrastructure-wide deduplication

This fragmentation forces organizations to deploy 30–50% more CPU and RAM than workloads otherwise require to absorb the overhead of constant rehydration and re-deduplication. WAN circuits carry redundant data streams. Backup windows extend as data repeatedly expands and contracts. IT teams assume they have comprehensive deduplication coverage, but in reality, they are paying a hidden tax across every system boundary.

Understanding these inefficiencies—and the architectural approaches that eliminate them—requires examining how different vendors implement deduplication across their platforms. Our white paper “Building Infrastructure on Integrated Deduplication” provides a detailed analysis of implementation patterns from bolt-on approaches to native integration, plus vendor-specific guidance on Unity, vSAN, Nutanix, Pure, and VergeOS platforms. Get the complete analysis at verge.io/building-infrastructure-on-integrated-deduplication.

How Infrastructure-Wide Deduplication Works

Infrastructure-wide deduplication eliminates these inefficiencies through three key principles:

Native Integration. Rather than bolting deduplication onto existing systems, it’s built into the platform from the earliest lines of code. Deduplication becomes part of the core infrastructure operating system, not a separate process competing for resources.

Unified Metadata. Instead of each system maintaining its own deduplication tables, infrastructure-wide implementations use a single, consistent metadata model. A block deduplicated in New York remains deduplicated when referenced in London or Tokyo. Data never loses its optimized state as it moves between functions or sites.

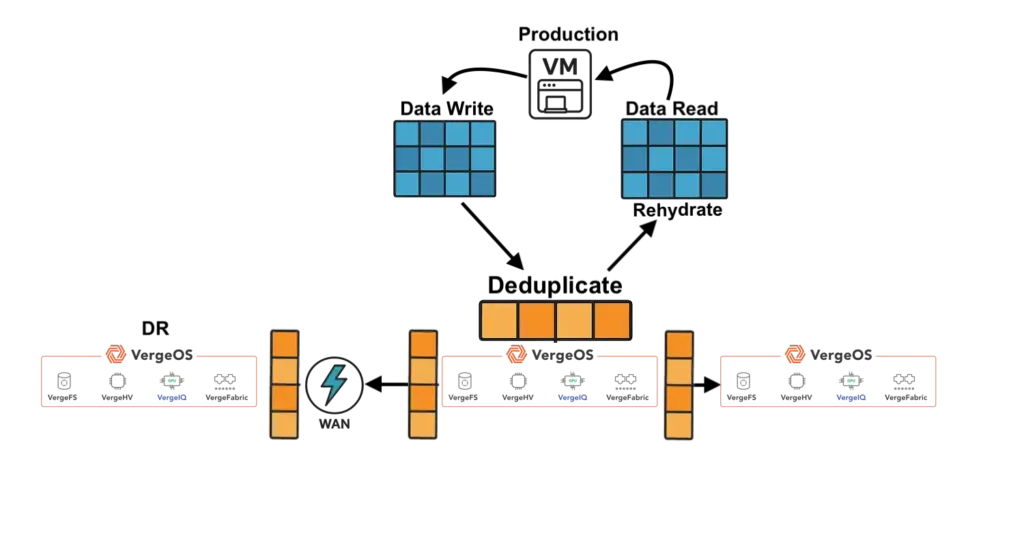
Cross-Layer Operation. Deduplication runs simultaneously across storage, virtualization, and network layers. When the hypervisor makes deduplication decisions, they directly inform storage operations. Network transfers automatically leverage existing deduplication metadata without redundant processing cycles.

Infrastructure-wide deduplication

This cross-layer integration has practical consequences. For example, when a virtual machine snapshot is taken, the hypervisor references existing deduplicated blocks instead of writing new ones. That reduces both I/O and backup times. Similarly, when replication jobs run, they automatically leverage deduplication tables maintained across the entire infrastructure, eliminating duplicate transfers without additional processing.

The VergeOS Implementation

VergeOS demonstrates this approach through its Infrastructure Operating System. Instead of separate storage, virtualization, and networking products that require integration, VergeOS provides a unified platform where deduplication operates across all infrastructure functions.

When a virtual machine writes data, the hypervisor immediately deduplicates at the source. Storage operations work with the optimized dataset. Network replication transmits unique blocks. Backup operations reference existing deduplicated blocks rather than creating new copies. Recovery uses the same optimized structure, eliminating expansion penalties.

This architectural integration explains why infrastructure-wide deduplication remains rare. Other vendors build platforms around separate components. Retrofitting unified deduplication requires redesigning core architectures rather than adding features—a significant undertaking that few vendors attempt. VergeOS avoids this problem by collapsing the stack into one code base where deduplication is built in, not bolted on. Deduplication becomes a key element in the VergeOS architecture.

Measurable Infrastructure-wide Deduplication Benefits

Infrastructure-wide deduplication delivers improvements that compound across the entire infrastructure:

Performance. By operating on deduplicated datasets from the start, I/O operations decrease by 40–60%. Cache hit rates improve by 2–3x because the working dataset is fundamentally smaller. Applications experience lower latency and higher throughput.

Infrastructure-wide deduplication

Resource Efficiency. Organizations can right-size servers based on actual workload requirements rather than deduplication overhead. Memory utilization improves because duplicate data never enters the cache hierarchy.

WAN Optimization. Only unique blocks traverse the network, reducing replication traffic by 70–90%. Organizations can handle more data on existing circuits or reduce bandwidth costs while maintaining protection levels.

Operational Simplicity. Backup windows shrink by 60–80% because data doesn’t rehydrate during protection operations. Snapshots become instant references to deduplicated blocks. Recovery operations are complete 5–10x faster using the same optimized block structure.

Multi-Site Flexibility. With consistent deduplication across locations, entire data centers can migrate between continents with minimal data transfer. AI training checkpoints that previously required hours to replicate are now completed in minutes.

Use Case Spotlights

VMware Exits. Organizations moving away from VMware face major infrastructure transitions. Infrastructure-wide deduplication offsets migration costs by reducing hardware requirements and enabling faster workload mobility.

AI/ML Pipelines. Training large language models generates terabytes of repetitive checkpoint data. Infrastructure-wide deduplication reduces replication from hours to minutes, enabling faster iteration and lower infrastructure cost.

Disaster Recovery Compliance. Meeting aggressive recovery time objectives (RTOs) requires restoring systems quickly. Infrastructure-wide deduplication cuts recovery times by up to 5–10x, helping organizations meet compliance and business continuity mandates.

Competitive Landscape

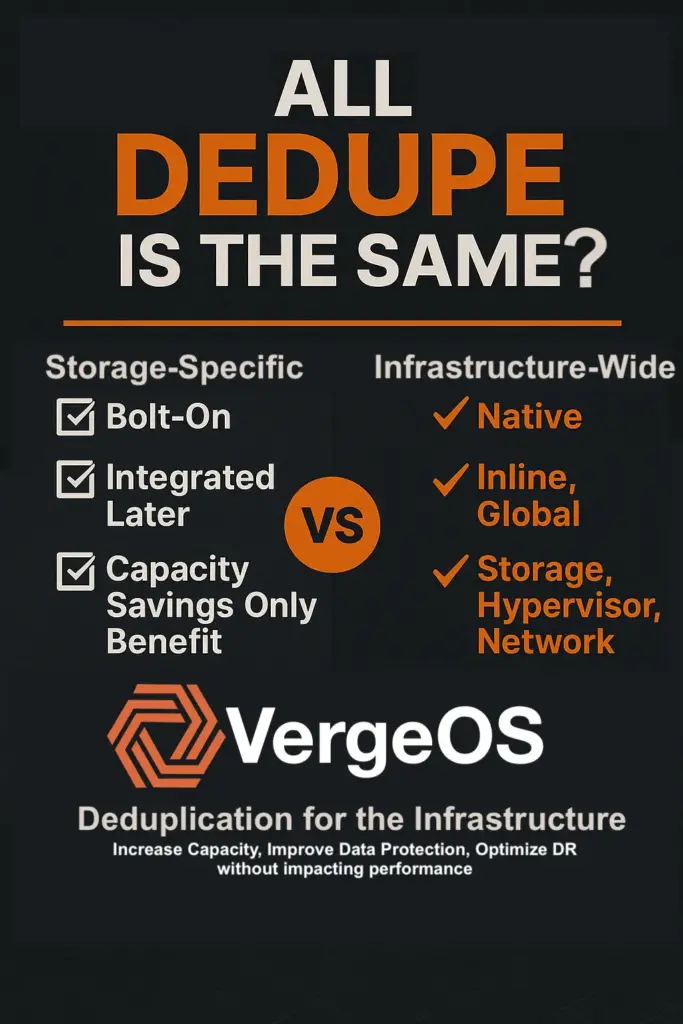
Not all deduplication is created equal. Broadly, vendors take one of three approaches:

  • Bolt-On: Deduplication is a separate process layered onto existing systems. It introduces overhead, requires additional metadata, and forces rehydration between steps.
  • Integrated Later: Deduplication was added to the platform after launch. Better than bolt-on, but still scoped to clusters or volumes rather than spanning the entire stack.
  • Array-Native: Vendors like Pure Storage offer always-on deduplication, but it starts once data hits the array. CPU, RAM, and WAN costs remain untouched.
  • Infrastructure-Wide: Platforms like VergeOS embed deduplication across storage, compute, and networking in a unified architecture, eliminating silos and preserving deduplication across the entire lifecycle of the data.

When Infrastructure-wide deduplication Matters

Infrastructure-wide deduplication becomes strategically relevant during periods of infrastructure change. Organizations evaluating VMware alternatives should reconsider their entire technology stack. AI workloads generate massive repetitive datasets that storage-specific deduplication handles poorly. Budget pressures make the 30–50% resource overhead of fragmented approaches increasingly difficult to justify, and fragmented deduplication is a key component of the AFA Tax.

The question for IT leaders isn’t whether deduplication works—it’s where it works and how broadly its benefits extend. Infrastructure-wide deduplication transforms a commodity storage feature into a competitive strategic advantage that improves performance, reduces costs, and enables new operational patterns.

Looking Ahead

As infrastructures evolve toward ultraconverged, AI-ready, and private-cloud designs, deduplication will become more than an efficiency tool. It will serve as a foundation for agility, enabling IT to scale workloads globally, replicate AI datasets instantly, and deliver faster recovery from outages.

Rather than accepting the inefficiencies of fragmented deduplication, organizations can adopt infrastructure-wide approaches that optimize the entire stack. The technology exists, the business case is clear, and the timing—with widespread infrastructure reevaluations underway—is ideal.

Ready to eliminate the deduplication tax?

[ Schedule a Whiteboard Technical Deepdive ] [ Download The White Paper ]

Filed Under: Storage Tagged With: Deduplication, Disaster Recovery, Storage

855-855-8300

Get Started

  • Versions
  • Request Tour

VergeIO For

  • VMware Alternative
  • SAN Replacement
  • Solving Infrastructure Modernization Challenges
  • Artificial Intelligence
  • Hyperconverged
  • Server Room
  • Secure Research Computing

Product

  • Benefits
  • Documents
  • Architecture Overview
  • Use Cases
  • Videos

Company

  • Blog
  • Technical Documentation
  • Legal

© 2026 VergeIO. All Rights Reserved.