• Skip to main content
  • Architecture
    • Overview
      Learn about VergeOS’ unique unfied architecture that integrates virtualization, storage, networking, AI, backup and DR into a single data center operating system
    • Infrastructure Wide Deduplication
      VergeOS transforms deduplication from a storage-only commodity into a native, infrastructure-wide capability that spans storage, virtualization, and networking, eliminating hidden resource taxes
    • VergeFS
      VergeFS is a distributed, high-performance global file system integrated into VergeOS, unifying storage across nodes, tiers, and workloads while eliminating the need for external SANs
    • VergeFabric
      VergeFabric is VergeOS’s integrated virtual networking layer, delivering high-speed, low-latency communication across nodes while eliminating the complexity of traditional network configurations.
    • Infrastructure Automation
      VergeOS integrates Packer, Terraform, and Ansible to deliver an end-to-end automation pipeline that eliminates infrastructure drift and enables predictable, scalable deployments.
    • VergeIQ
      Unlock secure, on-premises generative AI—natively integrated into VergeOS. With VergeIQ, your enterprise gains private AI capabilities without the complexity, cloud dependency, or token-based pricing.
  • Features
    • Virtual Data Centers
      A VergeOS Virtual Data Center (VDC) is a fully isolated, self-contained environment within a single VergeOS instance that includes its own compute, storage, networking, and management controls
    • High Availability
      VergeOS provides a unified, easy-to-manage infrastructure that ensures continuous high availability through automated failover, storage efficiency, clone-like snapshots, and simplified disaster recovery
    • ioClone
      ioClone utilizes global inline deduplication and a blockchain-inspired file system within VergeFS to create instant, independent, space-efficient, and immutable snapshots of individual VMs, volumes, or entire virtual data centers.
    • ioReplicate
      ioReplicate is a unified disaster-recovery solution that enables simple, cost-efficient DR testing and failover via three‑click recovery of entire Virtual Data Centers—including VMs, networking, and storage.
    • ioFortify
      ioFortify creates immutable, restorable VDC checkpoints and provides proactive ransomware detection with instant alerts for rapid recovery and response.
    • ioMigrate
      ioMigrate enables large-scale VMware migrations, automating the rehosting of hundreds of VMs (including networking settings) in seconds with minimal downtime by seamlessly transitioning entire VMware environments onto existing hardware stacks.
    • ioProtect
      ioProtect offers near-real-time replication of VMware VMs—including data, network, and compute configurations—to a remote disaster‑recovery site on existing hardware, slashing DR costs by over 60% while supporting seamless failover and testing in an efficient, turnkey VergeOS Infrastructure.
    • ioOptimize
      ioOptimize leverages AI and machine learning to seamlessly integrate new and old hardware and automatically migrate workloads from aging or failing servers.
    • ioGuardian
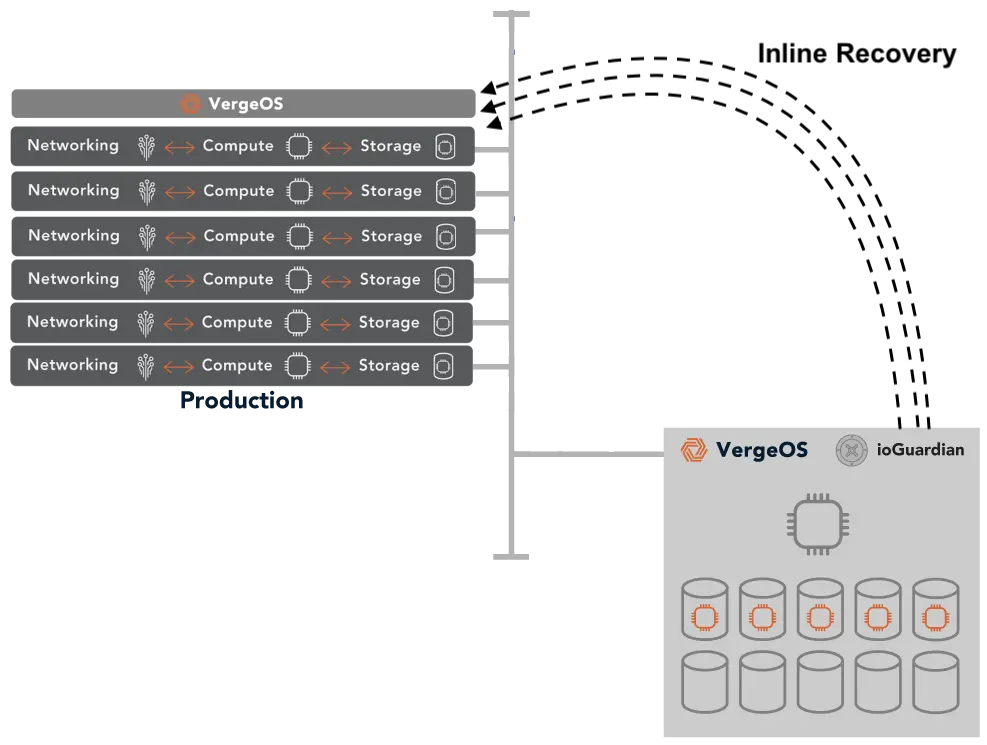
      ioGuardian is VergeIO’s built-in data protection and recovery capability, providing near-continuous backup and rapid VM recovery during multiple simultaneous drive or server failures.
  • IT Initiatives
    • VMware Alternative
      VergeOS offers seamless migration from VMware, enhancing performance and scalability by consolidating virtualization, storage, and networking into a single, efficient platform.
    • Hyperconverged Alternative
      VergeIO’s page introduces ultraconverged infrastructure (UCI) via VergeOS, which overcomes HCI limitations by supporting external storage, scaling compute and storage independently, using existing hardware, simplifying provisioning, boosting resiliency, and cutting licensing costs.
    • SAN Replacement / Storage Refresh
      VergeIO’s storage by replacing aging SAN/NAS systems within its ultraconverged infrastructure, enhancing security, scalability, and affordability.
    • Infrastructure Modernization
      Legacy infrastructure is fragmented, complex, and costly, built from disconnected components. VergeOS unifies virtualization, storage, networking, data protection, and AI into one platform, simplifying operations and reducing expenses.
    • Secure Research Computing
      VergeIO's Secure Research Computing solution combines speed, isolation, compliance, scalability, and resilience in a cohesive platform. It’s ideal for institutions needing segmented, compliant compute environments that are easy to deploy, manage, and recover.
    • Venues, Remote Offices, and Edge
      VergeOS delivers resiliency and centralized management across Edge, ROBO, and Venue environments. With one platform, IT can keep remote sites independent while managing them all from a single pane of glass.
    • Fight Data Center Inflation
      DRAM, SSD and server prices keep climbing. VergeOS uses as much as 50% less RAM per VM than VMware, runs on the servers you already own, and moves cold data to low-cost hard drives.
  • Blog
      • Comparing vSAN ESA to VergeFS
      • Edge Disaster Recovery: Keep Customer-Facing Locations OpenEdge disaster recovery for stores and venues. VergeOS runs a site on one server, recovers it locally from snapshots and fails it over to the core.
      • VMware Migration Testing Is Critical to Completing Your ExitVMware migration testing decides whether your exit finishes. VergeOS keeps the VMware image, takes instant snapshots and isolates each workload in a VDC.
    • View All Posts
  • Resources
    • Become a Partner
      Get repeatable sales and a platform built to simplify your customers’ infrastructure.
    • Technology Partners
      Learn about our technology and service partners who deliver VergeOS-powered solutions for cloud, VDI, and modern IT workloads.
    • White Papers
      Explore VergeIO’s white papers for practical insights on modernizing infrastructure. Each paper is written for IT pros who value clarity, performance, and ROI.
    • In The News
      See how VergeIO is making headlines as the leading VMware alternative. Industry analysts, press, and partners highlight our impact on modern infrastructure.
    • Press Releases
      Get the latest VergeOS press releases for news on product updates, customer wins, and strategic partnerships.
    • Case Studies
      See how organizations like yours replaced VMware, cut costs, and simplified IT with VergeOS. Real results, real environments—no fluff.
    • Webinars
      Explore VergeIO’s on-demand webinars to get straight-to-the-point demos and real-world infrastructure insights.
    • Documents
      Get quick, no-nonsense overviews of VergeOS capabilities with our datasheets—covering features, benefits, and technical specs in one place.
    • Videos
      Watch VergeIO videos for fast, focused walkthroughs of VergeOS features, customer success, and VMware migration strategies.
    • Technical Documentation
      Access in-depth VergeOS technical guides, configuration details, and step-by-step instructions for IT pros.
  • How to Buy
    • Schedule a Demo
      Seeing is believing, set up a call with one of our technical architects and see VergeOS in action.
    • Versions
      Discover VergeOS’s streamlined pricing and flexible deployment options—whether you bring your own hardware, choose a certified appliance, or run it on bare metal in the cloud.
    • Test Drive – No Hardware Required
      Explore VergeOS with VergeIO’s hands-on labs and gain real-world experience in VMware migration and data center resiliency—no hardware required
  • Company
    • About VergeIO
    • Support
      Get fast, expert help from VergeIO’s support team—focused on keeping your infrastructure running smoothly.
    • Careers
      Join VergeIO and help reshape the future of IT infrastructure. Explore open roles and growth opportunities.
  • 855-855-8300
  • Contact
  • Search
  • 855-855-8300
  • Contact
  • Search
  • Architecture
    • Overview
    • VergeFS
    • VergeFabric
    • Infrastructure Automation
    • VergeIQ
  • Features
    • Virtual Data Centers
    • High Availability
    • ioClone
    • ioReplicate
    • ioFortify
    • ioMigrate
    • ioProtect
    • ioOptimize
    • ioGuardian
  • IT Initiatives
    • VMware Alternative
    • Hyperconverged Alternative
    • SAN Replacement / Storage Refresh
    • Infrastructure Modernization
    • Secure Research Computing
    • Venues, Remote Offices, and Edge
    • Fight Data Center Inflation
  • Blog
  • Resources
    • Become a Partner
    • Technology Partners
    • White Papers
    • In The News
    • Press Releases
    • Case Studies
    • Webinars
    • Documents
    • Videos
    • Technical Documentation
  • How to Buy
    • Schedule a Demo
    • Versions
    • Test Drive – No Hardware Required
  • Company
    • About VergeIO
    • Support
    • Careers
Ă—
  • Architecture
    • Overview
    • VergeFS
    • VergeFabric
    • Infrastructure Automation
    • VergeIQ
  • Features
    • Virtual Data Centers
    • High Availability
    • ioClone
    • ioReplicate
    • ioFortify
    • ioMigrate
    • ioProtect
    • ioOptimize
    • ioGuardian
  • IT Initiatives
    • VMware Alternative
    • Hyperconverged Alternative
    • SAN Replacement / Storage Refresh
    • Infrastructure Modernization
    • Secure Research Computing
    • Venues, Remote Offices, and Edge
    • Fight Data Center Inflation
  • Blog
  • Resources
    • Become a Partner
    • Technology Partners
    • White Papers
    • In The News
    • Press Releases
    • Case Studies
    • Webinars
    • Documents
    • Videos
    • Technical Documentation
  • How to Buy
    • Schedule a Demo
    • Versions
    • Test Drive – No Hardware Required
  • Company
    • About VergeIO
    • Support
    • Careers

HCI

October 16, 2026 by George Crump

On-Demand · No Registration

How to Use HCI and Hard Drives to Fight Data Center Inflation

Watch the whole session, with every demo. No registration required.

Watch Now

Hard drive tiering moved back to the top of my list the day Dave Vincent and I priced drives to expand our lab. A 15.36 TB NVMe SSD quoted at $10,850, or about $706 per terabyte. A 24 TB Western Digital hard drive came in at $1,350, about $56 per terabyte. Flash now costs more than 12 times as much per terabyte as disk, and on October 7 Dave and I spent an hour with a record audience working through what IT teams can do about it.

Watch the whole session, with every demo, in the on-demand presentation. No registration required.

Key Takeaways
  • Data center inflation now reaches the drive bay, and putting every workload on flash has become an expensive default.
  • VergeOS sets the tier per virtual drive and moves it live, so the administrator decides placement and can reverse it in seconds.
  • Metadata on NVMe, write reordering, read prefetch and a deduplicated RAM cache make hard drives viable for the long tail of workloads.

Data Center Inflation Has Reached the Drive Bay

I love flash as much as the next guy, but I don’t love it 12 times as much. The price gap keeps widening, and I see no relief coming soon. A new fab takes at least two years to build, longer in countries with strict permitting, and the AI factories driving this demand will absorb new supply as fast as it ships.

Raw media cost, from one terabyte to a 150 TB estate, NVMe flash versus hard drives One terabyte costs about 706 dollars on NVMe flash and about 56 dollars on hard drives. Across a 150 TB estate that grows to 105,900 dollars on flash against 8,400 dollars on hard drives, 97,500 dollars less in raw media. One terabyte, then a 150 TB estate 1 TB of capacity 150 TB of capacity Raw media cost per terabyte Raw media cost for 150 TB All flash · 15.36 TB NVMe $706 $105,900 Hard drives · 24 TB HDD $56 $8,400 $97,500 less in raw media
Kioxia 15.36 TB NVMe at $10,850 against a WD 24 TB hard drive at $1,350, checked September 28, 2026. Raw media for a single copy, before redundancy.

When flash got cheaper every quarter, putting everything on it was like hitting a watermelon with a sledgehammer. It worked, and nobody questioned the bill. Back in my analyst days, friends at the all-flash array vendors told me their systems averaged under 5,000 IOPS. Most data sits idle most of the time. At today’s prices it pays to slice the watermelon, which means IT takes control of placement again.

Pick Your Tier, Then Change Your Mind

The first generation of hybrid storage relied on auto-tiering, where an algorithm decided which blocks went to disk. It moved data you wanted on flash, and undoing its choices meant scripting a touch of every file. I covered why that failed in Hybrid Storage Failed Once. Will It Fail Again? on StorageSwiss.

VergeOS hands the decision to the administrator. Each virtual drive has a preferred tier, and changing it starts a live, background migration with no reboot and no maintenance window. During the webinar Dave ran a SQL Server VM processing about 80,000 rows per second, moved its data drive from Tier 1 NVMe to Tier 5 hard drives, and moved it back. The query monitor never flinched. From the CLI, the same change took about 1.3 seconds to accept.

Hard drive tiering in VergeOS: moving a live SQL Server drive between NVMe and hard drives A SQL Server VM keeps its OS, transaction log and tempdb drives on Tier 1 NVMe. Its data drive moves from Tier 1 NVMe to Tier 5 hard drives and back while queries keep running. Preferred tier, set per virtual drive and changed live SQL Server VM OS · Tier 1 NVMe Transaction log · Tier 1 tempdb · Tier 1 NVMe Data · Tier 1 NVMe Data · Tier 5 hard drives Tier 1 · NVMe flash Tier 5 · hard drives SQL data drive Query monitor: about 80,000 rows per second, steady through both moves
The data drive moves to hard drives and back while the OS, log and tempdb stay on NVMe. The VM never stops.

That speed is what makes hard drive tiering practical. You can be aggressive, push the long tail to disk, and move a drive back to flash the moment someone complains. Dave also showed a local AI agent finding idle drives and moving them with the same CLI. If you want the cost math on a single database VM, Dave walks through it in Can HCI Run a Database Application on Hard Disk Drives?

How VergeOS Makes Hard Drives Perform

Our CTO, Greg Campbell, built most of this a decade ago, right before the industry went all-flash. VergeOS keeps all metadata on Tier 0 NVMe, so lookups never touch a spinning disk. It reorders incoming writes from many VMs into sequential streams, which is how hard drives like to work, and prefetches reads across the cluster.

How VergeOS makes hard drives perform Random writes from several VMs enter VergeOS, which sends metadata to Tier 0 NVMe and reorders the data into a sequential stream for the hard drive tier. A deduplicated RAM cache on each host serves repeat reads from memory. Random writes in, sequential writes out VM 1 VM 2 VM 3 VergeOS write reordering and read prefetch Tier 0 NVMe all metadata Hard drive tier sequential writes Host RAM cache deduplicated, next to the VM repeat reads served from memory
Metadata goes to Tier 0 NVMe, and writes from many VMs reach the hard drives as ordered, sequential streams.

Each host also keeps a RAM cache next to the VM. Global inline deduplication runs in the core code, so the cache holds no duplicate blocks and serves more of the working set from memory. Some of the performance in Dave’s demo came from that cache, and that is by design. It is why the disk tier sees far less random I/O than its raw specs suggest.

Protecting High-Capacity Drives

Hard drives fail, and so do SSDs, but a large hard drive takes longer to rebuild. VergeOS sets redundancy per system and applies it per tier. N+1 keeps two copies of every block and survives one failure. N+2 keeps three copies and survives two. A failure in the hard drive tier stays in that tier.

Frequent, deduplicated snapshots cover logical mistakes. For failures beyond the redundancy level, ioGuardian turns your DR site into a repair server. VergeOS pulls back the 64K blocks it needs from the remote copy, which avoids a rollback to a snapshot. The cost is latency on those reads. You can place a repair server in the primary data center to cut that latency, at the price of another set of drives.

ioGuardian supplies missing blocks from the DR site when drive failures exceed redundancy Three VMs each read from their own hard drive at the primary site. Two of the three drives fail, more than N+1 redundancy covers. The ioGuardian repair server at the DR site then supplies the missing 64K blocks to the two affected VMs, which keep running with added latency on those reads. ioGuardian: the DR copy doubles as a repair server Running VMs Primary site · hard drive tier, N+1 DR site · ioGuardian VM 1 Drive 1 Copy 1 VM 2 Drive 2 Copy 2 VM 3 Drive 3 Copy 3 Normal operation: each VM reads from its own drive 64K blocks Drives 2 and 3 fail, more than N+1 redundancy covers ioGuardian supplies the missing blocks from the DR site
Each VM reads from its own drive. When two drives fail, more than N+1 covers, ioGuardian at the DR site supplies the missing blocks, which avoids a rollback to a snapshot. The trade-off is latency on those reads.

What Attendees Asked

What happens on a cache miss? The read goes to the hard drive at its native speed. The sequential layout gives the drive the best possible access pattern, and the RAM cache absorbs the burst of requests, so the disk avoids hundreds of workloads hammering it at random.

How does VergeOS compare to Proxmox with Ceph? VergeOS is a single code base. You load one image and get compute, storage and networking in one product, which makes it faster to learn and run. Topgolf runs VergeOS across more than 100 venues, offices and data centers.

What server do I need for hard drives? Pick a chassis that fits the workload. That usually means a 2U server with more drive bays instead of a 1U flash-only node.

Where to Start

Pull a 30-day I/O report, find the VMs that sit idle, and set their preferred tier to hard drives. If a workload slows down, move it back.

The first step in fighting data center inflation is to avoid buying new hardware at all. VergeOS runs on the servers you already own, which also makes it the fastest path off VMware. Watch the on-demand presentation for every demo, no registration required, or book a technical whiteboard session and we will map your workloads to tiers.

Key Terms

Hard drive tiering

Placing data on hard disk drives instead of flash according to how often it is accessed.

Preferred tier

The VergeOS setting on each virtual drive that names the storage tier it should live on.

Long tail

The many workloads that generate little I/O over a 30-day period.

ioGuardian

A VergeOS repair server, usually at the DR site, that supplies missing blocks when failures exceed the redundancy level.

Frequently Asked Questions

Does moving a drive to a different tier require downtime?

The move runs in the background and the VM keeps running. Dave moved a live SQL Server data drive from NVMe to hard drives and back during the webinar.

Does VergeOS use auto-tiering?

The administrator sets the preferred tier for each virtual drive and can change it at any time, which keeps placement predictable and reversible.

Which workloads belong on hard drives?

Workloads in the long tail of a 30-day I/O report, such as file servers, ISO libraries, dev and test, backup targets and database data files with modest I/O.

Where can I watch the webinar?

The on-demand presentation includes every demo and requires no registration.
Filed Under: Storage Tagged With: flash inflation, hard disk drives, HCI, HCIandHDD, ioGuardian, Tiering, Webinar

October 12, 2026 by Dave Vincent

A database VM is five workloads sharing one box. Put each drive on the tier it needs, and most of the capacity lands on hard disk drives.

Here’s the result, up front: I moved a live SQL Server data drive from NVMe onto hard disk drives. At today’s street prices, that one change cuts the VM’s storage media cost from $263 to $133. No downtime, no maintenance window. One setting on one drive, while the database kept answering queries.

Now imagine that across a whole data center estate. Take 200 TB: if even 75% of it can move from NVMe to hard disk drives, that’s 150 TB at $650 less per terabyte, or $97,500 in raw media saved. Even if you keep a second copy on ioGuardian for better than RF3 redundancy, that’s still more than $50,000 in savings.

On-Demand · No Registration

How to Use HCI and Hard Drives to Fight Data Center Inflation

George Crump and Dave Vincent move a running VM from flash to hard drives and back. Every demo included.

Watch Now

Why it matters now: for years the default answer to “which storage?” was “more flash,” because flash got cheaper every quarter. That era is over. At late-September street prices, a 15.36 TB NVMe SSD costs $706 per terabyte and a 24 TB hard drive costs $56, and flash prices keep climbing. I don’t see that reversing. Put everything on flash, just in case has become an expensive habit.

So the real question isn’t can a database run on hard disk drives. It’s what level of performance does each part of that database actually need, and what are you willing to pay for it? Nobody can answer that for your workload but you, and you’ll get there by experimenting. What VergeOS gives you is the ability to put each workload on the right tier, and move it again whenever the numbers, or the business, tell you to.

Key Takeaways
  • Flash prices are rising with no relief in sight, so “all flash, just in case” is now an expensive default.
  • A database VM is several workloads, and each one should get the level of performance it needs, not more.
  • The right tier is something you find by experimenting. On VergeOS, Preferred Tier is set per VM drive and changes move live, so every experiment is reversible and placement can change whenever business needs do.
  • In one example, moving a 200 GB SQL Server data drive to hard disk drives cut the VM’s media cost roughly in half.

A Database Is Several Workloads Wearing One VM

Take the example VM for the math: SQL Server, five drives, 510 GB total. Look at what each drive actually does and the “databases need flash” rule starts to fall apart.

DriveSizeWhat it does all dayWhere it belongs
OS80 GBBoot, patches, logsNVMe
Transaction log40 GBSmall sequential writes; every commit waits on itNVMe
tempdb40 GBBursty random I/O from sorts, joins, temp tablesNVMe
Data files200 GBCheckpoint writes, reads of cold pagesIt depends (often HDD)
Local backups150 GBLarge sequential streamsHDD
A SQL Server VM is five workloads with different I/O patterns Animated diagram of five SQL Server VM drives. The OS drive sees light I/O, the transaction log a steady stream of small sequential writes, and tempdb random bursts, so all three belong on NVMe. Most reads headed for the data drive stop at the buffer pool in RAM, so the data drive is a hard disk drive candidate. Backups are large sequential streams that suit hard disk drives. DriveI/O patternWhere it belongs OS80 GB NVMe Transaction log40 GB NVMe tempdb40 GB NVMe Data files200 GB HDD candidate Local backups150 GB HDD Buffer pool(RAM)
Three drives need NVMe. Most reads bound for the data drive stop at the buffer pool, which makes it a hard disk drive candidate. Backups belong on HDD.

The transaction log is the drive that decides how the app feels. Every commit waits on it, so its latency shows up directly in response time. tempdb is the other flash-hungry one.

The data drive is the one people get wrong. SQL Server pulls pages into its buffer pool in RAM and serves repeat reads from there. If the active working set fits in memory, the data drive mostly sees checkpoint flushes and the occasional cold page. It isn’t idle, but it’s nowhere near the monster everyone pictures. And backups? Big sequential streams are the one job spinning disks have always been great at.

Why Most HCI Platforms Say No to Hard Disk Drives

Most HCI platforms treat storage as one cluster-wide pool run by policy, and that’s where the no comes from. VMware’s current direction, vSAN ESA, requires all-NVMe hardware, so HDD isn’t even on the menu. Hybrid designs put a flash cache in front of disk and, by default, let an algorithm decide what stays hot. Some let you pin specific disks to flash, but the starting assumption is that the cache will figure it out. That cache-first design is a big part of why hybrid storage failed the first time.

When the cache guesses wrong, the database eats full HDD latency at a moment nobody picked. So vendors play it safe and spec all-flash for anything that smells like a database. That means paying flash prices for backup files and cold data pages that a spinning disk would serve just fine.

Moving the Data Drive to HDD, Live

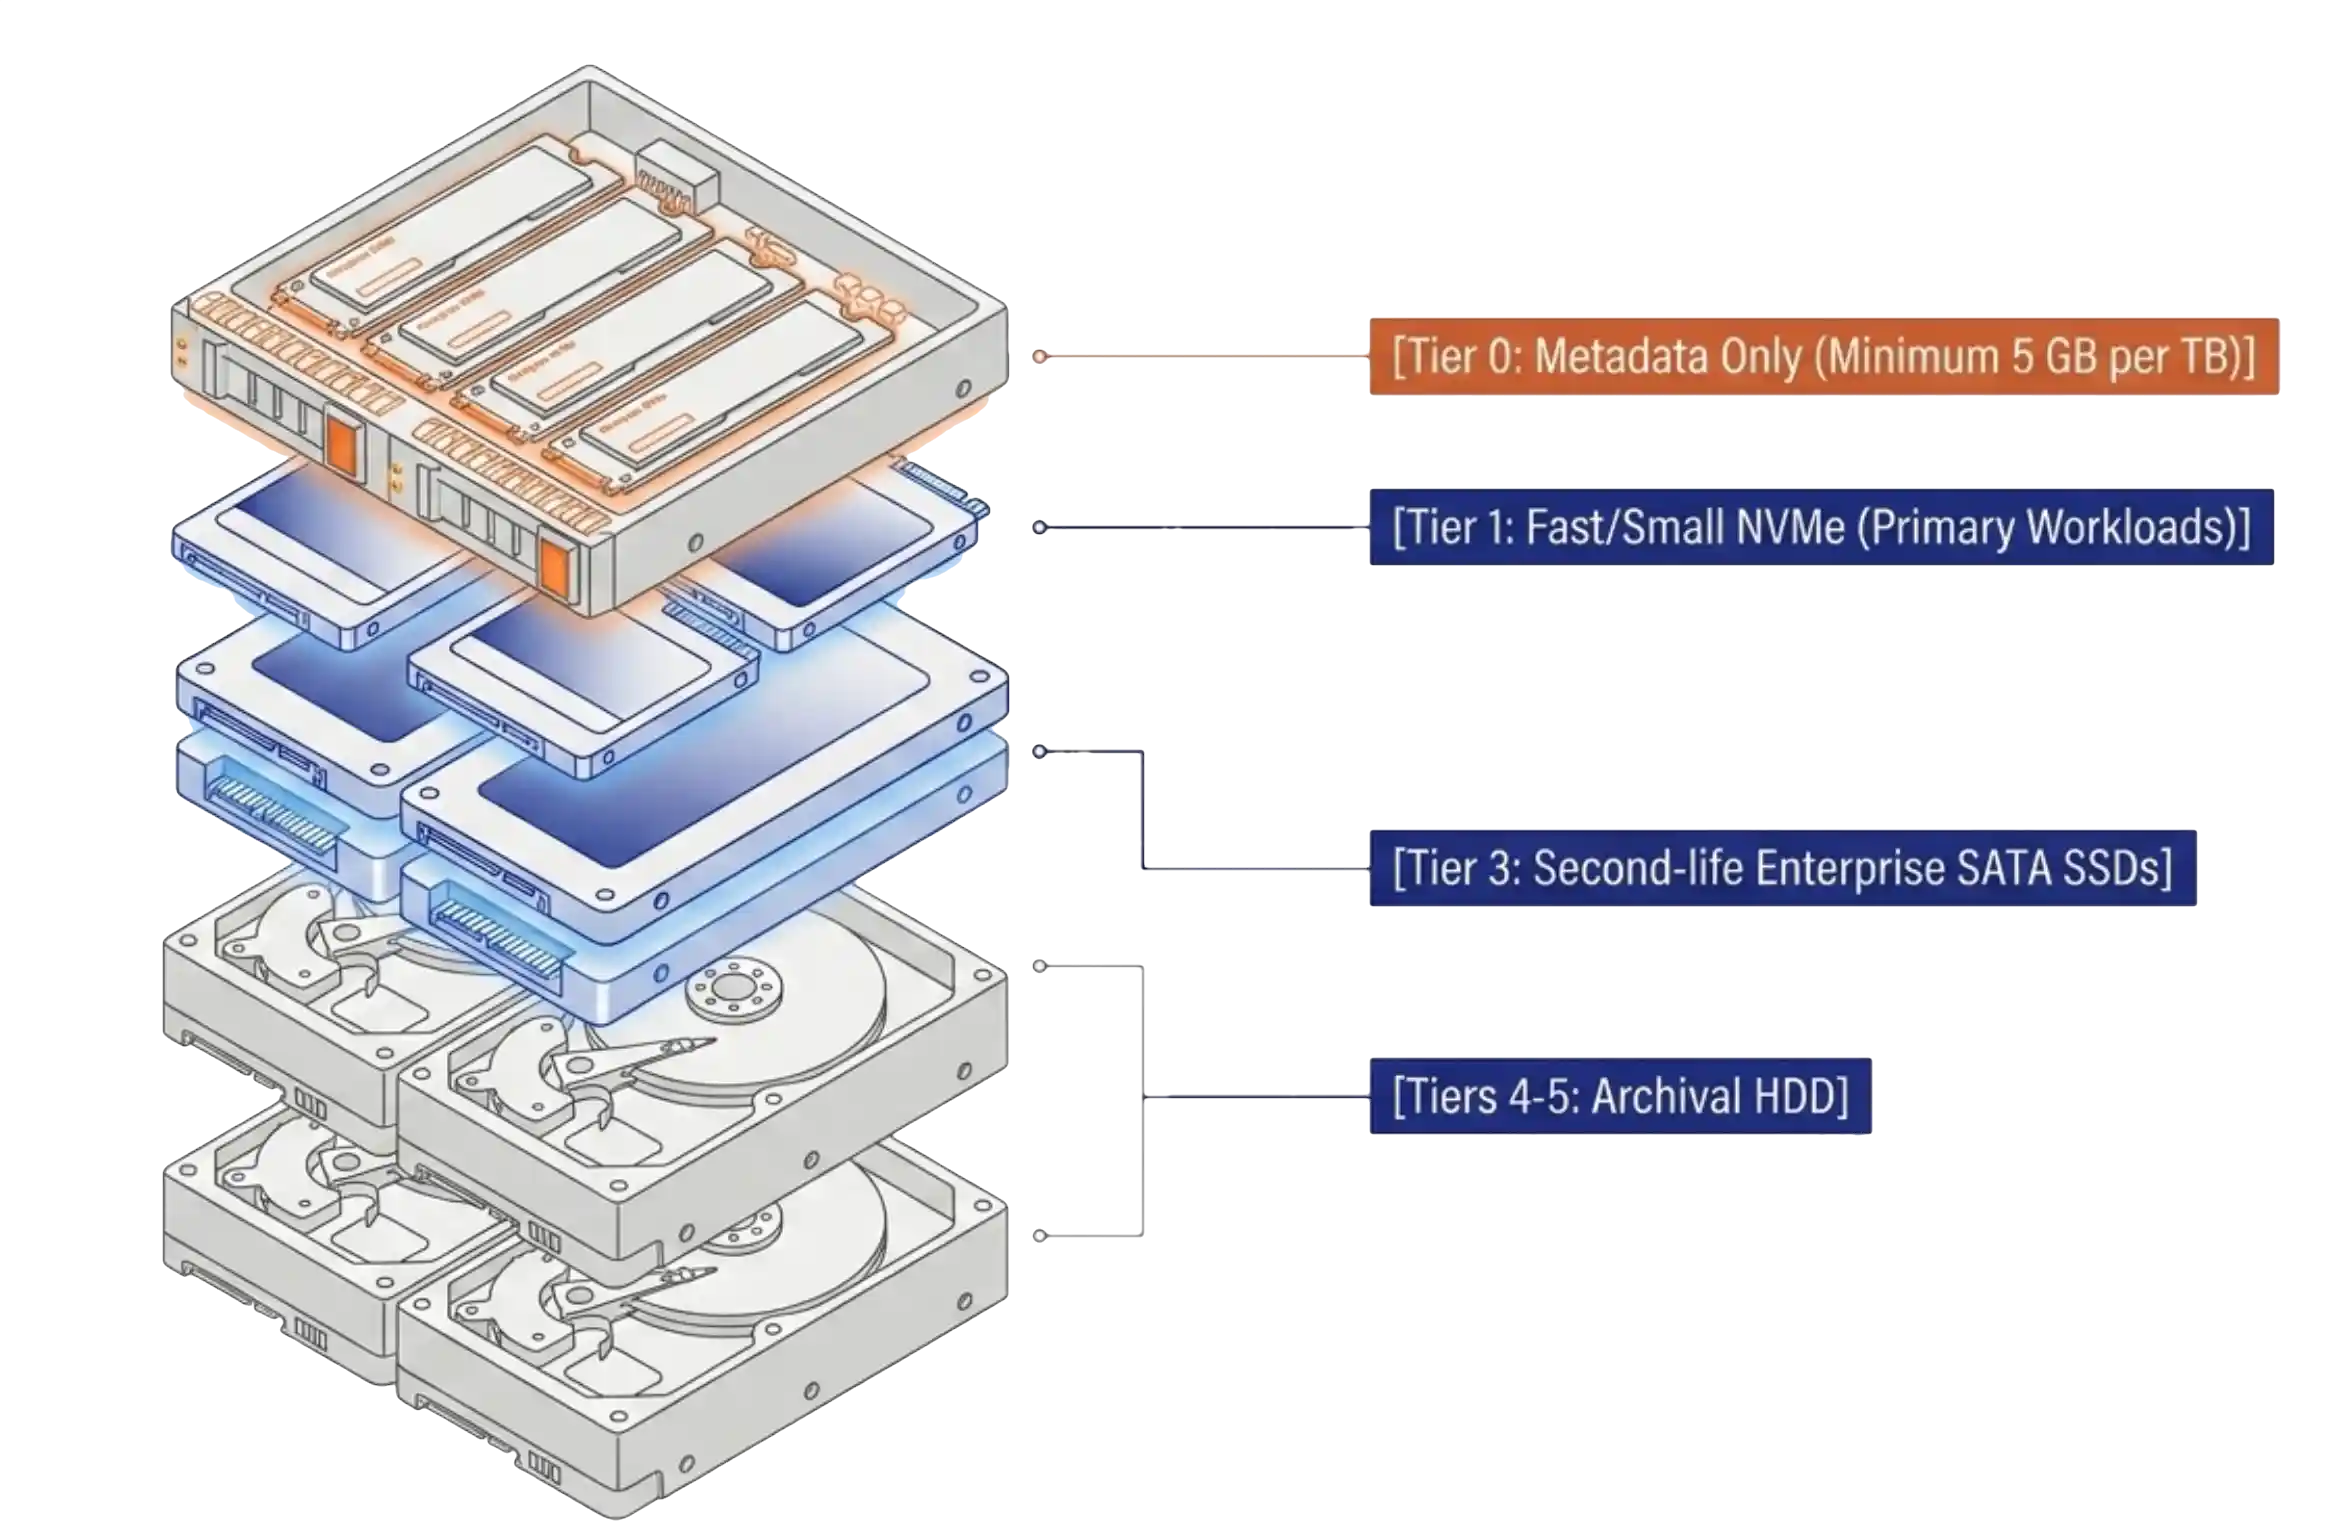
VergeOS builds storage into the same code base as compute and networking, and its built-in vSAN sorts media into six tiers. Three of them matter here:

  • Tier 0 holds metadata on enterprise NVMe, so block lookups never wait on a spinning disk, even when the data itself lives on HDD.
  • Tier 1 is performance NVMe, where latency-sensitive drives live.
  • Tiers 4 and 5 are high-capacity hard drives.

Placement is a per-drive setting called Preferred Tier. In the example, the OS, log, and tempdb drives stay on Tier 1 NVMe, and the backup drive already lives on Tier 4. Moving the data drive is one change:

  1. Open the VM and select the data drive.
  2. Change its Preferred Tier from 1 to 4 and save.
  3. That’s it. VergeOS starts a live, online background migration, and the VM keeps serving queries while the blocks move.
Moving a SQL Server data drive from Tier 1 NVMe to Tier 4 hard disk drives, live Animated diagram. The 200 GB data drive moves from the Tier 1 NVMe tier to the Tier 4 hard disk drive tier after one Preferred Tier change while the VM stays online. The VM’s storage media cost drops from $263 to $133, a $130 saving, and 69 percent of its capacity ends up on hard disk drives. SQL Server VM Online, serving queries Storage media cost $263 $133 Saved $130 (49.5%) Moving live, no downtime Move complete 69% of capacity on HDD Tier 1 · NVMe OS, transaction log, tempdb OS80 GB Log40 GB tempdb40 GB Tier 4 · Hard disk drives Backups, cold data Backups150 GB Preferred Tier 1 → 4 Data files 200 GB
One Preferred Tier change moves the 200 GB data drive to Tier 4 hard disk drives while the VM stays online. Media cost drops from $263 to $133.

And placement isn’t a one-time decision. Business needs change, so tiers can too. Quarter-end close coming up? Promote the finance database’s data drive to Tier 1 for the crunch, then drop it back to Tier 4 when it’s over. An app launch, an audit, a seasonal spike: same idea. The move runs live in the background, so storage follows the business instead of the other way around.

I ran exactly this kind of move on a live SQL workload and recorded the whole thing. Here’s the honest part about what to measure. Commit latency is the wrong number to brag about, because the transaction log never left NVMe. The numbers that tell you whether the data drive is happy on HDD are read latency on that drive and PAGEIOLATCH waits in SQL Server. Those are the numbers to watch when you try this on your own database, and What Trips People Up below covers what can push them the wrong way.

The ROI on One Database

Same street prices as our last post: $706 per terabyte for a 15.36 TB NVMe SSD, $56 per terabyte for a 24 TB hard drive. On flash, the 200 GB data drive costs $141.20 in raw media. On HDD, it costs $11.20. That’s 92% less for the same bytes.

SQL Server VM media cost and capacity before and after moving the data drive to hard disk drives Before the move the VM has 360 GB on flash and 150 GB on hard disk drives, for $262.56 in raw media. After moving the 200 GB data drive, it has 160 GB on flash and 350 GB on hard disk drives, for $132.56, a $130 saving or 49.5 percent. Prices are $706 per TB for NVMe flash and $56 per TB for hard disk drives. Flash at $706/TB Hard disk drives at $56/TB Media cost Before $262.56 After $132.56 −$130 (49.5%) Capacity Before 360 GB flash 150 GB HDD After 160 GB flash 350 GB HDD, 69% Raw media cost, single copy. Street prices checked September 28, 2026.
One drive move cuts the VM’s media cost by $130 and puts 69% of its capacity on hard disk drives.

One Preferred Tier change saved $130 and cut the VM’s media cost roughly in half (49.5%), with 69% of its capacity now on hard disk drives.

A $130 saving is small. That’s the point. This is one modest VM. Every terabyte you move from flash to HDD saves $650 in raw media, and a redundancy scheme that keeps a second copy doubles it. Move 20 TB of cold data files and backups across a cluster and that’s $13,000 in raw media, or $26,000 with the second copy counted. VergeOS licenses per server, so that money stays in your budget instead of feeding a capacity meter.

What Trips People Up

  • A working set bigger than RAM. Heavy OLTP that can’t fit its hot data in the buffer pool reads from the data drive constantly. That drive stays on Tier 1, full stop.
  • Maintenance jobs read everything. Index rebuilds, DBCC CHECKDB, and statistics updates scan the data drive end to end. On HDD they take longer, so test your maintenance window, not just your daytime queries.
  • Cold starts. After a restart or failover the buffer pool is empty, and the first wave of queries comes off disk. Expect a slower warm-up on HDD.
  • Checkpoints are light, but random. Random writes are a spinning disk’s weak spot. Watch write latency on the data drive during checkpoints, not just reads.
  • Guessing instead of experimenting. This is the big one. Nobody, me included, can tell you the right tier for your database from a blog post. The move is live and reversible, so treat it as an experiment: move the data drive to Tier 4, watch read latency and wait stats for a week, and move it back if the numbers disagree with you.

The best candidates for HDD: reporting databases, historical and archive databases, dev and test copies, and apps with a small hot set.

HCI Storage Placement Compared

All-flash HCIHybrid cache HCIVergeOS
Role of HDDNoneCapacity behind a flash cacheDedicated tiers (4 and 5)
Who decides where data livesCluster policyCaching algorithm by default; some allow pinningAdministrator, per VM drive
Metadata locationFlashVaries by designTier 0 NVMe
Changing placementNot applicablePolicy changeLive background migration, no downtime
Key Terms

Preferred Tier

A per-drive VergeOS setting that tells the vSAN which storage tier should hold that drive’s data. If the chosen tier doesn’t exist, VergeOS uses the nearest available tier.

Buffer pool

The memory SQL Server uses to cache data pages. It absorbs most repeat reads before they ever reach the data drive.

Live tier migration

Moving a drive’s data to a new tier in the background while the VM keeps running.

What This Adds Up To

A database isn’t a flash workload. It’s a handful of workloads, and each one deserves the level of performance it actually needs, at a price that makes sense. Flash isn’t getting cheaper, so that tradeoff will matter more with every refresh cycle. You’ll have to experiment to find the right balance for your environment, and VergeOS makes that experiment cheap: change a drive’s Preferred Tier, measure, and change it again whenever the business needs something different. Try it Monday, undo it Friday.

George Crump and I did this live: we moved a running VM from flash to hard drives and back, then walked through the refresh math for a real cluster. The full presentation is online now, with every demo included and no registration required. Watch How to Use HCI and Hard Drives to Fight Data Center Inflation.

Frequently Asked Questions

Can SQL Server run on hard disk drives in production?

Yes, for the right drives. Keep the transaction log and tempdb on NVMe. Data files for databases whose working set fits in memory, and backup files, can perform well on HDD. Test before you commit.

How much does moving a database to hard disk drives save?

At September 2026 street prices, each terabyte moved from NVMe to HDD saves about $650 in raw media. In the example above, one 200 GB data drive cut the VM’s media cost from $263 to $133.

Does changing a drive’s Preferred Tier require downtime?

No. VergeOS runs the move as a live, online background migration while the VM keeps running.

How do I pick the right tier for each drive?

Experiment. Start with the drives least sensitive to latency, like backups and cold data files, move them to HDD, and watch latency and wait stats. Because VergeOS moves data live, you can move a drive back if performance doesn’t meet your needs.

Is a drive’s tier placement permanent?

No. A drive can move between tiers at any time, live, as business needs change. Promote it to NVMe for a busy period and move it back to HDD afterward.

Filed Under: Storage Tagged With: flash inflation, hard disk drives, HCI, HCIandHDD, SQL Server, Tiering, vSAN

September 29, 2026 by George Crump

Flash now costs 12 to 14 times more per terabyte than a hard drive, and that gap changes how an HCI cluster gets built.

A 24 TB hard drive sells for about $1,350 today, and a 15.36 TB enterprise NVMe SSD sells for $10,850 or more, a gap wide enough to reopen a storage decision most IT teams considered closed years ago. Dave Vincent and I ran into it this month while pricing drives for our labs, where the SSD quote came in near $12,000 and the hard drive quote barely registered by comparison.

Key Takeaways
  • At September 2026 list prices, flash costs 12 to 14 times more per terabyte than a 24 TB hard drive.
  • All-flash HCI ties every terabyte of capacity growth to the most inflated component in the data center.
  • VergeOS runs hard drives and flash in one cluster, moves running VMs between them on command, and protects the hard drive tier with frequent snapshots and ioGuardian.

The Math Behind a $10,000 SSD

These are street prices, checked on September 28, 2026, that show the gap, and they move week to week right now.

DriveCapacityPriceCost per TB
Kioxia KCMYXRUG15T3 NVMe15.36 TB$10,850$706
Solidigm D7-PS1010 NVMe15.36 TB$12,500$814
WD Ultrastar DC HC580 SATA24 TB$1,350$56

The price of one 15.36 TB SSD buys eight 24 TB hard drives, 192 TB of raw capacity for the same money. VergeIO calls this data center inflation, hardware costs rising faster than IT budgets, driven by AI demand for memory and flash. Flash and memory prices climbed 70 to 95 percent through the first half of 2026, and AI buildouts absorb new fab capacity as fast as it comes online. I plan as if this pricing is permanent.

24 TB hard drive versus 15.36 TB SSD, cost per terabyte Kioxia 15.36 TB NVMe SSD at $706 per TB, Solidigm 15.36 TB NVMe SSD at $814 per TB, and a WD 24 TB hard drive at $56 per TB, based on street prices checked September 28, 2026. Cost per terabyte, street prices, September 28, 2026 $0 $200 $400 $600 $800 Kioxia 15.36 TB NVMe SSD: $10,850, or $706 per TB Kioxia 15.36 TB NVMe $10,850 per drive $706 Solidigm D7-PS1010 15.36 TB NVMe SSD: $12,500, or $814 per TB Solidigm 15.36 TB NVMe $12,500 per drive $814 WD Ultrastar DC HC580 24 TB hard drive: $1,350, or $56 per TB WD 24 TB hard drive $1,350 per drive $56 12 to 14 times less per terabyte
A 24 TB hard drive costs $56 per terabyte against $706 to $814 for a 15.36 TB NVMe SSD. Hover a bar for drive prices.

All-Flash HCI Turns a Media Choice into a Refresh Bill

Live Webinar · October 7 · 2:00 PM ET

How to use HCI and Hard Drives to Fight Data Center Inflation

George Crump and Dave Vincent move a running VM from flash to hard drives and back, live from Palo Alto.

Register Now

Every HCI platform sold today defaults to all-flash, a decision the platform made for the customer years ago, back when flash prices fell every quarter and the assumption looked safe. That default now means every terabyte added at refresh time pays the flash price, and capacity-based licensing charges a second time for the same terabyte.

Most workloads need far less performance than all-flash delivers. File shares, VDI profiles, dev and test environments, log retention and a large share of general-purpose VMs sit idle for most of the day. Hard drives are slower than flash, but they stay online, handle most of this work at a speed users accept and cost a fraction as much.

Aging All-Flash Array? Let the Refresh Replace It

An aging dedicated all-flash array faces the same price sheet at its next refresh. The array vendor buys NAND from the same fabs that supply every SSD in the table above, so the quote for new controllers or more capacity arrives with data center inflation already built in. Many arrays also add a per-terabyte software license on top of the hardware, which charges the inflated flash price a second time. For many IT teams, that refresh falls in the same year as a VMware renewal.

Use the refresh to replace the array and exit VMware in one project. VergeOS runs virtualization, storage and networking on standard x86 servers, so the next purchase buys off-the-shelf flash at server prices instead of flash sold through an array vendor. Global inline deduplication means you buy less of that flash, and the file shares, VM templates, aging VMs and snapshots that sit idle on the array today move to 24 TB hard drives at $56 per TB. The separate storage network and the array support contract go away with it. The Storage Refresh vs. Storage Inflation datasheet walks through the math.

Replacing an aging all-flash array and VMware hosts with VergeOS at refresh Animated diagram. Today, VMware hosts reach a dedicated all-flash array over a separate storage network, and the working set, file shares, VM templates, aging VMs and snapshots all pay the flash price. At refresh, VergeOS replaces the hosts and the array. The working set runs on off-the-shelf flash inside the servers, and everything else moves to 24 TB hard drives in the same cluster. Today At refresh, with VergeOS VMware hosts separate storage network Dedicated all-flash array Working set File shares VM templates Aging VMs and snapshots Every terabyte pays the flash price Replaced at refresh refresh VergeOS cluster ServerServerServer FlashFlashFlash 24 TB24 TB24 TB HDDHDDHDD Less flash, off the shelf. The rest at $56 per TB.
At refresh, VergeOS replaces the VMware hosts and the array. The working set runs on off-the-shelf flash inside the servers, and everything else moves to 24 TB hard drives.

Can a 24 TB Hard Drive Keep Up?

For most workloads, yes. Random-I/O databases still belong on flash, but for the rest of the data center the answer comes down to the platform in front of the drive. One of our customers ran a hosting business that sold both flash and spinning-disk capacity with VergeOS underneath. Their customers tested their workloads on hard drives, saw little difference, and kept moving more of them to disk. Dave Vincent saw the same result when he moved a live SQL workload from NVMe to spinning disk and commit latency stayed under a millisecond on both tiers.

VergeOS makes that result repeatable for any IT team. Global inline deduplication runs across every tier, so the cluster stores fewer blocks and more of the working set fits in cache. VergeOS caches data in RAM on the server running the VM, which VergeIO testing shows produces four to five times the cache hit rate of array-side caching. On the write side, VergeOS reorders and groups incoming writes into sequential runs before they reach the platter, the access pattern hard drives handle best.

How VergeOS makes a 24 TB hard drive tier keep up Animated diagram of the VergeOS I/O path. Reads are served from a RAM cache on the server running the VM. Random writes pass through global inline deduplication and are reordered and grouped into sequential runs before they reach the hard drive. VM any workload RAM cache on the server running the VM Reads served from RAM, 4 to 5 times the hit rate of array-side cache Random writes in Dedupe, reorder and group fewer blocks, longer runs Sequential runs out 24 TB hard drive Hard drives handle long sequential runs best. VergeOS shapes the write stream to match before it reaches the platter.
Reads come from RAM next to the VM. Writes arrive random and leave as sequential runs, the pattern a spinning drive handles best.

Afraid of Tiering? Select Tiering That Puts You in Control

Many IT teams steer clear of tiering, and automated tiering is the reason, after two decades of burning plenty of them. An auto-tiering algorithm samples activity, waits for a threshold and makes placement calls without knowing the business behind the workload. It is slow to spot cold data, it misses anything outside its sampling window, and it is slowest of all on the trip back to flash, usually right when users start to notice.

VergeOS puts the IT team in charge of placement instead. The people who run the workloads already know the business calendar, such as a tax application that is write-heavy through April 15 and read-heavy on April 16, and they need no algorithm to predict it. The IT team moves a running VM to the hard drive tier or back to flash on command, in either direction and with no maintenance window, and pins the workloads that must stay hot to a preferred tier. I covered why tiering itself was never the issue in Storage Tiering Is Not the Problem. Losing Control of It Is.

VergeOS moves a running VM between the flash tier and the hard drive tier on command Animated diagram. A running VM sits on the Tier 1 NVMe flash tier, moves down to the Tier 4 hard drive tier on command with the workload online, then moves back to flash the same way. Tier 1 NVMe flash Working set, random-I/O databases Tier 4 24 TB hard drives File shares, templates, aging VMs Move down on command Move back Running VM online the whole time Lab test: API acknowledged the move in 1.3 seconds. A 25 GB disk finished moving in 13 seconds.
The IT team decides placement. A running VM moves to the 24 TB hard drive tier and back on command, with no maintenance window.

Three Ways VergeOS Makes Hard Drives Safe to Use

Tiering under IT control. VergeOS supports six storage tiers inside one vSAN, with tiers 4 and 5 designed for high-capacity hard drives, and the IT team moves a running VM’s disk between tiers on command. In VergeIO lab testing, the API acknowledged the move in 1.3 seconds and a 25 GB disk finished moving in 13 seconds with the workload running. Be aggressive with it, moving a workload to hard drives and moving it back in seconds if someone complains two weeks later.

Frequent snapshots. VergeOS snapshots run on a schedule the IT team controls, hourly by default, which gives every VM on the hard drive tier recent recovery points inside the same system.

ioGuardian. Large drives raise a fair question about exposure during a rebuild. ioGuardian answers it by pulling missing or corrupted blocks from a synchronized remote VergeOS system after a failure that exceeds the cluster’s redundancy, such as multiple drive failures spread across nodes.

VergeOS licenses per server, so the money saved on hard drives and deduplication stays in the budget instead of feeding a capacity meter.

Key Terms

Data center inflation

Hardware costs rising faster than IT budgets, driven by AI demand for memory and flash.

Storage tier

A class of drives in the VergeOS vSAN, numbered 0 through 5, running from metadata NVMe to archival hard drives.

Preferred tier

The VergeOS setting that names the first-choice tier for a VM disk, used to keep critical workloads on flash.

ioGuardian

The VergeOS repair server that restores blocks from a synchronized remote system after a failure beyond redundancy tolerance.

All-Flash HCI and VergeOS Flash Plus Hard Drives

All-flash HCIVergeOS flash plus hard drives
Capacity cost at refreshFlash price for every TBFlash for the working set, $56 per TB for the rest
Workload placementEverything on flashIT team places each VM, moves it live
LicensingOften per TBPer server
Media mixFlash onlyFlash and hard drives in one cluster

See the Answer Live on October 7

Dave and I will answer the question in the title live from Palo Alto on Wednesday, October 7, at 2:00 PM ET, in How to use HCI and Hard Drives to Fight Data Center Inflation. Dave will move a running VM from flash to hard drives and back on camera, and I will walk through the refresh math for a real cluster, so register for the webinar.

Frequently Asked Questions

Can a 24 TB hard drive replace an SSD for every workload?

Random-I/O databases still belong on flash, and VergeOS lets you pin them to a preferred flash tier and place everything else on hard drives.

Does deduplication work on the hard drive tier?

VergeOS runs global inline deduplication across all six tiers, so the hard drive tier gets the same capacity savings as flash.

How long does it take to move a VM back to flash?

The move starts on command and runs with the VM online, and in lab testing small disks finish the trip back to flash in seconds.

Filed Under: Storage Tagged With: Deduplication, flash inflation, HCI, HCIandHDD, ioGuardian, Tiering

August 12, 2026 by Dave Vincent

Technical Deep Dive and How To

Storage tiering is the capability that made arrays worth buying in the first place, and 2026 is the year it stopped being a purely technical subject. Flash repriced this year, and it did not reprice gently. DRAM contract prices rose 90 to 95 percent in a single quarter in early 2026. Enterprise NAND moved 70 to 75 percent in the same window.

Storage tiering across NVMe and second-life SATA tiers in a VergeOS cluster

The cause sits entirely outside the enterprise data center. Hyperscalers building AI infrastructure walked into the component market with a budget that has no practical ceiling and bought the output of the storage industry. Nothing broke. The market simply reset around a new buyer, and the enterprise now sits behind that buyer in the allocation queue.

Buyers reached a conclusion about this on their own. In Omdia research commissioned by VergeIO, covering 400 North American IT professionals in May 2026, software-defined storage ranked first of eight technologies that non-users plan to invest in as a direct response to the shortage. It outranked every array architecture on the list. The reasoning behind that ranking is independence from the underlying hardware, which is a polite way of saying buyers want to stop asking a vendor for permission to purchase a drive.

Key Takeaways
  • Storage tiering is a data-placement decision rather than an array feature, and per-node licensing keeps it a technical decision instead of a financial one.
  • VergeOS exposes tier placement as one mutable field with an online migration behind it, so read tier, set tier, and create on tier are the only primitives a storage tiering policy needs.
  • Reclamation on a source tier is gated by the longest-lived snapshot still referencing the data, which makes retention schedules the real timeline for any capacity recovery plan.

That conclusion raises a fair technical objection. Storage tiering is the ability to put the transaction log on expensive media and the file server on inexpensive media, deliberately, and to change that decision later. Collapsing the array into the operating system to escape a capacity meter is a hollow win if storage tiering does not survive the move. It is a worse win if tiering survives and comes back as a different meter.

The measurements below come from a two-cluster VergeIO lab, and they answer the technical half of that objection. The commercial half is settled by the licensing model, and the two halves only matter together.

Scope note. Everything measured here comes from a VergeIO lab, not a production environment. Two three-node clusters, mixed media, a handful of test workloads, and a blast radius that ends at the lab bench. The commands, timings, and API behaviors are real and reproducible. The hardware choices are not a reference architecture. At least two of them, no Tier 0 on either cluster and a Tier 3 with drives on a single node, fail a production design review outright, and both appear in the fine print below. VergeOS hardware requirements call for enterprise-class drives and network cards in production, and the lab does not meet that bar on every tier. Read the storage tiering mechanics as transferable and the specific figures as illustrative.

Two classes of media, one cluster, one license

The lab’s second cluster mixes two classes of media on purpose, which makes it a useful place to watch storage tiering behave.

TierMediaDrivesRawUsable
1NVMe SSD3 × 256 GB768 GB356.04 GB
3SATA SSD, second-life enterprise3 × 800 GB2,400 GB1,115.77 GB

Tier 1 is fast and small. Tier 3 carries a little over three times the usable capacity on older, slower, second-hand drives. Fast where it matters and inexpensive where it does not is the entire value proposition of storage tiering, and nothing about this arrangement required a storage array.

The Tier 3 drives are the economically interesting ones. They are used enterprise SATA SSDs, the same category of hardware behind the CXTEC equal2new program that appeared in VergeIO’s August 4 announcement about Saratoga Casino Holdings. The comparison deserves a caveat. Saratoga bought professionally refurbished, warrantied servers to run a four-property gaming operation. The lab bought used parts with no warranty at all. What generalizes between the two is the platform economics, not the procurement decision.

Second-life enterprise storage is not inexpensive in absolute terms, and it has firmed up as the primary market tightened behind it. Relative to new flash it remains a bargain, and 2026 widened that gap sharply. Against DRAM at 90 to 95 percent and NAND at 70 to 75 percent in a single year, a used enterprise drive does not have to be cheap to be the obvious way to build a capacity tier. It only has to be less expensive than an alternative that just repriced.

The question that applies at both scales is whether the platform lets an organization use the less expensive media without charging for the privilege.

A license that meters raw physical capacity answers that question badly. Three second-hand 800 GB SATA drives meter identically to three new 800 GB NVMe drives. Same 2.4 TB raw, same bill, and the platform collects on hardware it had nothing to do with. Worse, a raw-capacity meter reads the physical drives before any data reduction happens, so every block the storage engine removes is a saving the vendor recaptures. That is the mechanism that pushes organizations back toward dedicated arrays, and it has been characterized as the case that storage licensing, not storage technology, is what broke hyperconverged infrastructure.

VergeOS licenses per node with every feature included, covering compute, storage, networking, and multi-tenancy in a single license tied to a System ID rather than to hardware (Licensing Overview, Transitioning from VMware). The drives are not a line item. The question stops being what an organization can afford to license and becomes what it can do with tiers.

How VergeOS storage tiering works

VergeOS vSAN organizes physical drives into six tiers, numbered 0 through 5. Tier assignment happens at the drive level, during installation or when drives get added. Tier 0 holds metadata only. Tiers 1 through 5 hold workload data, running from write-intensive NVMe at Tier 1 down to archival HDD at Tier 5 (VergeOS vSAN documentation).

VergeOS storage tiering, walked through in the UI and from the command line.

Three architectural properties matter more than the tier table itself.

Placement is derived, not looked up. Every block gets a SHA-1 content hash. That hash, run against per-tier device maps stored on Tier 0, deterministically derives where the block’s primary and redundant copies live. No central table records that block X sits on node Y, drive Z, and no controller sits in the write path. Reference counts are not stored persistently either. A background differential process called the vSAN Walk rebuilds them (vSAN Architecture and VergeFS). Reference counting explains a surprise in the fine print, so it is worth remembering.

Each tier is an independent failure and scaling domain. Every tier spans all storage-participating nodes, and redundancy is tracked per tier. A Tier 4 drive failure has no bearing on Tier 1 redundancy, and one tier scales without touching another.

Data placement stays with the administrator. VergeOS does not migrate data between tiers based on access patterns. No policy engine watches heat maps and demotes cold blocks at 2 a.m. Data stays on its provisioned tier until an administrator moves it, and the documentation flags this in a red warning box rather than burying it.

Predictable performance from administrator-controlled storage tiering in VergeOS

That reads like a missing feature to anyone who grew up on array auto-tiering. It is the most defensible design decision in the storage stack. Automated demotion is a policy someone else wrote for a workload that is not yours, and the failure mode arrives at month-end close, when the engine quietly moved the database overnight. The people in a building know things about their data that no access-recency algorithm infers. The documented reasons line up with that: predictable performance, capacity planning that reflects only what an administrator put on a tier, no background storage tiering engine consuming CPU and I/O, and cost modeling that holds still.

There is a fallback for provisioning safety. Every virtual disk carries a preferred tier, and when that exact tier does not exist, VergeOS selects the next less expensive tier, moving to a more expensive one only when no less expensive tier is available (Preferred Tier). Ask for Tier 3 on a system holding Tier 1 and Tier 4, and the disk lands on Tier 4. The system never refuses to provision, which is a safety feature and a trap in equal measure.

Automating placement from the command line

Administrator-controlled placement puts the work on the administrator. The useful discovery in the VergeIO lab is how small that work turns out to be, since tier placement is exposed as a single mutable field with an online migration behind it.

Every test below ran against a live VM on the lab’s second cluster. Snapshot first:

vrg -p homelab2 vm snapshot create test-ubuntu –name pre-tier-test-20260807-1554

Moving a running VM’s disk to a less expensive tier takes one command:

$ time vrg -p homelab2 vm drive update test-ubuntu OS –tier 3 ✓ Updated drive ‘OS’ tier 3 real 0m1.296s

The API acknowledged in 1.3 seconds. Block movement happened in the background, and within 13 seconds Tier 3 had grown by 2.32 GiB, the real thin-provisioned consumption of a 25 GiB disk. The VM stayed running throughout. No downtime, no guest awareness, no reboot.

Provisioning a new disk directly onto an inexpensive tier is also one command, and it hot-plugs into the running VM:

$ vrg -p homelab2 vm drive create test-ubuntu –name bulk-data –size 40GB –tier 3 ✓ Created drive ‘bulk-data’ (key: 13) size_gb 40.0 tier 3

Note the --tier flag. Leaving it off inherits the system default from System, System Settings, Default VM Drive Tier, which on a fresh system is not necessarily the right answer. Being explicit costs nothing.

Reading current placement needs no raw API call:

$ vrg -p homelab2 vm drive list test-ubuntu Key Name Media Interface Size (GB) Tier Enabled 6 OS disk virtio-scsi 25.0 1 Y

Read tier, set tier, create on tier. Three primitives, all non-destructive, all online, all scriptable. A storage tiering policy engine becomes a loop rather than a product.

The tags are the policy

The obvious first instinct is to match on VM names and demote anything called *-archive or *-backup. That instinct is wrong. Name patterns need an ordering, an escape hatch for the VM matching two patterns at once, and a naming convention everyone has to know and nobody can query. VergeOS already ships something better.

Desired placement lives in the platform as tags, and each run of the script reconciles reality to match. The script holds no state of its own. Three commands stand the whole thing up:

vrg tag category create –name storage-policy –single-selection –taggable-vms vrg tag create –name tier-1 –category storage-policy vrg tag create –name tier-3 –category storage-policy

Tagging a workload is one more:

vrg tag assign tier-3 vm my-fileserver

A tier-N tag on a VM means every disk on that VM belongs on tier N. Each run walks the tags in the category, then the VMs carrying each tag, then those VMs’ disks, comparing current placement against the tag and migrating whatever does not match. Reading the intended state back takes one command, and it works whether or not the script has ever run:

$ vrg -p homelab2 tag members tier-1 –type vm Key Type Resource Key Resource Name 1 vm 32

--single-selection on the category is the load-bearing flag. It makes the tags mutually exclusive. Assign tier-1 to a VM already carrying tier-3 and VergeOS silently drops tier-3. That behavior showed up during testing, where retagging one VM emptied the other tag’s member list with no unassign command issued.

One flag turns a pile of rules into a declarative system. A VM cannot hold two contradictory policies, so the conflict becomes impossible rather than merely detected. No precedence logic is needed, since there is never more than one answer. The policy stays queryable outside the script, through the platform’s own UI and API, by people who have never seen the code.

Tags deliberately move nothing on their own. A tag stays inert until the script runs, and untagged VMs are ignored completely, which makes the whole arrangement opt-in per workload rather than something that sweeps a cluster the first time anyone tries it. One caution applies: create tier-N tags only for tiers that exist on that system. Tag a VM tier-5 on a system with no Tier 5 and the script skips it with a warning. That is the right behavior, since the alternative is the preferred-tier fallback quietly placing data somewhere nobody chose.

The reconciler

The result is tier-policy.sh, dry run by default, with --apply to execute:

$ ./tier-policy.sh –profile homelab2 –apply [tier-policy/homelab2] starting (mode=APPLY, category=storage-policy) [tier-policy/homelab2] health gate passed (storage, alarms) [tier-policy/homelab2] tiers present: tier [email protected]%, tier [email protected]% [tier-policy/homelab2] test-ubuntu/OS: tier 1 -> 3 [PLANNED] [tier-policy/homelab2] scanned 1 tagged VM(s), 1 drive(s) need migration [tier-policy/homelab2] creating cloud snapshot ‘tier-policy-20260807-162850’ [tier-policy/homelab2] snapshot created [tier-policy/homelab2] MIGRATED test-ubuntu/OS: 1 -> 3 [tier-policy/homelab2] done: 1 migrated, 0 failed

Thirteen seconds end to end, covering health gate, snapshot, and migration, with the VM running throughout. A second run reports nothing to do, converged.

The gates are where the engineering went, and each one exists in response to something in the mechanics above. A health gate runs vrg doctor --check storage,alarms and aborts on any failure, since shuffling data across an unhealthy vSAN is a bad idea at any scale. A destination-tier existence check skips VMs loudly when a tag names a tier that does not exist, which prevents the preferred-tier fallback from placing archive data on whatever tier it finds. Silent success in the wrong place is worse than a refusal. A capacity gate refuses to migrate into a tier above 85 percent used, since throttling starts at 91 percent. A snapshot envelope takes a cloud snapshot before the first mutation and aborts the run when that snapshot fails.

Two problems cost a debugging cycle each, and both are worth knowing to anyone building something similar. vrg tag members returns an empty resource_name and populates only resource_key, so keys have to be resolved to names separately. And in bash, if ! cmd followed by rc=$? captures the status of the negation rather than the command, which turned a clean exit-10 connection error into a nonsensical “failed (exit 0)”. Run the command bare and capture $? on the next line. That second one is not VergeOS’s fault, and it is exactly the kind of defect that makes an unattended job lie to its owner at 2 a.m.

The script itself is beside the point. The point is that administrator-controlled placement is what makes automated placement tractable. The reconcile logic runs about sixty lines. Everything else is gates, error handling, and comments, which is what a script worth leaving in cron looks like. That ratio stays affordable for one reason. The underlying primitives are three clean commands rather than an API worth fighting. The policy ends up expressed in the platform’s own tagging system, in a language of the administrator’s choosing, on a schedule the administrator sets. The full script is available for download at the end of this post.

What placement below the meter buys

Data reduction accrues to the organization that paid for the drives. VergeOS runs global inline deduplication across the entire storage pool rather than per volume, per array, or per backup job. One metadata model spans the environment, so a block reduced on primary stays reduced downstream, with no boundary to cross and no rehydration on the way. Every implementation scoped to a volume or a job pays for the same block four times, on primary, in the backup, in the replica, and at the DR site.

A raw-capacity meter reads the physical drives and ignores all of it. The meter counts what an organization bought, not what its workloads believe they have, and the gap between those two numbers is the storage engine’s entire contribution. Under per-node licensing that gap belongs to the customer. Reduction ratios vary enormously by dataset, and any vendor quoting one without naming the workload behind it is selling a number rather than reporting one. The architectural point survives without a figure. Whatever the ratio turns out to be, the licensing model decides who captures it. The section below covers how to measure it on real data rather than trusting anyone’s headline.

Raw capacity is a poor proxy for delivered value, in both directions. Redundancy overhead measured consistently at roughly 2.15x across every tier in the VergeIO lab. The second cluster’s Tier 3 shows 2,400 GB raw against 1,115.77 GB usable. Its Tier 1 shows 768 GB raw against 356.04 GB usable. The primary cluster’s Tier 1 shows 6,000 GB raw against 2,791.65 GB usable. That is N+1, the default, keeping two copies of every block (redundancy models). N+2 runs closer to 3x.

That overhead is arithmetic rather than a licensing complaint, and it applies to VergeOS exactly as it applies to everyone else. Two copies of a block cost twice as much as one copy regardless of who wrote the storage engine. The narrower point concerns the metric. Raw capacity, the number a capacity meter counts, sits at roughly 2.15x what an administrator can provision against and a small fraction of what the workloads think they have. It overstates what is usable and understates what is served, which means it is not measuring storage at all. It is measuring drives.

Thin provisioning stops being a negotiation. The lab’s primary cluster reports 40,062 GB allocated against 2,791 GB usable, more than fourteen times its usable capacity in allocated virtual disk. That figure belongs to a lab bench, and a disciplined production environment should not run anywhere near it. The direction holds at any scale. Over-allocation is free under per-node licensing, and the documentation recommends provisioning generously rather than expanding later. On a capacity-metered platform, generous provisioning turns into a budget conversation with a procurement officer.

Mixed hardware becomes a design input rather than a liability. Storage tiering is what lets an administrator deliberately put the file server on second-life SATA and the database on NVMe, inside one cluster, under one license. The lab’s primary cluster currently holds two 12 TB HGST He12 drives and a 2 TB Micron SSD sitting unassigned, reported by the API at tier -1 with zero vSAN capacity. That is 26 TB of idle hardware available as Tier 4 and Tier 5 tomorrow at zero licensing cost. On a capacity-metered platform, adding 24 TB of raw HDD starts with a purchase order and a permission slip. The lab version of this is drives already on the shelf. The production version is the one Saratoga ran, where the same property means buying capacity on the open market instead of from a hypervisor vendor.

Failure domains stay separate. Each tier tracks redundancy independently, so a failure among the second-life Tier 3 SSDs cannot compromise Tier 1. That is what makes mixing media classes a calculated decision rather than a gamble. The blast radius of the less expensive hardware stays bounded by design, and bounded to the tier holding the lower-priority data.

This matters more in 2026 than it did in 2024. Eighty-three percent of the organizations in the Omdia study plan to run their arrays past historical utilization before refreshing. Extending hardware life, running fuller, and buying used are all rational responses to component pricing, and together they describe a market deliberately raising its own failure rate at the moment spare hardware became unaffordable. Tier-level failure isolation is one of the few answers to that condition that does not begin with buying something.

Key Terms
Storage tier
One of six drive groupings in the VergeOS vSAN storage tiering model, numbered 0 through 5, assigned at the drive level. Tier 0 holds metadata only. Tiers 1 through 5 hold workload data, running from write-intensive NVMe down to archival HDD.
Preferred tier
The tier a virtual disk requests. When that exact tier does not exist, VergeOS places the disk on the next less expensive tier, moving to a more expensive one only when no less expensive tier is available.
vSAN Walk
The background differential process that rebuilds block reference counts. Blocks reaching zero references wait roughly ten walks, about seventy seconds, before becoming eligible for reclamation.
Raw, usable, and logical capacity
Raw is the physical drive total and the number a capacity meter bills. Usable is what remains after redundancy, roughly raw divided by 2.15 at N+1. Logical is what the workloads believe they have after data reduction.

The fine print

Migrating off a tier does not return the capacity, and snapshot retention decides when it does. This is the finding that surprised the lab most, and the first explanation was wrong in a useful way.

Moving that 25 GiB disk from Tier 1 to Tier 3 grew Tier 3 by 2.32 GiB within seconds, and Tier 1 did not shrink at all. Eleven minutes of watching produced 41.2 GiB before and 41.2 GiB after. The vSAN Walk looked like the obvious culprit, and the documentation rules it out. Blocks reaching zero references wait roughly ten walks, about seventy seconds, before becoming eligible for reclamation. Eleven minutes is nine times that window.

The real gate is reference counting. A snapshot references blocks rather than copying them, and blocks referenced by a snapshot are retained after the live object stops pointing at them (vSAN Architecture and VergeFS). The count has to reach zero first, and it never did. That system carried a midnight system snapshot, hourly snapshots on a three-hour cycle, and a manual snapshot taken half an hour earlier, all still pointing at those blocks in their Tier 1 locations. The snapshot taken for safety before the migration is part of what stopped the space coming back. Taking it was still correct. It has a cost, and this is the cost.

The planning rule is sharper than patience. Reclamation on the source tier is gated by the longest-lived snapshot still referencing that data. Midnight snapshots on this cluster retain for three days, so evacuating a workload buys nothing measurable on Tier 1 until those age out. Anyone demoting data to relieve a full tier should read their retention schedule first, since that schedule is the actual timeline and it is measured in days.

A pleasant corollary follows from the same mechanism. Moving the disk back to Tier 1 was instantaneous and consumed no new Tier 1 capacity, for the same reason. The snapshots still held those blocks in place. Round-tripping costs almost nothing. One-way evacuation is the slow direction, and seasonal workloads that migrate down and back are the best fit for how this behaves.

Measure the reduction ratio from the API rather than a summary field. The authoritative per-tier numbers are used, physical bytes committed, and used_inflated, logical bytes stored, both in the storage_tiers table. Dividing one by the other produces the real reduction for that tier on real data, which is worth wiring into existing capacity reporting:

curl -ks -H “Authorization: Bearer $KEY” “$HOST/api/v4/storage_tiers?fields=all” \ | python3 -c ” import sys,json G=1024**3 for t in json.load(sys.stdin): u,ui=t.get(‘used’,0),t.get(‘used_inflated’,0) print(f\”tier {t[‘tier’]}: {u/G:.1f} GiB physical, {ui/G:.1f} GiB logical, {ui/u:.2f}x\”)”

Two cautions apply to the result. A lab estate full of VMs cloned from one golden template produces a flattering number that no production estate will match, so measure against real data before modeling with it. And do not add a compression multiplier on top of that ratio. VergeOS does not compress data at rest. Compression applies only during site-sync replication, to save WAN bandwidth between sites, and the number above already reflects everything happening locally.

Get the drive layout right at install, since both halves of it are painful to change later. Two rules carry most of the weight.

The first concerns Tier 0. It holds metadata only, explicitly not a cache, and no workload data. Sizing guidance is 5 GB per TB of usable storage minimum and 10 GB per TB recommended, on enterprise NVMe rated 3 DWPD or equivalent, with 30 percent free space maintained. Consumer NVMe is not supported for it in production. Neither lab cluster has a Tier 0 at all, so nothing here should be read as guidance on Tier 0 behavior under load. Tier 0 is normally configured at install time. The documented procedure for adding it afterward carries a hard warning that only qualified VergeOS engineers, or an administrator under direct support guidance, should perform it. Selected devices get formatted, and a wrong device path causes serious damage.

The second concerns homogeneity. All drives within a tier should match in type, capacity, and performance, and a tier can only use the capacity of its smallest drive, so one undersized drive silently caps the whole tier. Each node should also carry the same number of drives per tier. The lab’s primary cluster demonstrates the failure mode. A 2 TB Micron sits assigned to Tier 3 on exactly one node, Tier 3 does not appear in vrg storage list at all, and tier_count reads 1. A tier that cannot satisfy cross-node redundancy is not a tier anyone can use.

Know where the throttling cliffs sit. Below 91 percent is normal operation. Between 91 and 95 percent, low-space throttling adds 10ms of latency. At 96 percent and above, critical throttling adds 50ms (Diagnostics Toolkit). Target free space is 30 percent or more on Tier 0, 20 to 30 percent on Tiers 1 through 3, and 15 to 20 percent on Tiers 4 and 5. Any automated placement policy should treat those as hard gates rather than advice.

Second-life media needs a monitoring discipline, and one organization’s risk calculus is not another’s. Quality used enterprise drives are a legitimate way to build a capacity tier, and they arrive with less runway than new ones, so SMART and wear telemetry become something to watch rather than background noise. vrg doctor surfaces drive health as a first-class check, and running it on a schedule beats running it once suspicion sets in. Replacement planning matters too, since a swap requires the node in maintenance mode with only one repair running per tier at a time. Weigh the strategy against real consequences. A lab accepts older media on a capacity tier, since the worst realistic outcome there is a rebuilt test cluster. Put a customer-facing workload, a recovery point objective, and a support contract behind it and the acceptable age and condition of that hardware changes completely. That difference is precisely why Saratoga bought warrantied refurbished gear and a lab bench does not have to.

Three nodes and two VMs is not a load test. The lab’s second cluster ran two VMs during the tier migration, and both clusters sit under 27 percent tier utilization. What got measured is that migration is online and non-disruptive at that scale. What did not get measured is what a storage tiering migration does to latency on a busy cluster, what happens when fifty disks demote at once, and how the vSAN Walk behaves under sustained write pressure. Anyone planning bulk tier movement in production should assume those answers exist and go find them before trusting a 1.3-second acknowledgment to mean anything about their environment.

What this adds up to

Pick tiers explicitly at provisioning time, every time. The --tier flag costs six characters and saves a migration. The preferred-tier fallback places every disk somewhere, which is a safety feature and a footgun in equal measure. A disk nobody thought about lands on whatever the system default happens to be, and nobody notices until it becomes a performance ticket.

Automate the storage tiering decisions VergeOS deliberately leaves to the administrator. A tag category, four gates, and a reconcile loop produce declarative tier placement with logging and a snapshot envelope, all of it auditable, versionable, and owned by the organization running it. It took an afternoon and fits in one file. That is the compounding advantage of a platform with a clean CLI. Capabilities that otherwise wait on a vendor’s roadmap become things an administrator assembles, and the policy ends up living in the platform’s own tagging system rather than buried in code.

Model capacity in three numbers rather than one. Raw, usable at roughly raw divided by 2.15 at N+1, and logical at usable multiplied by a measured reduction ratio from real data. Each number answers a different question, and they are not interchangeable. Raw is what an organization bought and what a capacity meter bills. Usable is what an administrator can provision against once redundancy takes its cut. Logical is what the workloads believe they have. Bringing the wrong one to a capacity conversation produces an error of an order of magnitude in whichever direction is least convenient.

Saratoga’s $50,000 a year was never an array-maintenance line item in any meaningful sense. It was the price of keeping data placement inside a box that charged rent for the privilege. Storage tiering never needed to live in a dedicated array. It needed to live somewhere that was not metering the drives underneath it.

A lab cannot prove that at Saratoga’s scale, and it does not need to. What a lab proves is whether the mechanism is real before anyone bets a data center on it. Is the tier field genuinely just a field. Is the migration genuinely online. Does the efficiency genuinely accrue to the organization that bought the hardware. All three held up. The rest is a procurement decision made by people with more at stake, and the useful thing to carry into that decision is what the lab found. The inexpensive tier and the fast tier are the same system, under the same license, one command apart.

Download tier-policy.sh

The tag-driven storage tiering reconciler described above. 282 lines of bash, requiring vrg, python3 3.11 or later, and coreutils timeout. It runs as a dry run by default, with --apply to execute. Configuration instructions live in the header comment.

Download the script (.zip) tier-policy.sh · bash · dry run by default

Live Webinar · August 20

The Great Enterprise Storage Squeeze

Simon Robinson, Principal Analyst at Omdia, joins VergeIO on August 20 at 12:00 PM ET to walk through the study behind the numbers in this post, covering what 400 IT buyers reported about component pricing, refresh deferral, and where software-defined storage landed on their shortlists.

Register for the session

Raw-capacity metered licensing versus per-node licensing

 Raw-capacity metered licenseVergeOS per-node license
What the license countsPhysical drive capacity, before any data reductionNodes, tied to a System ID rather than hardware
Who captures data reductionThe vendor, since the meter reads the drivesThe customer, since the drives are not a line item
Adding a capacity tierA purchase order plus a licensing add-onAssign existing drives to a tier at no licensing cost
Mixing media classesConstrained by a vendor compatibility listMixed drive types, capacities, and server generations
Using quality used enterprise drivesMetered identically to new drives of the same sizeMetered not at all
Changing tier placementDepends on array capability and licensed capacity headroomOne command, online, with the workload running
Frequently Asked Questions
Does VergeOS storage tiering move data between tiers automatically based on access patterns?
No. Data stays on its provisioned tier until an administrator moves it. Automated demotion is a policy written by a vendor for a workload that is not yours, and the failure mode arrives when the engine demotes a dataset the night before someone needs it. Administrator-controlled storage tiering is a design decision rather than a gap, and the CLI makes automating it a short exercise.
Does moving a virtual disk between tiers require downtime?
No. The API acknowledged a tier change in 1.3 seconds in lab testing, block movement completed in the background within 13 seconds for a 25 GiB thin-provisioned disk, and the VM stayed running throughout with no guest awareness and no reboot.
Why did the source tier not free up space after migration?
Snapshots reference blocks rather than copying them, and referenced blocks are retained after the live object stops pointing at them. Reclamation waits for the reference count to reach zero, which means the longest-lived snapshot still referencing that data sets the timeline. Check retention schedules before planning capacity recovery around a migration.
Can VergeOS run on quality used enterprise hardware?
VergeOS runs on standard enterprise servers and supports mixing drive types, capacities, and server generations within its documented requirements. Enterprise-grade components are required. Consumer-grade disks and consumer or off-brand network cards are not supported, and any specific configuration should be validated before it appears on a quote.
What reduction ratio should an organization plan for?
Measure it rather than inherit it. The authoritative per-tier numbers are used and used_inflated in the storage_tiers table, and dividing one by the other produces the real ratio for real data. Lab estates built from cloned templates produce flattering numbers that heterogeneous production data will not match.

Filed Under: Storage Tagged With: Alternative, HCI, IT infrastructure, VMware

April 22, 2026 by George Crump

For most IT organizations, the VMware server upgrade conversation arrives at the same time as the renewal decision. Broadcom’s per-core subscriptions drove 300–500% VMware cost increases, turning a technology preference into a financial emergency. But migrations take time, and the working plan for many organizations has been sensible: renew for one more year, buy the servers needed to keep the environment running, and use that window to evaluate alternatives properly.

Now is the worst time to renew VMware and buy new serversThat plan made sense in 2024. The renewal was expensive but predictable — Broadcom had only completed the acquisition a year earlier, many organizations still had time remaining on existing contracts, and buying one more year to evaluate alternatives was a reasonable call. The servers were a known quantity. The budget math was uncomfortable but manageable. What changed is not the plan — it is the price of executing it. The two line items that seemed controllable have both moved against you at the same time, and the combined number no longer looks like buying time. It looks like paying a premium to stay on a platform you have already decided to leave.
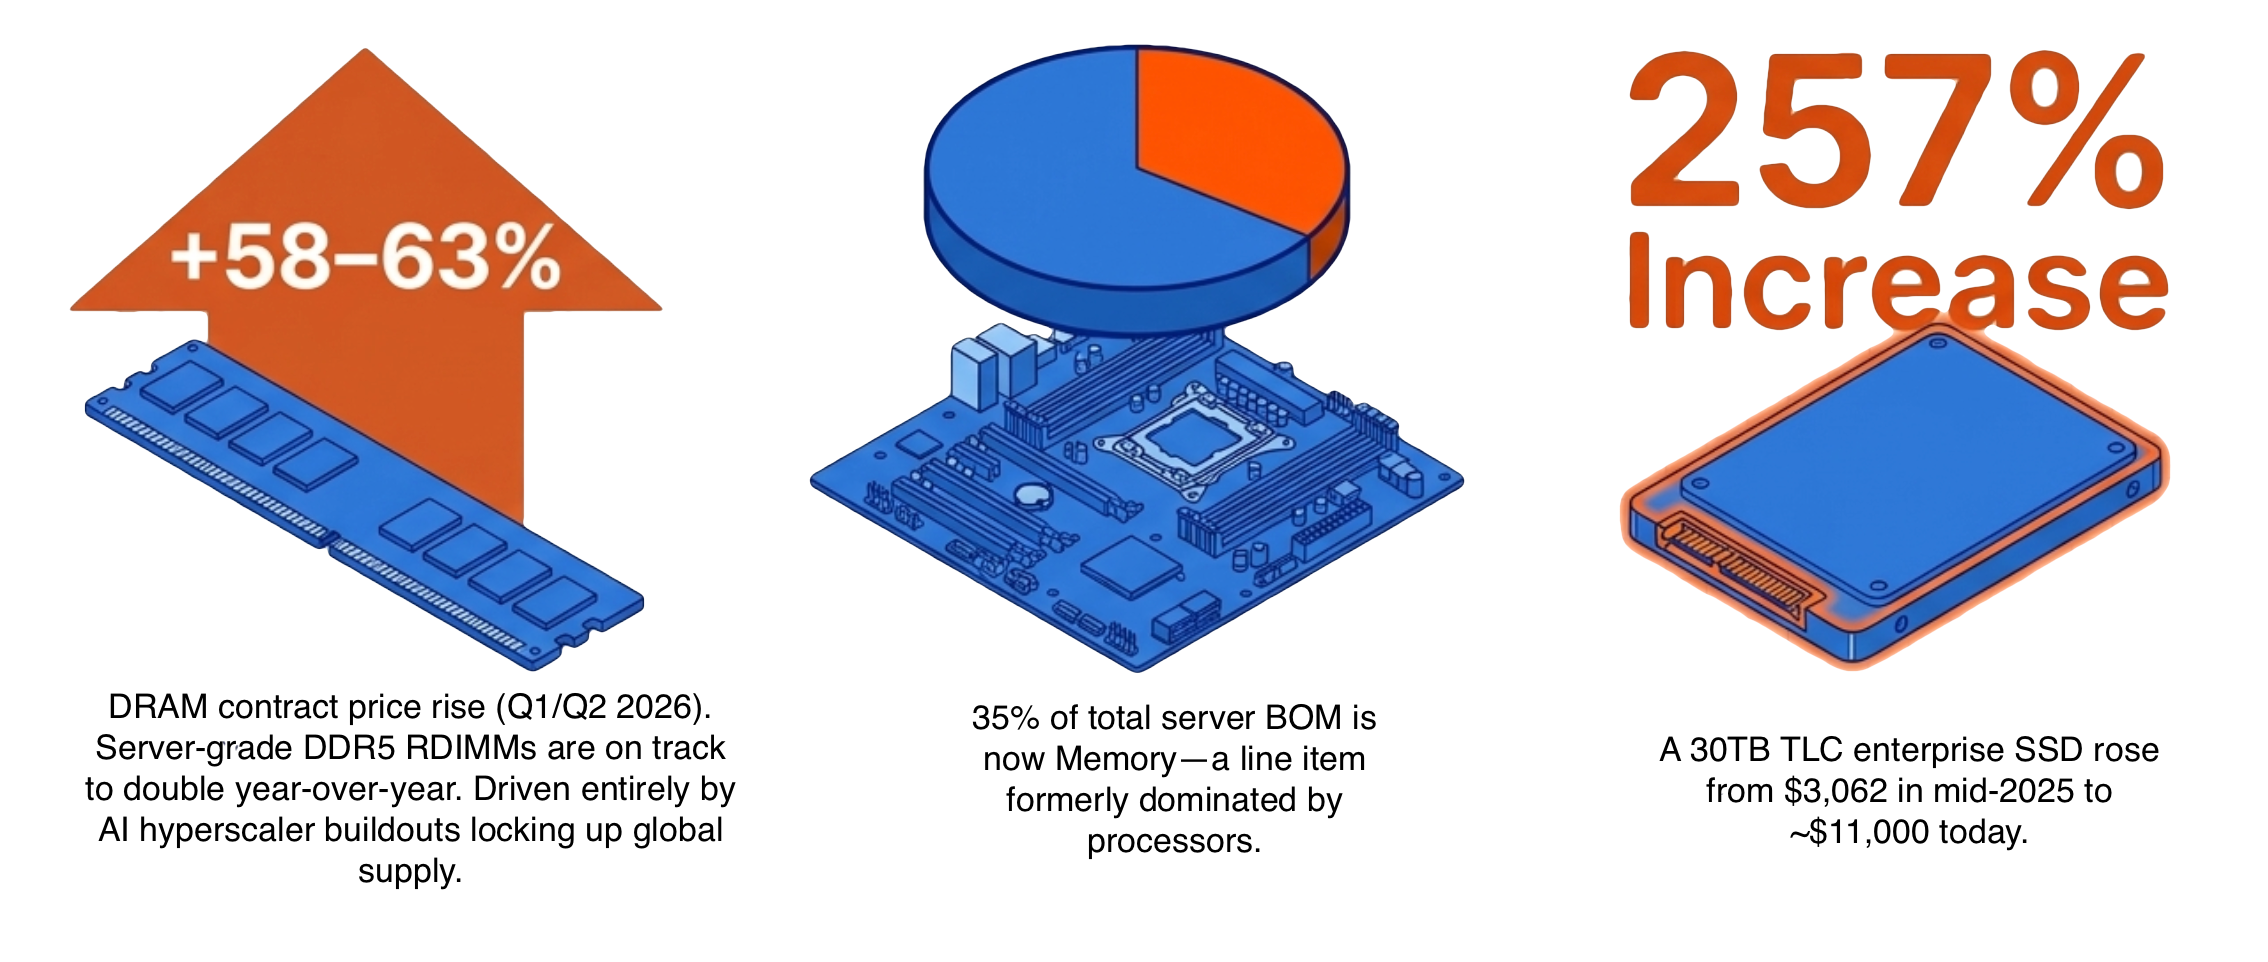
Key Takeaways
Broadcom’s per-core subscriptions drove 300–500% VMware cost increases. The exit decision is made for most organizations — the question is the cost of execution.
Server-grade DDR5 RDIMMs are on track to double year over year by late 2026. Memory now represents 35% of total server BOM cost — the largest single line item in a build that used to be dominated by processors.
A 30TB TLC enterprise SSD that cost $3,062 in mid-2025 now costs nearly $11,000 — a 257% increase in under a year.
Renewing VMware and buying servers simultaneously means paying peak prices on both at exactly the same moment.
Server lead times of 3–6 months mean hardware ordered at month four of a one-year extension may not arrive before the next renewal conversation begins.
VergeOS starts the migration on existing hardware — eliminating the hardware purchase, the lead time risk, and the VMware subscription simultaneously.
VergeOS runs at 2–3% memory overhead vs. double-digit percentages for VMware — the same servers run more workloads after the migration completes.

Why VMware Server Upgrade Costs Have Changed

VMware server upgrade costs rising alongside Broadcom licensing fees in 2026The server market shifted in late 2024 and has not corrected. DRAM contract prices rose 58–63% quarter over quarter in the first half of 2026, driven by AI infrastructure buildout at the hyperscaler level that locked up supply before enterprise buyers could compete. This cycle has been characterized as a Memory and Flash Supercycle — a structural market shift projected to persist well beyond 2027, not a temporary correction. Server-grade DDR5 RDIMMs are on track to double year over year by late 2026. Memory now represents 35% of total server BOM cost, a line item that used to be dominated by processors.
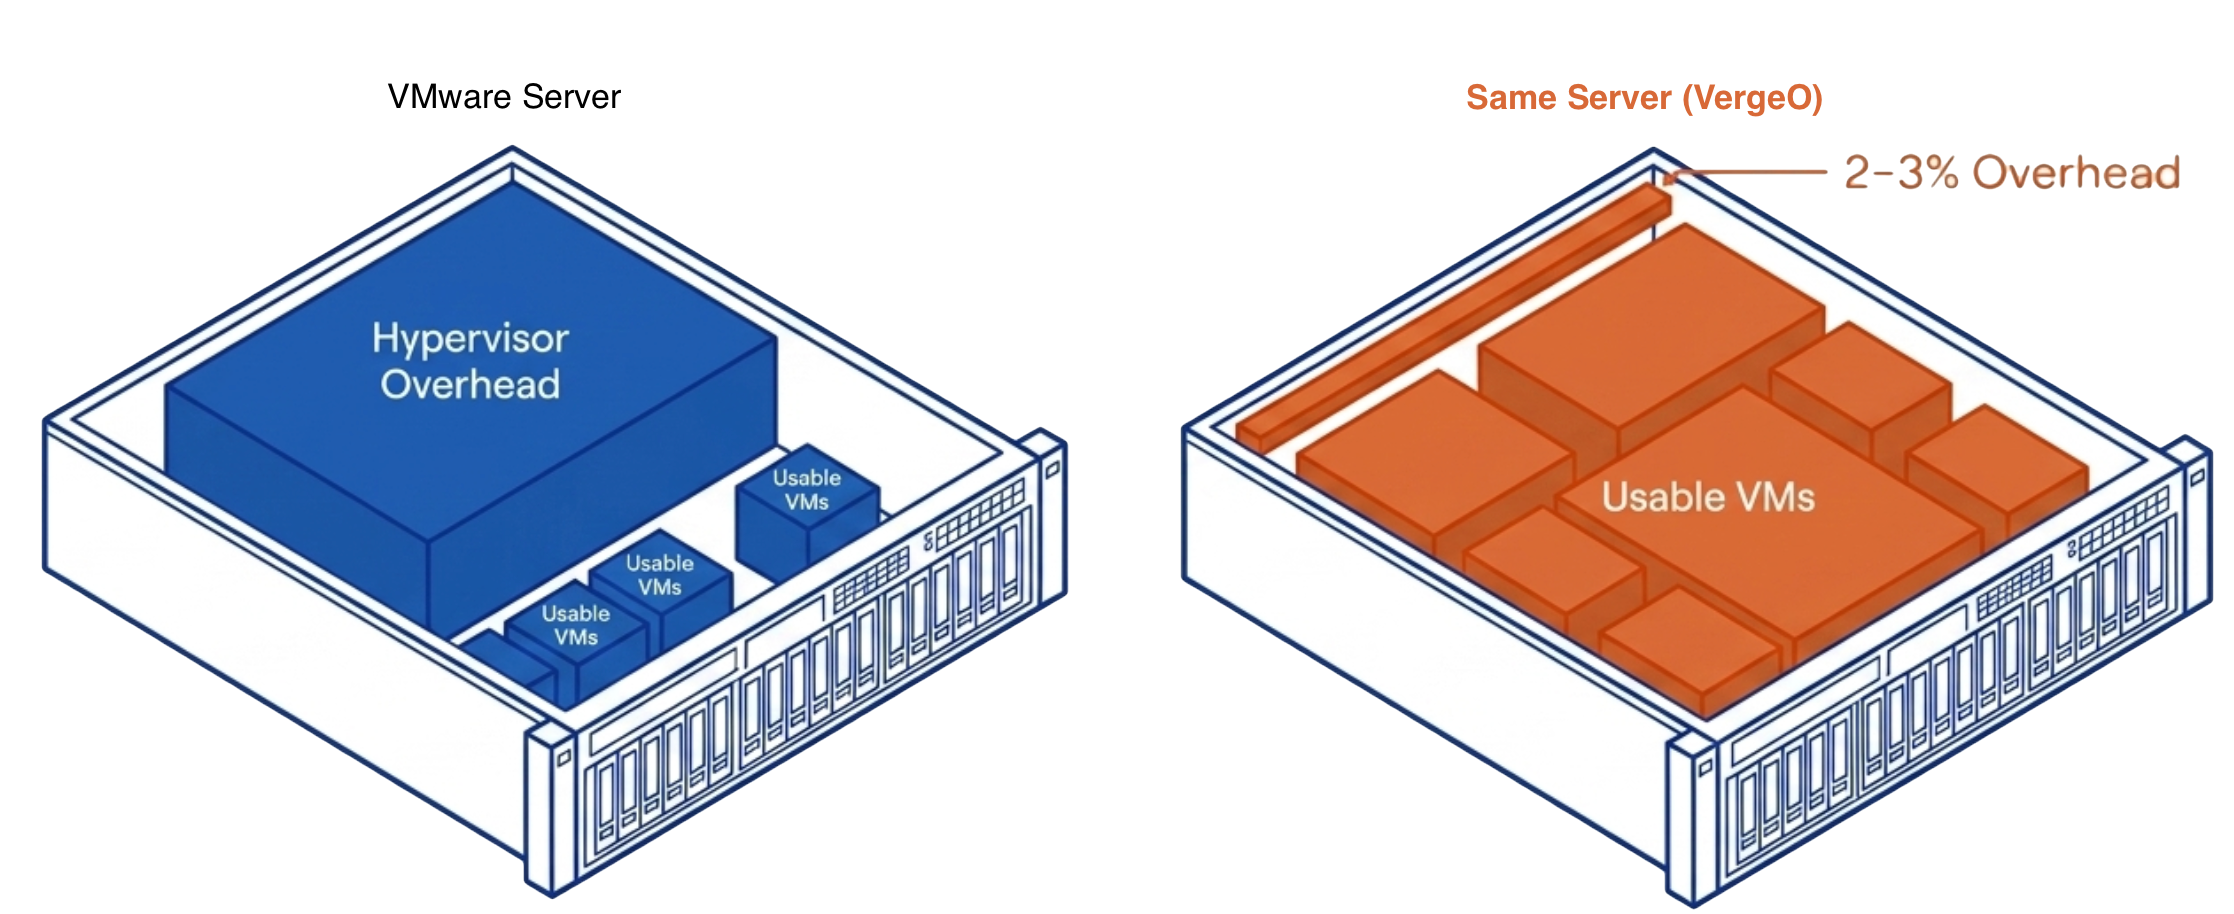
Enterprise SSD pricing compounded the problem. A 30TB TLC enterprise SSD that cost $3,062 in mid-2025 now costs nearly $11,000 — a 257% increase in under a year. For organizations that planned a server refresh at 2024 pricing, the storage bill alone can flip a manageable capital project into a budget conversation that goes back to the CFO. And unlike the licensing increase, which arrived as a known policy change, the hardware inflation arrived quietly — embedded in quotes that came back higher than expected, with OEM validity windows shrinking from thirty days to fifteen. The price you get today expires before your purchase order clears.

Key Terms
Per-Core Subscription

Broadcom’s VMware licensing model that charges based on the number of processor cores in use, replacing perpetual licenses. Drove 300–500% cost increases for most organizations after the acquisition closed.

DDR5 RDIMM

Registered Dual In-Line Memory Module using the DDR5 standard — the server-grade RAM required by modern virtualization hosts. Contract prices are on track to double year over year by late 2026, driven by AI infrastructure demand at the hyperscaler level.

BOM (Bill of Materials)

The itemized cost breakdown of all components in a server build. Memory now represents 35% of total server BOM cost in 2026 — the largest single line item, a position historically held by processors.

Platform Overhead

The memory and compute resources consumed by the hypervisor stack itself before any workload runs. VMware runs at double-digit percentages. VergeOS runs at 2–3%, returning the difference to productive workloads on the same physical hardware.

Global Deduplication

VergeOS’s storage architecture that holds only unique data blocks across all VMs and all nodes, delivering significantly more effective capacity from the storage organizations already own.

The Compounding Trap

Here is where the two costs stop being separate line items. The Broadcom per-core subscription is running at elevated rates with annual escalation baked in. The servers are running at elevated prices with no correction in sight.

The organization that decides to renew VMware for one more year and buy a few servers to bridge the gap is making two purchases simultaneously — at the worst possible time for both.
TruthInIT Webinar
The New Economics of VMware Exit

George Crump and Mike Matchett unpack the full cost equation — the hardware ambush, the license squeeze, and why VergeOS changes the math. Live Q&A included.

Register Now →

The budget that was approved to buy evaluation time is now funding a premium VMware environment on hardware that costs twice what the CFO expected when the plan was signed off. Neither purchase is optional — the environment needs to keep running, and the servers are needed to run it. The combined spend is no longer a bridge to a better decision. It is the cost of not having made the decision sooner.

The compounding works against you in a third way that rarely appears in the analysis. Every month inside that one-year extension is a month the organization is not migrating. Server lead times of three to six months mean that even if the decision to exit comes at month four of the extension, hardware ordered then may not arrive until the extension is nearly over — triggering a second renewal conversation before the first one has paid off. The organization that bought time to evaluate alternatives ends up buying time to buy more time. Each cycle runs at current pricing.

The VMware Exit That Costs Less Than the Renewal

VergeOS migration starting on existing infrastructure without new VMware server purchasesVergeOS changes the math at every layer where the conventional path breaks down. The starting point is hardware: VergeOS installs on any x86 server already in the data center. The servers the organization was planning to buy are no longer required. The $40,000 nodes, the three-to-six-month lead times, the OEM quote that expires before the purchase order clears — none of that applies. The migration starts on the day the organization decides to move, on hardware already powered on and already running workloads.
The VMware subscription disappears on day one. That eliminates the compounding trap — there is no renewal to sign, no escalation clause to absorb, and no ongoing Broadcom billing cycle running while the migration proceeds. For an organization paying $30,000 per month in VMware subscription fees, eliminating even six months of that cost covers a significant portion of the migration project itself.

VergeOS does more than start the migration on existing hardware — it makes that hardware perform better than it did under VMware. The entire VergeOS stack runs at 2–3% memory overhead versus double-digit percentages for VMware. That overhead gap translates directly into workload capacity: the same physical servers run more VMs, with more memory available to the workloads that matter. VergeOS storage is globally deduplicated across all VMs and all nodes, which means the flash capacity the organization already owns works significantly harder. Customers consistently find greater storage efficiencies through VergeOS deduplication than they achieved on VMware — the same drives, more effective capacity. The servers that were already paid for become better servers on the day the migration completes.

Make the Decision You Have Already Made

2×
Server-grade DDR5 RDIMMs on track to double year over year by late 2026
257%
Enterprise SSD price increase — 30TB TLC drive from $3,062 to ~$11,000 in under a year
3–6 mo
Server lead times in many regions — hardware ordered today may arrive after next renewal

The VMware exit is not a question most IT organizations are still debating. The question is when, and how much the delay costs. Every month inside a renewed VMware contract is a month of Broadcom billing at elevated per-core rates. Every month that passes is another month closer to needing those servers — at whatever price they quote when the order finally goes in.

The organizations finishing their VMware exits in 2026 are not the ones that found a better renewal deal or waited for server prices to correct. They are the ones that recognized the exit itself was the lower-cost option — and that VergeOS made it possible to start on hardware already in the data center, eliminate the subscription on day one, and come out the other side running more workloads on less memory than VMware ever delivered. The math on staying has never been worse. The math on leaving has never been more in favor of moving now.

Renewing VMware vs. Migrating to VergeOS: The 2026 Cost Comparison

  Renew VMware + Buy Servers Migrate to VergeOS
Hardware cost$40K nodes at peak pricing — when availableStart on existing hardware today
Server lead time3–6 months before migration can beginZero — migration starts immediately
VMware subscriptionFull renewal at elevated per-core rateEliminated on day one
Annual escalationBaked into new contract termGone entirely
RAM utilizationDouble-digit platform overhead unchanged2–3% overhead — more workloads, same servers
Storage efficiencyNo change from existing VMware environmentGlobal deduplication — existing drives work harder
Migration timelineStarts after hardware arrivesStarts the day the decision is made

Join George Crump and Mike Matchett on April 30 for The New Economics of VMware Exit — a live TruthInIT webinar unpacking the full cost equation and the path forward. Register for the webinar.

For the complete TCO model and four-step business case, download the white paper: The New Economics of the VMware Exit.

Ready to see VergeOS running on your existing infrastructure? Take a Test Drive Today.

Frequently Asked Questions
Why have VMware server upgrade costs increased so much in 2026?
AI infrastructure buildout at the hyperscaler level has locked up DRAM and NAND flash supply before enterprise buyers can compete for it. Server-grade DDR5 RDIMMs are on track to double year over year by late 2026. A 30TB TLC enterprise SSD that cost $3,062 in mid-2025 now costs nearly $11,000. Memory now represents 35% of total server BOM cost — the largest single line item in a build that used to be dominated by processors.
Does VergeOS require new hardware to migrate from VMware?
VergeOS installs on any x86 server already in the data center. There are no hardware compatibility lists requiring certified configurations. The migration starts on existing infrastructure — no procurement cycle, no lead time exposure, and no repricing risk between project approval and purchase order.
How does VergeOS make existing servers perform better than VMware?
The entire VergeOS stack — hypervisor, storage, networking, and data protection — runs at 2–3% memory overhead versus double-digit percentages for VMware. That gap returns directly to workload capacity: the same physical servers run more VMs with more memory available. VergeOS storage is also globally deduplicated across all VMs and all nodes, delivering significantly more effective capacity from the flash storage organizations already own.
Will VMware server prices come down before I need to buy?
Industry forecasts indicate memory shortages will persist through at least Q4 2027, with new manufacturing capacity not coming online until 2027–2028. Organizations waiting for prices to normalize before proceeding with a conventional migration are likely to wait through multiple VMware renewal cycles at current Broadcom rates.
What happens to the servers we were planning to buy for VMware?
The servers the organization was planning to purchase are no longer required for the VergeOS migration. If additional capacity is needed in the future, VergeOS runs on any x86 server from any manufacturer and incorporates new nodes without downtime. The migration itself starts on hardware already in place, at zero new hardware cost.
How long does a VergeOS migration from VMware take?
VergeOS migrations are software-driven and measured in weeks rather than months. Because there is no hardware procurement dependency, the timeline is not gated by server lead times. VergeOS snap-based import brings VMware VMs across as-is, eliminating the conversion step that adds cost and risk to every other exit path.

Filed Under: VMwareExit Tagged With: Alternative, HCI, IT infrastructure, VMware

November 12, 2025 by George Crump

Extending server longevity requires more than maintaining software compatibility, yet most virtualization and infrastructure software vendors don’t offer even that. Instead, they end hardware support after 4 or 5 years, long before the server has outlived its usefulness. This short timeline reflects how quickly software requirements outpace the systems they run on, not hardware failure or performance degradation. The result is a predictable refresh cycle that replaces hardware long before its physical limits are reached.

Compatibility alone does not keep older servers productive. Running software on legacy hardware is not the same as running it well. Performance declines with every new release. Component wear translates directly into downtime risk.

Extending server longevity demands infrastructure software that runs efficiently on existing hardware, delivering consistent performance without additional resources. It also requires protection that keeps applications and data available as servers age. VergeOS was built on that principle.

Why Vendors Don’t Prioritize Extending Server Longevity

Most virtualization and infrastructure platforms are not designed with extending server longevity as a core goal. Their architecture and development model make it difficult to maintain performance and reliability as hardware ages. Over time, this leads to the familiar four- to five-year refresh cycle that defines enterprise IT planning.

Watch Now

Traditional virtualization software is built from multiple independent layers: a hypervisor, a virtual storage engine, a network virtualization component, and a management framework. Each layer consumes CPU cycles, memory, and I/O bandwidth. Vendors add new features by introducing additional modules that must interact with the existing management layer and hypervisor. Each module introduces its own background services and control processes. With every update, the total resource requirement grows.

The hardware does not inherently become obsolete. The software demands more. A version upgrade that improves functionality also increases CPU utilization and memory consumption. What begins as a minor performance reduction compounds over time until older servers cannot keep up. Replacement becomes the practical response.

This pattern does not stem from neglect or deliberate obsolescence. It is the natural outcome of building large, modular software that continues to expand. Features accumulate, interdependencies multiply, and the software relies on newer hardware generations to maintain responsiveness. The model favors innovation speed and feature breadth at the expense of long-term hardware usability.

VergeOS approaches infrastructure differently. By integrating compute, storage, and networking into a single codebase, the platform eliminates redundant modules and interprocess communication that drain resources in traditional architectures. New features are built directly into the existing framework, maintaining performance instead of eroding it.

Servers continue to perform well, stay reliable, and remain part of the production environment long after other platforms declare them outdated.

Extracting Modern Performance from Existing Hardware

Extending server longevity depends as much on software design as it does on hardware reliability. The physical systems inside a data center have far more capability than the software running on them fully uses. The limiting factor isn’t the hardware. It’s the architectural overhead introduced by complex, multi-layer virtualization stacks.

Each software layer adds its own control processes, scheduling mechanisms, and data translation routines. Over time, these layers stack up like filters, each one slowing the flow of compute and I/O. Hardware performance appears to decline when the underlying components are perfectly capable. The system is working harder to do the same amount of work.

VergeOS runs compute, storage, networking, and AI in a single, unified code base. There are no redundant services or handoffs between independent modules. Every operation travels the shortest possible path through the system. This design reduces CPU utilization, shortens I/O latency, and improves cache efficiency.

The platform restores balance between what hardware does and what the software allows it to do. By removing unnecessary translation layers, older servers run workloads at modern performance levels. Environments that once struggled with overhead-heavy hypervisors see measurable performance improvements simply by switching to a unified infrastructure model.

VergeOS customers exiting VMware report not only continuing to use their existing servers but also repurposing systems that VMware had already deprecated. These customers keep servers in production for eight to ten years, well beyond the typical refresh cycle, maintaining consistent performance and reliability.

Artificial Intelligence as an Example

Most vendors are adding AI as a set of external modules that sit on top of their existing stack. Each new layer brings its own management and resource overhead, increasing complexity and accelerating hardware refresh cycles.

VergeOS integrates AI directly. It includes AI as a service, built into the infrastructure operating system. The feature appears and activates with a toggle: no new layers, no extra configuration, and no performance penalty. Older servers contribute to AI initiatives by hosting GPUs or supporting complementary workloads. This design keeps infrastructure simple and extends the usefulness of servers into the AI era.

Overcoming Hardware Aging Through Software Design

Fans, power supplies, and storage devices wear out over time. Traditional virtualization platforms treat these events as interruptions, forcing downtime for replacement or triggering complex failover procedures that require external tools. VergeOS treats protection as an inherent part of its design, not a separate feature.

The platform continuously monitors every system component, watching for early indicators of degradation: rising temperatures, increased I/O latency, or power fluctuations. When it detects a potential issue, it alerts administrators long before the problem becomes critical. Maintenance happens during normal operations rather than during an emergency outage.

If a component fails unexpectedly, VergeOS isolates the affected node and automatically redistributes workloads across healthy servers in the instance. Using ioOptimize, it distributes those workloads intelligently to deliver the best possible performance with the remaining resources. Applications and data remain online without impacting performance. Users experience no interruption. VergeOS’s single-codebase architecture enables instant coordination of recovery operations without external orchestration or third-party clustering tools.

Protection extends beyond simple fault tolerance. The platform guards data using synchronous replication, also known as mirroring. This method provides immediate, real-time protection by maintaining identical copies of data across nodes. It introduces far less overhead than erasure coding or RAID and delivers high performance and low latency. VergeOS incorporates infrastructure-wide deduplication, which significantly reduces the capacity impact of mirroring.

When combined with ioGuardian, protection extends even further. The feature creates a third copy of critical data without the high cost of traditional three-way mirrors or a replication factor of 3. The result is superior data integrity and availability that goes beyond a three-way mirror at lower cost and without added infrastructure complexity.

These capabilities are part of VergeOS’s architectural foundation, not layered add-ons. All this protection comes included at no additional cost. VergeOS was designed with safety in mind from the start. By embedding it into the platform’s foundation, the need for add-on licensing or external recovery tools disappears. Every environment, regardless of size, has the same level of protection and availability.

Hardware aging no longer dictates risk. Servers reaching the end of their expected lifespan keep workloads running and data protected. This approach transforms hardware from a potential single point of failure into a flexible resource pool that evolves gracefully over time.

Conclusion: Redefining Modernization Through Extending Server Longevity

Most organizations are facing an infrastructure modernization problem; they are forced to update their infrastructure due to VMware upheaval and to support new workloads like AI. But modernization need not come at the expense of existing hardware. The right software delivers modernization and extends hardware life.

VergeOS customers experience measurable, lasting value. They routinely extend refresh cycles, reduce capital expenses, and keep servers in production for 8 to 10 years while maintaining full performance and reliability. Many also repurpose previously deprecated systems to support new workloads, from edge environments to AI infrastructure. These outcomes redefine modernization—proving that progress is not about replacement, but about achieving sustained capability and long-term return on investment.

Filed Under: Virtualization Tagged With: Alternative, HCI, Hyperconverged, IT infrastructure, UCI, VMware

  • Page 1
  • Page 2
  • Page 3
  • Interim pages omitted …
  • Page 5
  • Go to Next Page »

855-855-8300

Get Started

  • Versions
  • Request Tour

VergeIO For

  • SAN Replacement
  • Solving Infrastructure Modernization Challenges
  • Artificial Intelligence
  • Hyperconverged
  • Server Room
  • Secure Research Computing

Product

  • Benefits
  • Documents
  • Architecture Overview
  • Use Cases
  • Videos

Company

  • Blog
  • Technical Documentation
  • Legal

© 2026 VergeIO. All Rights Reserved.