• Skip to main content
  • Architecture
    • Overview
      Learn about VergeOS’ unique unfied architecture that integrates virtualization, storage, networking, AI, backup and DR into a single data center operating system
    • Infrastructure Wide Deduplication
      VergeOS transforms deduplication from a storage-only commodity into a native, infrastructure-wide capability that spans storage, virtualization, and networking, eliminating hidden resource taxes
    • VergeFS
      VergeFS is a distributed, high-performance global file system integrated into VergeOS, unifying storage across nodes, tiers, and workloads while eliminating the need for external SANs
    • VergeFabric
      VergeFabric is VergeOS’s integrated virtual networking layer, delivering high-speed, low-latency communication across nodes while eliminating the complexity of traditional network configurations.
    • Infrastructure Automation
      VergeOS integrates Packer, Terraform, and Ansible to deliver an end-to-end automation pipeline that eliminates infrastructure drift and enables predictable, scalable deployments.
    • VergeIQ
      Unlock secure, on-premises generative AI—natively integrated into VergeOS. With VergeIQ, your enterprise gains private AI capabilities without the complexity, cloud dependency, or token-based pricing.
  • Features
    • Virtual Data Centers
      A VergeOS Virtual Data Center (VDC) is a fully isolated, self-contained environment within a single VergeOS instance that includes its own compute, storage, networking, and management controls
    • High Availability
      VergeOS provides a unified, easy-to-manage infrastructure that ensures continuous high availability through automated failover, storage efficiency, clone-like snapshots, and simplified disaster recovery
    • ioClone
      ioClone utilizes global inline deduplication and a blockchain-inspired file system within VergeFS to create instant, independent, space-efficient, and immutable snapshots of individual VMs, volumes, or entire virtual data centers.
    • ioReplicate
      ioReplicate is a unified disaster-recovery solution that enables simple, cost-efficient DR testing and failover via three‑click recovery of entire Virtual Data Centers—including VMs, networking, and storage.
    • ioFortify
      ioFortify creates immutable, restorable VDC checkpoints and provides proactive ransomware detection with instant alerts for rapid recovery and response.
    • ioMigrate
      ioMigrate enables large-scale VMware migrations, automating the rehosting of hundreds of VMs (including networking settings) in seconds with minimal downtime by seamlessly transitioning entire VMware environments onto existing hardware stacks.
    • ioProtect
      ioProtect offers near-real-time replication of VMware VMs—including data, network, and compute configurations—to a remote disaster‑recovery site on existing hardware, slashing DR costs by over 60% while supporting seamless failover and testing in an efficient, turnkey VergeOS Infrastructure.
    • ioOptimize
      ioOptimize leverages AI and machine learning to seamlessly integrate new and old hardware and automatically migrate workloads from aging or failing servers.
    • ioGuardian
      ioGuardian is VergeIO’s built-in data protection and recovery capability, providing near-continuous backup and rapid VM recovery during multiple simultaneous drive or server failures.
  • IT Initiatives
    • VMware Alternative
      VergeOS offers seamless migration from VMware, enhancing performance and scalability by consolidating virtualization, storage, and networking into a single, efficient platform.
    • Hyperconverged Alternative
      VergeIO’s page introduces ultraconverged infrastructure (UCI) via VergeOS, which overcomes HCI limitations by supporting external storage, scaling compute and storage independently, using existing hardware, simplifying provisioning, boosting resiliency, and cutting licensing costs.
    • SAN Replacement / Storage Refresh
      VergeIO’s storage by replacing aging SAN/NAS systems within its ultraconverged infrastructure, enhancing security, scalability, and affordability.
    • Infrastructure Modernization
      Legacy infrastructure is fragmented, complex, and costly, built from disconnected components. VergeOS unifies virtualization, storage, networking, data protection, and AI into one platform, simplifying operations and reducing expenses.
    • Secure Research Computing
      VergeIO's Secure Research Computing solution combines speed, isolation, compliance, scalability, and resilience in a cohesive platform. It’s ideal for institutions needing segmented, compliant compute environments that are easy to deploy, manage, and recover.
    • Venues, Remote Offices, and Edge
      VergeOS delivers resiliency and centralized management across Edge, ROBO, and Venue environments. With one platform, IT can keep remote sites independent while managing them all from a single pane of glass.
    • Fight Data Center Inflation
      DRAM, SSD and server prices keep climbing. VergeOS uses as much as 50% less RAM per VM than VMware, runs on the servers you already own, and moves cold data to low-cost hard drives.
  • Blog
      • The Midsize Enterprise Needs Infrastructure SimplicityInfrastructure simplicity matters most to midsize IT, where three to five generalists run virtualization, storage, networking, data protection and DR. Three-tier and HCI hide that complexity behind a GUI. VergeOS unifies all five in one code base with one interface.
      • The Midsize Enterprise Needs Greater ResiliencyResiliency belongs in every VMware alternative evaluation for small IT teams. See how VergeOS keeps midsize enterprise workloads running through drive and server failures, locks snapshots against ransomware, and turns Patch Tuesday from a weekend maintenance window into a weekday task.
      • Edge Disaster Recovery: Keep Customer-Facing Locations OpenEdge disaster recovery for stores and venues. VergeOS runs a site on one server, recovers it locally from snapshots and fails it over to the core.
    • View All Posts
  • Resources
    • Become a Partner
      Get repeatable sales and a platform built to simplify your customers’ infrastructure.
    • Technology Partners
      Learn about our technology and service partners who deliver VergeOS-powered solutions for cloud, VDI, and modern IT workloads.
    • White Papers
      Explore VergeIO’s white papers for practical insights on modernizing infrastructure. Each paper is written for IT pros who value clarity, performance, and ROI.
    • In The News
      See how VergeIO is making headlines as the leading VMware alternative. Industry analysts, press, and partners highlight our impact on modern infrastructure.
    • Press Releases
      Get the latest VergeOS press releases for news on product updates, customer wins, and strategic partnerships.
    • Case Studies
      See how organizations like yours replaced VMware, cut costs, and simplified IT with VergeOS. Real results, real environments—no fluff.
    • Webinars
      Explore VergeIO’s on-demand webinars to get straight-to-the-point demos and real-world infrastructure insights.
    • Documents
      Get quick, no-nonsense overviews of VergeOS capabilities with our datasheets—covering features, benefits, and technical specs in one place.
    • Videos
      Watch VergeIO videos for fast, focused walkthroughs of VergeOS features, customer success, and VMware migration strategies.
    • Technical Documentation
      Access in-depth VergeOS technical guides, configuration details, and step-by-step instructions for IT pros.
  • How to Buy
    • Schedule a Demo
      Seeing is believing, set up a call with one of our technical architects and see VergeOS in action.
    • Versions
      Discover VergeOS’s streamlined pricing and flexible deployment options—whether you bring your own hardware, choose a certified appliance, or run it on bare metal in the cloud.
    • Test Drive – No Hardware Required
      Explore VergeOS with VergeIO’s hands-on labs and gain real-world experience in VMware migration and data center resiliency—no hardware required
  • Company
    • About VergeIO
    • Support
      Get fast, expert help from VergeIO’s support team—focused on keeping your infrastructure running smoothly.
    • Careers
      Join VergeIO and help reshape the future of IT infrastructure. Explore open roles and growth opportunities.
  • 855-855-8300
  • Contact
  • Search
  • 855-855-8300
  • Contact
  • Search
  • Architecture
    • Overview
    • VergeFS
    • VergeFabric
    • Infrastructure Automation
    • VergeIQ
  • Features
    • Virtual Data Centers
    • High Availability
    • ioClone
    • ioReplicate
    • ioFortify
    • ioMigrate
    • ioProtect
    • ioOptimize
    • ioGuardian
  • IT Initiatives
    • VMware Alternative
    • Hyperconverged Alternative
    • SAN Replacement / Storage Refresh
    • Infrastructure Modernization
    • Secure Research Computing
    • Venues, Remote Offices, and Edge
    • Fight Data Center Inflation
  • Blog
  • Resources
    • Become a Partner
    • Technology Partners
    • White Papers
    • In The News
    • Press Releases
    • Case Studies
    • Webinars
    • Documents
    • Videos
    • Technical Documentation
  • How to Buy
    • Schedule a Demo
    • Versions
    • Test Drive – No Hardware Required
  • Company
    • About VergeIO
    • Support
    • Careers
×
  • Architecture
    • Overview
    • VergeFS
    • VergeFabric
    • Infrastructure Automation
    • VergeIQ
  • Features
    • Virtual Data Centers
    • High Availability
    • ioClone
    • ioReplicate
    • ioFortify
    • ioMigrate
    • ioProtect
    • ioOptimize
    • ioGuardian
  • IT Initiatives
    • VMware Alternative
    • Hyperconverged Alternative
    • SAN Replacement / Storage Refresh
    • Infrastructure Modernization
    • Secure Research Computing
    • Venues, Remote Offices, and Edge
    • Fight Data Center Inflation
  • Blog
  • Resources
    • Become a Partner
    • Technology Partners
    • White Papers
    • In The News
    • Press Releases
    • Case Studies
    • Webinars
    • Documents
    • Videos
    • Technical Documentation
  • How to Buy
    • Schedule a Demo
    • Versions
    • Test Drive – No Hardware Required
  • Company
    • About VergeIO
    • Support
    • Careers

George Crump

September 22, 2026 by George Crump

Ann Arbor, MI  ·  September 22, 2026

New CEO will accelerate VergeIO’s mission to collapse the fragmented data center stack onto a single operating system — delivering the Simplicity, Savings, and Service companies need as AI reshapes infrastructure demand

VergeIO, maker of the VergeOS private cloud operating system, today announced the appointment of Parag Patel as Chief Executive Officer, effective September 8, 2026. Mr. Patel succeeds Yan Ness, who will remain on the Board, as the company enters its next phase of growth.

30+ Years in data center,
cloud infrastructure and AI
Sept 8 Effective date as
Chief Executive Officer
5 → 1 Separate vendors replaced
by one operating system
70% Infrastructure cost reduction
for customers leaving VMware
Key Takeaways
  • Parag Patel is VergeIO’s Chief Executive Officer, effective September 8, 2026. He succeeds Yan Ness, who remains on the Board.
  • Patel brings more than 30 years in data center, cloud infrastructure and AI, including half his career at VMware and leadership roles at C3.ai and Forcepoint.
  • VergeOS unifies virtualization, storage, data protection, networking and automation in a single piece of software running on standard hardware.
  • Customers moving off VMware have used VergeOS to cut infrastructure costs by as much as 70 percent.
  • Simplicity, Savings and Service anchor the company’s mission as AI reshapes infrastructure demand.
A Pivotal Moment for Enterprise Infrastructure

The harder problem is the infrastructure teams already run

The appointment comes at a pivotal moment for enterprise infrastructure. Trillions of dollars are being committed to data center capacity worldwide as organizations race to build for AI — but for most IT teams, the more immediate problem isn’t a shortage of GPUs, it’s the accumulated weight of the infrastructure they already run. Two decades of bolting together separate products for virtualization, storage, data protection, networking, and automation have left most data centers as a patchwork of licenses, vendors, and integration points. For the typical mid-market company with limited staff and resources, this is expensive to operate and difficult to adapt to whatever comes next, AI included.

Meet the New CEO

Parag Patel, Chief Executive Officer

Parag Patel brings over 30 years of experience in Data center, Cloud Infrastructure and AI to VergeIO. Half of his professional career was spent at VMware, where he joined a company of roughly 500 people and helped build it into a global infrastructure standard. He has also held pivotal leadership roles at C3.ai and Forcepoint.

“Parag joins VergeIO at exactly the moment when what we’ve built stops being an alternative to what came before and starts being the answer to what comes next. We looked for three things: deep domain expertise, a record of success at companies at our stage, and a leader who fits the culture we built on purpose. Parag has all three. VergeIO has the product, the customers, and the momentum, and I feel really good about handing him the keys.”

Yan NessBoard Member and former CEO, VergeIO

“We are in the midst of a breathtaking data center renaissance. Every company rebuilding its data center for the AI era is discovering the same thing: you can’t bolt AI-readiness onto an infrastructure stack that’s already complicated. VergeOS’s whole premise is that simplicity, savings, and service aren’t trade-offs against capability — they’re what makes a company ready for what’s coming. We are building the software substrate that will enable this transformation.”

Parag PatelChief Executive Officer, VergeIO
A Different Premise

A unified operating system underneath the stack

VergeOS was built on a different premise: that the data center doesn’t need another point product layered on top of the stack — it needs a unified operating system underneath it. VergeOS unifies virtualization, storage, data protection, networking, and automation into a single piece of software running on standard hardware, replacing what typically takes five separate vendors with one. Customers moving off VMware have used it to cut infrastructure costs by as much as 70 percent, but the company’s ambition extends well beyond hypervisor replacement: VergeOS is designed as the foundation layer that lets companies and MSPs run today’s workloads and tomorrow’s AI applications without re-platforming every time the industry moves.

On-Demand Webinar

Beyond the Hypervisor Swap: A Deep Dive into the VergeOS Architecture

Recorded June 11, 2026

Kit Colbert, VMware’s former CTO and now a VergeIO board advisor, joins VergeIO founder Greg Campbell for a conversation between two infrastructure software architects. Watch why a unified code base solves problems a hypervisor swap leaves in place.

Watch On Demand

About VergeIO

VergeIO delivers VergeOS, a private cloud operating system that consolidates virtualization, storage, data protection, networking, and automation into a single software layer running on standard hardware. Rather than another point product to manage, VergeOS replaces the fragmented, multi-vendor data center stack outright — giving IT teams one platform, one license, and one interface to run their infrastructure today and extend it for AI tomorrow. Organizations use VergeOS to reduce combined capital and operating costs by up to 70 percent while eliminating the compounding complexity that comes from stitching together separate virtualization, storage, and networking products. VergeIO is headquartered in Ann Arbor, Michigan. Learn more at www.verge.io.

Media Contact

George Crump
Chief Marketing Officer, VergeIO
[email protected]

###

See the operating system built for what comes next

VergeOS unifies virtualization, storage, data protection, networking and automation on the servers you already own.
Read the Architecture Datasheet Request a Demo

Filed Under: Press Release

September 17, 2026 by George Crump

Hardware fails whether it is new or refurbished. VergeOS turns drive and server failures into routine events, which makes refurbished hardware a practical way to fund the VMware exit.

Refurbished hardware makes financial sense for a VMware exit, but IT teams then ask, “What happens when a used drive or server fails?” Hypervisor license costs have skyrocketed over the past two years but hardware always costs more than the hypervisor license, and the 2026 memory and flash price spike has widened that gap. Many migration projects now stall at finance review. Reusing the servers already on the floor and adding refurbished drives brings the budget back within reach, provided the platform treats hardware failure as routine.

Key Takeaways
  • Every drive and server fails eventually, new or refurbished, so resiliency belongs in the software.
  • VergeOS keeps workloads running through drive and server failures, holds data online past the resiliency factor with ioGuardian, and recovers VMs and files from snapshots at no additional software cost.
  • The on-demand Premier Connects session shows each failure live, from a pulled drive to a full data center failover.

Why Refurbished Hardware Makes IT Nervous

Traditional Recovery PathDrive failsRAID rebuild startsSecond drive failsbefore the rebuild finishesArray goes offlineworkloads stopRestore from backupthe recovery clock starts

In a three-tier data center, the storage array protects blocks with RAID, and a second drive failure during a rebuild turns into a backup restore job with significant downtime. Legacy HCI moved storage into the servers and added workload restart, yet recovery still lives in a separate backup product on separate hardware, with its own license and its own console. In both designs, a failure that exceeds the protection level hands the problem to the backup team and starts the recovery clock.

Buying premium new hardware became the standard way to push that moment further out, which ties resiliency to a purchase order finance now keeps rejecting.

Resiliency and Protection for Refurbished Hardware

The Price of ResiliencyCostResiliencyRAID 5RF2RF3Longer retentionBubble size = performance impact

Resiliency keeps an application running with zero downtime and zero data loss when a component fails. Protection restores data after resiliency runs out. Every environment has a resiliency limit, and raising it costs money. RAID 5 costs the least, offers the least resiliency, and imposes the highest performance penalty. RF2 costs more with almost no performance impact, RF3 costs more again with none, and longer snapshot retention sits at the top of the scale.

VergeOS changes where that money goes. Each step up is a setting in the platform, so climbing the scale costs capacity instead of another software license. Refurbished drives make that capacity affordable. An organization can run RF3 with longer retention on the budget that once bought a smaller pool of new drives.

Saratoga Casino Holdings runs this model in production. The company moved to VergeOS on CXTEC® equal2new® refurbished servers and removed roughly $50,000 a year in Pure Storage array maintenance. Read the Saratoga Casino Holdings case study for the full story.

Resilient: Refurbished Hardware Keeps the Workload Running

VergeOS runs compute, storage, networking, and data protection in one code base. With RF2 or RF3 set per workload, a failed drive is invisible to the application. A server failure triggers an automatic restart of its workloads on the surviving nodes, with no operator in the loop. The age of the failed part makes no difference, so refurbished hardware delivers the same outcome as new hardware.

RF vs. RAID

RF vs. RAIDShare of raw capacityRAID 5Usable20-25%RAID 6Usable25-33%RF2Usable2nd copyGlobal inline dedup recovers most of the gapPerformanceNormalDrive failedRAID 5/6Parity penaltySevereRF2Almost noneNone

At first glance, RF2 looks like it doubles capacity consumption, since every block exists twice. The real gap is much smaller. RAID 5 gives up 20 to 25 percent of raw capacity to parity in a typical four or five drive group, and RAID 6 gives up 25 to 33 percent with two parity drives in a six to eight drive group. VergeOS global inline deduplication makes up for most of the difference. It works across every drive and server in the environment, so a block shared by many VMs is stored once.

Performance favors RF from the start. During normal production operations, RF2 has almost no performance impact, and it improves read performance, since VergeOS serves reads from multiple drives and servers. A failed drive leaves performance where it was, with the surviving copy answering every request. RAID 5 and RAID 6 pay a parity penalty on writes in normal operation, and the penalty grows sharply in a degraded state, when the array reconstructs data on every read and runs a rebuild at the same time. That degraded window is exactly where refurbished hardware puts the most pressure on a design, a point that has been characterized as storage recovery architecture mattering more than drive reliability.

Repairable: Data on Refurbished Hardware Stays Online Past the Limit

The hardest objection to refurbished hardware is a second failure before the first repair finishes. Two drives failing at once exceed RF2, and in most designs that means a restore. ioGuardian covers that window. A dedicated server, the ioGuardian target, delivers missing data segments to VMs in real time, so workloads keep running as the system repairs itself. The mechanics are covered in detail in Surviving Cascading Drive Failure.

▶
On-Demand Webinar · Premier Connects
Exit VMware to Resilient HCI
Aaron Richman and David Vincent fail drives, a server, and a full virtual data center live on VergeOS.
Watch Now →

Recoverable: Recovery From the Same Interface

Recovery Inside the PlatformVM volumeSnapshot 1Snapshot 2Snapshot 3Each ioClone snapshot is a standalone copyVirtual data centerVMs, network,storage settingsDR siterefurbishedhardwareThe whole environment fails over as one object

Some events have nothing to do with hardware, like an administrator deleting a VM or a user removing files. VergeOS snapshots use ioClone and behave as independent copies instead of a dependent chain, so retention is bounded by capacity. A deleted VM comes back instantly from a snapshot, and individual files recover through a hot plug drive attached to the running VM. Recovery works the same way on refurbished hardware as it does on new servers.

For a site-level event, a virtual data center encapsulates the VMs, networking, and storage settings, and it fails over to the DR site as one object. The DR site can run on refurbished hardware too.

How Each Design Handles Failure

FailureThree-TierLegacy HCIVergeOS
One driveRAID rebuild on the arrayHCI storage layerRF2 or RF3, workload unaffected
One serverHypervisor HA restartWorkload restartAutomatic restart on surviving nodes
Beyond the protection levelRestore from backup productRestore from backup productioGuardian keeps data online
Deleted VM or filesSeparate backup productSeparate backup productioClone snapshot, hot plug drive
Site lossArray replication plus runbooksReplication plus separate DR toolingVirtual data center failover
Protection software costSeparate licensesSeparate licensesIncluded in VergeOS
Key Terms
Resiliency factor (RF2, RF3)
The number of synchronous copies VergeOS keeps of each block, set per workload. RF2 survives one failure and RF3 survives two, on new or refurbished hardware.
ioGuardian
The VergeOS capability that delivers missing data segments to VMs in real time during multiple drive or server failures, using a dedicated server called the ioGuardian target.
ioClone
The VergeOS snapshot technology. Each snapshot behaves as an independent copy, so retention is bounded by capacity.
Virtual data center (VDC)
A single object that encapsulates VMs, networking, and storage settings, so the whole environment replicates and fails over together.

See Every Failure Now

The Premier Connects session, Exit VMware to Resilient HCI: Integrated Data Protection, Faster Recovery, and Built-In DR, walks through each stage in order. Aaron Richman, Field Evangelist, explains each feature, and David Vincent, Technical Evangelist, demonstrates it on a running VergeOS environment. The demos escalate from a pulled drive and a failed server to two failed drives, a deleted VM and files, and a full virtual data center failover. Watch the on-demand session to see how refurbished hardware made resilient changes the math on your VMware exit.

Frequently Asked Questions
Is refurbished hardware reliable enough for production?
Every drive and server fails eventually, new or refurbished. VergeOS plans for that failure with RF2 or RF3, ioGuardian, and snapshots, so production reliability comes from the platform instead of the age of the part.
What do these resiliency capabilities cost?
RF2 and RF3, ioGuardian, unlimited snapshots, instant recovery, and virtual data center failover come with VergeOS at no additional software cost.
Do I still need a backup product?
A backup product becomes optional, used for GUI-based single file recovery and long term archiving. VergeOS supports the backup platforms customers already run, including Veeam.

Next Steps

The on-demand session, the architecture behind it, and a customer running VergeOS on refurbished hardware are one click away.

On-Demand Webinar
Exit VMware to Resilient HCI
Live drive, server, and data center failures on VergeOS, from a pulled drive to VDC failover.
White Paper
Beyond the Hypervisor Swap
The VergeOS architecture in depth, including resiliency, recovery, and disaster recovery.
Case Study
Saratoga Casino Holdings
VergeOS on CXTEC® equal2new® refurbished servers, with Pure Storage array maintenance removed.

Filed Under: Storage, VMwareExit Tagged With: data protection, Disaster Recovery, ioGuardian, refurbished hardware, refurbished SSDs, RF3, VergeOS, VMware, VMware alternative, VMware exit

September 9, 2026 by George Crump

Eight minutes, one SQL Server, and a performance monitor that stays on screen through both migrations.

Presented by David Vincent, Technical Marketing, VergeIO. Roughly eight minutes.

Can you run SQL Server on spinning disk without paying for it in latency? Most storage tiering demos show you the interface rather than the answer. David Vincent moves a live SQL workload across VergeOS tiers, from NVMe down to 10K spinning disk and back, and leaves the throughput and latency graphs running the whole time so you can watch what the move actually does.

Key Takeaways
  • A live SQL workload moves from Tier 1 NVMe to Tier 4 spinning disk with throughput and latency holding flat, since reads are served from RAM cache.
  • At a 10,000 request peak load the application handles about 727 filings per second on NVMe and about 473 on 10K spinning disk, with commit latency under a millisecond on both runs.
  • Tier placement is a volume property an administrator sets. The migration runs through the API in the background and the workload stays online.

What happens when you move SQL Server to spinning disk

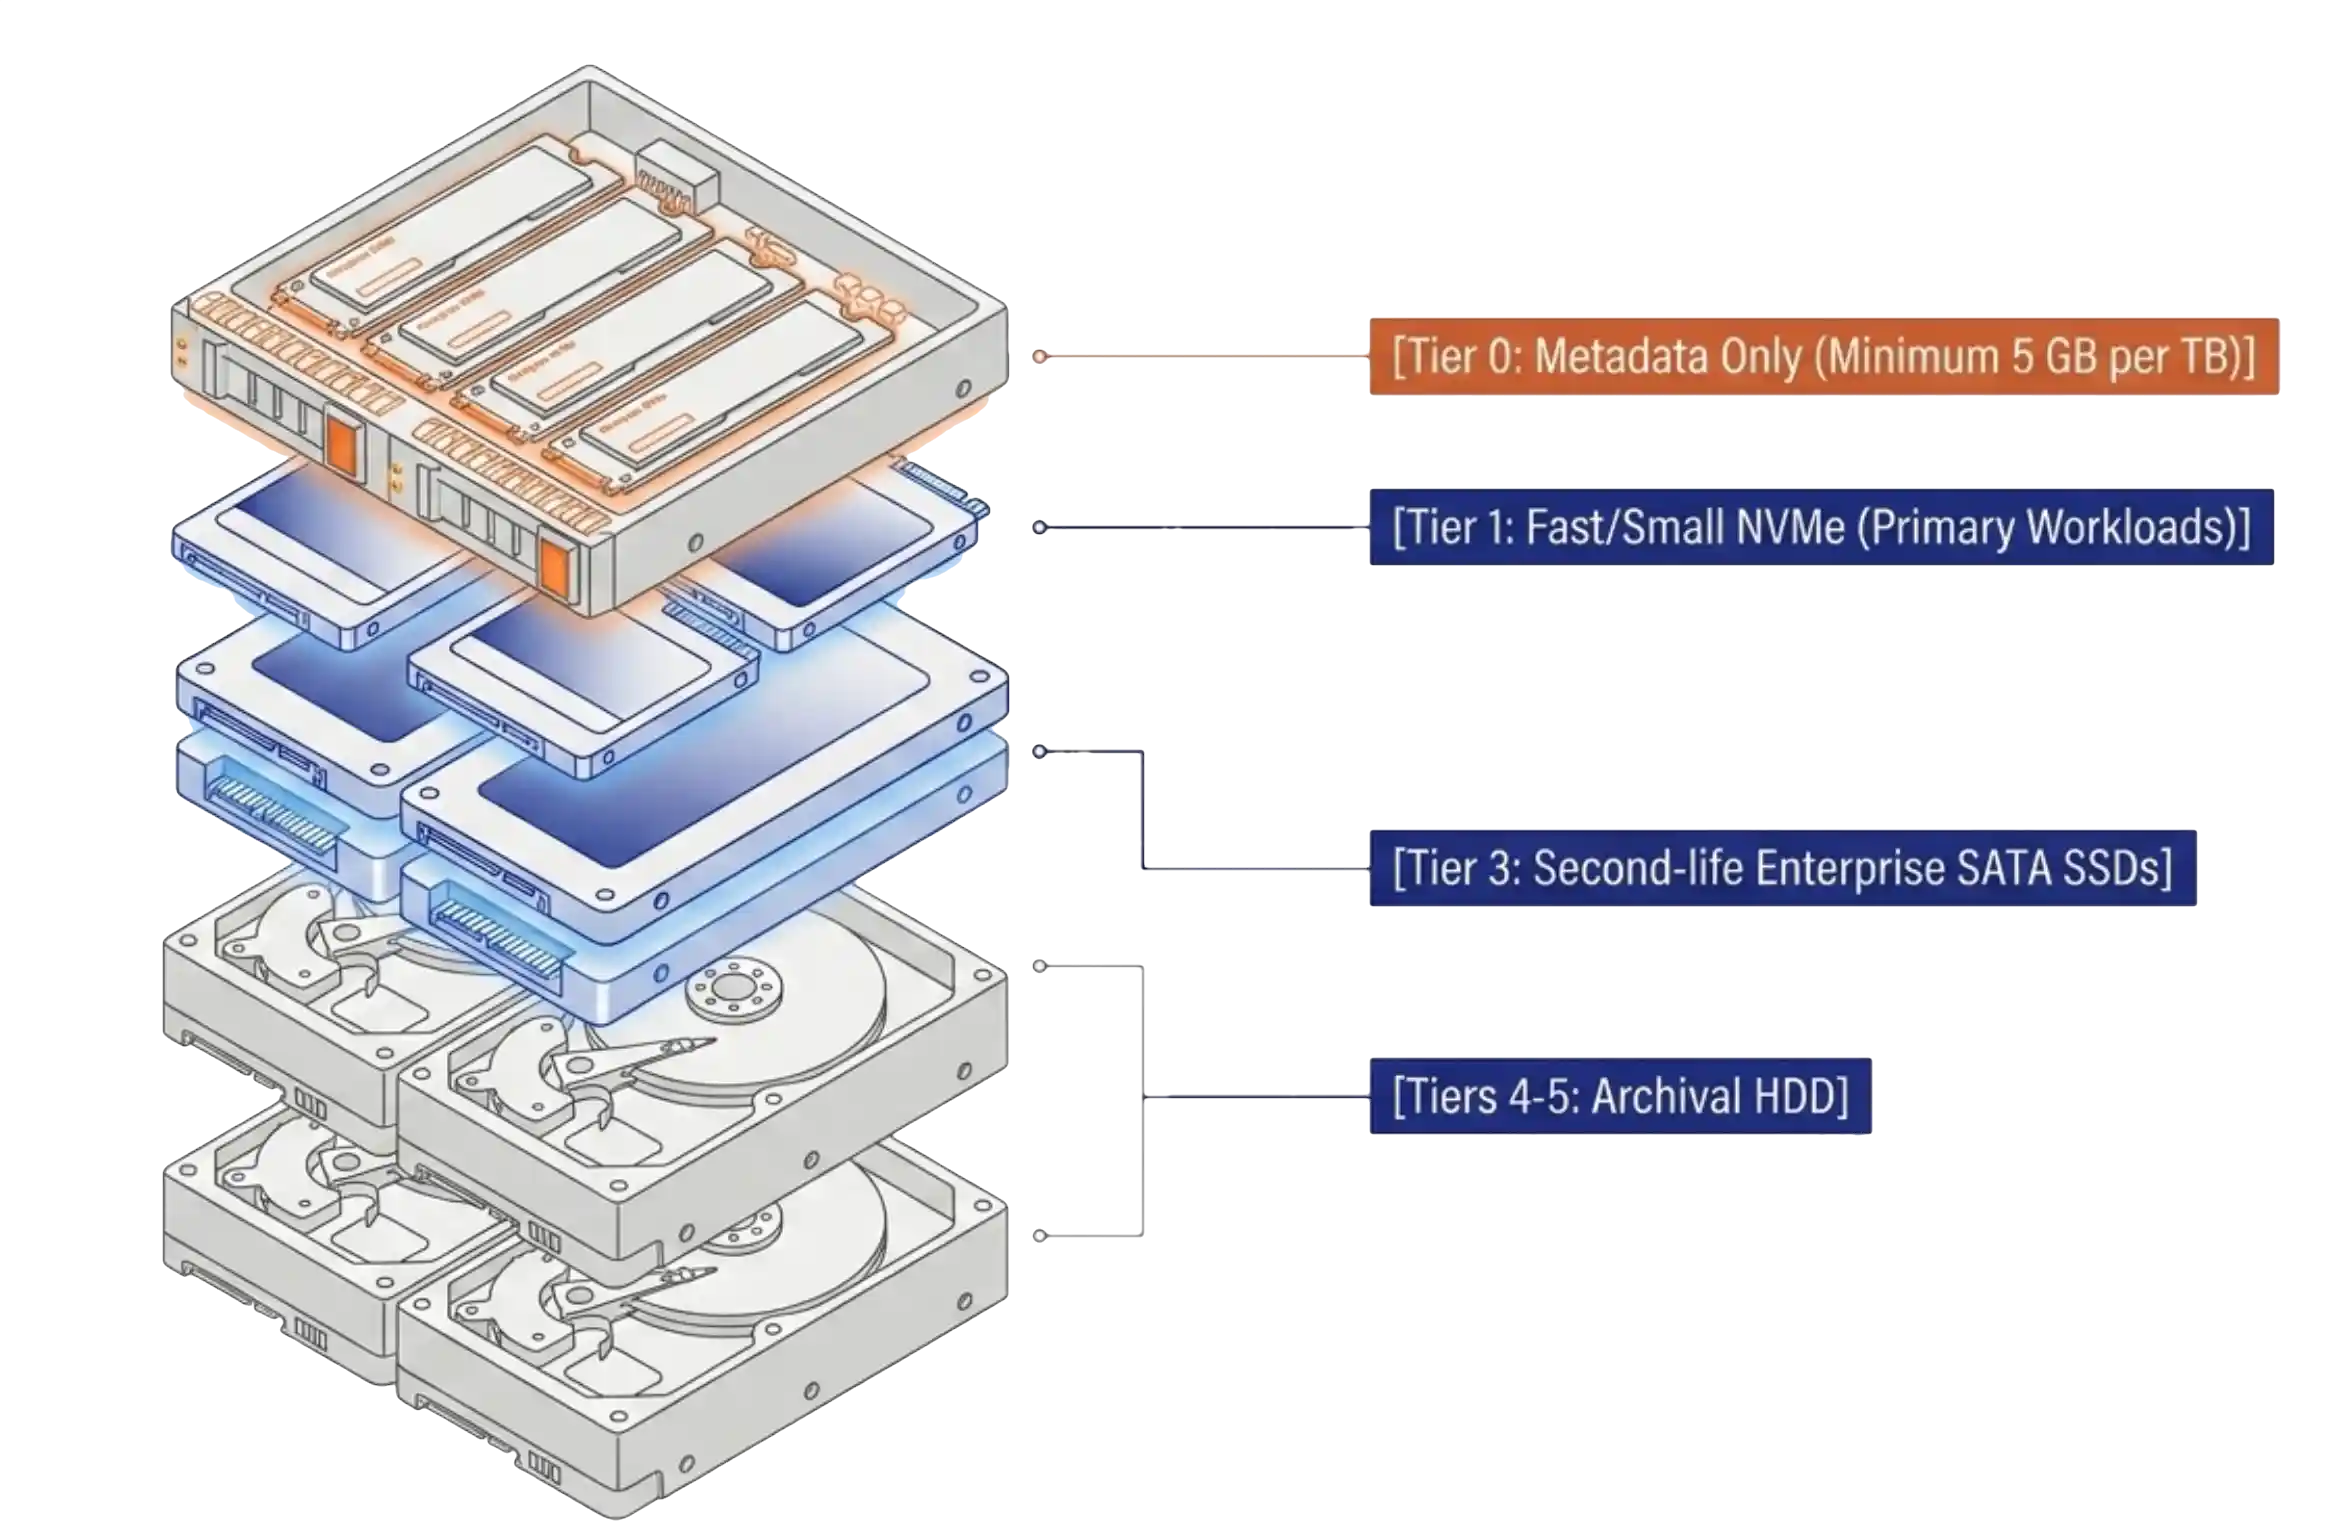
The Verge lab runs four tiers in one cluster: Tier 1 NVMe, Tier 2 SAS SSD, and Tiers 4 and 5 on 10K SAS hard drives. Changing a volume’s tier takes one field. Open the drive, set Preferred Tier, submit. TempDB moves from Tier 1 to Tier 4 in seconds.

Then comes the part that matters. The SQL data and log volumes move down to Tier 4 with the monitoring app running, and the latency line holds where it was. A load simulator fires 10,000 filings at a tax application on Tier 1, then repeats the identical run after a migration to Tier 5.

Why SQL Server on spinning disk holds its latency

The Full Session

Can You Afford Your Next Storage Refresh?

George Crump and David Vincent on the first storage refresh in thirty years that prices higher than the original purchase. Available on demand.

Watch the Session

The answer sits in the read path. VergeOS caches the active working set in server memory and in an NVMe read cache. The demo includes an anatomy view of one transaction: the client issues the request, the server checks the pool, finds the page resident in RAM, skips the disk entirely, and returns in 146 microseconds. Tier assignment has no influence on that path.

Most database workloads run read-heavy, commonly around eighty percent reads against twenty percent writes. Those reads come out of the RAM cache rather than off the media, and global inline deduplication lets that cache serve more of the environment from the same memory.

Writes go to the tier the volume currently sits on. The tier therefore governs a minority of the real I/O path, which is why moving a database to spinning disk costs about a third of the throughput rather than falling off a cliff.

Cold reads tell the honest version of the story. A request that misses both RAM and the read cache goes to the media, and spinning disk answers slower than flash. That difference shows up under peak load, and it stays a fraction of the price difference between the two.

Figures come from a single lab run on one workload, shown live in the recording. Read them as the shape of the trade rather than as a benchmark.
MeasureTier 1 NVMeTier 5 10K SAS
Filings per second, peak loadAbout 727About 473
Commit latencyUnder 1 msUnder 1 ms
10,000 filingsAbout 13 secondsAbout 21 seconds at that rate
Single read, RAM hit146 microseconds146 microseconds
Time to change the tierSecondsSeconds
Block migrationBackground, workload onlineBackground, workload online

What this means for a 2026 refresh

Auto-tiering guesses where your data should live. You already know. A tax firm knows in October what April looks like, and the identification algorithm learns that fact weeks late. Tier control turns a capacity purchase into a calendar decision: flash for the busy season, hard drives for the eleven months after it, in the same pool, under the same deduplication.

That matters more this year than it did three years ago. Flash and DRAM prices are climbing into 2027 as the cloud AI build out consumes supply, which makes an all flash refresh the most expensive way to solve a problem the drives in your servers can already solve. The licensing side compounds it, and Storage Switzerland has written about how capacity-based storage licensing breaks the economics of HCI.

The written version of this argument runs in Storage Tiering Is Not the Problem, Losing Control of It Is. To put a number on your own environment, the Refresh Cost Diagnostic is a twenty minute working session and a five page report.

Frequently Asked Questions

Does the workload go offline during a tier migration?

The volume stays online. VergeOS moves the blocks in the background through the API as the application keeps serving requests, and the demo runs a load test across a migration to show it.

How much slower is spinning disk in practice?

In this lab run, peak throughput moved from about 727 filings per second to about 473, with commit latency under a millisecond on both. Your result depends on how much of your working set fits in RAM and read cache, which is the first thing worth measuring.

Can tier assignment be automated?

Preferred Tier is exposed through the API, so the change scripts cleanly against a calendar or a monitoring trigger. Your rules drive it, on your schedule, with a record of what changed.

Do all the servers need matching drives?

Tiers exist wherever drives of that class are installed in the cluster. Nodes can carry different mixes, and capacity grows by adding drives to the servers running the workload.

Filed Under: Videos Tagged With: Storage

September 3, 2026 by George Crump

Storage tiering control belongs to the team running the workload, not to an algorithm guessing at it from a dashboard. Tiering itself was never the flaw in enterprise storage. IT teams have separated hot data from cold data across flash and disk for two decades, and the price gap between flash and hard drives makes that discipline worth more this year than ever. The flaw sits in auto-tiering, the algorithm vendors ask IT to trust with the decision of what moves and when. IT has never trusted it, and giving up that control was never something IT wanted to do. There is a better way.

Key Takeaways
  • Automated tiering moves too slowly, works from an incomplete picture of the workload, and struggles most on the return trip, warming data back up to flash once the business needs it again.
  • VergeOS puts storage tiering control back with the IT team that already knows the workload, and moves a running VM between tiers, in either direction, with no downtime.
  • The same mechanism that puts you in control of tiering also shrinks the flash you have to buy at 2026 prices, and VergeOS licenses by the server so that saving reaches the bill.

The Guess Nobody Asked For

Auto-tiering reacts late in both directions Actual workload demand Auto-tiering’s guess Paying for flash no one needs Waiting on flash it needs

A policy engine cannot know that tax season ends on a specific date. It watches a heat map, applies a threshold, and moves blocks when the pattern crosses that threshold. The workload behind the pattern is quarter-end close one month, a once-a-month batch job the next, or an application the finance team only touches for three weeks a year. The engine treats all three the same way, and it promotes or demotes data on its own schedule, not the schedule the business actually runs on.

Three failures live inside that schedule. The algorithm often takes too long to identify data that has gone cold enough to move, so a block sits on expensive flash for days or weeks past the point it earned the spot. The data set behind the decision is frequently incomplete, built from a sampling window that misses the workload’s real pattern. And when the engine does act, it moves the wrong data at the wrong time, demoting a block the application still needs or promoting one nobody asked for.

The bigger failure sits on the return trip. Moving data down to a cheap tier is the easy direction for most auto-tiering engines. Moving it back up to flash the moment the business needs it again is not. Warm paths back to the fast tier run limited and slow in most implementations, so a demotion that made sense in April turns into a performance problem the following January, when tax season starts back up and the data that matters most is still sitting on a hard drive, waiting for the algorithm to notice.

That mismatch is common. It is built into the design. A policy someone else wrote has no way to know what your calendar looks like this month, in either direction.

Who Actually Knows the Workload

Storage tiering control moving a live VergeOS workload between NVMe flash and second-life SATA tiers

Storage tiering control starts with the person who already knows the answer. The IT professional running the application knows when it goes hot and when it goes cold, without a heat map to tell them. Tax season ends on a date on the calendar, not on an algorithm’s guess, and it starts back up on a date too. A batch job runs on a schedule the operations team set months ago. Nobody in that room needs a prediction. They need the ability to act on what they already know, the moment they know it, in either direction.

VergeOS builds tiering around that fact instead of working around it. A running VM moves between tiers on command, live, and it keeps serving reads and writes the entire time. No reboot, no guest awareness, no maintenance window. VergeOS documentation on the mechanism reports an API acknowledgment in about a second and full block movement completing in the background within seconds, with the VM staying in a running state throughout. The decision comes from the person who owns the workload, and the system carries it out the moment they make it.

The Tax Season Test

Picture an application that runs mostly writes during a specific stretch of the year. It earns its place on the flash tier, and the workload profile on screen shows the write-heavy pattern plainly. Once that stretch ends, the same application turns mostly reads. It no longer needs flash, and the flash it was holding is needed somewhere else.

On-Demand Webinar
Can You Afford Your Next Storage Refresh?
Watch David Vincent flip this exact workload from flash to hard drive live, then move it back, with zero downtime either direction.
Watch On Demand

That is the exact scenario VergeIO walks through live in the TruthInIT session “Can You Afford Your Next Storage Refresh?” David Vincent flips the workload from writes to reads, then migrates the running VM from the flash tier to the hard drive tier, and it keeps serving I/O the entire time. The move takes seconds on screen, and the performance impact stays limited. The RAM cache handles the reads underneath the move.

The same command runs in reverse. That is storage tiering control working in both directions, not just one. When tax season starts back up, the workload moves from the hard drive tier back to flash on that same on-command basis, warmed up the moment the team calls for it, with no policy engine standing between the decision and the move.

The pattern is not exclusive to tax season. A retail chain building for the holiday quarter needs the same flash from November through the January returns window, then has no use for it once that window closes. A law firm that takes on a large case needs the same flash for the length of discovery, and lets it go the moment the matter closes. Every one of these workloads runs on a calendar the IT team already tracks, and storage tiering control means the storage follows that calendar instead of a policy engine’s guess.

Where Storage Tiering Control Meets the Refresh Math

Control over tiering is not just an operational win. It changes what you have to buy on the next refresh. VergeOS deduplicates data across storage, virtualization, and networking with shared metadata, so a block stays deduplicated as it moves through the system instead of getting rehydrated the moment it lands on an array. That lets RAM cache sit directly in the server next to the VM. VergeOS documentation puts the resulting cache hit rate at four to five times what array-side caching delivers. The cache no longer spends space storing the same block many times over.

Deduplication and RAM cache shrink what the refresh has to buy Global Deduplication 4 copies stored 1 unique block + RAM cache: 4-5x hit rate Flash needed on the next refresh Without dedup + cache Full footprint With storage tiering control + dedup Shrinks Same performance, less flash to buy at 2026 prices

A smaller working set and a higher cache hit rate both point the same direction. Less flash has to sit in the design to hit the same performance. Flash and memory prices climbed 70 to 95 percent through the first half of 2026, with more increases projected into the third quarter. Every gigabyte of flash a design avoids buying is a gigabyte that never has to be priced again at those numbers on the next refresh.

None of that math holds if the license meter cancels it out. Capacity-priced storage licensing charges for every terabyte purchased, and the meter reads raw capacity, so deduplication and thin provisioning never lower the number on the bill. That mismatch is what turns a converged platform’s hardware advantage back into a dedicated array’s advantage. VergeOS licenses by the server, not the terabyte, so the flash a design avoids buying through storage tiering control and deduplication stays avoided on the license line too.

Key Terms
Storage tiera category of storage media grouped by performance and cost, running from high-endurance flash down to archival hard drives.
Auto-tieringa policy engine that predicts which data is hot or cold from access patterns and moves it on its own schedule, without an operator making the call.
Live tier migrationmoving a running VM’s storage between tiers, in either direction, with no reboot, no interruption, and no pause in reads or writes.
Global inline deduplicationremoving duplicate data blocks before they get written, so cache and flash capacity carry unique data instead of storing the same block many times over.

Auto-Tiering vs. Storage Tiering Control

Auto-tiering (policy engine)VergeOS tiering control
Who decidesA heuristic reading access patternsThe team running the workload
When it movesCrosses a threshold on its own scheduleThe moment the team calls for it
Moving back to flashLimited and slow in most implementationsThe same on-command move, run in reverse
Downtime during a moveVaries by vendor and arrayNone, the VM stays running
Failure modeWrong guess shows up at month-end closeNone, nothing gets guessed

The Bottom Line

Storage tiering control earns its place in a design when the person who understands the workload makes the call. It fails when that call gets handed to a policy engine reading a heat map from the outside, in both directions, down to a cheap tier and back up to flash. VergeOS keeps the decision with the team, moves the data live once they make it, and uses the same deduplication and cache architecture that makes that move fast to shrink what the next refresh has to buy in flash, on a license that charges by the server instead of the terabyte.

Watch David Vincent run this exact scenario live, tax season and beyond, and register to watch the full TruthInIT session on demand. For the engineering detail behind the live tier move itself, read Storage Tiering Without the Capacity Tax.

Frequently Asked Questions

Does automated tiering ever get the prediction right?

Sometimes. A wrong guess costs capacity or performance at the moment the business can least afford either one, and nobody controls when that moment lands.

Why is warming data back up to flash the harder problem?

Most auto-tiering engines build their entire design around demotion. Moving cold data down is the direction the heat map handles. Moving hot data back up on demand, before the algorithm even notices the pattern changed, gets little of that same engineering attention.

How long does a live tier move take in VergeOS?

In documented testing, the system acknowledged the move in about a second, and block movement finished in the background within seconds, with the VM running throughout. The same speed applies whether the move goes down to a cheaper tier or back up to flash.

Does moving data to a colder tier hurt performance?

The RAM cache sits in the server next to the VM and handles the reads, keeping application performance steady even after a move to a slower tier.

What does storage tiering control have to do with my next storage refresh?

Less flash in the design means less exposure to 2026 flash and memory pricing, and a per-server license means that savings is not clawed back on the capacity meter. The same architecture that puts tiering under your control also shrinks what you have to buy at today’s prices.

Filed Under: Storage

September 2, 2026 by George Crump

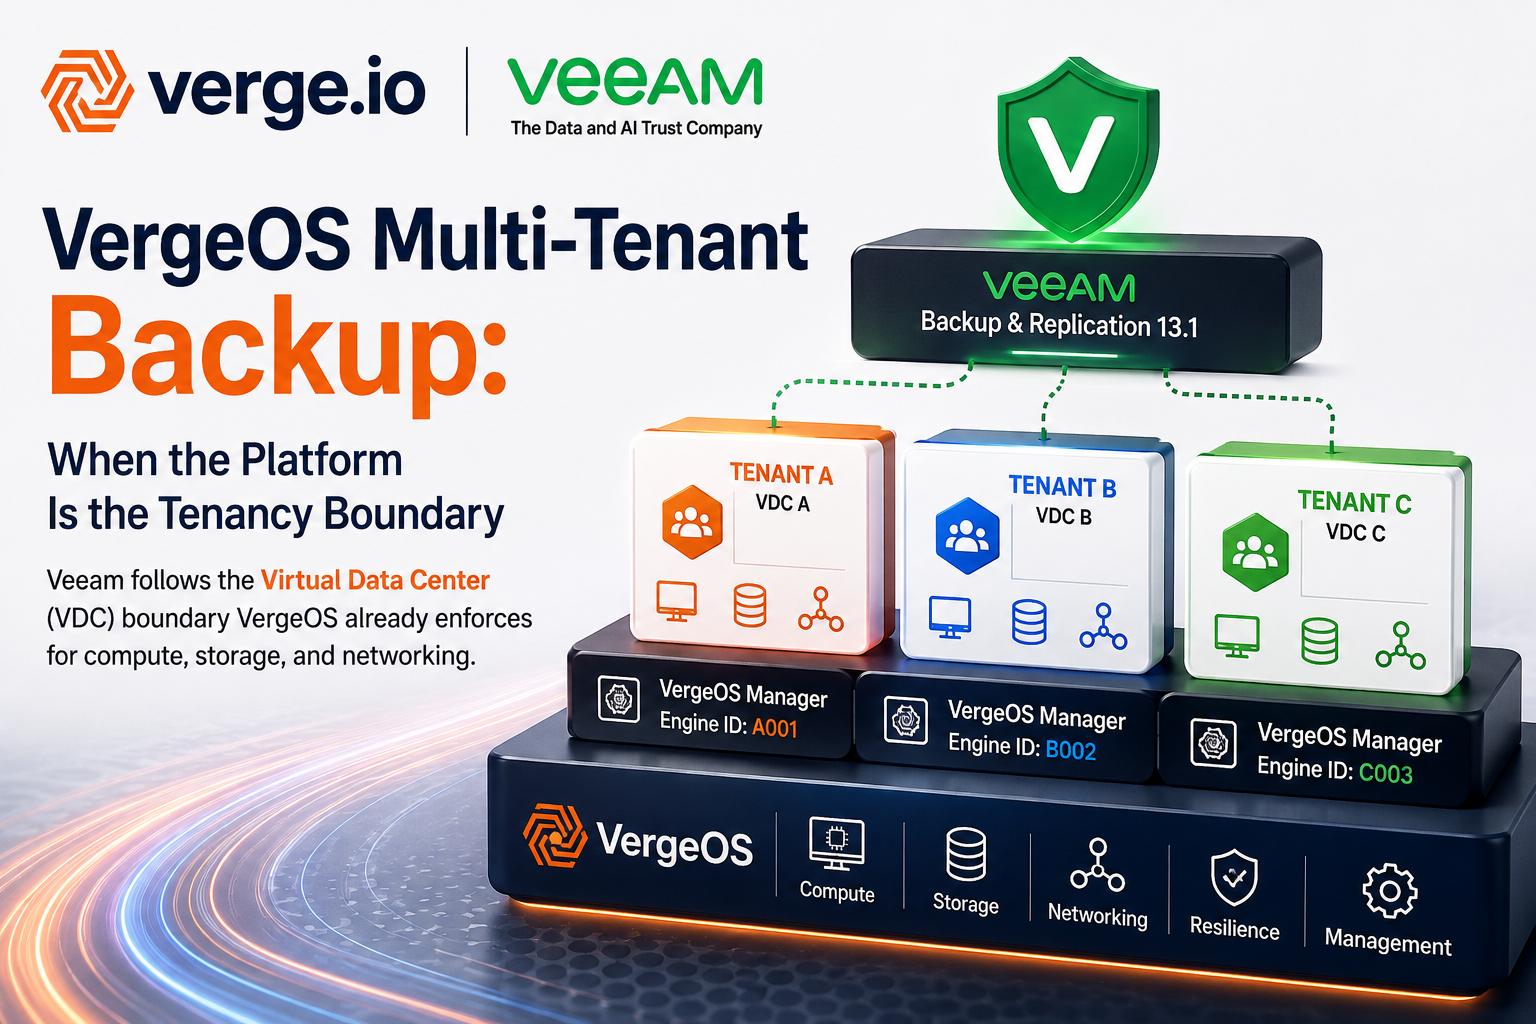
VergeOS multi-tenant backup: Veeam Backup and Replication protecting isolated Virtual Data Centers

Each VergeOS tenant becomes its own VergeOS Manager and engine ID in Veeam Backup & Replication, so multi-tenant backup follows the Virtual Data Center boundary the platform already enforces.

VergeOS multi-tenant backup follows a boundary the platform already enforces, not one a backup administrator builds on top of it. Most Veeam coverage of the VergeOS integration treats it as a hypervisor story, and multi-tenant behavior gets one line in a feature list near the bottom of the page. The architecture behind that line carries the real argument. Each VergeOS tenant is added to Veeam Backup & Replication as its own VergeOS Manager, with its own engine ID. Jobs, retention, and reporting stay separated per tenant, and that separation follows the Virtual Data Center, the isolation unit VergeOS already enforces for compute, storage, and networking.

Key Takeaways
  • VergeOS multi-tenant backup follows the Virtual Data Center boundary the platform enforces for compute, storage, and networking. Veeam inherits that boundary rather than reconstructing it.
  • Enterprises carry the same tenancy problem service providers do. Production and development, a subsidiary under its own compliance rules, an acquired company, and a regulated department all need the same separation.
  • VergeOS multi-tenant backup means Veeam adds each tenant as its own VergeOS Manager with its own engine ID, so jobs, retention, and reporting stay separated without a backup administrator maintaining the boundary by hand.

The Enterprise Case for Virtual Data Centers

Most readers categorize a Virtual Data Center as a cloud provider feature, and that categorization costs VergeOS an audience that skips past anything with “multi-tenant” in the title. An enterprise runs the same problem under different names. Production and development need real separation, not a naming convention two engineers agreed to follow. A subsidiary carries its own compliance obligations. An acquired company arrives with an infrastructure estate that has to stay intact through an integration that runs two years. Departments charge back their own infrastructure costs, and regulated workloads live under audit scope that cannot spread into the rest of the estate.

VDC 01 Production VMVMVMVM Isolated tenant VDC 02 Subsidiary VMVMVMVM Isolated tenant VDC 03 Dev / Test VMVMVMVM Isolated tenant Shared Physical Infrastructure — VergeOS

VergeOS multi-tenant backup, visualized: three isolated tenants, each running its own VMs, on one shared platform.

Every one of those is a tenancy problem, and enterprises solve it today by buying separate clusters. Separate hardware is the enterprise version of a tenant boundary. It sits idle between peaks, and moving a workload from one cluster to another means a migration project rather than a configuration change. The VDC delivers the same isolation without the second cluster, and the Veeam integration lets the backup design inherit that isolation instead of fighting for it.

The Virtual Data Center as the Isolation Unit

A VDC is a full encapsulation of compute, storage, and networking, the same way a virtual machine encapsulates its own resources, scaled up to data center size. VergeOS describes the result as complete isolation at the infrastructure level, and draws a direct contrast with a VLAN, which segments only the network and operates at the data link layer. A VLAN separates traffic. A VDC separates the infrastructure the traffic runs on.

That distinction carries the whole piece. On most platforms, multi-tenant backup is a discipline the backup administrator imposes on infrastructure that has no idea tenancy exists. Folder hierarchies, job naming conventions, tag policies, and scoped credentials all approximate a boundary the hypervisor never had. The approximation holds until someone edits a job, renames a folder, or reassigns a credential. On VergeOS the boundary already exists at the infrastructure layer before a single backup job gets created, so the backup topology inherits it instead of reconstructing it.

How Veeam Inherits VergeOS Multi-Tenant Backup

VDC 01 Tenant VDC 02 Tenant VDC 03 Tenant VergeOS Manager Engine ID 01 VergeOS Manager Engine ID 02 VergeOS Manager Engine ID 03 Veeam Backup & Replication Job 01 Job 02 Job 03

Each isolated VDC becomes its own VergeOS Manager and Veeam job — no shared path between tenants.

Veeam Backup & Replication 13.1 connects directly to that structure. A VergeOS provider system, or an individual tenant inside it, gets added to Veeam under Virtualization Platforms as its own VergeOS Manager, and each one carries its own engine ID. Jobs point at a specific VergeOS Manager, so a job built against one tenant has no path to the VMs living inside another. Retention policies, schedules, and reporting all follow the same separation, tenant by tenant, without a shared job that a backup administrator has to scope by hand.

One deployment step earns a place in this piece rather than a footnote. The provider’s External network has to extend into each tenant Veeam will protect, so Veeam Workers can reach the VMs they back up. It is a real step in a real deployment plan, and a piece that skips it loses credibility with the reader who tries the integration next.

State the division of labor plainly, since getting it backwards inverts the whole argument. VergeOS enforces the tenant boundary, and Veeam inherits it. Veeam reads a structure that already exists and reports against it, tenant by tenant, a smaller job than enforcing isolation and a more reliable one.

 Most Backup PlatformsVergeOS with Veeam
What separates tenantsFolder structure, job naming, tag policy, scoped credentialsThe Virtual Data Center, enforced at the infrastructure layer
Who enforces the boundaryThe backup administrator, job by jobThe platform, before a backup job exists
What happens when a job is misconfiguredThe boundary can be crossedThe job has no path across it
Where the boundary livesInside the backup productInside the infrastructure the backup product reads

What the Design Buys Operationally

VergeOS multi-tenant backup pays off at restore time. A tenant-scoped restore returns exactly what that tenant owns, and nothing from a neighboring tenant surfaces in the recovery, since the VergeOS Manager backing the job never had a path to that data in the first place. An enterprise running production and development as separate VDCs gets the same guarantee a service provider gets for two customers, without asking a backup administrator to police the line between them every time a job changes.

Tenant isolation answers one restore question. Whether the restored VM opens the way the application left it is a separate one, and it turns on application-consistent backup, not on which VDC the job ran against. VergeOS earns that guarantee through the same Veeam Deployment Toolkit mechanism vSphere and Hyper-V already use, and the tenant boundary has no bearing on it either way.

That is the part worth carrying past this article. A tenant boundary built from folders and naming conventions holds until somebody edits a job. A tenant boundary built into the infrastructure has nothing to edit.

Key Terms
Virtual Data Center (VDC)
A VergeOS construct that encapsulates a dedicated allocation of compute, storage, and networking, delivering isolation at the infrastructure level rather than through network segmentation alone.
VergeOS Manager
The object added under Virtualization Platforms in the Veeam console, representing either a VergeOS provider system or an individual tenant to Veeam.
Engine ID
The identifier tied to each VergeOS Manager in Veeam, unique per tenant, that keeps jobs, retention, and reporting from crossing between tenants.
Veeam Universal Hypervisor API
The Veeam interface through which VergeOS is integrated and shipped as a fully supported hypervisor in Veeam Backup & Replication 13.1.

See the Tenant Model in a Live Console

Live Webinar · September 3, 2:00 PM ET
Veeam’s Role in a VMware Exit
Veeam’s Rick Vanover joins VergeIO’s Dave Vincent and George Crump. Dave adds VergeOS to a Veeam console and walks the tenant model directly.
Register

Read the full capability set, including the multi-tenant deployment step, in the datasheet: Leave VMware. Keep Veeam.

Frequently Asked Questions
Is Virtual Data Center tenancy only useful for service providers?
Enterprises need VergeOS multi-tenant backup as much as service providers do. A service provider separating customers and an enterprise separating production from development, a subsidiary, or a regulated department all need the same boundary. Enterprises solve it today with separate clusters, and the VDC delivers the same isolation on shared hardware.
How does Veeam separate tenant backup jobs on VergeOS?
Each tenant is added to Veeam as its own VergeOS Manager with its own engine ID. Jobs, retention, and reporting all follow that separation, so a job built against one tenant has no path to another tenant’s VMs.
What has to be configured before Veeam can protect a tenant?
The provider’s External network has to extend into each tenant Veeam will protect, so Veeam Workers can reach the VMs inside it. Plan for that step alongside adding the VergeOS Manager.
Does Veeam enforce the tenant boundary, or does VergeOS?
VergeOS enforces it, at the infrastructure layer, before a backup job exists. Veeam reads that structure and reports against it, tenant by tenant, through the VergeOS Manager and engine ID model.

Filed Under: Protection

August 26, 2026 by George Crump

Veeam Backup & Replication 13.1 moves workloads into VergeOS from vSphere, Hyper-V, Nutanix AHV, AWS, Azure, GCP, and physical servers. Consolidation means all of them.

Every VMware alternative on the market describes itself as a place to move vSphere workloads. That framing sells the platform short. The data center leaving VMware is rarely running only VMware. It runs a vSphere cluster, a Hyper-V cluster someone inherited, a few dozen AWS or Azure instances that began as a pilot, a Nutanix pod that arrived with an acquisition, and a rack of physical servers nobody ever virtualized. Infrastructure consolidation means bringing all of it onto one platform. With official VergeOS support in Veeam Backup & Replication 13.1, the tool that moves all of it is the backup tool the customer already owns.

Key Takeaways
  • Veeam Entire VM Restore brings workloads into VergeOS from any supported hypervisor, from AWS, Azure, or GCP, and from Veeam Agent backups of physical servers.
  • The migration path is a restore job the backup team has already rehearsed, run from the console they already operate.
  • VergeOS holds all of it: five infrastructure products in one code base, global deduplication and node-by-node scale for the mixed estate, and Virtual Data Centers that give each group of workloads its own performance guarantee and quality of service.

One Migration Path for Every Source

Official support arrived in Veeam Backup & Replication 13.1, initial release build 13.1.0.411, through the Veeam Universal Hypervisor API. VergeOS appears under Virtualization Platforms in the Veeam console and is added as a VergeOS Manager. On the Veeam side it is a native platform selection. On the VergeOS side, the oVirt-engine package, listed as oVirt API compatibility, is turned on through system updates in VergeOS 26.1.7 or later. From that point VergeOS is a restore target like any other platform Veeam protects.

Entire VM Restore is the feature that turns the backup console into a consolidation console. It takes a protected machine from any hypervisor Veeam supports, from AWS, Azure, or GCP, or from a physical server protected by Veeam Agent, and brings it up inside VergeOS. Each move is a restore job. The backup team has run restore jobs for years, tested them in audits, and documented them in runbooks. A migration that reuses that muscle memory removes the retraining, the second vendor, and the second project plan that stall most platform changes.

Key Terms
Veeam Universal Hypervisor API
The first-party Veeam interface through which VergeOS is integrated and shipped as a fully supported hypervisor in Veeam Backup & Replication 13.1.
Entire VM Restore
The Veeam recovery operation that brings a complete protected machine up on a target platform. On VergeOS it doubles as the migration path from any supported hypervisor, from AWS, Azure, or GCP, and from physical servers.
Veeam Agent
Veeam’s in-guest backup software for physical Windows and Linux servers. Its backups restore into VergeOS as virtual machines through Entire VM Restore.
VergeOS Manager
The object added under Virtualization Platforms in the Veeam console that represents a VergeOS system, or an individual tenant, to Veeam.
Virtual Data Center
A VergeOS construct that groups workloads with their own allocation of compute, storage, and networking, and the isolation and quality of service to keep one group from affecting another.
Global inline deduplication
VergeOS storage efficiency that removes duplicate blocks across the entire environment as data is written, so workloads from different sources share common data rather than each holding a full copy.

Where each workload comes from, and how it moves

Source Veeam path Result on VergeOS
vSphere, Hyper-V, Nutanix AHV, other supported hypervisors Entire VM Restore from the existing backup Virtual machine in a VergeOS Virtual Data Center
AWS, Azure, GCP instances Entire VM Restore from the cloud backup Virtual machine on servers already paid for
Physical Windows and Linux servers Veeam Agent backup, then Entire VM Restore Virtual machine, original server untouched until cutover

The Hyper-V Cluster and the Cloud Pilot

Most consolidation plans stop at vSphere and leave the rest of the estate where it sits. The Hyper-V cluster keeps running for the one application built on it. The AWS and Azure instances that started as a pilot now bill every month for steady-state workloads that belong on-premises. Each platform needs its own patching cycle, monitoring, skills, and protection policy, and each one keeps the infrastructure team fragmented.

Veeam moves each of those sources through the same restore job it uses for vSphere. The Hyper-V cluster retires and its hardware joins the VergeOS pool. The cloud instances return to servers the organization already paid for. The result is one platform to patch, one platform to protect, and one platform to staff, which is the outcome consolidation promised in the first place.

Physical Servers, the Consolidation Nobody Talks About

Bare metal servers waiting to be consolidated onto VergeOS with Veeam

Physical servers survive every virtualization wave for the same reason. The migration was never worth the risk for a system that has run for years. Veeam Agent changes the calculation. A physical Windows or Linux server protected by Veeam Agent restores into VergeOS as a virtual machine through the same Entire VM Restore path. The team restores it, validates the application, and cuts over on a schedule they control, with the original server untouched until they are satisfied.

That turns the last rack of standalone servers into VergeOS capacity instead of a permanent exception. It is the part of consolidation most VMware alternatives leave out, and it is the part that frees the most floor space, power, and support contracts.

Why VergeOS Is the Platform to Consolidate On

Moving every workload to one platform only pays if that platform can hold all of them. VergeOS consolidates five infrastructure products into a single software layer on standard hardware. Compute, storage, networking, protection, and management ship in one code base, so the platforms that moved in stop needing their own stacks, and the team stops maintaining five vendors’ worth of upgrade cycles.

Live Webinar · September 3

Veeam’s Role in a VMware Exit

Veeam’s Rick Vanover joins VergeIO’s Dave Vincent and George Crump. Dave adds VergeOS to a Veeam console, runs a first backup, and restores a workload into VergeOS from another platform. Thursday, September 3, 2026 at 2:00 PM ET / 11:00 AM PT.

Register Now

Efficiency and scale decide whether the consolidated estate fits. Global inline deduplication runs across the entire environment, so the Hyper-V images, the returning cloud instances, and the former physical servers share common blocks instead of each holding a full copy. Capacity and performance grow by adding a node to the pool, and a mixed pool of new and existing servers runs as one system, so the hardware freed by retiring the other platforms goes straight back to work.

Infrastructure consolidation of every platform onto VergeOS

Workloads from different sources arrive with different expectations, and Virtual Data Centers keep those expectations intact. Each Virtual Data Center receives its own allocation of compute, storage, and networking, with the isolation and quality of service to protect one group of workloads from another. The database that ran alone on a physical server keeps its performance guarantee. The cloud pilot that expects elastic capacity gets it. The inherited Hyper-V application runs in its own boundary with its own policies. One platform, with a defined home for every workload it absorbed.

The hardware math reinforces the timing. Conventional DRAM contract prices rose 93 to 98 percent quarter over quarter in the first quarter of 2026, and server DRAM is set to rise another 13 to 18 percent in the third quarter, according to TrendForce. Most VMware alternatives force a server refresh alongside the platform change. VergeOS runs on the servers already running production load, and deduplication reduces the memory footprint per workload, which extends the working life of DDR4 systems that otherwise drive a DDR5 purchase.

Two Layers Stay in Place

After the consolidation, Veeam keeps doing what enterprise backup was built for: Changed Block Tracking backups, file-level restore, and application-item recovery through Veeam Explorers. VergeOS provides infrastructure-scale protection as a core function through Virtual Data Center snapshots, ioReplicate, ioFortify, and ioGuardian. The two layers answer different failures, and organizations running both get depth neither produces alone.

Read the announcement: VergeIO Announces VergeOS Support in Veeam Backup & Replication. Ready to see the consolidated estate on your own hardware? Take a Test Drive Today.

Frequently Asked Questions
Which sources can Veeam restore into VergeOS?
Any hypervisor Veeam supports, AWS, Azure, and GCP instances, and physical servers protected by Veeam Agent, all through Entire VM Restore.
What versions do I need?
Veeam Backup & Replication 13.1 or later on the Veeam side, and VergeOS 26.1.7 or later with the oVirt-engine package turned on. VergeOS 26.1.8 is the current production release.
Does my existing Veeam licensing change?
The existing deployment adds a platform. The product, the licensing, the policies, and the retention schedules stay as they are.

Filed Under: VMwareExit

  • « Go to Previous Page
  • Page 1
  • Page 2
  • Page 3
  • Page 4
  • Page 5
  • Interim pages omitted …
  • Page 40
  • Go to Next Page »

855-855-8300

Get Started

  • Versions
  • Request Tour

VergeIO For

  • SAN Replacement
  • Solving Infrastructure Modernization Challenges
  • Artificial Intelligence
  • Hyperconverged
  • Server Room
  • Secure Research Computing

Product

  • Benefits
  • Documents
  • Architecture Overview
  • Use Cases
  • Videos

Company

  • Blog
  • Technical Documentation
  • Legal

© 2026 VergeIO. All Rights Reserved.