• Skip to main content
  • Architecture
    • Overview
      Learn about VergeOS’ unique unfied architecture that integrates virtualization, storage, networking, AI, backup and DR into a single data center operating system
    • Infrastructure Wide Deduplication
      VergeOS transforms deduplication from a storage-only commodity into a native, infrastructure-wide capability that spans storage, virtualization, and networking, eliminating hidden resource taxes
    • VergeFS
      VergeFS is a distributed, high-performance global file system integrated into VergeOS, unifying storage across nodes, tiers, and workloads while eliminating the need for external SANs
    • VergeFabric
      VergeFabric is VergeOS’s integrated virtual networking layer, delivering high-speed, low-latency communication across nodes while eliminating the complexity of traditional network configurations.
    • Infrastructure Automation
      VergeOS integrates Packer, Terraform, and Ansible to deliver an end-to-end automation pipeline that eliminates infrastructure drift and enables predictable, scalable deployments.
    • VergeIQ
      Unlock secure, on-premises generative AI—natively integrated into VergeOS. With VergeIQ, your enterprise gains private AI capabilities without the complexity, cloud dependency, or token-based pricing.
  • Features
    • Virtual Data Centers
      A VergeOS Virtual Data Center (VDC) is a fully isolated, self-contained environment within a single VergeOS instance that includes its own compute, storage, networking, and management controls
    • High Availability
      VergeOS provides a unified, easy-to-manage infrastructure that ensures continuous high availability through automated failover, storage efficiency, clone-like snapshots, and simplified disaster recovery
    • ioClone
      ioClone utilizes global inline deduplication and a blockchain-inspired file system within VergeFS to create instant, independent, space-efficient, and immutable snapshots of individual VMs, volumes, or entire virtual data centers.
    • ioReplicate
      ioReplicate is a unified disaster-recovery solution that enables simple, cost-efficient DR testing and failover via three‑click recovery of entire Virtual Data Centers—including VMs, networking, and storage.
    • ioFortify
      ioFortify creates immutable, restorable VDC checkpoints and provides proactive ransomware detection with instant alerts for rapid recovery and response.
    • ioMigrate
      ioMigrate enables large-scale VMware migrations, automating the rehosting of hundreds of VMs (including networking settings) in seconds with minimal downtime by seamlessly transitioning entire VMware environments onto existing hardware stacks.
    • ioProtect
      ioProtect offers near-real-time replication of VMware VMs—including data, network, and compute configurations—to a remote disaster‑recovery site on existing hardware, slashing DR costs by over 60% while supporting seamless failover and testing in an efficient, turnkey VergeOS Infrastructure.
    • ioOptimize
      ioOptimize leverages AI and machine learning to seamlessly integrate new and old hardware and automatically migrate workloads from aging or failing servers.
    • ioGuardian
      ioGuardian is VergeIO’s built-in data protection and recovery capability, providing near-continuous backup and rapid VM recovery during multiple simultaneous drive or server failures.
  • IT Initiatives
    • VMware Alternative
      VergeOS offers seamless migration from VMware, enhancing performance and scalability by consolidating virtualization, storage, and networking into a single, efficient platform.
    • Hyperconverged Alternative
      VergeIO’s page introduces ultraconverged infrastructure (UCI) via VergeOS, which overcomes HCI limitations by supporting external storage, scaling compute and storage independently, using existing hardware, simplifying provisioning, boosting resiliency, and cutting licensing costs.
    • SAN Replacement / Storage Refresh
      VergeIO’s storage by replacing aging SAN/NAS systems within its ultraconverged infrastructure, enhancing security, scalability, and affordability.
    • Infrastructure Modernization
      Legacy infrastructure is fragmented, complex, and costly, built from disconnected components. VergeOS unifies virtualization, storage, networking, data protection, and AI into one platform, simplifying operations and reducing expenses.
    • Secure Research Computing
      VergeIO's Secure Research Computing solution combines speed, isolation, compliance, scalability, and resilience in a cohesive platform. It’s ideal for institutions needing segmented, compliant compute environments that are easy to deploy, manage, and recover.
    • Venues, Remote Offices, and Edge
      VergeOS delivers resiliency and centralized management across Edge, ROBO, and Venue environments. With one platform, IT can keep remote sites independent while managing them all from a single pane of glass.
    • Fight Data Center Inflation
      DRAM, SSD and server prices keep climbing. VergeOS uses as much as 50% less RAM per VM than VMware, runs on the servers you already own, and moves cold data to low-cost hard drives.
  • Blog
      • Edge Disaster Recovery: Keep Customer-Facing Locations OpenEdge disaster recovery for stores and venues. VergeOS runs a site on one server, recovers it locally from snapshots and fails it over to the core.
      • VMware Migration Testing Is Critical to Completing Your ExitVMware migration testing decides whether your exit finishes. VergeOS keeps the VMware image, takes instant snapshots and isolates each workload in a VDC.
      • How to Use Hard Drive Tiering to Fight Data Center InflationHard drive tiering is back. See how VergeOS lets you pick each drive's tier, move it live, and put the long tail on $56/TB disk instead of $706/TB flash.
    • View All Posts
  • Resources
    • Become a Partner
      Get repeatable sales and a platform built to simplify your customers’ infrastructure.
    • Technology Partners
      Learn about our technology and service partners who deliver VergeOS-powered solutions for cloud, VDI, and modern IT workloads.
    • White Papers
      Explore VergeIO’s white papers for practical insights on modernizing infrastructure. Each paper is written for IT pros who value clarity, performance, and ROI.
    • In The News
      See how VergeIO is making headlines as the leading VMware alternative. Industry analysts, press, and partners highlight our impact on modern infrastructure.
    • Press Releases
      Get the latest VergeOS press releases for news on product updates, customer wins, and strategic partnerships.
    • Case Studies
      See how organizations like yours replaced VMware, cut costs, and simplified IT with VergeOS. Real results, real environments—no fluff.
    • Webinars
      Explore VergeIO’s on-demand webinars to get straight-to-the-point demos and real-world infrastructure insights.
    • Documents
      Get quick, no-nonsense overviews of VergeOS capabilities with our datasheets—covering features, benefits, and technical specs in one place.
    • Videos
      Watch VergeIO videos for fast, focused walkthroughs of VergeOS features, customer success, and VMware migration strategies.
    • Technical Documentation
      Access in-depth VergeOS technical guides, configuration details, and step-by-step instructions for IT pros.
  • How to Buy
    • Schedule a Demo
      Seeing is believing, set up a call with one of our technical architects and see VergeOS in action.
    • Versions
      Discover VergeOS’s streamlined pricing and flexible deployment options—whether you bring your own hardware, choose a certified appliance, or run it on bare metal in the cloud.
    • Test Drive – No Hardware Required
      Explore VergeOS with VergeIO’s hands-on labs and gain real-world experience in VMware migration and data center resiliency—no hardware required
  • Company
    • About VergeIO
    • Support
      Get fast, expert help from VergeIO’s support team—focused on keeping your infrastructure running smoothly.
    • Careers
      Join VergeIO and help reshape the future of IT infrastructure. Explore open roles and growth opportunities.
  • 855-855-8300
  • Contact
  • Search
  • 855-855-8300
  • Contact
  • Search
  • Architecture
    • Overview
    • VergeFS
    • VergeFabric
    • Infrastructure Automation
    • VergeIQ
  • Features
    • Virtual Data Centers
    • High Availability
    • ioClone
    • ioReplicate
    • ioFortify
    • ioMigrate
    • ioProtect
    • ioOptimize
    • ioGuardian
  • IT Initiatives
    • VMware Alternative
    • Hyperconverged Alternative
    • SAN Replacement / Storage Refresh
    • Infrastructure Modernization
    • Secure Research Computing
    • Venues, Remote Offices, and Edge
    • Fight Data Center Inflation
  • Blog
  • Resources
    • Become a Partner
    • Technology Partners
    • White Papers
    • In The News
    • Press Releases
    • Case Studies
    • Webinars
    • Documents
    • Videos
    • Technical Documentation
  • How to Buy
    • Schedule a Demo
    • Versions
    • Test Drive – No Hardware Required
  • Company
    • About VergeIO
    • Support
    • Careers
×
  • Architecture
    • Overview
    • VergeFS
    • VergeFabric
    • Infrastructure Automation
    • VergeIQ
  • Features
    • Virtual Data Centers
    • High Availability
    • ioClone
    • ioReplicate
    • ioFortify
    • ioMigrate
    • ioProtect
    • ioOptimize
    • ioGuardian
  • IT Initiatives
    • VMware Alternative
    • Hyperconverged Alternative
    • SAN Replacement / Storage Refresh
    • Infrastructure Modernization
    • Secure Research Computing
    • Venues, Remote Offices, and Edge
    • Fight Data Center Inflation
  • Blog
  • Resources
    • Become a Partner
    • Technology Partners
    • White Papers
    • In The News
    • Press Releases
    • Case Studies
    • Webinars
    • Documents
    • Videos
    • Technical Documentation
  • How to Buy
    • Schedule a Demo
    • Versions
    • Test Drive – No Hardware Required
  • Company
    • About VergeIO
    • Support
    • Careers

VMware

October 20, 2026 by George Crump

VergeOS 26.2 moves the data faster. Snapshots and virtual data centers prove each workload runs before it goes into production.

VMware migration testing is one of the most important parts of selecting and moving to a VMware alternative. I mean the big migration, when you move everything into production. That is a different job from moving a few VMs during a proof of concept, which I covered in How to Create a VMware Migration Test. As we will show in our webinar, Finish the VMware Exit, the latest VergeOS release raises the bar for fully exiting VMware.

In our lab, transfer performance runs 2.2 times faster than VergeOS 26.1.8, so even large workloads complete their move. VergeFS now supports shared disks for Microsoft Failover Clustering. That means clustered applications like SQL Server and file services migrate too. These changes move data and applications into VergeOS, where you enjoy our simple server-based licensing model. You also get the operational simplicity of a unified codebase.

Key Takeaways
  • VergeOS stores the original VMware image and offers a snapshot when you create the VM, so a failed test sends you back to the original state without re-copying data.
  • VergeOS snapshots take less than a second, use almost no capacity, and stand independent of each other, so any snapshot can become the new source.
  • Placing each migrated workload in its own Virtual Data Center isolates VMware migration testing, caps CPU and GPU use, and lets many testers work in parallel.

Why VMware Migration Testing Decides the Exit

Completing the move to a VMware alternative is about more than getting data and applications from point A to point B. Everything has to work when it gets there. Migration capability belongs on the short list of requirements for any VMware alternative, but moving the data only proves the platform can receive it. VMware migration testing proves the applications run, which is critical, and VergeOS uniquely excels here.

Key Terms
VMware Migration Testing
Validating that each migrated workload runs correctly on the new platform before it goes into production.
Virtual Data Center (VDC)
The VergeOS implementation of multi-tenancy. A VDC holds VMs, networks, storage, and policies in an isolated environment that IT manages as one unit.
Independent Snapshot
A VergeOS snapshot with no dependency on other snapshots or the original source. Any snapshot can become the new source, and you can delete the rest.

Snapshots Make VMware Migration Testing Safe

VergeOS Keeps the Original VMware Image

After your VMware data set arrives on VergeOS, it stays in its original VMware format at first. VergeOS stores the VMware image. If something goes wrong in testing, you return to it without re-copying data from the VMware environment. Then, when you create that VM under VergeOS, it asks whether you want to create a snapshot. That gives you a second copy of the original state before the first test runs.

Snapshots Built for Aggressive Testing

Those snapshots let you test aggressively. You can take as many as you want. Each takes less than a second, with almost no capacity impact. VergeOS snapshots are also independent of each other and of the original source. For example, you can make snapshot 100 the new source and delete all the other snapshots. The same cleanup on a dedicated external array can take hours, or even days, to reclaim space.

Snapshots make VMware migration testing safeSNAPSHOTS · SAFE TESTINGVMware VMsource environmentVergeOSOriginal VMware imageKept on VergeFS. Revert without re-copying.VM created under VergeOSCreate a snapshot?Yes ✓SNAPSHOTS · UNDER A SECOND EACH#1#2#3#4#5#6#7…#99#100New sourceDelete the rest. No chain to unwind.CAPACITY IMPACTalmost none

Virtual Data Centers for VMware Migration Testing

The next way VergeOS excels is our Virtual Data Center (VDC) technology, our take on multi-tenancy. It is also the most distinctive and underused. Most customers use VDCs in production. Cloud service providers create a tenant for each client. Enterprises use VDCs to isolate mission-critical workloads from standard business workloads. That same isolation makes VDCs ideal for testing.

One Workload, One VDC

A testing best practice is to migrate by workload instead of one VM at a time. We suggest that each workload you migrate goes into its own VDC. That isolates it from the workloads you have already migrated, which ideally sit in their own VDCs. Now you can test the latest workload relentlessly without impacting other workloads. You can also control how much CPU and GPU a workload gets, so a runaway process can’t steal resources from workloads you have already certified and are now running in production on VergeOS.

One workload, one VDCONE WORKLOAD, ONE VDCVergeOSVDCProd ✓VDCProd ✓VDCProd ✓Test VDC · newest workloadVMVMVMtestCPUGPUA runaway process stops at its cap.Certified workloads keep their resources.

Mass VMware Migration Testing with VDC Snapshots

You can take VDCs a step further. First, migrate the workload into a VDC with all of its special network and configuration settings intact. Next, make five or ten snapshots of it. Then assign each one to a fellow IT staffer, or even an application stakeholder, for mass testing.

The IP addresses and other settings within each VDC can be the same. The VDC technology keeps them isolated, so testers work without IP address conflicts. If one tester breaks the application, the other testers keep working. If another tester creates the perfect configuration, you promote that version. Then you delete all the others, including the original.

Mass VMware migration testing with VDC snapshotsMASS TESTING · VDC SNAPSHOTSOrder app VDCmigrated workload · 10.0.0.105 SNAPSHOTSCopy 1Order app10.0.0.10ITCopy 2Order app10.0.0.10brokenDBACopy 3Order app10.0.0.10App ownerCopy 4Order app10.0.0.10ITCopy 5Order app10.0.0.10Stakeholderothers unaffectedbest configPromoted copyFive copies of one workload. Same IPs, no conflicts.

Prove the Cluster Before Cutover

This approach pays off most with clustered applications. Migrate a SQL Server failover cluster into its own VDC, snapshot it, and hand copies to the DBA team and the application owners. One tester shuts down a cluster node. That tester confirms the shared disk on VergeFS changes hands through SCSI-3 Persistent Reservations and the database comes back online. Another runs the month-end workload against the cluster. All of this happens before production depends on the cluster, giving application owners the confidence they need to approve cutover.

Prove the cluster before cutoverPROVE THE CLUSTERTest VDC · SQL Server clusterSQL Node 1ownerSQL Node 1shut down ✕SQL Node 2standbySQL Node 2new ownerVergeFS shared diskSCSI-3 Persistent ReservationsDatabase onlineFailover proven before production depends on it.

Add AI to Your VMware Migration Testing Team

With the GPU management built into VergeOS, you can even run a local AI LLM as part of the testing team. It puts the application through its paces alongside your staff and stakeholders. The model runs on your own GPUs inside its own VDC and works through test cases around the clock. Your application data stays inside your environment.

AI on the VMware migration testing teamAI ON THE TESTING TEAMTest VDCGPUlocal LLMMigratedappTEST CASES · AROUND THE CLOCK✓ Logins and permissions✓ Month-end batch run✓ Reports and integrations✓ Edge cases at 3:00 AMYour GPUs. Your data stays in your environment.
Live Webinar · October 22 · 12:00 PM CT
Finish the VMware Exit
Aaron Richman and Dave Vincent demonstrate faster migration, Failover Clustering on VergeFS, and VDCs for testing and protection.
Register

Finish the VMware Exit

From Tested to Production

The certified VDC becomes production. You put into service the environment your testers approved, with its VMs, network settings, and configuration. Nothing gets rebuilt or re-entered between the last test and go-live. When the next workload arrives, you start the process again in a new VDC. The production VDCs you already certified stay untouched.

From tested to productionFROM TESTED TO PRODUCTIONTestingProductionCertified VDCtests passed ✓Same VDC, same settings. Nothing rebuilt.

Parallel Testing Shortens the Exit

Testing is where most migration timelines slip. Parallel VMware migration testing changes that. When several testers and an AI model work against identical copies of the same workload, serial testing that delays cutover shrinks. Each workload reaches production sooner, the next one starts in its own VDC, and the last workloads leave VMware on a schedule you control instead of one the testing backlog sets.

Parallel testing shortens the exitPARALLEL TESTING SHORTENS THE EXITOne tester at a timecutoverParallel VMware migration testingtesters + AI model on identical VDC copiescutoverEach workload reaches production sooner.

See VergeOS 26.2 Live

VergeOS 26.2 moves the data faster and brings clustered applications across. Its snapshots and VDCs let you prove everything works once it arrives. The VergeOS 26.2 datasheet covers everything in the release. Leave No VM Behind explains how 26.2 moves the last workloads off VMware. Aaron Richman and Dave Vincent demonstrate it live on Thursday, October 22, 2026, at 12:00 PM CT. Register for Finish the VMware Exit, or schedule a technical whiteboard session to plan your own migration and testing approach.

Finish the VMware exitFINISH THE VMWARE EXITVMwareVergeOSClustered SQL Server included.LIVE DEMO · OCT 22 · 12:00 PM CT

VMware Migration Testing on VergeOS

Testing NeedWhat VergeOS Provides
Fall back to the originalStored VMware image plus a snapshot at VM creation
Many test iterationsSnapshots in under a second with almost no capacity impact
Keep the winner, drop the restIndependent snapshots, any one can become the new source
Protect production during testsOne VDC per workload with CPU and GPU limits
Parallel testersVDC snapshots per tester with the same IP addresses
Clustered applicationsFailover tests on VergeFS shared disks inside an isolated VDC
Go-liveThe certified VDC becomes production, with nothing rebuilt
Frequently Asked Questions
What is VMware migration testing?
It validates each migrated workload on the new platform before it goes into production. That covers application behavior, network configuration, and performance.
Can I return to the original VMware VM if a test fails?
Yes. VergeOS stores the VMware image and offers a snapshot when you create the VM. You return to the original state without re-copying data from VMware.
Why put each migrated workload in its own VDC?
A VDC isolates the workload from everything already in production and caps its CPU and GPU use. It also lets several testers work on copies with identical IP addresses and no conflicts.

Next Steps

The datasheet, the live demonstration and the first 26.2 blog are one click away.
Datasheet
VergeOS 26.2
Faster VMware migration, Failover Clustering on VergeFS and single-server distributed data centers.
Live Webinar · October 22
Finish the VMware Exit
Aaron Richman and Dave Vincent demonstrate the release. 12:00 PM CT.
Blog
Leave No VM Behind
How VergeOS 26.2 moves clustered SQL Server and the last workloads off VMware.

Filed Under: VMwareExit Tagged With: migration testing, snapshots, SQL Server, VergeOS 26.2, virtual data center, VMware, VMware exit, VMware migration

October 13, 2026 by George Crump

A complete VMware migration now includes clustered SQL Server. VergeOS 26.2 cuts migration transfer time by about 55 percent and protects mission-critical workloads inside isolated virtual data centers.

A complete VMware migration moves every workload, including the clustered SQL Server instances that nobody wants to touch. Most VMware exits start with the easy virtual machines. File servers, web tiers and test systems move quickly. Then the project stalls on two problems: the cutover window for large, busy VMs and the Windows workloads that depend on Microsoft Failover Clustering. The organization ends up running two hypervisors and paying VMware to protect a handful of servers. VergeOS 26.2 solves both problems, so IT can finish a complete VMware migration.

Key Takeaways
  • VergeOS 26.2 adds asynchronous I/O to NBD transfers, so initial and final migration transfers finish in about 55 percent less time and cutover windows shrink.
  • Microsoft Failover Clustering now runs on VergeFS with shared disks and SCSI-3 Persistent Reservations, so a complete VMware migration includes clustered SQL Server.
  • Virtual data centers encapsulate those workloads for portable test and DR, and isolate them from the rest of the environment.

Why a Complete VMware Migration Stalls

A complete VMware migration stalls when clustered SQL Server stays behind on VMware VMware VMware Alternative Clustered SQL Migration progress Stalls at the last workloads

The last workloads in a VMware estate are the ones the business depends on most. They run the ERP database, the order system and the applications with uptime commitments written into contracts. Two issues hold them back. Large VMs with high change rates need a cutover window that application owners refuse to approve. Windows workloads protected by Microsoft Failover Clustering need a shared disk with SCSI-3 Persistent Reservations, a requirement that has historically pushed customers toward a dedicated storage array.

When those requirements go unmet, IT keeps a small VMware cluster running next to the new platform. That choice means two management interfaces, two support contracts and a VMware renewal sized around the servers that matter to the business. Many teams renew VMware for just one year to buy time, and the renewal repeats every year the hard workloads stay put. The exit stays incomplete, and the savings that justified it shrink.

Shorter Cutover for a Complete VMware Migration

VergeOS 26.2 cuts migration transfer time by about 55 percent compared to the previous VergeOS release Migration transfer time Previous VergeOS release VergeOS 26.2 About 55% less time 2.2x faster NBD transfers

The VergeOS VMware migration service has used changed block tracking for years. First, it copies the full VM with the source still running. Then it sends only the blocks that changed since the last pass. At cutover, the source VM powers off, the last changed blocks transfer, and the VM boots on VergeOS. Version 26.2 adds asynchronous I/O to its network block device (NBD) transfers, so both the initial full copy and the final transfer move faster. In VergeIO lab testing against VergeOS 26.1.8, transfers ran 2.2 times faster, cutting transfer time by about 55 percent.

A cutover that fits inside a standard maintenance window gets approved. One that stretches past it gets deferred, and deferred workloads are how VMware exits stall.

Mission-Critical Windows Workloads on VergeFS

SQL Server Failover Cluster Instances and clustered file servers rely on a shared disk that every cluster node can reach. Microsoft Failover Clustering also uses SCSI-3 Persistent Reservations to control which node owns that disk at any moment. VergeOS 26.2 delivers both inside VergeFS, the storage layer built into VergeOS. VergeFS aggregates the drives inside each server into a single high-performance pool, so the cluster gets its shared disk from the same servers that run it.

Clustered SQL Server now moves with the rest of the estate. For the workloads that kept VMware in the data center, a complete VMware migration is finally on the table.

Three VMware hosts in production Drain host 3 with vMotion Install VergeOS on host 3 Full copy of host 2’s workloads into VergeOS Validate the copies on VergeOS Incremental pass: changed blocks only Cutover: host 2’s workloads now run on VergeOS Move SQL node B to host 1 with vMotion Install VergeOS on host 2 Balance workloads across both VergeOS hosts Full copy of host 1’s workloads into VergeOS Validate, then send changed blocks only Cutover: only the SQL cluster remains on VMware Last move: the SQL cluster and its shared disk Final pass, then cutover to a VergeFS shared disk Install VergeOS on host 1 and retire the array Same three servers, one VergeOS cluster Add File node B: a file cluster with no new hardware VMware ESXiHost 1 VergeOSHost 1 VMware ESXiHost 2 VergeOSHost 2 VMware ESXiHost 3 VergeOSHost 3 Web 1 Web 2 File App 1 App 2 Print Dev Test SQL node A SQL node B App 1 App 2 Print Test Web 1 Web 2 FileFile node A Dev SQL node A SQL node B Storage array | shared disk VergeFS shared disk spans hosts 2 and 3 | SCSI-3 PR VergeFS spans all three hosts | SCSI-3 PR shared disk File node B LEAVE NO VM BEHIND | ONE CLUSTER, SAME SERVERS, NO ARRAY
One host at a time on the same servers. General workloads move first, and the SQL Server failover cluster and its shared disk move last, onto VergeFS. Once the move is complete, the file server becomes a cluster with no new infrastructure.

Protect Mission-Critical Workloads After a Complete VMware Migration

VergeOS virtual data centers (VDCs) give these workloads a home of their own. A VDC encapsulates virtual machines, virtual networks, storage and policies into a single object that IT manages as a unit. The clustered database, its application servers and the network that connects them all live inside one VDC.

A VergeOS virtual data center encapsulates mission-critical workloads after a complete VMware migration for test clones, DR replication and ransomware isolation Virtual Data Center SQL Cluster App Servers Virtual network Storage and policies Test cloneSame addressing, isolated network DR siteWhole VDC replicated as one unit Ransomware stops at the VDC boundary

Portable for Test and DR

IT snapshots, clones and replicates the entire VDC as one object. For example, cloning a production VDC creates a copy of the application environment, network configuration included, for testing patches, upgrades or a new SQL Server version without touching production. The clone keeps its internal addressing inside its own isolated network, so nobody re-addresses servers for a test lab. For disaster recovery, IT replicates the VDC to a second VergeOS site and brings up the whole application environment there with its networking intact.

Isolated from Ransomware

Each VDC runs in its own network space, separate from other VDCs and from the host environment. Ransomware that compromises a workstation or a general-purpose server elsewhere reaches the VDC holding the clustered database only through the paths IT explicitly allows. That boundary limits lateral movement, the technique attackers use to spread from an initial foothold to the systems that hold the most valuable data. Frequent VergeOS snapshots of the VDC also give IT a clean, complete point to recover from.

Live Webinar · October 22 · 12:00 PM CT
See VergeOS 26.2 Live
Aaron Richman and Dave Vincent demonstrate faster migration, Failover Clustering on VergeFS and VDC protection.
Register
Key Terms
Network Block Device (NBD)
The transport VergeOS uses to read VM disks from VMware during migration, with changed block tracking limiting later passes to the blocks that changed.
SCSI-3 Persistent Reservations
The disk-locking mechanism Microsoft Failover Clustering uses to control which node owns a shared disk.
Virtual Data Center (VDC)
A VergeOS object that encapsulates VMs, networks, storage and policies so IT manages, protects and moves them as one unit.

Before and After VergeOS 26.2

WorkloadWhat Held It on VMwareVergeOS 26.2
Large, busy VMsCutover window too longAsynchronous I/O on NBD cuts transfer time by about 55 percent
Clustered SQL ServerShared disk with SCSI-3 PRFailover Clustering on VergeFS
Critical app environmentsHard to clone, test and recover as a unitVDC snapshots, clones and replication

Finish Your Complete VMware Migration

VergeOS 26.2 removes the two most common reasons VMware migrations stop short. Once the workloads move, VDCs keep them portable and isolated. The VergeOS 26.2 datasheet covers everything in the release. Aaron Richman and Dave Vincent demonstrate it live on Thursday, October 22, 2026, at 12:00 PM CT. Register for the webinar. To scope your own exit, start with the VMware Exit Readiness Assessment or schedule a technical whiteboard session.

Frequently Asked Questions
Can a complete VMware migration include clustered SQL Server?
Yes. VergeOS 26.2 runs Microsoft Failover Clustering on VergeFS, which provides the shared disk and SCSI-3 Persistent Reservations from the drives inside the VergeOS servers.
How does VergeOS 26.2 shorten cutover?
Changed block tracking keeps the final transfer small, and asynchronous I/O on NBD cuts the time for both transfers by about 55 percent.
What does a virtual data center add for mission-critical workloads?
A VDC lets IT clone the full application environment for testing, replicate it for DR, and isolate it from other workloads to limit ransomware spread.

Next Steps

The datasheet, the live demonstration, the VDC overview and an exit readiness check are one click away.

Datasheet
VergeOS 26.2
Faster VMware migration, Failover Clustering on VergeFS and single-server distributed data centers.
Live Webinar · October 22
See VergeOS 26.2 Live
Aaron Richman and Dave Vincent demonstrate the release. 12:00 PM CT.
Platform
VergeOS Virtual Data Centers
Encapsulate, clone, replicate and isolate entire application environments.
Assessment · 3 Minutes
VMware Exit Readiness Assessment
Check your pain points, see which part of VergeOS addresses each one and get a live savings estimate.

Filed Under: VMwareExit Tagged With: ransomware, SQL Server, VergeOS 26.2, virtual data center, VMware, VMware exit, VMware migration

October 12, 2026 by George Crump

Press Release

VergeOS 26.2 makes VMware migrations 120% faster, brings Microsoft Failover Clustering to VergeFS, and extends to single-server distributed data centers.

ANN ARBOR, Mich., October 13, 2026 – VergeIO, the infrastructure software company, today announced the immediate availability of VergeOS 26.2. VergeIO customers use VergeOS to exit VMware, fight data center inflation, support distributed data centers, and prepare their infrastructure and their organization for private AI, eliminating per-token costs.

What’s new in VergeOS 26.2

  • Faster VMware migration. Initial and final transfers now run 120% faster.
  • Mission-critical Windows workloads. Microsoft Failover Clustering now runs on VergeFS.
  • Single-server distributed data centers. Remote sites need only one server with two network connections.

Faster VMware migration

The VergeOS VMware migration service has delivered rapid migrations for years through changed block tracking, which keeps cutover time short. VergeOS 26.2 adds asynchronous I/O to its network block device (NBD) transfers, making both the initial full backup and the final transfer 120% faster and shortening cutover even further.

Same VMware workload, two VergeOS releasesVergeOS 26.2 finishes in less than half the timeVMware ESXiVM 1VM 2VM 3VM 4VM 5VM 6VergeOSVM 1VM 2VM 3VM 4VM 5VM 6VergeOS 26.1DoneVergeOS 26.2 | asynchronous I/O for NBDDone120% faster2.2 times the transfer speed of VergeOS 26.1INITIAL FULL BACKUP | FINAL TRANSFER | 120% FASTER
The same VMware workload on VergeOS 26.1 and 26.2. Bar lengths reflect the measured 2.2x speedup.

A complete exit for mission-critical workloads

Mission-critical Windows workloads like Microsoft SQL Server typically rely on Microsoft Failover Clustering, which requires a shared disk and SCSI-3 Persistent Reservations. That requirement has often led customers to a dedicated storage array, stalled many VMware migrations, or left customers running two hypervisors. VergeOS 26.2 now supports Microsoft Failover Clustering within VergeFS, its internal storage capability, which aggregates commodity drives inside servers into a highly scalable, high-performance vSAN.

A VMware estate: general VMs and a SQL cluster The first migration waves move the general VMs The SQL cluster stays behind on its shared disk Two platforms, and the VMware renewal is still due VergeOS 26.2 puts a SQL node on each server The ESXi host converts to a VergeOS server VMs rebalance across three VergeOS servers VMware ESXiProduction VergeOSServer 3 VergeOSServer 1 VergeOSServer 2 Storage array | shared disk VergeFS shared disk spans both servers | SCSI-3 PR VergeFS shared disk spans all three servers | SCSI-3 PR VM 1 VM 2 VM 3 VM 4 SQL node A SQL node B VMware renewal still due ONE PLATFORM | NO SECOND RENEWAL | NO ARRAY
The last workloads decide whether the VMware renewal goes away.

Single-server distributed data centers

Distributed architectures like retail point-of-sale often run single-server data centers that replicate back to a core VergeOS implementation. VergeOS 26.2 lowers the requirements for these sites to one server with two network connections and no core network, so customers can bring those locations along in their VMware exit.

“VergeIO is focused on simplifying infrastructure design and operations by helping customers exit legacy stacks, reuse hardware to combat data center inflation, manage any number of distributed data centers, and prepare for on-premises AI workloads. Today’s release lets IT execute a faster, less disruptive, and more complete VMware exit.”

Parag Patel, CEO of VergeIO

Availability and live webinar

VergeOS 26.2 is available now. For details on each capability, see the VergeOS 26.2 datasheet. Aaron Richman, Field Evangelist, and Dave Vincent, Technical Solutions Strategist, will explain and demonstrate its capabilities in a live webinar on Thursday, October 22, at 12:00 PM CT. Register for the webinar.

About VergeIO

VergeOS is infrastructure software that customers use to replace VMware, fight data center inflation, support distributed data centers, and prepare their infrastructure for AI and private AI workloads. It is a single piece of software for the entire infrastructure that runs on bare metal on the servers the organization already owns. It can mix vendors and CPU generations within the same instance and helps customers run private AI on GPUs they already own, avoiding expensive token costs and maintaining data sovereignty. VergeIO is headquartered in Ann Arbor, Michigan. Learn more at verge.io.

Media contact

George Crump
CMO
VergeIO
[email protected]

###

Filed Under: Press Release Tagged With: Edge, Migration, Press Release, SQL Server, VergeOS, VergeOS26dot2, VMware, VMware exit, vSAN

September 17, 2026 by George Crump

Hardware fails whether it is new or refurbished. VergeOS turns drive and server failures into routine events, which makes refurbished hardware a practical way to fund the VMware exit.

Refurbished hardware makes financial sense for a VMware exit, but IT teams then ask, “What happens when a used drive or server fails?” Hypervisor license costs have skyrocketed over the past two years but hardware always costs more than the hypervisor license, and the 2026 memory and flash price spike has widened that gap. Many migration projects now stall at finance review. Reusing the servers already on the floor and adding refurbished drives brings the budget back within reach, provided the platform treats hardware failure as routine.

Key Takeaways
  • Every drive and server fails eventually, new or refurbished, so resiliency belongs in the software.
  • VergeOS keeps workloads running through drive and server failures, holds data online past the resiliency factor with ioGuardian, and recovers VMs and files from snapshots at no additional software cost.
  • The on-demand Premier Connects session shows each failure live, from a pulled drive to a full data center failover.

Why Refurbished Hardware Makes IT Nervous

Traditional Recovery PathDrive failsRAID rebuild startsSecond drive failsbefore the rebuild finishesArray goes offlineworkloads stopRestore from backupthe recovery clock starts

In a three-tier data center, the storage array protects blocks with RAID, and a second drive failure during a rebuild turns into a backup restore job with significant downtime. Legacy HCI moved storage into the servers and added workload restart, yet recovery still lives in a separate backup product on separate hardware, with its own license and its own console. In both designs, a failure that exceeds the protection level hands the problem to the backup team and starts the recovery clock.

Buying premium new hardware became the standard way to push that moment further out, which ties resiliency to a purchase order finance now keeps rejecting.

Resiliency and Protection for Refurbished Hardware

The Price of ResiliencyCostResiliencyRAID 5RF2RF3Longer retentionBubble size = performance impact

Resiliency keeps an application running with zero downtime and zero data loss when a component fails. Protection restores data after resiliency runs out. Every environment has a resiliency limit, and raising it costs money. RAID 5 costs the least, offers the least resiliency, and imposes the highest performance penalty. RF2 costs more with almost no performance impact, RF3 costs more again with none, and longer snapshot retention sits at the top of the scale.

VergeOS changes where that money goes. Each step up is a setting in the platform, so climbing the scale costs capacity instead of another software license. Refurbished drives make that capacity affordable. An organization can run RF3 with longer retention on the budget that once bought a smaller pool of new drives.

Saratoga Casino Holdings runs this model in production. The company moved to VergeOS on CXTEC® equal2new® refurbished servers and removed roughly $50,000 a year in Pure Storage array maintenance. Read the Saratoga Casino Holdings case study for the full story.

Resilient: Refurbished Hardware Keeps the Workload Running

VergeOS runs compute, storage, networking, and data protection in one code base. With RF2 or RF3 set per workload, a failed drive is invisible to the application. A server failure triggers an automatic restart of its workloads on the surviving nodes, with no operator in the loop. The age of the failed part makes no difference, so refurbished hardware delivers the same outcome as new hardware.

RF vs. RAID

RF vs. RAIDShare of raw capacityRAID 5Usable20-25%RAID 6Usable25-33%RF2Usable2nd copyGlobal inline dedup recovers most of the gapPerformanceNormalDrive failedRAID 5/6Parity penaltySevereRF2Almost noneNone

At first glance, RF2 looks like it doubles capacity consumption, since every block exists twice. The real gap is much smaller. RAID 5 gives up 20 to 25 percent of raw capacity to parity in a typical four or five drive group, and RAID 6 gives up 25 to 33 percent with two parity drives in a six to eight drive group. VergeOS global inline deduplication makes up for most of the difference. It works across every drive and server in the environment, so a block shared by many VMs is stored once.

Performance favors RF from the start. During normal production operations, RF2 has almost no performance impact, and it improves read performance, since VergeOS serves reads from multiple drives and servers. A failed drive leaves performance where it was, with the surviving copy answering every request. RAID 5 and RAID 6 pay a parity penalty on writes in normal operation, and the penalty grows sharply in a degraded state, when the array reconstructs data on every read and runs a rebuild at the same time. That degraded window is exactly where refurbished hardware puts the most pressure on a design, a point that has been characterized as storage recovery architecture mattering more than drive reliability.

Repairable: Data on Refurbished Hardware Stays Online Past the Limit

The hardest objection to refurbished hardware is a second failure before the first repair finishes. Two drives failing at once exceed RF2, and in most designs that means a restore. ioGuardian covers that window. A dedicated server, the ioGuardian target, delivers missing data segments to VMs in real time, so workloads keep running as the system repairs itself. The mechanics are covered in detail in Surviving Cascading Drive Failure.

▶
On-Demand Webinar · Premier Connects
Exit VMware to Resilient HCI
Aaron Richman and David Vincent fail drives, a server, and a full virtual data center live on VergeOS.
Watch Now →

Recoverable: Recovery From the Same Interface

Recovery Inside the PlatformVM volumeSnapshot 1Snapshot 2Snapshot 3Each ioClone snapshot is a standalone copyVirtual data centerVMs, network,storage settingsDR siterefurbishedhardwareThe whole environment fails over as one object

Some events have nothing to do with hardware, like an administrator deleting a VM or a user removing files. VergeOS snapshots use ioClone and behave as independent copies instead of a dependent chain, so retention is bounded by capacity. A deleted VM comes back instantly from a snapshot, and individual files recover through a hot plug drive attached to the running VM. Recovery works the same way on refurbished hardware as it does on new servers.

For a site-level event, a virtual data center encapsulates the VMs, networking, and storage settings, and it fails over to the DR site as one object. The DR site can run on refurbished hardware too.

How Each Design Handles Failure

FailureThree-TierLegacy HCIVergeOS
One driveRAID rebuild on the arrayHCI storage layerRF2 or RF3, workload unaffected
One serverHypervisor HA restartWorkload restartAutomatic restart on surviving nodes
Beyond the protection levelRestore from backup productRestore from backup productioGuardian keeps data online
Deleted VM or filesSeparate backup productSeparate backup productioClone snapshot, hot plug drive
Site lossArray replication plus runbooksReplication plus separate DR toolingVirtual data center failover
Protection software costSeparate licensesSeparate licensesIncluded in VergeOS
Key Terms
Resiliency factor (RF2, RF3)
The number of synchronous copies VergeOS keeps of each block, set per workload. RF2 survives one failure and RF3 survives two, on new or refurbished hardware.
ioGuardian
The VergeOS capability that delivers missing data segments to VMs in real time during multiple drive or server failures, using a dedicated server called the ioGuardian target.
ioClone
The VergeOS snapshot technology. Each snapshot behaves as an independent copy, so retention is bounded by capacity.
Virtual data center (VDC)
A single object that encapsulates VMs, networking, and storage settings, so the whole environment replicates and fails over together.

See Every Failure Now

The Premier Connects session, Exit VMware to Resilient HCI: Integrated Data Protection, Faster Recovery, and Built-In DR, walks through each stage in order. Aaron Richman, Field Evangelist, explains each feature, and David Vincent, Technical Evangelist, demonstrates it on a running VergeOS environment. The demos escalate from a pulled drive and a failed server to two failed drives, a deleted VM and files, and a full virtual data center failover. Watch the on-demand session to see how refurbished hardware made resilient changes the math on your VMware exit.

Frequently Asked Questions
Is refurbished hardware reliable enough for production?
Every drive and server fails eventually, new or refurbished. VergeOS plans for that failure with RF2 or RF3, ioGuardian, and snapshots, so production reliability comes from the platform instead of the age of the part.
What do these resiliency capabilities cost?
RF2 and RF3, ioGuardian, unlimited snapshots, instant recovery, and virtual data center failover come with VergeOS at no additional software cost.
Do I still need a backup product?
A backup product becomes optional, used for GUI-based single file recovery and long term archiving. VergeOS supports the backup platforms customers already run, including Veeam.

Next Steps

The on-demand session, the architecture behind it, and a customer running VergeOS on refurbished hardware are one click away.

On-Demand Webinar
Exit VMware to Resilient HCI
Live drive, server, and data center failures on VergeOS, from a pulled drive to VDC failover.
White Paper
Beyond the Hypervisor Swap
The VergeOS architecture in depth, including resiliency, recovery, and disaster recovery.
Case Study
Saratoga Casino Holdings
VergeOS on CXTEC® equal2new® refurbished servers, with Pure Storage array maintenance removed.

Filed Under: Storage, VMwareExit Tagged With: data protection, Disaster Recovery, ioGuardian, refurbished hardware, refurbished SSDs, RF3, VergeOS, VMware, VMware alternative, VMware exit

August 17, 2026 by George Crump

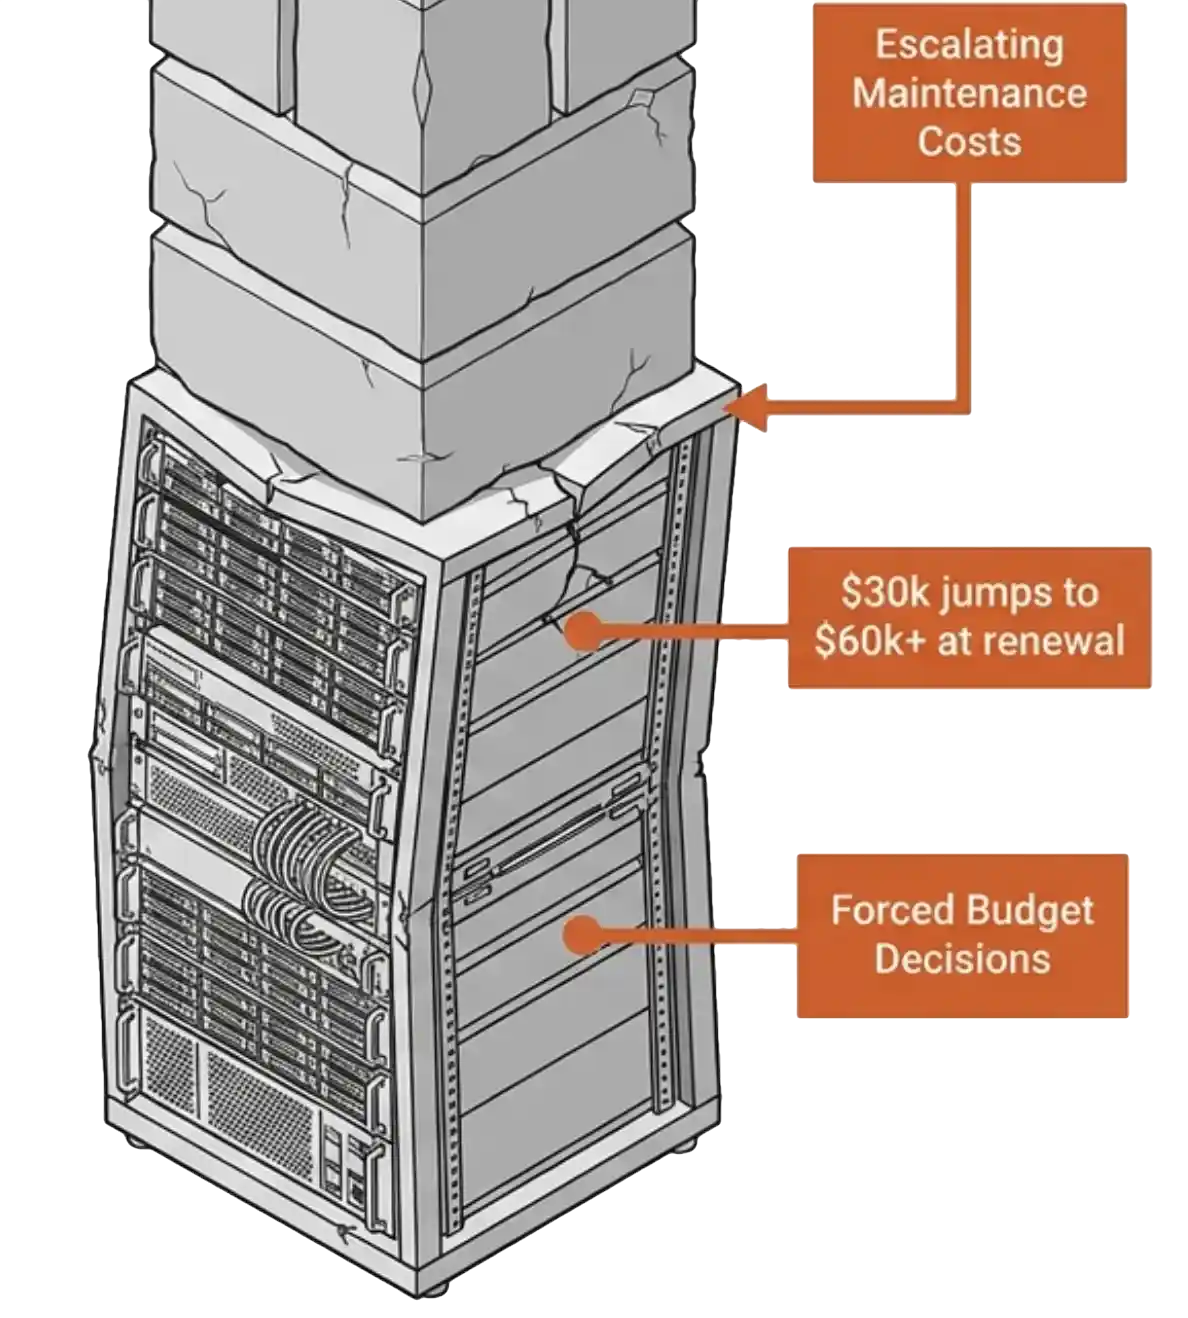
The weight of stacked renewals that pushed Saratoga Casino Holdings to stop paying VMware maintenance and freeze at version 7

A VMware perpetual license feels like leverage right up to the moment you need a patch. You already own the software. Stop paying maintenance, keep the environment running, and the renewal quote goes away. Scott Bartgis, Corporate Director of IT at Saratoga Casino Holdings, made exactly that call after the post-Broadcom numbers arrived. He stopped at version 7 and let maintenance expire. On our August 13 session he described the position he had occupied ever since in four words: stuck on unpatchable VMware.

He arrived there by elimination. A regulated gaming floor belongs on current code, and every engineer running one knows it. He refused to fund the renewal, and the license he already owned offered him exactly one other move: freeze.

That distinction matters more than the perpetual-versus-subscription argument the industry keeps having. Own the license outright and you still want it under maintenance, since maintenance is what delivers support and updates. Rent it by subscription and the same holds. Either way you are paying a line item every year to keep the software supported. What separates one vendor from the next is what happens to that line item over time.

Key Takeaways
  • Perpetual or subscription, infrastructure software stays under maintenance if you want support and security updates. The license model does not change that.
  • The variable that matters is the escalation rate. Saratoga watched a combined renewal climb from the thirty-thousand range into the fifty and sixty-thousand range, then stopped paying and froze at version 7.
  • The VergeIO terms and conditions currently cap any subscription increase at 5 percent per period, and a customer can lock the price for one year, three years, or five years.

The Renewal Number That Kept Climbing

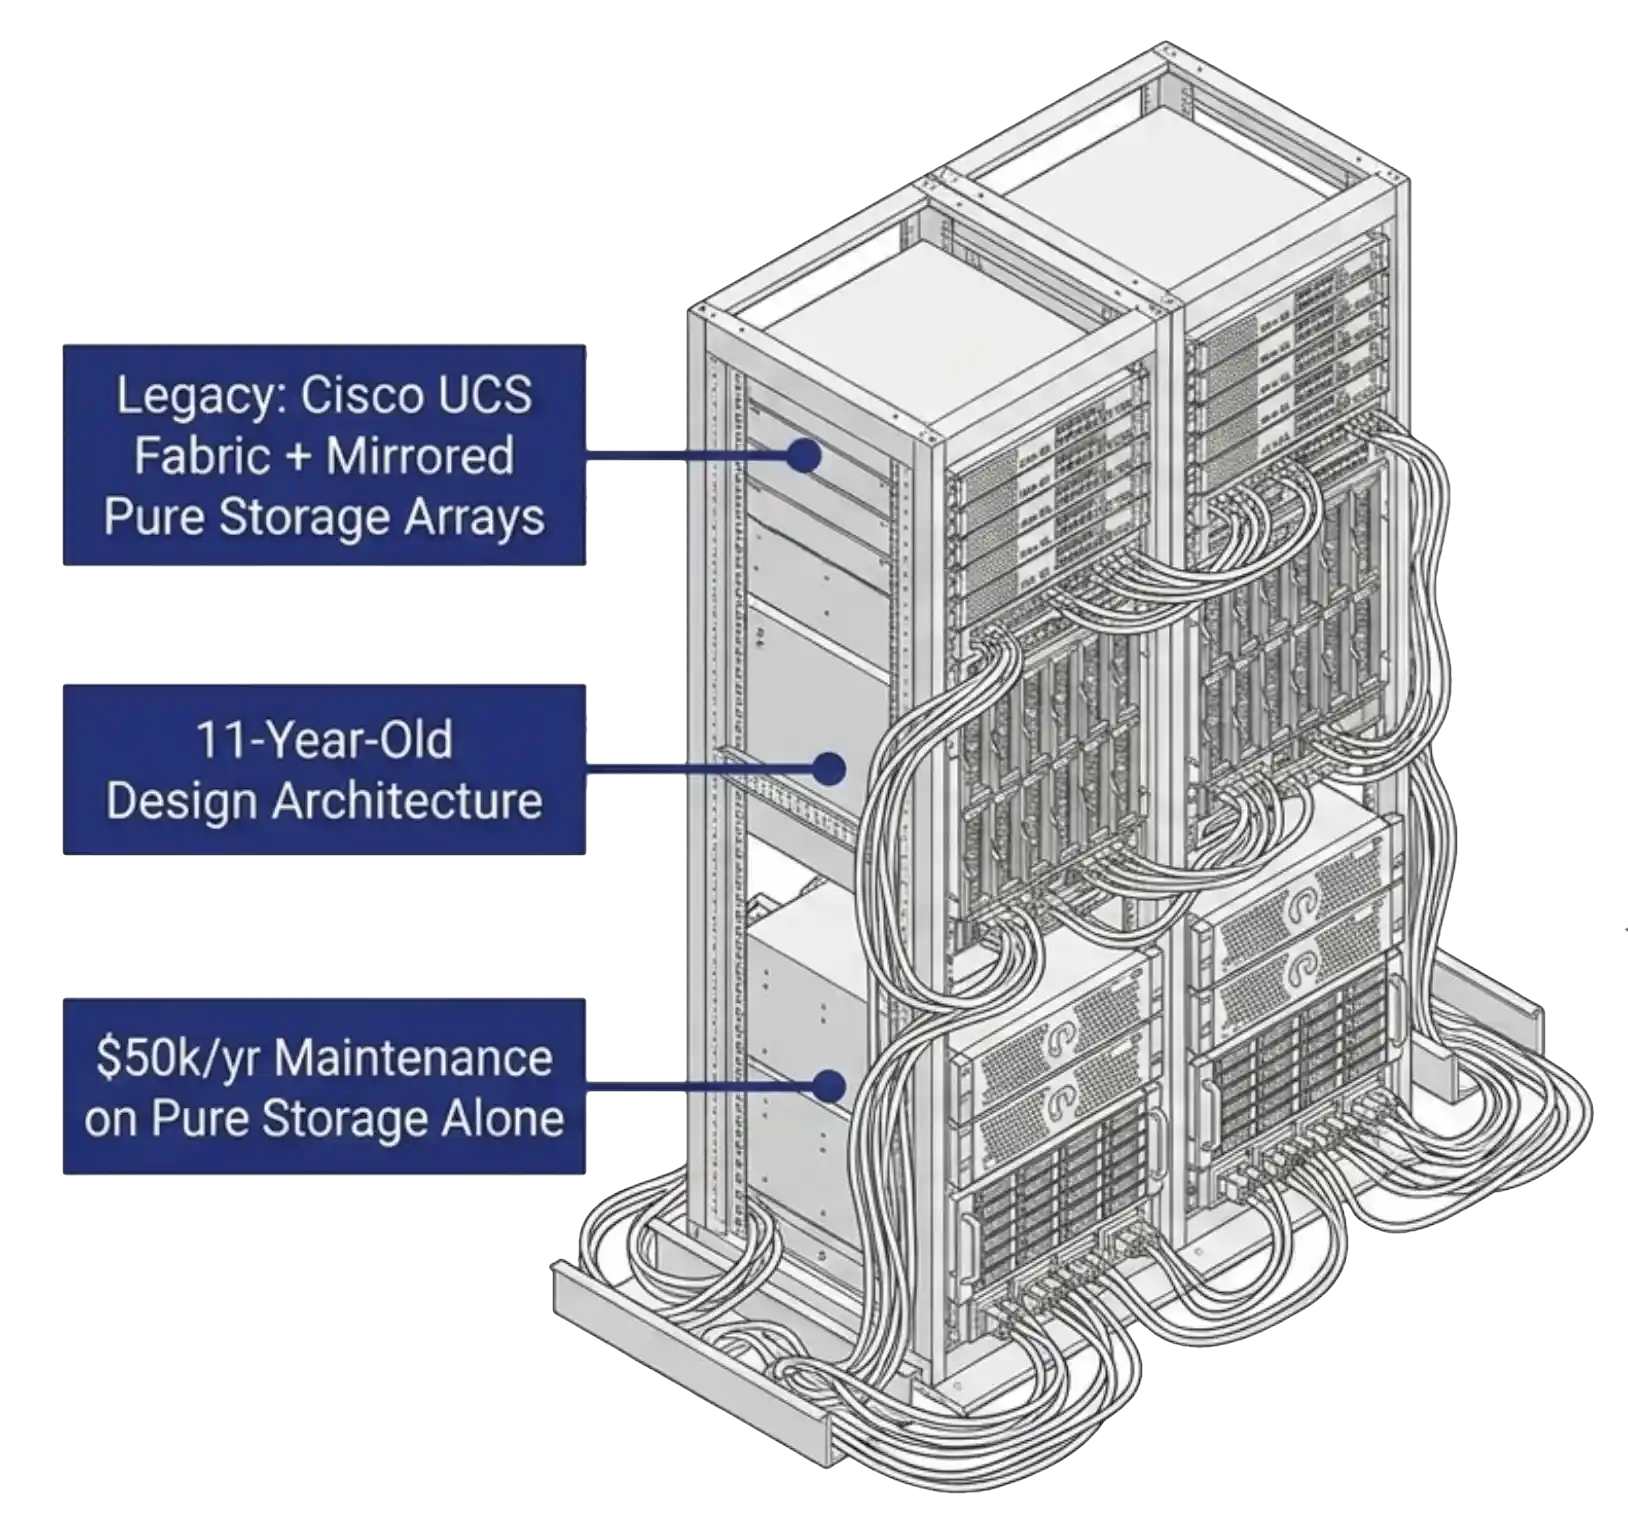
Three contracts came due against the same budget year. Maintenance on the two mirrored Pure Storage arrays ran about $50,000 a year on its own. Cisco UCS hardware support added another line, and the post-Broadcom VMware quote asked Scott to pay again for licenses he already owned. He watched the combined annual figure move from the thirty-thousand range into the fifty and sixty-thousand range across successive renewals, then drew a line and stopped renewing.

The legacy VMware, Cisco UCS, and mirrored Pure Storage stack behind three renewals coming due in the same budget year at Saratoga Casino Holdings

Dropping maintenance removed one invoice and started a different clock. Every quarter the version stayed put widened the distance between the code in production and the code with fixes available. That trade works fine in a lab. In a regulated gaming environment it works for a limited time, which is why the search for a replacement platform started the same year.

Read the sequence carefully and the cost curve is the cause, not the license type. A perpetual license renewing at a predictable number stays under maintenance.

What to Ask Before You Sign Anything

Every infrastructure vendor charges for support and updates. Very few will tell you in writing how much that charge can rise at renewal, which is how a manageable line item becomes a budget event three years later. The question worth asking on the first call is simple: what is the ceiling, and can I lock it?

VergeIO answers both in writing. The current terms and conditions cap any subscription increase at 5 percent per period, and a customer can lock that price for one year, three years, or five years. The software still costs money, and a subscription is still a subscription. What disappears is the surprise, which is the part that pushed Saratoga onto an unpatched version in the first place.

Key Terms
Maintenance
The annual charge that delivers support, patches, and version updates. Both perpetual and subscription licensing require it to stay current.
equal2new®
CXTEC®’s refurbished hardware program, built to order in ISO 9001 facilities, with a lifetime warranty on chassis and components.
Cutover
The moment a workload stops on the source platform and starts on the target. VergeOS synchronizes beforehand, so the cutover itself runs about 30 seconds.

Four Quotes, One Delivery Date

Scott priced the exit properly, with four builds in side-by-side columns. Scale Computing came up short on node count and capacity for the Saratoga property. Nutanix priced close enough to VMware that he grouped the two together on cost and complexity. The finalists were VergeOS on new Dell servers and VergeOS on CXTEC® equal2new® systems.

Delivery date decided it. He ran the numbers in February, and the new-build answer put his servers on a loading dock somewhere around August. CXTEC delivered four equal2new® nodes in about two weeks, ahead of the rack he had ordered to hold them. Each equal2new® server ships with a lifetime warranty on the chassis and its components, and RapidCare® support runs about a third of OEM cost. CXTEC makes the same argument from the hardware side of the transaction in their own post on hardware freedom with VergeOS.

A Migration That Ran on His Calendar

The move started one workload at a time rather than as a single weekend event. VergeOS synchronizes a running VMware VM in the background, then takes a final sync once the source powers down. That final step runs about 30 seconds. Scott had moved 36 workloads by the day of the session with 19 still to go, all of it inside maintenance windows he already had.

Data protection stayed exactly where it was. He runs Veeam into an air-gapped immutable target, and Veeam 13.1 added native VergeOS support with no agents and a VergeOS entry in the backup job dropdown. Knowing that integration was close is what moved him to start migrating his most critical workloads.

Two Ways to Pay for Support

 Frozen VMware stackVergeOS on equal2new®
Support and patchesNone, maintenance expired at version 7Current code under active maintenance
Renewal exposureRepriced at the vendor’s discretion5 percent per period ceiling in the terms and conditions, lockable for one, three, or five years
Hardware choiceVendor compatibility listStandard x86 servers, buyer’s pick
DeliveryFour to six months for new OEM nodesAbout two weeks
Storage growthArray expansion in the vendor’s incrementsAdd a node, spread the workload wider
BackupAgent-basedNative VergeOS support in Veeam 13.1

The Performance Question, Answered

Retiring an all-flash array raises one objection above all others. Scott keeps the same database replicated on both platforms and compares them the way a twenty-year engineer does, by feel. His verdict: “If you blindfolded me, I wouldn’t be able to tell.”

VergeOS on CXTEC equal2new servers running twice the capacity on half the hardware at Saratoga Casino Holdings

He runs twice the capacity on half the hardware, at roughly a quarter of what the UCS and Pure design cost eleven years ago. The cluster holds a terabyte of RAM and just under 40 terabytes of storage, with a 25 gigabit fabric the blade chassis design priced out of reach. One player tracking SQL server takes 96 virtual CPUs, past the point where the interface stops to ask whether the number is a typo.

Own Your Stack Again

Scott is back under maintenance today, on hardware he selected, with a renewal number he can predict. That last part is what he lost when the post-Broadcom quote arrived, and getting it back is what let him stop running production on frozen code.

On-Demand Webinar · 45 Minutes
How Saratoga Casino Left VMware, Cisco UCS, and Pure Storage Behind
Scott Bartgis tells the story himself, then VergeIO engineers migrate a live VMware workload, move it between storage tiers, and pull a server out of the cluster with the applications still serving.
Watch Now
Frequently Asked Questions
Does a VMware perpetual license keep my environment supported?
A perpetual license grants the right to run the version already owned. Support, patches, and security fixes end when the maintenance contract expires, which leaves the environment running on frozen code.
Is a subscription worse than a perpetual license?
Both require maintenance to deliver support and updates, so the recurring charge exists either way. The practical difference sits in the renewal terms: whether the vendor caps the increase, and whether you can lock the price. The VergeIO terms and conditions currently cap any increase at 5 percent per period, with locks of one, three, or five years.
Can workloads move without a maintenance window?
VergeOS synchronizes a running VMware VM in the background and completes a final sync after the source powers down. That cutover runs about 30 seconds per workload, so most teams fit the move inside windows they already schedule.
Is refurbished hardware appropriate for production?
CXTEC® has refurbished enterprise hardware since 1995 and builds equal2new® systems to order in ISO 9001 certified facilities. Every server gets firmware and BIOS updates, a burn-in test, and a lifetime warranty on the chassis and its components.

Next Steps

The recorded session, the full customer story, and the combined solution details are one click away.

On-Demand Webinar
How Saratoga Casino Left VMware, Cisco UCS, and Pure Storage Behind
Scott Bartgis, CXTEC®, and VergeIO engineering, plus a live migration demonstration. 45 minutes.
Case Study
Saratoga Casino Holdings Owns Its Stack Again
The inherited stack, the proof of concept, the migration order, and the results across four properties.
Datasheet
Better Together: VergeOS + CXTEC® equal2new®
Warranty terms, RapidCare® tiers, trade-in mechanics, and the four plays that solve a blocked VMware exit.

Filed Under: VMwareExit Tagged With: Alternative, Hyperconverged, IT infrastructure, UCI, VMware

August 12, 2026 by Dave Vincent

Technical Deep Dive and How To

Storage tiering is the capability that made arrays worth buying in the first place, and 2026 is the year it stopped being a purely technical subject. Flash repriced this year, and it did not reprice gently. DRAM contract prices rose 90 to 95 percent in a single quarter in early 2026. Enterprise NAND moved 70 to 75 percent in the same window.

Storage tiering across NVMe and second-life SATA tiers in a VergeOS cluster

The cause sits entirely outside the enterprise data center. Hyperscalers building AI infrastructure walked into the component market with a budget that has no practical ceiling and bought the output of the storage industry. Nothing broke. The market simply reset around a new buyer, and the enterprise now sits behind that buyer in the allocation queue.

Buyers reached a conclusion about this on their own. In Omdia research commissioned by VergeIO, covering 400 North American IT professionals in May 2026, software-defined storage ranked first of eight technologies that non-users plan to invest in as a direct response to the shortage. It outranked every array architecture on the list. The reasoning behind that ranking is independence from the underlying hardware, which is a polite way of saying buyers want to stop asking a vendor for permission to purchase a drive.

Key Takeaways
  • Storage tiering is a data-placement decision rather than an array feature, and per-node licensing keeps it a technical decision instead of a financial one.
  • VergeOS exposes tier placement as one mutable field with an online migration behind it, so read tier, set tier, and create on tier are the only primitives a storage tiering policy needs.
  • Reclamation on a source tier is gated by the longest-lived snapshot still referencing the data, which makes retention schedules the real timeline for any capacity recovery plan.

That conclusion raises a fair technical objection. Storage tiering is the ability to put the transaction log on expensive media and the file server on inexpensive media, deliberately, and to change that decision later. Collapsing the array into the operating system to escape a capacity meter is a hollow win if storage tiering does not survive the move. It is a worse win if tiering survives and comes back as a different meter.

The measurements below come from a two-cluster VergeIO lab, and they answer the technical half of that objection. The commercial half is settled by the licensing model, and the two halves only matter together.

Scope note. Everything measured here comes from a VergeIO lab, not a production environment. Two three-node clusters, mixed media, a handful of test workloads, and a blast radius that ends at the lab bench. The commands, timings, and API behaviors are real and reproducible. The hardware choices are not a reference architecture. At least two of them, no Tier 0 on either cluster and a Tier 3 with drives on a single node, fail a production design review outright, and both appear in the fine print below. VergeOS hardware requirements call for enterprise-class drives and network cards in production, and the lab does not meet that bar on every tier. Read the storage tiering mechanics as transferable and the specific figures as illustrative.

Two classes of media, one cluster, one license

The lab’s second cluster mixes two classes of media on purpose, which makes it a useful place to watch storage tiering behave.

TierMediaDrivesRawUsable
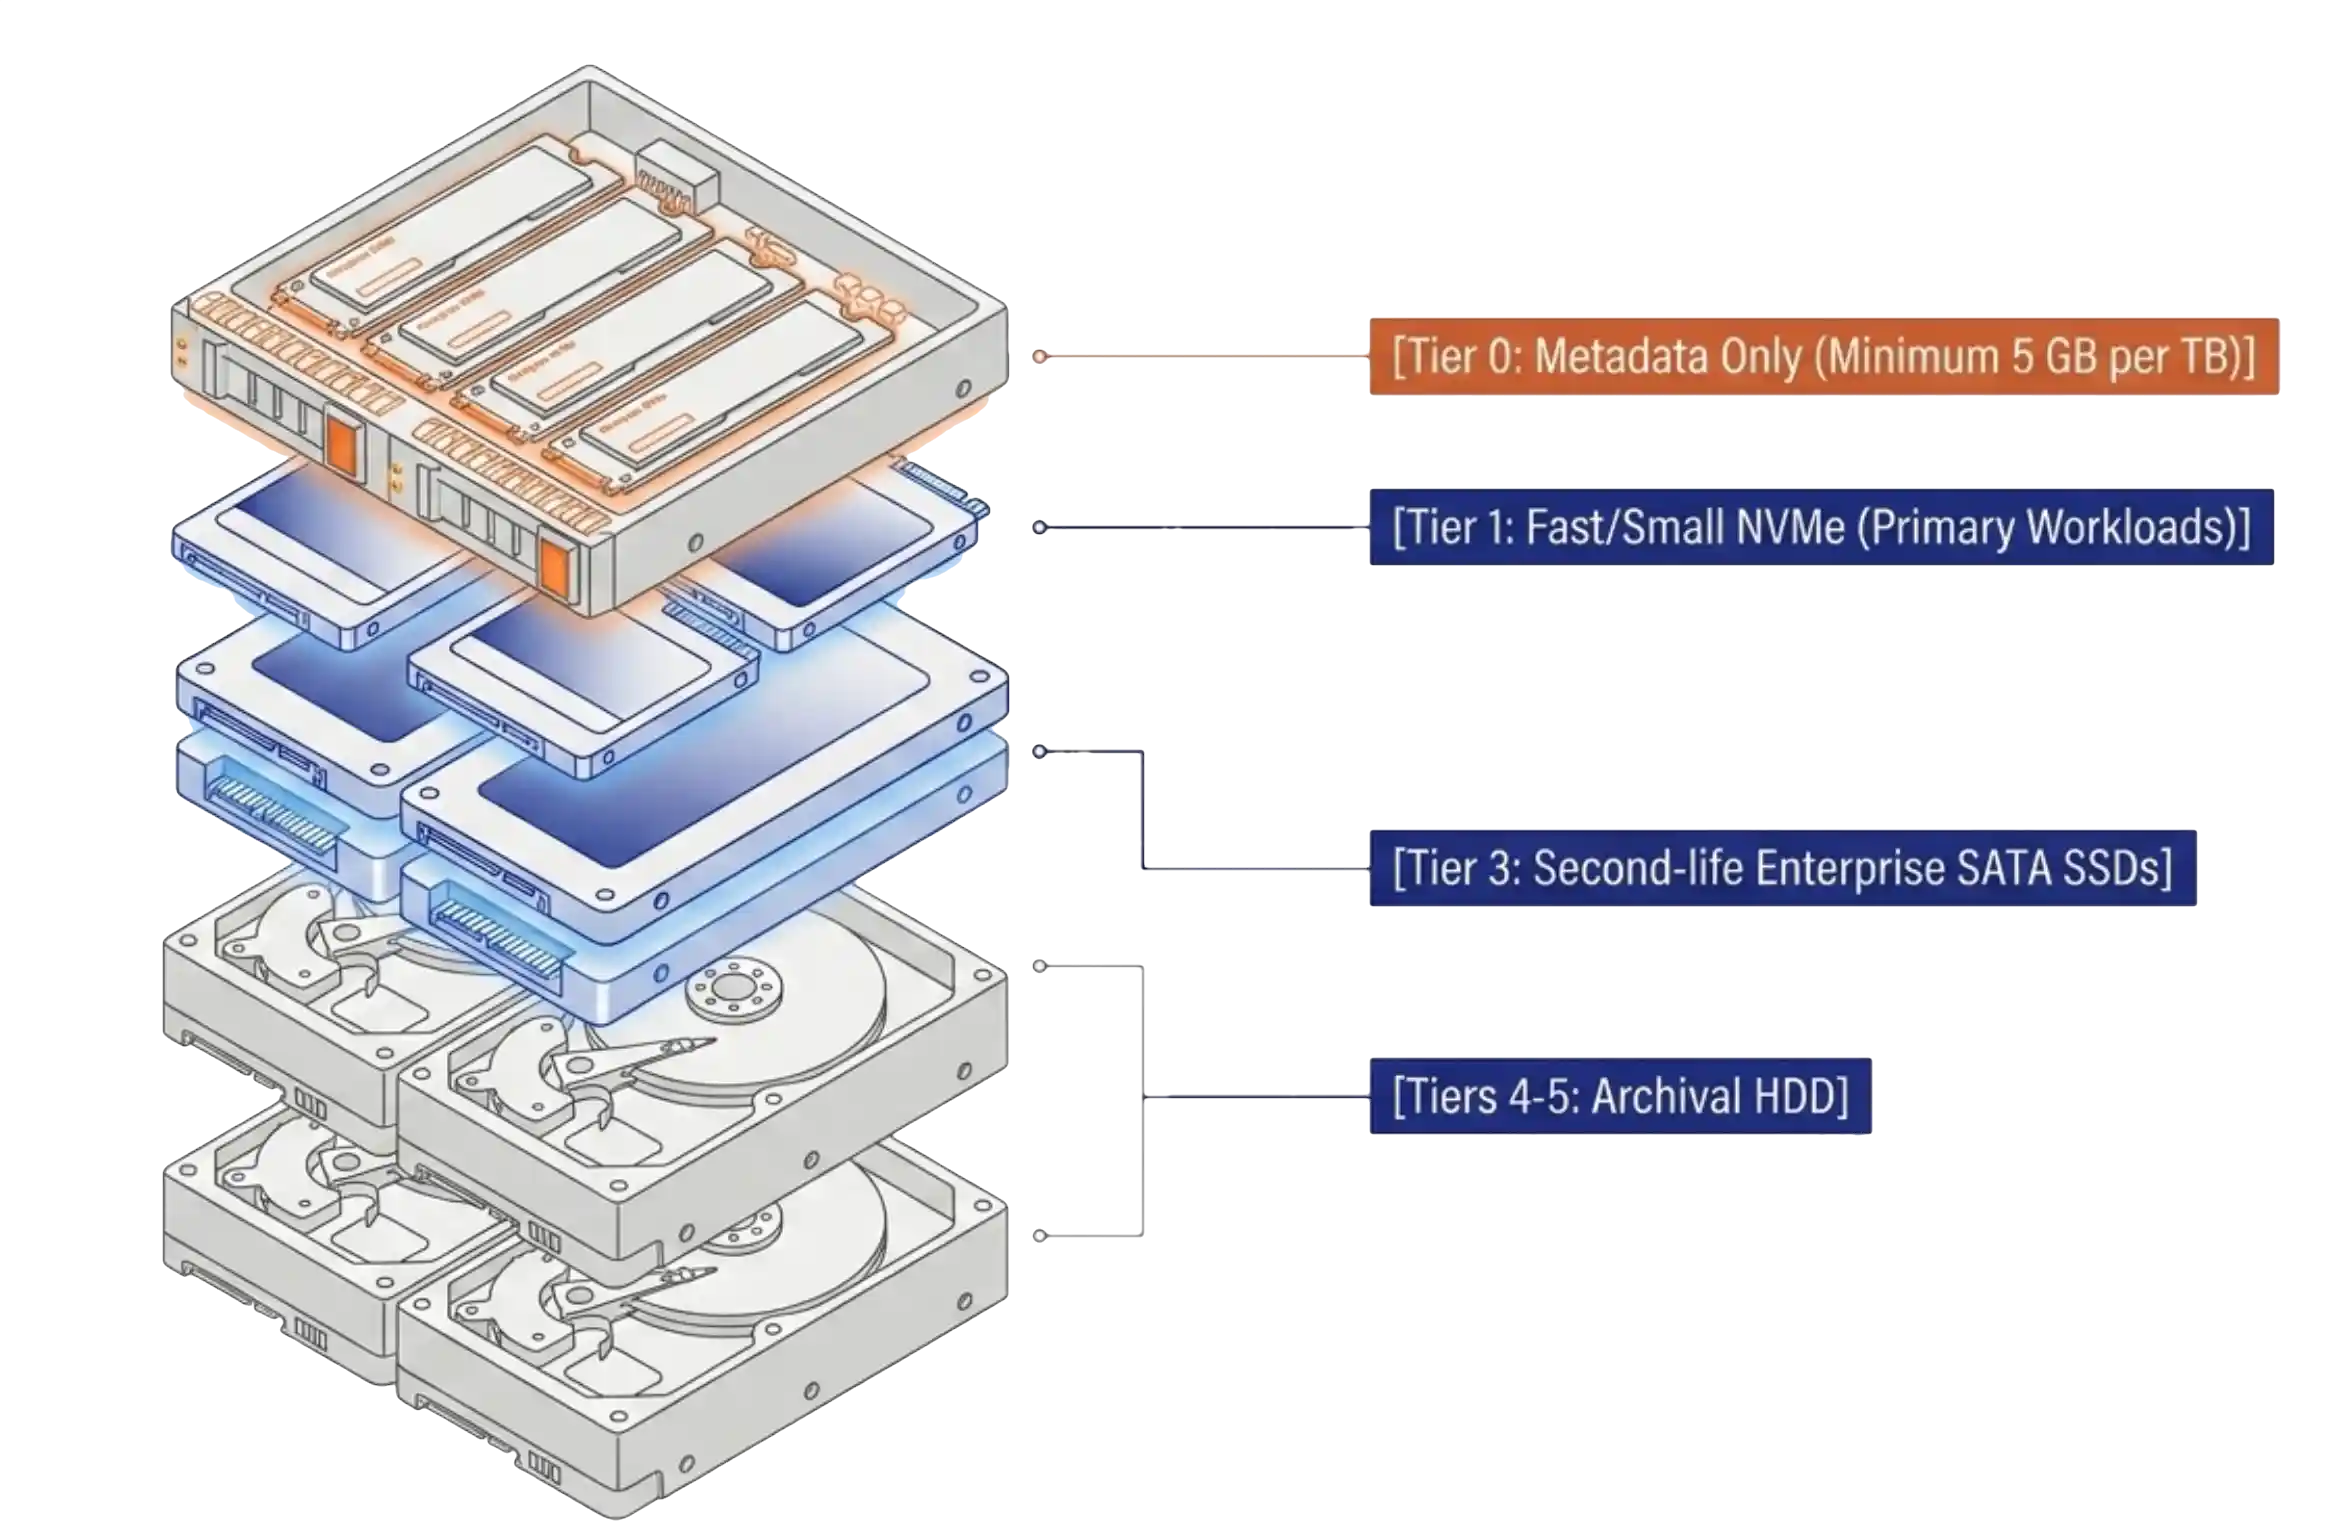
1NVMe SSD3 × 256 GB768 GB356.04 GB
3SATA SSD, second-life enterprise3 × 800 GB2,400 GB1,115.77 GB

Tier 1 is fast and small. Tier 3 carries a little over three times the usable capacity on older, slower, second-hand drives. Fast where it matters and inexpensive where it does not is the entire value proposition of storage tiering, and nothing about this arrangement required a storage array.

The Tier 3 drives are the economically interesting ones. They are used enterprise SATA SSDs, the same category of hardware behind the CXTEC equal2new program that appeared in VergeIO’s August 4 announcement about Saratoga Casino Holdings. The comparison deserves a caveat. Saratoga bought professionally refurbished, warrantied servers to run a four-property gaming operation. The lab bought used parts with no warranty at all. What generalizes between the two is the platform economics, not the procurement decision.

Second-life enterprise storage is not inexpensive in absolute terms, and it has firmed up as the primary market tightened behind it. Relative to new flash it remains a bargain, and 2026 widened that gap sharply. Against DRAM at 90 to 95 percent and NAND at 70 to 75 percent in a single year, a used enterprise drive does not have to be cheap to be the obvious way to build a capacity tier. It only has to be less expensive than an alternative that just repriced.

The question that applies at both scales is whether the platform lets an organization use the less expensive media without charging for the privilege.

A license that meters raw physical capacity answers that question badly. Three second-hand 800 GB SATA drives meter identically to three new 800 GB NVMe drives. Same 2.4 TB raw, same bill, and the platform collects on hardware it had nothing to do with. Worse, a raw-capacity meter reads the physical drives before any data reduction happens, so every block the storage engine removes is a saving the vendor recaptures. That is the mechanism that pushes organizations back toward dedicated arrays, and it has been characterized as the case that storage licensing, not storage technology, is what broke hyperconverged infrastructure.

VergeOS licenses per node with every feature included, covering compute, storage, networking, and multi-tenancy in a single license tied to a System ID rather than to hardware (Licensing Overview, Transitioning from VMware). The drives are not a line item. The question stops being what an organization can afford to license and becomes what it can do with tiers.

How VergeOS storage tiering works

VergeOS vSAN organizes physical drives into six tiers, numbered 0 through 5. Tier assignment happens at the drive level, during installation or when drives get added. Tier 0 holds metadata only. Tiers 1 through 5 hold workload data, running from write-intensive NVMe at Tier 1 down to archival HDD at Tier 5 (VergeOS vSAN documentation).

VergeOS storage tiering, walked through in the UI and from the command line.

Three architectural properties matter more than the tier table itself.

Placement is derived, not looked up. Every block gets a SHA-1 content hash. That hash, run against per-tier device maps stored on Tier 0, deterministically derives where the block’s primary and redundant copies live. No central table records that block X sits on node Y, drive Z, and no controller sits in the write path. Reference counts are not stored persistently either. A background differential process called the vSAN Walk rebuilds them (vSAN Architecture and VergeFS). Reference counting explains a surprise in the fine print, so it is worth remembering.

Each tier is an independent failure and scaling domain. Every tier spans all storage-participating nodes, and redundancy is tracked per tier. A Tier 4 drive failure has no bearing on Tier 1 redundancy, and one tier scales without touching another.

Data placement stays with the administrator. VergeOS does not migrate data between tiers based on access patterns. No policy engine watches heat maps and demotes cold blocks at 2 a.m. Data stays on its provisioned tier until an administrator moves it, and the documentation flags this in a red warning box rather than burying it.

Predictable performance from administrator-controlled storage tiering in VergeOS

That reads like a missing feature to anyone who grew up on array auto-tiering. It is the most defensible design decision in the storage stack. Automated demotion is a policy someone else wrote for a workload that is not yours, and the failure mode arrives at month-end close, when the engine quietly moved the database overnight. The people in a building know things about their data that no access-recency algorithm infers. The documented reasons line up with that: predictable performance, capacity planning that reflects only what an administrator put on a tier, no background storage tiering engine consuming CPU and I/O, and cost modeling that holds still.

There is a fallback for provisioning safety. Every virtual disk carries a preferred tier, and when that exact tier does not exist, VergeOS selects the next less expensive tier, moving to a more expensive one only when no less expensive tier is available (Preferred Tier). Ask for Tier 3 on a system holding Tier 1 and Tier 4, and the disk lands on Tier 4. The system never refuses to provision, which is a safety feature and a trap in equal measure.

Automating placement from the command line

Administrator-controlled placement puts the work on the administrator. The useful discovery in the VergeIO lab is how small that work turns out to be, since tier placement is exposed as a single mutable field with an online migration behind it.

Every test below ran against a live VM on the lab’s second cluster. Snapshot first:

vrg -p homelab2 vm snapshot create test-ubuntu –name pre-tier-test-20260807-1554

Moving a running VM’s disk to a less expensive tier takes one command:

$ time vrg -p homelab2 vm drive update test-ubuntu OS –tier 3 ✓ Updated drive ‘OS’ tier 3 real 0m1.296s

The API acknowledged in 1.3 seconds. Block movement happened in the background, and within 13 seconds Tier 3 had grown by 2.32 GiB, the real thin-provisioned consumption of a 25 GiB disk. The VM stayed running throughout. No downtime, no guest awareness, no reboot.

Provisioning a new disk directly onto an inexpensive tier is also one command, and it hot-plugs into the running VM:

$ vrg -p homelab2 vm drive create test-ubuntu –name bulk-data –size 40GB –tier 3 ✓ Created drive ‘bulk-data’ (key: 13) size_gb 40.0 tier 3

Note the --tier flag. Leaving it off inherits the system default from System, System Settings, Default VM Drive Tier, which on a fresh system is not necessarily the right answer. Being explicit costs nothing.

Reading current placement needs no raw API call:

$ vrg -p homelab2 vm drive list test-ubuntu Key Name Media Interface Size (GB) Tier Enabled 6 OS disk virtio-scsi 25.0 1 Y

Read tier, set tier, create on tier. Three primitives, all non-destructive, all online, all scriptable. A storage tiering policy engine becomes a loop rather than a product.

The tags are the policy

The obvious first instinct is to match on VM names and demote anything called *-archive or *-backup. That instinct is wrong. Name patterns need an ordering, an escape hatch for the VM matching two patterns at once, and a naming convention everyone has to know and nobody can query. VergeOS already ships something better.

Desired placement lives in the platform as tags, and each run of the script reconciles reality to match. The script holds no state of its own. Three commands stand the whole thing up:

vrg tag category create –name storage-policy –single-selection –taggable-vms vrg tag create –name tier-1 –category storage-policy vrg tag create –name tier-3 –category storage-policy

Tagging a workload is one more:

vrg tag assign tier-3 vm my-fileserver

A tier-N tag on a VM means every disk on that VM belongs on tier N. Each run walks the tags in the category, then the VMs carrying each tag, then those VMs’ disks, comparing current placement against the tag and migrating whatever does not match. Reading the intended state back takes one command, and it works whether or not the script has ever run:

$ vrg -p homelab2 tag members tier-1 –type vm Key Type Resource Key Resource Name 1 vm 32

--single-selection on the category is the load-bearing flag. It makes the tags mutually exclusive. Assign tier-1 to a VM already carrying tier-3 and VergeOS silently drops tier-3. That behavior showed up during testing, where retagging one VM emptied the other tag’s member list with no unassign command issued.

One flag turns a pile of rules into a declarative system. A VM cannot hold two contradictory policies, so the conflict becomes impossible rather than merely detected. No precedence logic is needed, since there is never more than one answer. The policy stays queryable outside the script, through the platform’s own UI and API, by people who have never seen the code.

Tags deliberately move nothing on their own. A tag stays inert until the script runs, and untagged VMs are ignored completely, which makes the whole arrangement opt-in per workload rather than something that sweeps a cluster the first time anyone tries it. One caution applies: create tier-N tags only for tiers that exist on that system. Tag a VM tier-5 on a system with no Tier 5 and the script skips it with a warning. That is the right behavior, since the alternative is the preferred-tier fallback quietly placing data somewhere nobody chose.

The reconciler

The result is tier-policy.sh, dry run by default, with --apply to execute:

$ ./tier-policy.sh –profile homelab2 –apply [tier-policy/homelab2] starting (mode=APPLY, category=storage-policy) [tier-policy/homelab2] health gate passed (storage, alarms) [tier-policy/homelab2] tiers present: tier [email protected]%, tier [email protected]% [tier-policy/homelab2] test-ubuntu/OS: tier 1 -> 3 [PLANNED] [tier-policy/homelab2] scanned 1 tagged VM(s), 1 drive(s) need migration [tier-policy/homelab2] creating cloud snapshot ‘tier-policy-20260807-162850’ [tier-policy/homelab2] snapshot created [tier-policy/homelab2] MIGRATED test-ubuntu/OS: 1 -> 3 [tier-policy/homelab2] done: 1 migrated, 0 failed

Thirteen seconds end to end, covering health gate, snapshot, and migration, with the VM running throughout. A second run reports nothing to do, converged.

The gates are where the engineering went, and each one exists in response to something in the mechanics above. A health gate runs vrg doctor --check storage,alarms and aborts on any failure, since shuffling data across an unhealthy vSAN is a bad idea at any scale. A destination-tier existence check skips VMs loudly when a tag names a tier that does not exist, which prevents the preferred-tier fallback from placing archive data on whatever tier it finds. Silent success in the wrong place is worse than a refusal. A capacity gate refuses to migrate into a tier above 85 percent used, since throttling starts at 91 percent. A snapshot envelope takes a cloud snapshot before the first mutation and aborts the run when that snapshot fails.

Two problems cost a debugging cycle each, and both are worth knowing to anyone building something similar. vrg tag members returns an empty resource_name and populates only resource_key, so keys have to be resolved to names separately. And in bash, if ! cmd followed by rc=$? captures the status of the negation rather than the command, which turned a clean exit-10 connection error into a nonsensical “failed (exit 0)”. Run the command bare and capture $? on the next line. That second one is not VergeOS’s fault, and it is exactly the kind of defect that makes an unattended job lie to its owner at 2 a.m.

The script itself is beside the point. The point is that administrator-controlled placement is what makes automated placement tractable. The reconcile logic runs about sixty lines. Everything else is gates, error handling, and comments, which is what a script worth leaving in cron looks like. That ratio stays affordable for one reason. The underlying primitives are three clean commands rather than an API worth fighting. The policy ends up expressed in the platform’s own tagging system, in a language of the administrator’s choosing, on a schedule the administrator sets. The full script is available for download at the end of this post.

What placement below the meter buys

Data reduction accrues to the organization that paid for the drives. VergeOS runs global inline deduplication across the entire storage pool rather than per volume, per array, or per backup job. One metadata model spans the environment, so a block reduced on primary stays reduced downstream, with no boundary to cross and no rehydration on the way. Every implementation scoped to a volume or a job pays for the same block four times, on primary, in the backup, in the replica, and at the DR site.

A raw-capacity meter reads the physical drives and ignores all of it. The meter counts what an organization bought, not what its workloads believe they have, and the gap between those two numbers is the storage engine’s entire contribution. Under per-node licensing that gap belongs to the customer. Reduction ratios vary enormously by dataset, and any vendor quoting one without naming the workload behind it is selling a number rather than reporting one. The architectural point survives without a figure. Whatever the ratio turns out to be, the licensing model decides who captures it. The section below covers how to measure it on real data rather than trusting anyone’s headline.

Raw capacity is a poor proxy for delivered value, in both directions. Redundancy overhead measured consistently at roughly 2.15x across every tier in the VergeIO lab. The second cluster’s Tier 3 shows 2,400 GB raw against 1,115.77 GB usable. Its Tier 1 shows 768 GB raw against 356.04 GB usable. The primary cluster’s Tier 1 shows 6,000 GB raw against 2,791.65 GB usable. That is N+1, the default, keeping two copies of every block (redundancy models). N+2 runs closer to 3x.

That overhead is arithmetic rather than a licensing complaint, and it applies to VergeOS exactly as it applies to everyone else. Two copies of a block cost twice as much as one copy regardless of who wrote the storage engine. The narrower point concerns the metric. Raw capacity, the number a capacity meter counts, sits at roughly 2.15x what an administrator can provision against and a small fraction of what the workloads think they have. It overstates what is usable and understates what is served, which means it is not measuring storage at all. It is measuring drives.

Thin provisioning stops being a negotiation. The lab’s primary cluster reports 40,062 GB allocated against 2,791 GB usable, more than fourteen times its usable capacity in allocated virtual disk. That figure belongs to a lab bench, and a disciplined production environment should not run anywhere near it. The direction holds at any scale. Over-allocation is free under per-node licensing, and the documentation recommends provisioning generously rather than expanding later. On a capacity-metered platform, generous provisioning turns into a budget conversation with a procurement officer.

Mixed hardware becomes a design input rather than a liability. Storage tiering is what lets an administrator deliberately put the file server on second-life SATA and the database on NVMe, inside one cluster, under one license. The lab’s primary cluster currently holds two 12 TB HGST He12 drives and a 2 TB Micron SSD sitting unassigned, reported by the API at tier -1 with zero vSAN capacity. That is 26 TB of idle hardware available as Tier 4 and Tier 5 tomorrow at zero licensing cost. On a capacity-metered platform, adding 24 TB of raw HDD starts with a purchase order and a permission slip. The lab version of this is drives already on the shelf. The production version is the one Saratoga ran, where the same property means buying capacity on the open market instead of from a hypervisor vendor.

Failure domains stay separate. Each tier tracks redundancy independently, so a failure among the second-life Tier 3 SSDs cannot compromise Tier 1. That is what makes mixing media classes a calculated decision rather than a gamble. The blast radius of the less expensive hardware stays bounded by design, and bounded to the tier holding the lower-priority data.

This matters more in 2026 than it did in 2024. Eighty-three percent of the organizations in the Omdia study plan to run their arrays past historical utilization before refreshing. Extending hardware life, running fuller, and buying used are all rational responses to component pricing, and together they describe a market deliberately raising its own failure rate at the moment spare hardware became unaffordable. Tier-level failure isolation is one of the few answers to that condition that does not begin with buying something.

Key Terms
Storage tier
One of six drive groupings in the VergeOS vSAN storage tiering model, numbered 0 through 5, assigned at the drive level. Tier 0 holds metadata only. Tiers 1 through 5 hold workload data, running from write-intensive NVMe down to archival HDD.
Preferred tier
The tier a virtual disk requests. When that exact tier does not exist, VergeOS places the disk on the next less expensive tier, moving to a more expensive one only when no less expensive tier is available.
vSAN Walk
The background differential process that rebuilds block reference counts. Blocks reaching zero references wait roughly ten walks, about seventy seconds, before becoming eligible for reclamation.
Raw, usable, and logical capacity
Raw is the physical drive total and the number a capacity meter bills. Usable is what remains after redundancy, roughly raw divided by 2.15 at N+1. Logical is what the workloads believe they have after data reduction.

The fine print

Migrating off a tier does not return the capacity, and snapshot retention decides when it does. This is the finding that surprised the lab most, and the first explanation was wrong in a useful way.

Moving that 25 GiB disk from Tier 1 to Tier 3 grew Tier 3 by 2.32 GiB within seconds, and Tier 1 did not shrink at all. Eleven minutes of watching produced 41.2 GiB before and 41.2 GiB after. The vSAN Walk looked like the obvious culprit, and the documentation rules it out. Blocks reaching zero references wait roughly ten walks, about seventy seconds, before becoming eligible for reclamation. Eleven minutes is nine times that window.

The real gate is reference counting. A snapshot references blocks rather than copying them, and blocks referenced by a snapshot are retained after the live object stops pointing at them (vSAN Architecture and VergeFS). The count has to reach zero first, and it never did. That system carried a midnight system snapshot, hourly snapshots on a three-hour cycle, and a manual snapshot taken half an hour earlier, all still pointing at those blocks in their Tier 1 locations. The snapshot taken for safety before the migration is part of what stopped the space coming back. Taking it was still correct. It has a cost, and this is the cost.

The planning rule is sharper than patience. Reclamation on the source tier is gated by the longest-lived snapshot still referencing that data. Midnight snapshots on this cluster retain for three days, so evacuating a workload buys nothing measurable on Tier 1 until those age out. Anyone demoting data to relieve a full tier should read their retention schedule first, since that schedule is the actual timeline and it is measured in days.

A pleasant corollary follows from the same mechanism. Moving the disk back to Tier 1 was instantaneous and consumed no new Tier 1 capacity, for the same reason. The snapshots still held those blocks in place. Round-tripping costs almost nothing. One-way evacuation is the slow direction, and seasonal workloads that migrate down and back are the best fit for how this behaves.

Measure the reduction ratio from the API rather than a summary field. The authoritative per-tier numbers are used, physical bytes committed, and used_inflated, logical bytes stored, both in the storage_tiers table. Dividing one by the other produces the real reduction for that tier on real data, which is worth wiring into existing capacity reporting:

curl -ks -H “Authorization: Bearer $KEY” “$HOST/api/v4/storage_tiers?fields=all” \ | python3 -c ” import sys,json G=1024**3 for t in json.load(sys.stdin): u,ui=t.get(‘used’,0),t.get(‘used_inflated’,0) print(f\”tier {t[‘tier’]}: {u/G:.1f} GiB physical, {ui/G:.1f} GiB logical, {ui/u:.2f}x\”)”

Two cautions apply to the result. A lab estate full of VMs cloned from one golden template produces a flattering number that no production estate will match, so measure against real data before modeling with it. And do not add a compression multiplier on top of that ratio. VergeOS does not compress data at rest. Compression applies only during site-sync replication, to save WAN bandwidth between sites, and the number above already reflects everything happening locally.

Get the drive layout right at install, since both halves of it are painful to change later. Two rules carry most of the weight.

The first concerns Tier 0. It holds metadata only, explicitly not a cache, and no workload data. Sizing guidance is 5 GB per TB of usable storage minimum and 10 GB per TB recommended, on enterprise NVMe rated 3 DWPD or equivalent, with 30 percent free space maintained. Consumer NVMe is not supported for it in production. Neither lab cluster has a Tier 0 at all, so nothing here should be read as guidance on Tier 0 behavior under load. Tier 0 is normally configured at install time. The documented procedure for adding it afterward carries a hard warning that only qualified VergeOS engineers, or an administrator under direct support guidance, should perform it. Selected devices get formatted, and a wrong device path causes serious damage.

The second concerns homogeneity. All drives within a tier should match in type, capacity, and performance, and a tier can only use the capacity of its smallest drive, so one undersized drive silently caps the whole tier. Each node should also carry the same number of drives per tier. The lab’s primary cluster demonstrates the failure mode. A 2 TB Micron sits assigned to Tier 3 on exactly one node, Tier 3 does not appear in vrg storage list at all, and tier_count reads 1. A tier that cannot satisfy cross-node redundancy is not a tier anyone can use.

Know where the throttling cliffs sit. Below 91 percent is normal operation. Between 91 and 95 percent, low-space throttling adds 10ms of latency. At 96 percent and above, critical throttling adds 50ms (Diagnostics Toolkit). Target free space is 30 percent or more on Tier 0, 20 to 30 percent on Tiers 1 through 3, and 15 to 20 percent on Tiers 4 and 5. Any automated placement policy should treat those as hard gates rather than advice.

Second-life media needs a monitoring discipline, and one organization’s risk calculus is not another’s. Quality used enterprise drives are a legitimate way to build a capacity tier, and they arrive with less runway than new ones, so SMART and wear telemetry become something to watch rather than background noise. vrg doctor surfaces drive health as a first-class check, and running it on a schedule beats running it once suspicion sets in. Replacement planning matters too, since a swap requires the node in maintenance mode with only one repair running per tier at a time. Weigh the strategy against real consequences. A lab accepts older media on a capacity tier, since the worst realistic outcome there is a rebuilt test cluster. Put a customer-facing workload, a recovery point objective, and a support contract behind it and the acceptable age and condition of that hardware changes completely. That difference is precisely why Saratoga bought warrantied refurbished gear and a lab bench does not have to.

Three nodes and two VMs is not a load test. The lab’s second cluster ran two VMs during the tier migration, and both clusters sit under 27 percent tier utilization. What got measured is that migration is online and non-disruptive at that scale. What did not get measured is what a storage tiering migration does to latency on a busy cluster, what happens when fifty disks demote at once, and how the vSAN Walk behaves under sustained write pressure. Anyone planning bulk tier movement in production should assume those answers exist and go find them before trusting a 1.3-second acknowledgment to mean anything about their environment.

What this adds up to

Pick tiers explicitly at provisioning time, every time. The --tier flag costs six characters and saves a migration. The preferred-tier fallback places every disk somewhere, which is a safety feature and a footgun in equal measure. A disk nobody thought about lands on whatever the system default happens to be, and nobody notices until it becomes a performance ticket.

Automate the storage tiering decisions VergeOS deliberately leaves to the administrator. A tag category, four gates, and a reconcile loop produce declarative tier placement with logging and a snapshot envelope, all of it auditable, versionable, and owned by the organization running it. It took an afternoon and fits in one file. That is the compounding advantage of a platform with a clean CLI. Capabilities that otherwise wait on a vendor’s roadmap become things an administrator assembles, and the policy ends up living in the platform’s own tagging system rather than buried in code.

Model capacity in three numbers rather than one. Raw, usable at roughly raw divided by 2.15 at N+1, and logical at usable multiplied by a measured reduction ratio from real data. Each number answers a different question, and they are not interchangeable. Raw is what an organization bought and what a capacity meter bills. Usable is what an administrator can provision against once redundancy takes its cut. Logical is what the workloads believe they have. Bringing the wrong one to a capacity conversation produces an error of an order of magnitude in whichever direction is least convenient.

Saratoga’s $50,000 a year was never an array-maintenance line item in any meaningful sense. It was the price of keeping data placement inside a box that charged rent for the privilege. Storage tiering never needed to live in a dedicated array. It needed to live somewhere that was not metering the drives underneath it.

A lab cannot prove that at Saratoga’s scale, and it does not need to. What a lab proves is whether the mechanism is real before anyone bets a data center on it. Is the tier field genuinely just a field. Is the migration genuinely online. Does the efficiency genuinely accrue to the organization that bought the hardware. All three held up. The rest is a procurement decision made by people with more at stake, and the useful thing to carry into that decision is what the lab found. The inexpensive tier and the fast tier are the same system, under the same license, one command apart.

Download tier-policy.sh

The tag-driven storage tiering reconciler described above. 282 lines of bash, requiring vrg, python3 3.11 or later, and coreutils timeout. It runs as a dry run by default, with --apply to execute. Configuration instructions live in the header comment.

Download the script (.zip) tier-policy.sh · bash · dry run by default

Live Webinar · August 20

The Great Enterprise Storage Squeeze

Simon Robinson, Principal Analyst at Omdia, joins VergeIO on August 20 at 12:00 PM ET to walk through the study behind the numbers in this post, covering what 400 IT buyers reported about component pricing, refresh deferral, and where software-defined storage landed on their shortlists.

Register for the session

Raw-capacity metered licensing versus per-node licensing

 Raw-capacity metered licenseVergeOS per-node license
What the license countsPhysical drive capacity, before any data reductionNodes, tied to a System ID rather than hardware
Who captures data reductionThe vendor, since the meter reads the drivesThe customer, since the drives are not a line item
Adding a capacity tierA purchase order plus a licensing add-onAssign existing drives to a tier at no licensing cost
Mixing media classesConstrained by a vendor compatibility listMixed drive types, capacities, and server generations
Using quality used enterprise drivesMetered identically to new drives of the same sizeMetered not at all
Changing tier placementDepends on array capability and licensed capacity headroomOne command, online, with the workload running
Frequently Asked Questions
Does VergeOS storage tiering move data between tiers automatically based on access patterns?
No. Data stays on its provisioned tier until an administrator moves it. Automated demotion is a policy written by a vendor for a workload that is not yours, and the failure mode arrives when the engine demotes a dataset the night before someone needs it. Administrator-controlled storage tiering is a design decision rather than a gap, and the CLI makes automating it a short exercise.
Does moving a virtual disk between tiers require downtime?
No. The API acknowledged a tier change in 1.3 seconds in lab testing, block movement completed in the background within 13 seconds for a 25 GiB thin-provisioned disk, and the VM stayed running throughout with no guest awareness and no reboot.
Why did the source tier not free up space after migration?
Snapshots reference blocks rather than copying them, and referenced blocks are retained after the live object stops pointing at them. Reclamation waits for the reference count to reach zero, which means the longest-lived snapshot still referencing that data sets the timeline. Check retention schedules before planning capacity recovery around a migration.
Can VergeOS run on quality used enterprise hardware?
VergeOS runs on standard enterprise servers and supports mixing drive types, capacities, and server generations within its documented requirements. Enterprise-grade components are required. Consumer-grade disks and consumer or off-brand network cards are not supported, and any specific configuration should be validated before it appears on a quote.
What reduction ratio should an organization plan for?
Measure it rather than inherit it. The authoritative per-tier numbers are used and used_inflated in the storage_tiers table, and dividing one by the other produces the real ratio for real data. Lab estates built from cloned templates produce flattering numbers that heterogeneous production data will not match.

Filed Under: Storage Tagged With: Alternative, HCI, IT infrastructure, VMware

  • Page 1
  • Page 2
  • Page 3
  • Interim pages omitted …
  • Page 15
  • Go to Next Page »

855-855-8300

Get Started

  • Versions
  • Request Tour

VergeIO For

  • SAN Replacement
  • Solving Infrastructure Modernization Challenges
  • Artificial Intelligence
  • Hyperconverged
  • Server Room
  • Secure Research Computing

Product

  • Benefits
  • Documents
  • Architecture Overview
  • Use Cases
  • Videos

Company

  • Blog
  • Technical Documentation
  • Legal

© 2026 VergeIO. All Rights Reserved.